2026 Latest Pass4Test Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1OfUCUGX-9B1c3FsNrA1GNGb3_b8qQ7kL
If you find the most suitable Databricks-Generative-AI-Engineer-Associate study materials on our website, just add the Databricks-Generative-AI-Engineer-Associate actual exam to your shopping cart and pay money for our products. Our online workers will quickly deal with your orders. We will follow the sequence of customers’ payment to send you our Databricks-Generative-AI-Engineer-Associate Guide questions to study right away with 5 to 10 minutes. It is quite easy and convenient for you to download our Databricks-Generative-AI-Engineer-Associate practice engine as well.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Databricks-Generative-AI-Engineer-Associate Test Cram Review <<
Our to-the-point and trustworthy Databricks Databricks Certified Generative AI Engineer Associate Exam Questions in three formats for the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certification exam will surely assist you to qualify for Databricks Databricks-Generative-AI-Engineer-Associate certification. Do not underestimate the value of our Databricks Databricks-Generative-AI-Engineer-Associate Exam Dumps because it is the make-or-break point of your career. Therefore, make the most of this opportunity of getting these superb exam questions for the Financials in Databricks Databricks-Generative-AI-Engineer-Associate certification exam.
NEW QUESTION # 76
A company has a typical RAG-enabled, customer-facing chatbot on its website.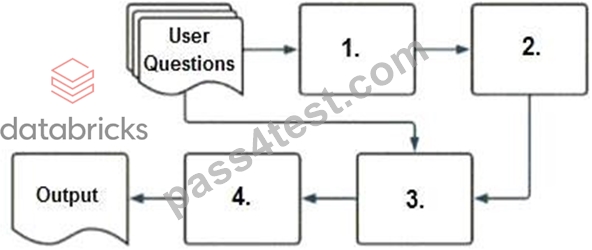
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user ' s question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1) : The first step involves the user ' s question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2) : The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3) : The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4) : Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable :
* B, C, D : These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response- generating LLM , which is option A.
NEW QUESTION # 77
A company selling gourmet mushroom-growing supplies has a script that runs once per day to scrape various social media platforms for posts that mention its name. The scraped text data is loaded into a Delta table each night for a downstream processing task that summarizes each post and its sentiment for internal use. Given the small size of the company, it only receives a couple hundred posts per day.
Which solution best optimizes for cost and ease of implementation?
Answer: A
Explanation:
A scheduled SQL query using ai_query() is a straightforward way to process text already stored in a Delta table. The query can send each post to a supported model with instructions to return a summary and sentiment, then persist the results for internal reporting. A pay-per-token service avoids dedicating serving capacity to a workload containing only a few hundred daily records. Calling an external batch API introduces additional integration and result-handling work, while downloading and hosting a model adds infrastructure responsibilities. Provisioned throughput is generally more appropriate when sustained demand justifies dedicated capacity. B is the best fit among these choices; actual costs still depend on model selection, token volume, SQL compute, and the applicable inference pricing. Databricks documentation
NEW QUESTION # 78
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
Answer: B
Explanation:
Problem Context: The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns. The key factors areconfidentialityandsensitivityof the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
Explanation of Options:
* Option A: Dolly 1.5B: This model does not typically support RAG applications as it's more focused on image generation tasks.
* Option B: OpenAI GPT-4: While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
* Option C: BGE-large: The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements.
Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project's sensitivity and confidentiality needs.
* Option D: Llama2-70B: Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns,BGE-largeis assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
NEW QUESTION # 79
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
Answer: B
Explanation:
* Problem Context: The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns. The key factors are confidentiality and sensitivity of the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
* Explanation of Options:
Option A: Dolly 1.5B: This model does not typically support RAG applications as it's more focused on image generation tasks.
Option B: OpenAI GPT-4: While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
Option C: BGE-large: The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements. Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project's sensitivity and confidentiality needs.
Option D: Llama2-70B: Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns, BGE-large is assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
NEW QUESTION # 80
A Generative Al Engineer is helping a cinema extend its website's chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.
Which option will do this with the least effort and in the most performant way?
Answer: C
Explanation:
The task is to extend a cinema chatbot to provide movie showtime information using a RAG application, leveraging user location and a continuously updated Delta table, with minimal effort and high performance. Let's evaluate the options.
Option A: Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation Databricks Feature Serving provides low-latency access to real-time data from Delta tables via an online store. Syncing the Delta table to a Feature Serving Endpoint allows the chatbot to query showtimes efficiently, integrating seamlessly into the RAG agent's tool logic. This leverages Databricks' native infrastructure, minimizing effort and ensuring performance.
Databricks Reference: "Feature Serving Endpoints provide real-time access to Delta table data with low latency, ideal for production systems" ("Databricks Feature Engineering Guide," 2023).
Option B: Query the Delta table directly via a SQL query constructed from the user's input using a text-to-SQL LLM in the agent logic / tool Using a text-to-SQL LLM to generate queries adds complexity (e.g., ensuring accurate SQL generation) and latency (LLM inference + SQL execution). While feasible, it's less performant and requires more effort than a pre-built serving solution.
Databricks Reference: "Direct SQL queries are flexible but may introduce overhead in real-time applications" ("Building LLM Applications with Databricks").
Option C: Write the Delta table contents to a text column, then embed those texts using an embedding model and store these in the vector index. Look up the information based on the embedding as part of the agent logic / tool implementation Converting structured Delta table data (e.g., showtimes) into text, embedding it, and using vector search is inefficient for structured lookups. It's effort-intensive (preprocessing, embedding) and less precise than direct queries, undermining performance.
Databricks Reference: "Vector search excels for unstructured data, not structured tabular lookups" ("Databricks Vector Search Documentation").
Option D: Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation Exporting to an external database (e.g., MySQL) adds setup effort (workflow, external DB management) and latency (periodic updates vs. real-time). It's less performant and more complex than using Databricks' native tools.
Databricks Reference: "Avoid external systems when Delta tables provide real-time data natively" ("Databricks Workflows Guide").
Conclusion: Option A minimizes effort by using Databricks Feature Serving for real-time, low-latency access to the Delta table, ensuring high performance in a production-ready RAG chatbot.
NEW QUESTION # 81
......
Our product backend port system is powerful, so it can be implemented even when a lot of people browse our website can still let users quickly choose the most suitable for his Databricks-Generative-AI-Engineer-Associate qualification question, and quickly completed payment. Once the user finds the Databricks-Generative-AI-Engineer-Associate learning material that best suits them, only one click to add the Databricks-Generative-AI-Engineer-Associate Study Tool to their shopping cart, and then go to the payment page to complete the payment, our staff will quickly process user orders online. In general, users can only wait about 5-10 minutes to receive our Databricks-Generative-AI-Engineer-Associate learning material,
Databricks-Generative-AI-Engineer-Associate Dump Check: https://www.pass4test.com/Databricks-Generative-AI-Engineer-Associate.html
P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Pass4Test: https://drive.google.com/open?id=1OfUCUGX-9B1c3FsNrA1GNGb3_b8qQ7kL