P.S. Kostenlose und neue DP-100 Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1PVQsA8JWm4wExOHaCSVH2bhb7roar75a
Die Microsoft DP-100 Prüfungsdumps von It-Pruefung haben hohe Hit-Rate und helfen den Kadidaten, die Prüfung einmalig zu bestehen. Das kann von vielen Kadidaten bewiesen werden. Deshalb sorgen Sie nicht um die Qualität dieser Microsoft DP-100 Prüfungsfragen. Die sind die Prüfungsmaterialien, an denen Sie wirklich glauben können. Wenn Sie nicht glauben, dann probieren Sie persönlich einmal. Damit können Sie an meinen Worten glauben.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Explore data and run experiments | 20-25% | - Implement pipelines
|
| Topic 2: Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
| Topic 3: Train and deploy models | 25-30% | - Monitor and maintain models
|
| Topic 4: Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
Die Prüfungsunterlagen zur Microsoft DP-100 Zertifizierungsprüfung werden nach dem Lehrkompendium und den echten Prüfungen bearbeitet. Wir aktualisieren auch ständig unsere Schulungsunterlagen, so dass Sie in erster Zeit die neuesten und besten Informationen bekommen. Wenn Sie unsere Schulungsunterlagen zur Microsoft DP-100 Zertifizierungsprüfung kaufen, können Sie einen einjährigen kostenlosen Update-Service bekommen. Sie können jederzeit Abonnmentszeit verlängern, so dass Sie mehr Zeit haben, sich auf die Microsoft DP-100 Prüfung vorzubereiten.
396. Frage
You need to use the Python language to build a sampling strategy for the global penalty detection models.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Reference:
https://github.com/pytorch/pytorch/blob/master/torch/utils/data/distributed.py
Topic 2, Overview
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns:
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column. The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment Requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
397. Frage
You manage an Azure Machine Learning workspace and a GitHub repository. The GitHub repository contains a CSV file located at httpsy/raw.githubusercontent.com/account1/repo1/main/doc1/data1.csv. The CSV file includes embedded newlines.
You plan to consume the content of the CSV file in the workspace. The solution must minimize the possibility of misaligned field values when reading the file content.
You need to create a data asset that references the CSV file.
Which data asset configuration values should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
398. Frage
You have an Azure Machine Learning workspace named workspace1 that is accessible from a public endpoint.
The workspace contains an Azure Blob storage datastore named store1 that represents a blob container in an Azure storage account named account1. You configure workspace1 and account1 to be accessible by using private endpoints in the same virtual network.
You must be able to access the contents of store1 by using the Azure Machine Learning SDK for Python. You must be able to preview the contents of store1 by using Azure Machine Learning studio.
You need to configure store1.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.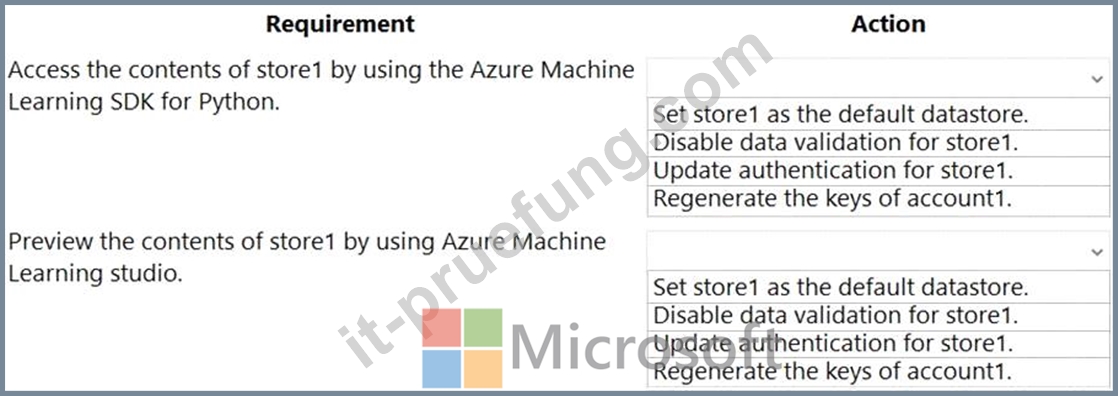
Antwort:
Begründung:
Explanation:
Box 1: Regenerate the keys of account1.
Azure Blob Storage support authentication through Account key or SAS token.
To authenticate your access to the underlying storage service, you can provide either your account key, shared access signatures (SAS) tokens, or service principal Box 2: Update the authentication for store1.
For Azure Machine Learning studio users, several features rely on the ability to read data from a dataset; such as dataset previews, profiles and automated machine learning. For these features to work with storage behind virtual networks, use a workspace managed identity in the studio to allow Azure Machine Learning to access the storage account from outside the virtual network.
Note: Some of the studio's features are disabled by default in a virtual network. To re-enable these features, you must enable managed identity for storage accounts you intend to use in the studio.
The following operations are disabled by default in a virtual network:
* Preview data in the studio.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-access-data
399. Frage
You are creating a binary classification by using a two-class logistic regression model.
You need to evaluate the model results for imbalance.
Which evaluation metric should you use?
Antwort: F
Begründung:
One can inspect the true positive rate vs. the false positive rate in the Receiver Operating Characteristic (ROC) curve and the corresponding Area Under the Curve (AUC) value. The closer this curve is to the upper left corner, the better the classifier's performance is (that is maximizing the true positive rate while minimizing the false positive rate). Curves that are close to the diagonal of the plot, result from classifiers that tend to make predictions that are close to random guessing.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio/evaluate-model-performance#evaluating-a- binary-classification-model
400. Frage
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are analyzing a numerical dataset which contains missing values in several columns.
You must clean the missing values using an appropriate operation without affecting the dimensionality of the feature set.
You need to analyze a full dataset to include all values.
Solution: Calculate the column median value and use the median value as the replacement for any missing value in the column.
Does the solution meet the goal?
Antwort: B
Begründung:
Explanation/Reference:
Explanation:
Use the Multiple Imputation by Chained Equations (MICE) method.
References:
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC3074241/
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data
401. Frage
......
Wenn Sie die Microsoft DP-100 Zertifizierungsprüfung bestehen, können Sie bestimmt größere Errungenschaften im Berufsleben erzielen. Wenn Sie It-Pruefung wählen, können wir Ihnen sicherlich Freude wegen des Bestehens der Microsoft DP-100 Zertifizierungsprüfung mitbringen. Kaufen Sie Prüfungsfragen und Antworten von It-Pruefung, können wir Ihnen garantieren, dass Sie die Microsoft DP-100 Zertifizierungsprüfung 100% bestehen können. Zugleich werden Sie auch einjährige Aktualisierung kostenlos genießen.
DP-100 PDF: https://www.it-pruefung.com/DP-100.html
2026 Die neuesten It-Pruefung DP-100 PDF-Versionen Prüfungsfragen und DP-100 Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1PVQsA8JWm4wExOHaCSVH2bhb7roar75a