DOWNLOAD the newest Prep4pass DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BsyaGb3t93V-aq2HOhYpFRzv9vhePpGx
Prep4pass will give you the best exam DP-750 study guide for your exam. The validity and reliability of our DP-750 practice torrent is confirmed by our experts. There are many customers have passed their DP-750 exam with our help. Our DP-750 test materials will be updated on the homepage and timely update the information related to the DP-750 qualification examination. We will give some promotion on our pdf cram, so that you can get the most valid and cost effective DP-750 prep material. So you can rest assured to choose our DP-750 training guide.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
Our DP-750 exam materials are formally designed for the exam. With its help, you don't have to worry about the exam any more for it almost guarantees you get what you want. If you think i'm exaggerating, you might as well take a look at our DP-750 Actual Exam. With a high pass rate as 98% to 100%, you will be bound to pass the exam. And our DP-750 training questions are popular in the market. We believe you will make the right choice.
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1. Table1 stores customer data.
You need to implement a data lifecycle solution that meets the following requirements:
* Deleted data must be recoverable for 30 days to support audits.
* Data that is older than 30 days must be removed permanently.
* The solution must minimize administrative effort.
* The solution must be enforced consistently.
What should you configure?
Answer: D
Explanation:
Data retention for Table1 should be configured to retain logically deleted Delta data files for 30 days. The delta.deletedFileRetentionDuration table property determines how long deleted or replaced files remain available before they become eligible for permanent removal by VACUUM. Configuring this property with a
30-day interval allows deleted data to remain recoverable through Delta Lake time travel during the required audit period. After the retention interval expires, VACUUM can permanently remove the unreferenced files.
Predictive optimization can automatically run VACUUM for Unity Catalog managed tables, minimizing administrative effort and applying the configured retention behavior consistently. learn.microsoft.com Scheduled DELETE operations logically remove records but do not independently delete their historical data files. Data lineage tracks relationships and transformations between data objects; it does not enforce lifecycle rules. Azure Storage lifecycle management is unaware of Delta transaction-log dependencies and must not be used to delete Delta files directly. Therefore, configuring table-level data retention is the correct solution.
NEW QUESTION # 47
You have an Apache Spark DataFrame named salesDF that contains the following columns:
Product
Region
Sales
Date
You need to create a pivot table that shows the total sales by product for each region.
How should you complete the PySpark code segment? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
groupBy
pivot
The groupBy( " Region " ) operation establishes one aggregation group for each geographical region in the DataFrame. The subsequent pivot( " Product " ) operation converts every distinct Product value into a separate output column. Finally, agg(F.sum( " Sales " )) calculates the total sales for every product within each region. The resulting DataFrame contains one row per region and one column for each product, with the corresponding aggregated sales value. cogroup combines grouped datasets and is not used for creating a conventional pivot table. coalesce controls the number of DataFrame partitions or replaces null values, depending on its context. The sum function is already provided inside the aggregation expression and therefore is not required in either blank.
NEW QUESTION # 48
You have an Azure Databricks workspace named Workspace1 that contains a cluster named Cluster1.
You need to enable a user named User1 to install a Maven package on all the nodes of Cluster1. The solution must follow the principle of least privilege.
What should you do?
Answer: D
Explanation:
Installing a Maven package on every node requires changing Cluster1's library configuration. The CAN MANAGE permission grants the cluster-level management capabilities required to add or remove libraries without giving User1 broader control over the entire workspace or Azure resource group. CAN RESTART allows a user to restart the cluster but does not provide sufficient authority to change its library configuration.
Assigning the Azure Contributor role would grant excessive control over the resource group and does not represent the appropriate Databricks object-level permission. Making User1 a workspace administrator would provide substantially more privileges than necessary. Granting CAN MANAGE directly on Cluster1 therefore satisfies the operational requirement while limiting User1's authority to the specific compute resource that must be modified.
NEW QUESTION # 49
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation: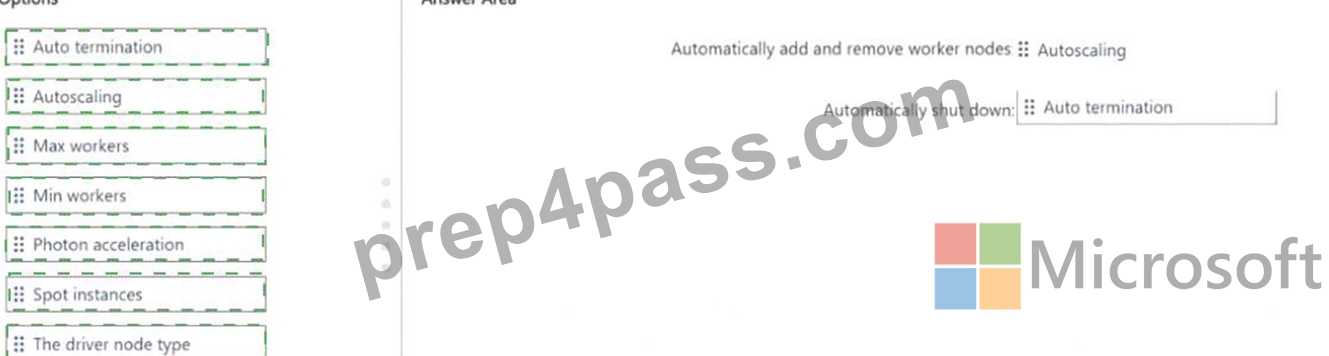
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 50
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.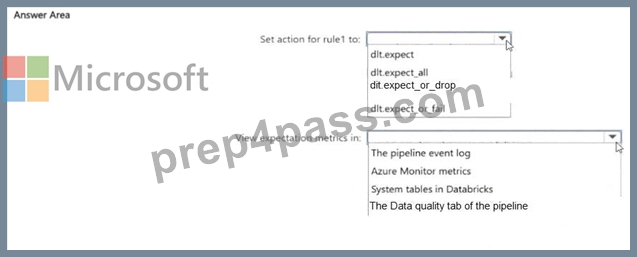
Answer:
Explanation: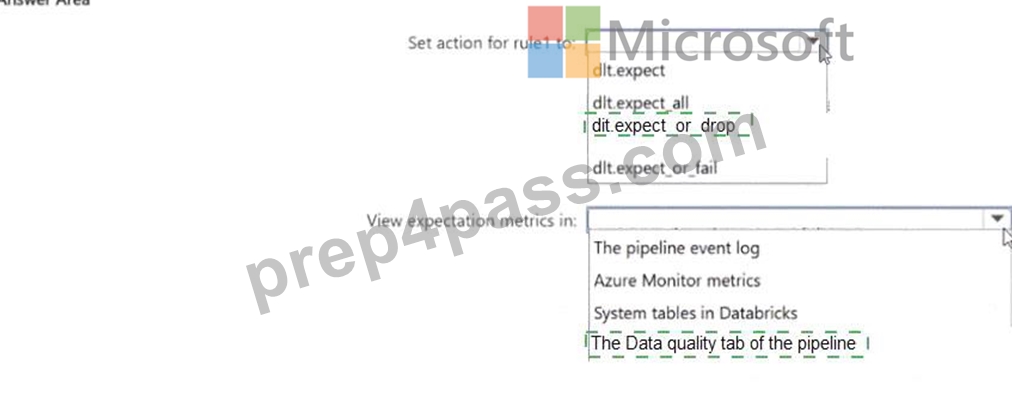
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 51
......
People who want to pass the exam have difficulty in choosing the suitable DP-750 guide questions. They do not know which study materials are suitable for them, and they do not know which the study materials are best. Our company can promise that the DP-750 study materials from our company are best among global market. As is known to us, the DP-750 Certification guide from our company is the leading practice materials in this dynamic market for DP-750 study materials from our company are designed by a lot of experts and professors. Yon can rely on our DP-750 exam questions!
Reliable DP-750 Test Cram: https://www.prep4pass.com/DP-750_exam-braindumps.html
What's more, part of that Prep4pass DP-750 dumps now are free: https://drive.google.com/open?id=1BsyaGb3t93V-aq2HOhYpFRzv9vhePpGx