Although our company has designed the best and most suitable Databricks-Certified-Data-Engineer-Professional learn prep, we also do not stop our step to do research about the Databricks-Certified-Data-Engineer-Professional study materials. All experts and professors of our company have been trying their best to persist in innovate and developing the Databricks-Certified-Data-Engineer-Professional test training materials all the time in order to provide the best products for all people and keep competitive in the global market. We believe that the Databricks-Certified-Data-Engineer-Professional Study Materials will keep the top selling products. We sincerely hope that you can pay more attention to our Databricks-Certified-Data-Engineer-Professional study questions.
| Section | Objectives |
|---|---|
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture - Medallion architecture (Bronze, Silver, Gold) - Data governance concepts (Unity Catalog basics) |
| Data Modeling and Transformation | - Dimensional modeling concepts - Performance optimization techniques - Spark SQL transformations |
| Production Pipelines and Orchestration | - Job scheduling and monitoring - Error handling and recovery strategies - Databricks Workflows |
| Delta Lake and Data Management | - Delta Lake transactions and ACID properties - Time travel and versioning - Schema evolution and enforcement |
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader - Structured Streaming fundamentals - ETL pipeline design patterns |
>> Exam Databricks-Certified-Data-Engineer-Professional Cost <<
By offering you excellent Databricks-Certified-Data-Engineer-Professional dumps files, DumpTorrent make you career bright and successful. We will offer you discount in buying Databricks-Certified-Data-Engineer-Professional exam pdf. Once you buy our Databricks practice questions, you will receive the download link immediately. Our aim is to provide our customers with latest exam study guide and the best-quality service. The up-to-date Databricks-Certified-Data-Engineer-Professional Practice Questions and answers are right here.
NEW QUESTION # 40
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
Answer: B
Explanation:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
NEW QUESTION # 41
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: D
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 42
When a new Databricks project starts, the central IP team provisions the required infrastructure using Terraform and a Service Principal. This includes creating a Databricks workspace, a Unity Catalog linked to an External Location, and a Databricks group containing all project team members. Project teams must store all assets - e.g., tables and volumes, as Managed assets in Unity Catalog. This model hides infrastructure complexity while giving teams autonomy within their catalog. They can create and manage schemas, tables, volumes, and related objects but cannot rename, delete, or change catalog permissions, those remain under IT's control. Which rights should the project group be granted to enable this model?
Answer: D
Explanation:
Granting the project group USE CATALOG (and USE SCHEMA on existing schemas) allows team members to work within the catalog without giving them ownership or administrative control.
This enables teams to create and manage schemas, tables, and volumes inside the catalog while preventing them from renaming, deleting, or modifying catalog-level permissions, which remain under central IT governance.
NEW QUESTION # 43
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
Answer: A
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
NEW QUESTION # 44
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table: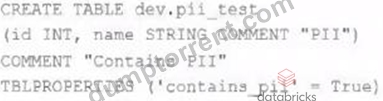
Which command allows manual confirmation that these three requirements have been met?
Answer: E
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 45
......
The Databricks-Certified-Data-Engineer-Professional Exam practice software is based on the real Databricks-Certified-Data-Engineer-Professional exam dumps. The interface of Databricks-Certified-Data-Engineer-Professional exam practice software is user-friendly so you will not face any difficulty to become familiar with it. Practice test software contains simulated real Databricks-Certified-Data-Engineer-Professional exam scenario. It has numerous self-learning and self-assessment features to test their learning. Our software exam offers you statistical reports which will upkeep the students to find their weak areas and work on them. We guarantee if you trust the Databricks-Certified-Data-Engineer-Professional Exam Practice test software, getting the highest score in the actual Databricks-Certified-Data-Engineer-Professional exam will not be difficult anymore.
Databricks-Certified-Data-Engineer-Professional Study Guide Pdf: https://www.dumptorrent.com/Databricks-Certified-Data-Engineer-Professional-braindumps-torrent.html