P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1qN_wyFZcIWwxL47JtMrPSDWfzLK2Zs84
Our online test engine and the windows software of the AI-300 study materials can evaluate your exercises of the virtual exam and practice exam intelligently. Our calculation system of the AI-300 study materials is designed subtly. Our evaluation process is absolutely correct. We are strictly in accordance with the detailed grading rules of the real exam. The point of every question is set separately. Once you submit your exercises of the AI-300 Study Materials, the calculation system will soon start to work.
| Section | Objectives |
|---|---|
| Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates |
| Design and implement a GenAIOps infrastructure | - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails |
| Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Optimize inference performance, caching, and throughput - Implement cost management and scaling strategies for GenAI workloads |
| Implement machine learning model lifecycle and operations | - Retrain, update, and manage model versions in production - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Deploy models to real-time and batch endpoints |
| Design and implement an MLOps infrastructure | - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows |
With the consistent reform in education, our AI-300 test question also change with the newest education regulation. We have strong confidence in offering the first-class AI-300 study prep to our customers. So what you have learned is fully conforming to the latest test syllabus. Also, our specialists can predicate the AI-300 exam precisely. Firstly, our company has summed up much experience after so many years’ accumulation. The model test is very important. You are advised to master all knowledge of the model test. Most of the real exam questions come from the adaption of our AI-300 Test Question. In fact, we get used to investigate the real test every year. The similarity between our study materials and official test is very amazing. In a word, your satisfaction and demands of the AI-300 exam braindump is our long lasting pursuit. Hesitation will not generate good results. Action always speaks louder than words. Our AI-300 study prep will not disappoint you. So just click to pay for it.
NEW QUESTION # 178
You use an Azure Machine Learning workspace.
You must monitor cost at the endpoint and deployment level.
You have a trained model that must be deployed as an online endpoint. Users must authenticate by using Microsoft Entra ID.
What should you do?
Answer: B
NEW QUESTION # 179
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.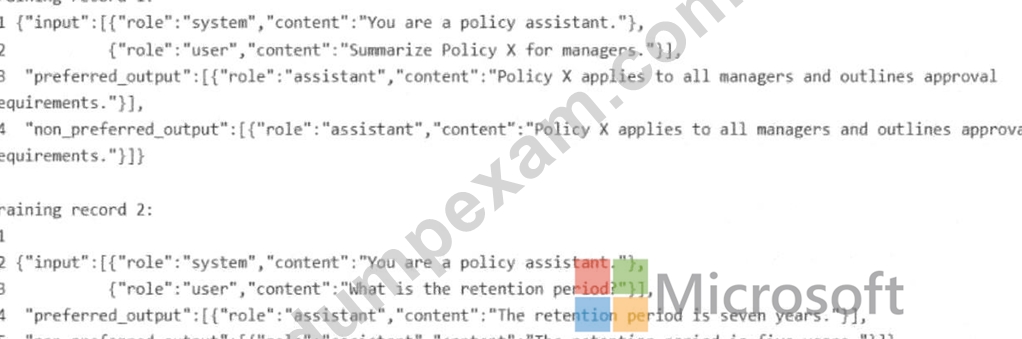
For each of the following statements, select Yes if the statement is true. Otherwise, select No . NOTE: Each correct selection is worth one point.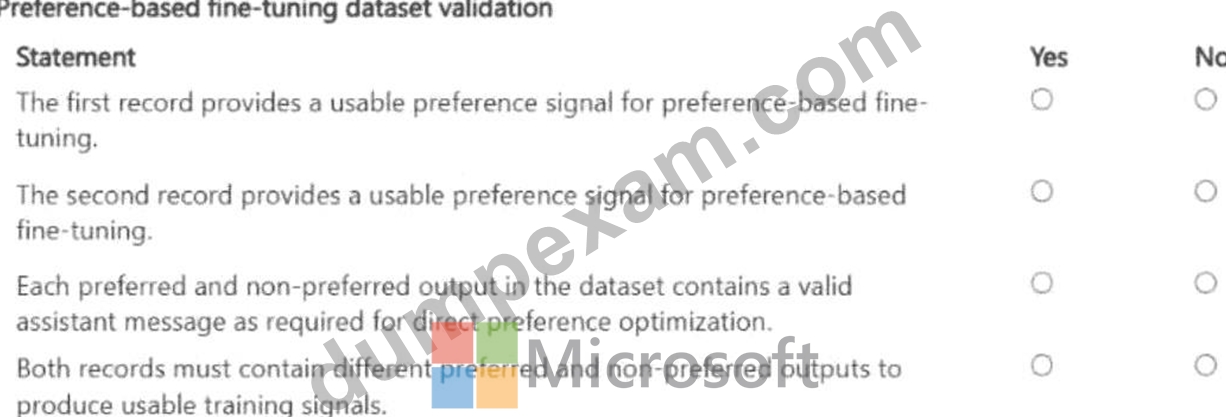
Answer:
Explanation: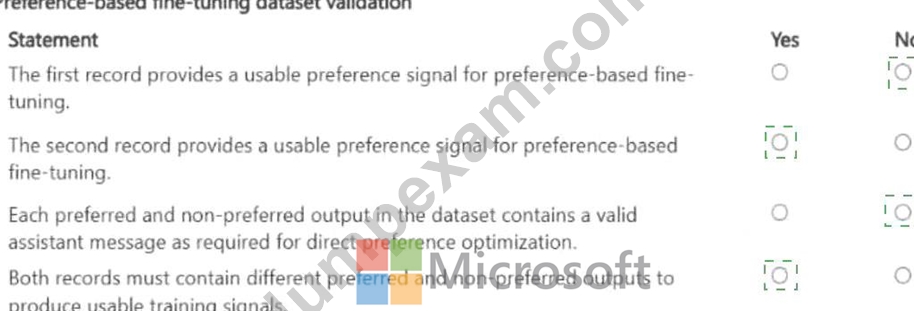
Explanation:
Preference comparison data with chosen versus rejected response pairs is the input format for Direct Preference Optimization (DPO) or RLHF-style fine-tuning - an advanced fine-tuning technique available in Microsoft Foundry. A valid DPO dataset record must have three fields: a prompt as the input, a chosen field containing the preferred response, and a rejected field containing the less preferred response. The file must be in JSONL format with UTF-8 encoding, where each line represents one complete preference pair. When evaluating statements about this dataset, mark True if the dataset contains all three required fields and chosen responses represent higher-quality outputs than rejected ones. Mark False if the format is incompatible with DPO requirements, if the required rejected field is missing, or if the chosen and rejected responses appear to be of equivalent quality with no clear preference signal.
Microsoft Learn Reference Topic: Advanced fine-tuning with preference data in Microsoft Foundry - DPO dataset format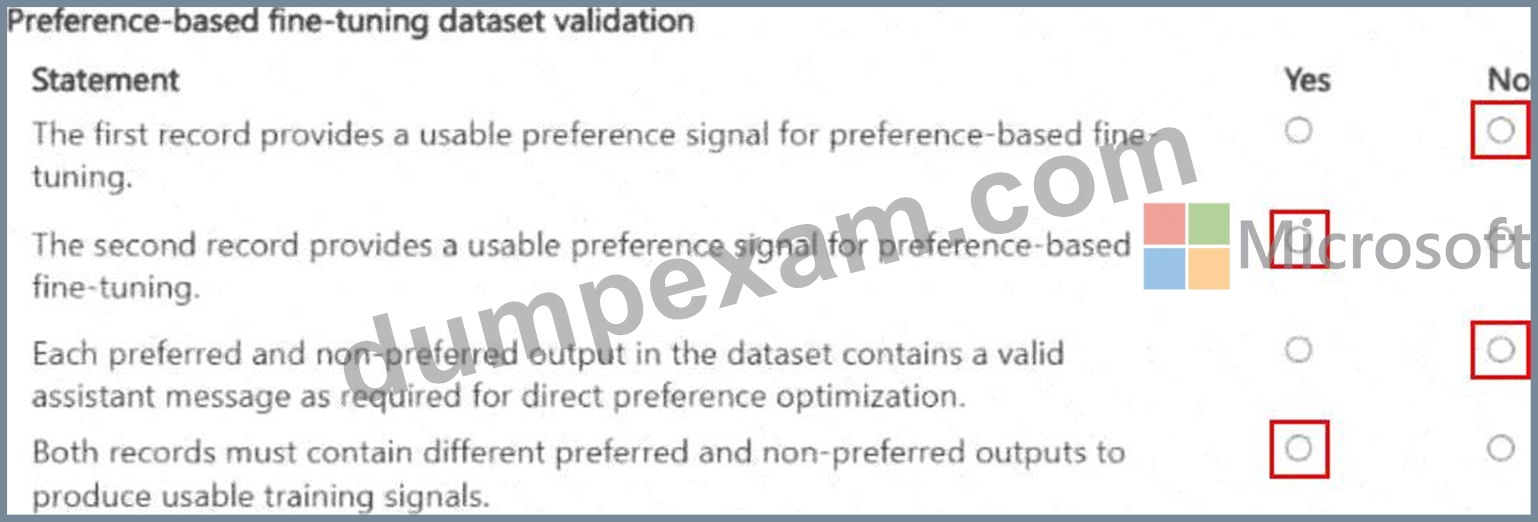
NEW QUESTION # 180
You manage an Azure Machine Learning workspace
You build an Azure Machine Learning pipeline for image classification by using custom components. You need to define the interface, metadata, and code to execute components from a Python function. Which function should you use?
Answer: A
NEW QUESTION # 181
You create an Azure Machine Learning workspace. You use the Azure Machine Learning Python SDK v2 to create a compute cluster.
The compute cluster must run a training script. Costs associated with running the training script must be minimized.
You need to complete the Python script to create the compute cluster.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.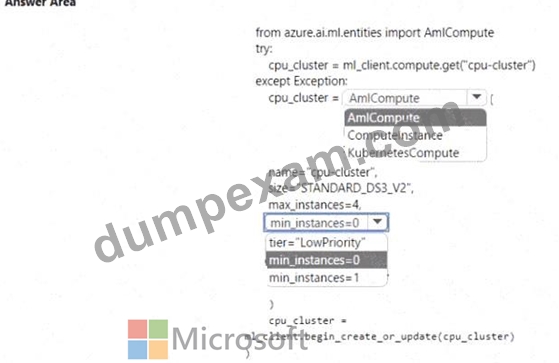
Answer:
Explanation: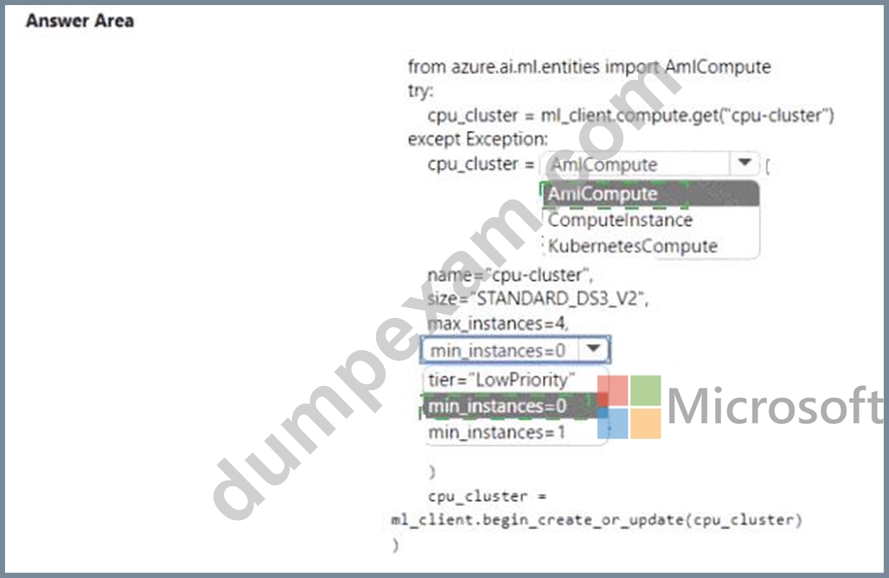
Explanation: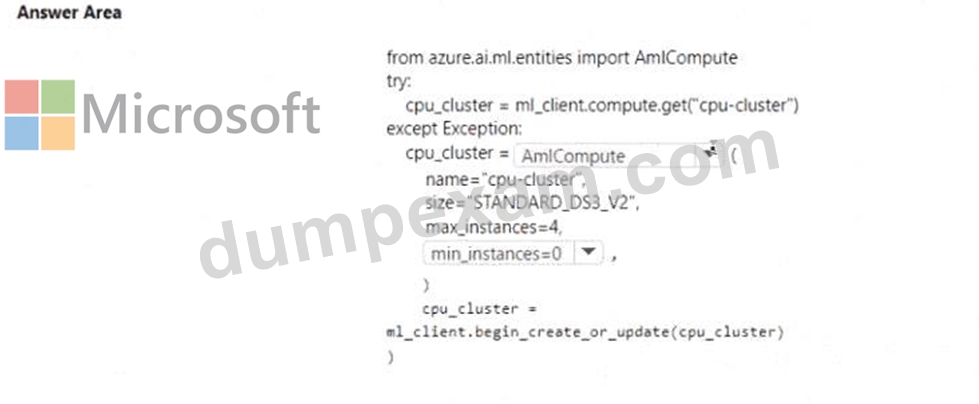
NEW QUESTION # 182
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Create an environment.
Does the solution meet the goal?
Answer: A
Explanation:
Yes. Before registering a new Jupyter kernel on an Azure Machine Learning compute instance, you create a separate environment that will contain the Python runtime and packages associated with that kernel.
Microsoft's current Azure Machine Learning terminal guidance explicitly starts the new-kernel procedure by creating a Conda environment, for example:
conda create --name newenv
The environment is then activated by using conda activate newenv. After activation, pip and ipykernel are installed into that environment, and the environment is finally registered as a Jupyter kernel by using python - m ipykernel install.
This separation is important because each Jupyter kernel should execute against a defined Python environment containing its own dependencies. It prevents package changes for one notebook workload from unexpectedly affecting another kernel or the Azure Machine Learning system environment.
Therefore, creating an environment is a valid prerequisite in the process of adding a new Jupyter kernel from the Azure Machine Learning terminal. The environment provides the runtime context that is subsequently exposed to Jupyter through its kernel specification.
Study Guide Reference: Design and implement an MLOps infrastructure - Azure Machine Learning compute instances, Jupyter kernels, Conda environments, dependency isolation, and interactive development.
NEW QUESTION # 183
......
Now rest assured that with the Microsoft AI-300 exam questions you will get the updated version of AI-300 exam real questions all the time. You have the option to download updated Microsoft AI-300 Exam Questions up to 12 months from the date of Microsoft AI-300 exam questions purchase.
Testking AI-300 Exam Questions: https://www.dumpexam.com/AI-300-valid-torrent.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by DumpExam: https://drive.google.com/open?id=1qN_wyFZcIWwxL47JtMrPSDWfzLK2Zs84