The countless candidates have already passed their Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification exam and they all used the real, valid, and updated Databricks-Certified-Professional-Data-Engineer exam questions. So, why not, take a decision right now and ace your Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam preparation with top-notch Databricks Databricks-Certified-Professional-Data-Engineer exam questions?
| Section | Objectives |
|---|---|
| Topic 1: Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Topic 2: Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance - Build and manage workflows using Databricks Jobs |
| Topic 3: Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines |
| Topic 4: Data Modeling and Storage | - Design scalable data lakehouse architectures - Delta Lake table design and optimization - Schema evolution and data partitioning strategies |
>> Exam Databricks-Certified-Professional-Data-Engineer Simulator Online <<
BraindumpQuiz senior experts have developed exercises and answers about Databricks certification Databricks-Certified-Professional-Data-Engineer exam with their knowledge and experience, which have 95% similarity with the real exam. I believe that you will be very confident of our products. If you choose to use BraindumpQuiz's products, BraindumpQuiz can help you 100% pass your first time to attend Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam. If you fail the exam, we will give a full refund to you.
NEW QUESTION # 84
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: B
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 85
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI. Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job. They attempt to transfer
"Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
Answer: A
Explanation:
The reason why the junior data engineer cannot transfer "Owner" privileges to the "DevOps" group is that Databricks jobs must have exactly one owner, and the owner must be an individual user, not a group. A job cannot have more than one owner, and a job cannot have a group as an owner. The owner of a job is the user who created the job, or the user who was assigned the ownership by another user. The owner of a job has the highest level of permission on the job, and can grant or revoke permissions to other users or groups. However, the owner cannot transfer the ownership to a group, only to another user. Therefore, the junior data engineer's attempt to transfer "Owner" privileges to the "DevOps" group is not possible. References:
* Jobs access control: https://docs.databricks.com/security/access-control/table-acls/index.html
* Job permissions: https://docs.databricks.com/security/access-control/table-acls/privileges.html#job- permissions
NEW QUESTION # 86
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: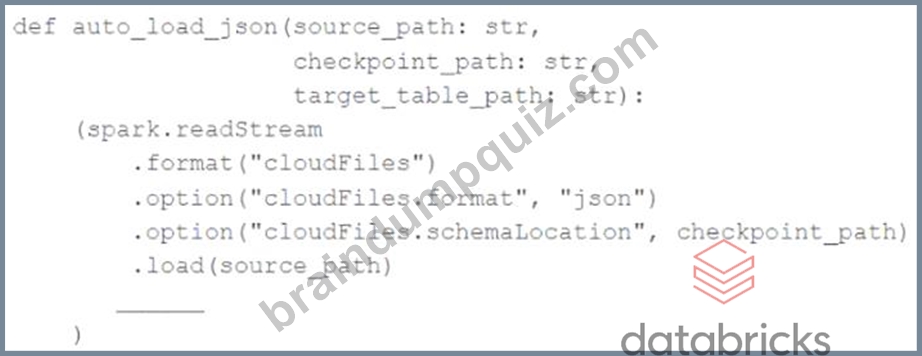
Which response correctly fills in the blank to meet the specified requirements?
Answer: B
Explanation:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the
"cloudFiles.schemaLocation" option, which is required for the schema detection andevolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References:
* Configure schema inference and evolution in Auto Loader:
https://docs.databricks.com/en/ingestion/auto-loader/schema.html
* Write streaming data:
https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming-data.html
NEW QUESTION # 87
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables.
Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
Answer: C
Explanation:
Explanation
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "Database object privileges" section.
NEW QUESTION # 88
A data engineer needs to create a database called customer360 at the loca-tion /customer/customer360. The
data engineer is unsure if one of their colleagues has already created the database.
Which of the following commands should the data engineer run to complete this task?
Answer: D
NEW QUESTION # 89
......
If you do all things with efficient, you will have a promotion easily. If you want to spend less time on preparing for your Databricks-Certified-Professional-Data-Engineer exam, if you want to pass your exam and get the certification in a short time, our Databricks-Certified-Professional-Data-Engineer Study Materials will be your best choice to help you achieve your dream. Only studying with our Databricks-Certified-Professional-Data-Engineer learning engine for 20 to 30 hours, we can claim that you can pass you exam without difficulty.
Databricks-Certified-Professional-Data-Engineer Actual Exams: https://www.braindumpquiz.com/Databricks-Certified-Professional-Data-Engineer-exam-material.html