P.S. Free & New NCP-AII dumps are available on Google Drive shared by Prep4sureExam: https://drive.google.com/open?id=1XWqh0zJCoHShpgWw9hv7cqfLWP6KHyLN
In order to help customers, who are willing to buy our NCP-AII test torrent, make good use of time and accumulate the knowledge, Our company have been trying our best to reform and update our NVIDIA AI Infrastructure exam tool. “Quality First, Credibility First, and Service First” is our company’s purpose, we deeply hope our NCP-AII study materials can bring benefits and profits for our customers. So we have been persisting in updating our NCP-AII Test Torrent and trying our best to provide customers with the latest study materials. More importantly, the updating system we provide is free for all customers. If you decide to buy our NCP-AII study materials, we can guarantee that you will have the opportunity to use the updating system for free.
| Certification Vendor: | NVIDIA |
|---|---|
| Exam Name: | NVIDIA-Certified Professional AI Infrastructure Exam |
| Exam Number: | NCP-AII |
| Real Exam Qty: | 60-70 |
| Exam Price: | $400 USD |
| Related Certifications: | NVIDIA-Certified Associate AI Infrastructure and Operations (NCA-AIIO) NVIDIA-Certified Professional AI Networking (NCP-AIN) NVIDIA-Certified Professional AI Operations (NCP-AIO) |
| Available Languages: | English |
| Passing Score: | Pass/Fail only, no numerical score |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple-choice questions, Scenario-based items |
| Recommended Training: | NVIDIA AI Infrastructure Training |
| Exam Registration: | NVIDIA Certification Portal |
| Sample Questions: | NVIDIA NCP-AII Sample Questions |
| Exam Way: | Online remote proctored or onsite at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 2–3 years of experience in data center infrastructure, Linux administration, and NVIDIA hardware/software environments |
| Official Syllabus URL: | https://www.nvidia.com/en-us/learn/certification/ai-infrastructure-professional/ |
>> Test NCP-AII Questions Pdf <<
NCP-AII study materials like a mini boot camp, you'll be prepared for NCP-AII test and guaranteed you to get the certificate you have been struggling to. The product here of NVIDIA-Certified Professional test, is cheaper, better and higher quality; you can learn NCP-AII skills and theory at your own pace; you will save more time and energy. No other NCP-AII Study Materials or study dumps will bring you the knowledge and preparation that you will get from the NCP-AII study materials available only from Prep4sureExam. Not only will you be able to pass any NCP-AII test, but will gets higher score, if you choose our NCP-AII study materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 12
For a 48-hour NCCL burn-in test, which parameters ensure sustained fabric stress while detecting silent data corruption?
Answer: C
Explanation:
all_reduce_perf with large message sizes sustains heavy fabric stress, while the validation/checking option helps detect silent data corruption during the burn-in. The long iteration count and GPU Direct usage keep the NCCL workload active long enough to expose intermittent fabric or data-integrity issues.
NEW QUESTION # 13
You're monitoring the storage I/O for an AI training workload and observe high disk utilization but relatively low CPU utilization. Which of the following actions is LEAST likely to improve the performance of the training job?
Answer: B
Explanation:
High disk utilization and low CPU utilization indicate an 1/0 bottleneck. Switching to faster storage (A), prefetching data (B), increasing the batch size (C), and adding more RAM (D) can all help alleviate the I/O bottleneck. Reducing the number of parallel data loading threads (E) would likely worsen the bottleneck by underutilizing the available 1/0 bandwidth.
NEW QUESTION # 14
A system administrator needs to install a container toolkit and successfully run the following commands: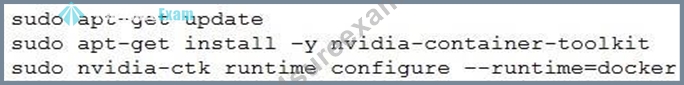
What step should be taken next to finish the installation?
Answer: C
Explanation:
After configuring the NVIDIA Container Toolkit runtime for Docker with nvidia-ctk runtime configure --runtime=docker, Docker must be restarted so it reloads the updated runtime configuration and can run GPU-enabled containers correctly.
NEW QUESTION # 15
Consider a scenario where you are running a CUDA application on an NVIDIA GPU. The application compiles successfully but crashes during runtime with a *CUDA ERROR ILLEGAL ADDRESS* error. You've carefully reviewed your code and can't find any obvious out- of-bounds memory accesses. What advanced debugging techniques could help you pinpoint the source of this error?
Answer: A,C,D
Explanation:
'cuda-memcheck' (A) is specifically designed to detect memory access errors. 'cuda-gdb' (B) allows for detailed code inspection. NVIDIA Nsight Systems (C) provides profiling information that can help identify memory allocation issues that lead to the error. Enabling ECC (D) might mask the symptom but doesn't fix the underlying code error, also ECC is enabled by default, so that's a red herring. Reducing block size (E) is only relevant if shared memory is involved and potentially overflowing.
NEW QUESTION # 16
An enterprise is deploying an AI Factory using NVIDIA DGX BasePOD architecture. The infrastructure team must ensure high availability and efficient data transfer between compute nodes. Which network topology should they implement for the InfiniBand fabric?
Answer: D
Explanation:
The correct answer is Fat-Tree topology with rail-optimized design. NVIDIA DGX BasePOD and similar AI Factory architectures rely on high-performance InfiniBand fabrics to support distributed GPU training, low- latency communication, and scalable bandwidth between compute nodes. A Fat-Tree topology provides multiple high-bandwidth paths between servers and switches, helping reduce oversubscription and improve bisection bandwidth. Rail-optimized design is especially important in DGX environments because each GPU or network adapter path can be aligned to a specific network rail, improving predictable communication behavior for NCCL collectives such as all-reduce and reduce-scatter. A simple ring topology is not suitable because it introduces unnecessary hop latency and limited failure tolerance. A single flat Ethernet network for all traffic does not meet the dedicated high-performance InfiniBand fabric requirement. A star topology with one central switch can become a bottleneck and single point of failure. For BasePOD-scale AI workloads, the fabric must support high availability, bandwidth consistency, and efficient East-West GPU communication, making a rail-optimized Fat-Tree the correct design.
NEW QUESTION # 17
......
NCP-AII Valid Dumps Sheet: https://www.prep4sureexam.com/NCP-AII-dumps-torrent.html
What's more, part of that Prep4sureExam NCP-AII dumps now are free: https://drive.google.com/open?id=1XWqh0zJCoHShpgWw9hv7cqfLWP6KHyLN