Microsoft AI-500 exam dumps is a surefire way to get success. Lead2Passed has assisted a lot of professionals in passing their Microsoft AI-500 certification test. In case you don't pass the Microsoft AI-500 pdf questions and practice tests, you have the full right to claim your full refund. You can download and test any AI-500 Exam Questions format before purchase. So don't get worried, start Microsoft AI-500 exam preparation and get successful.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Topic 2: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> Certification Microsoft AI-500 Test Questions <<
May be there are many materials for Microsoft practice exam, but the AI-500 exam dumps provided by our website can ensure you the accuracy and profession. If you decided to choose us as your training tool, you just need to use your spare time preparing AI-500 Free Download Pdf, and you will be surprised by yourself to get the certification.
NEW QUESTION # 33
You have a Microsoft Foundry project that includes four independent analysis agents. Each agent invocation consumes 500 tokens per minute (TPM) from a Foundry deployment that has a TPM rate limit of 1,000.
After each agent completes, it writes 200 small records to Microsoft Dataverse. Running multiple agents simultaneously causes write bursts that result in HTTP 429 (Too Many Requests) responses.
You need to reduce the end-to-end task duration, while preventing provider and platform throttling. The solution must meet the following requirements:
* Keep as much agent parallelism as the TPM rate limit permits.
* Handle Dataverse throttling without sending premature retries.
How should you configure the orchestration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.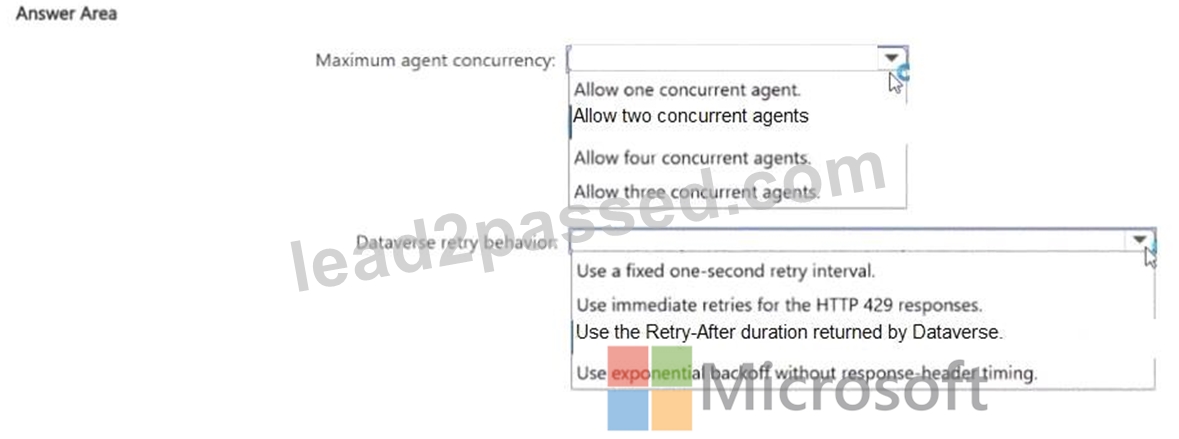
Answer:
Explanation: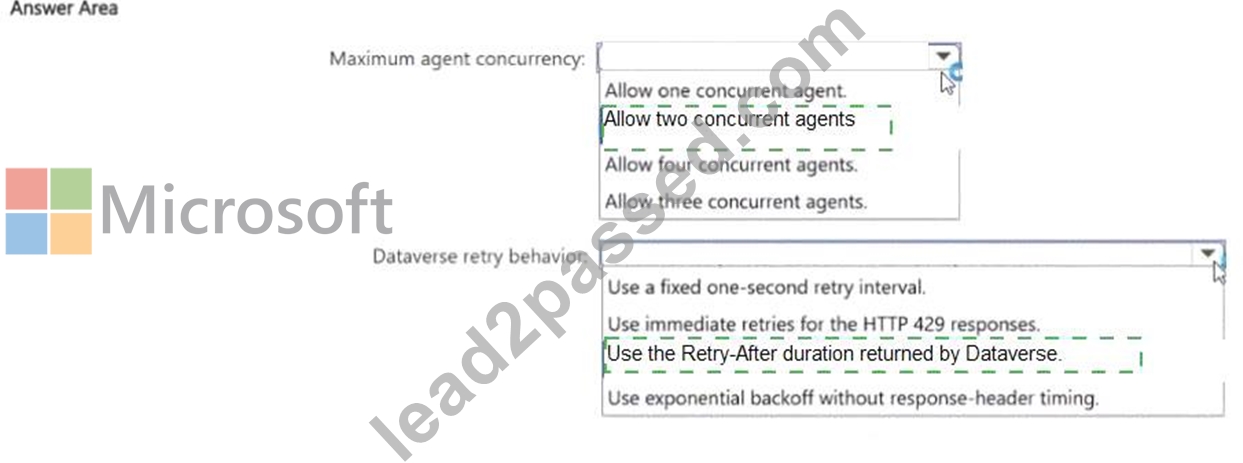
Explanation:
Maximum agent concurrency: Two agents; Dataverse retry behavior: Respect the Retry-After duration returned by Dataverse.
Each analysis agent consumes 500 TPM and the deployment permits 1,000 TPM, so at most two agents can run simultaneously without exceeding the stated model limit. Running only one wastes available parallelism; running three or four violates the limit. The separate Dataverse problem is HTTP 429 service-protection throttling. Microsoft Dataverse returns a `Retry-After` duration that tells clients how long to wait before retrying. Respecting that value prevents premature retries from worsening the overload condition. A fixed retry interval or immediate retry ignores the server ' s current capacity signal. The orchestration should therefore cap model-side concurrency at two and, after each agent finishes, pace Dataverse writes according to the returned retry guidance. This combination minimizes task duration while honoring both provider and platform throttling constraints. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Dataverse service protection API limits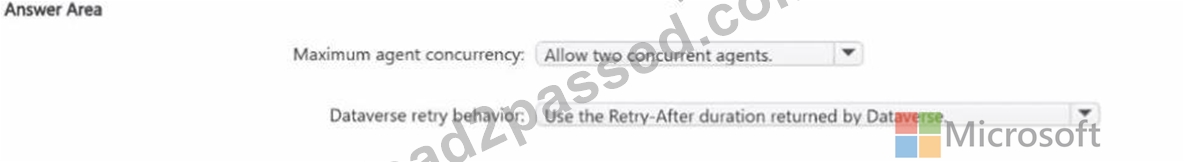
NEW QUESTION # 34
You have a Microsoft Foundry multi-agent solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. The retrieval agent uses a knowledge search tool.
Security testing reveals the following recurring issues:
* Some users submit jailbreak-style prompts at the start of a conversation.
* Some retrieved documents contain hidden instructions intended to manipulate the downstream agent The legal department at your company requires that final responses be flagged for review if they contain protected text. You need to configure guardrails to resolve the security issues and meet the legal requirements.
What should you configure?
Answer: B
Explanation:
The three risks occur at three different intervention points. Direct jailbreak attempts originate in the user prompt, so User input attacks should be evaluated at the User input boundary and blocked. Malicious instructions embedded in retrieved documents are indirect prompt-injection attacks and belong at the Tool response boundary before the retrieved content can influence downstream reasoning. Protected material in the final response must be flagged for legal review, not necessarily blocked, so an Output control using annotate- only behavior matches the requirement. Options A and B misplace at least one control or block content that the scenario says should only be flagged. Microsoft Foundry guardrails are explicitly designed around these intervention points, making C the configuration that aligns each risk with the stage where it can be detected and acted upon. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points
NEW QUESTION # 35
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.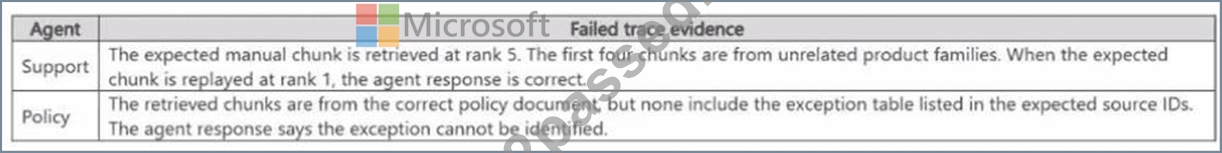
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation: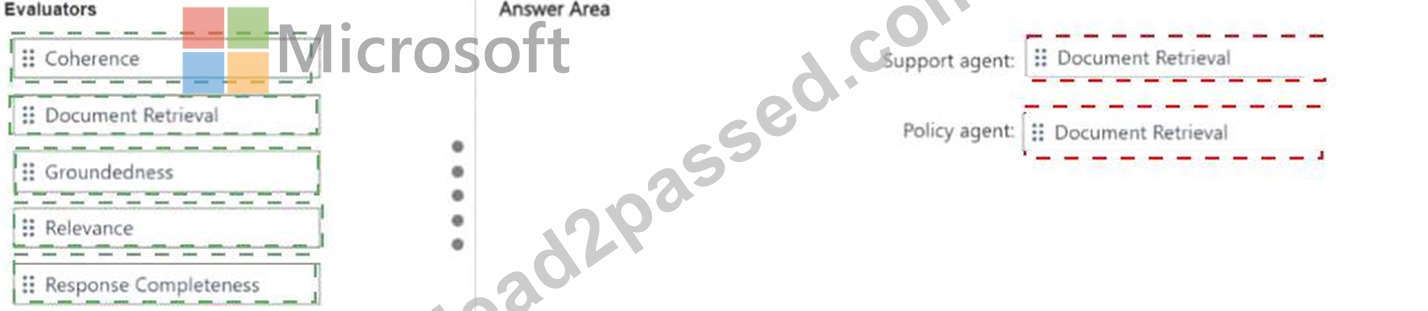
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 36
You have the following tool integration configuration for a Microsoft Foundry claims-processing assistant.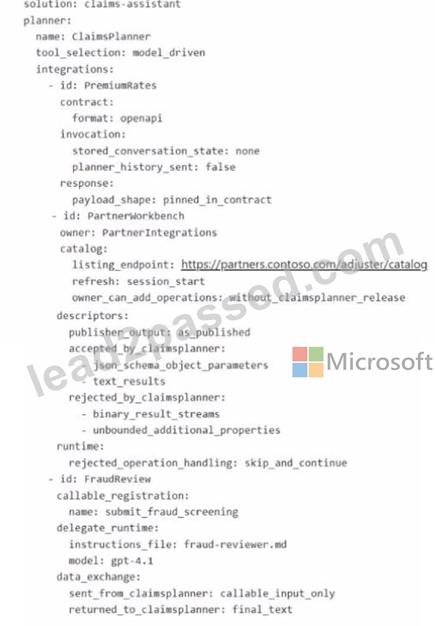
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.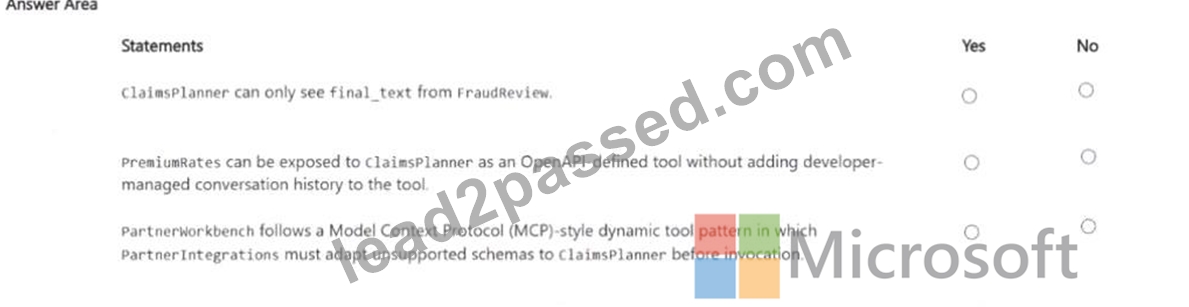
Answer:
Explanation: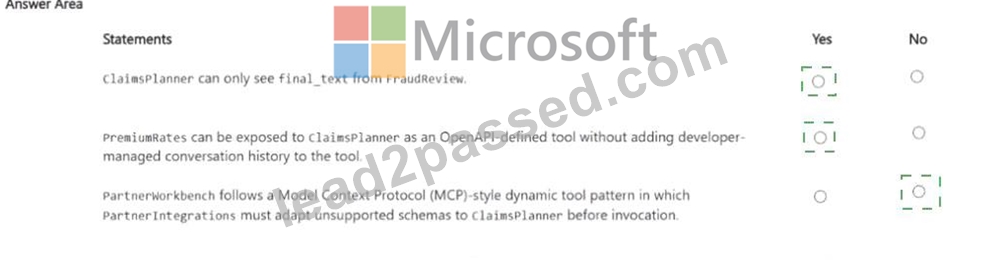
Explanation:
Yes / Yes / No
The first statement is true because the tool-integration contract returns only the explicitly defined `final_text` from FraudReview to ClaimsPlanner; the planner does not automatically receive the specialist ' s entire internal execution history. The second statement is also true because an external REST service such as PremiumRates can be exposed as an OpenAPI-defined tool. The OpenAPI schema describes operations and parameters, while the surrounding agent system retains conversational state; the REST tool itself does not need a developer-managed chat transcript. The third statement is false under the shown configuration because the partner publishes tool descriptors as published while the planner defines which schemas it accepts or rejects. Compatibility handling therefore occurs at the consumer/tool boundary rather than requiring PartnerIntegrations to rewrite every unsupported schema before invocation. The correct sequence is Yes, Yes, No. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry agents - OpenAPI tools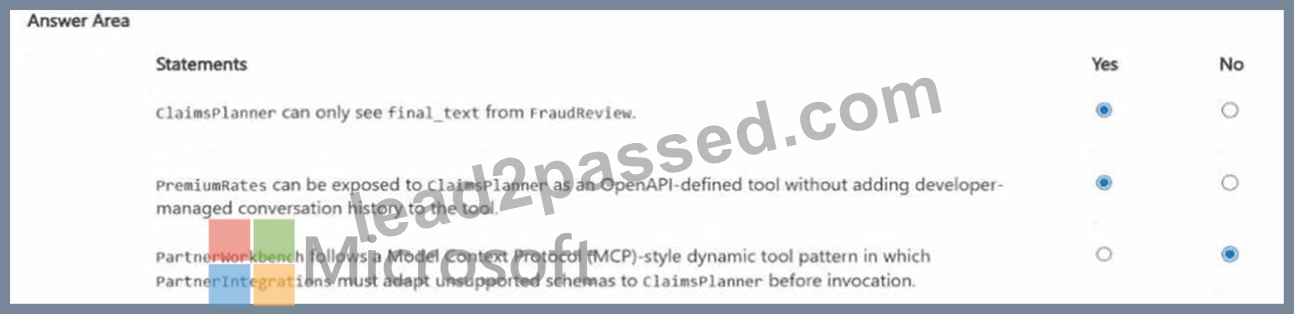
NEW QUESTION # 37
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.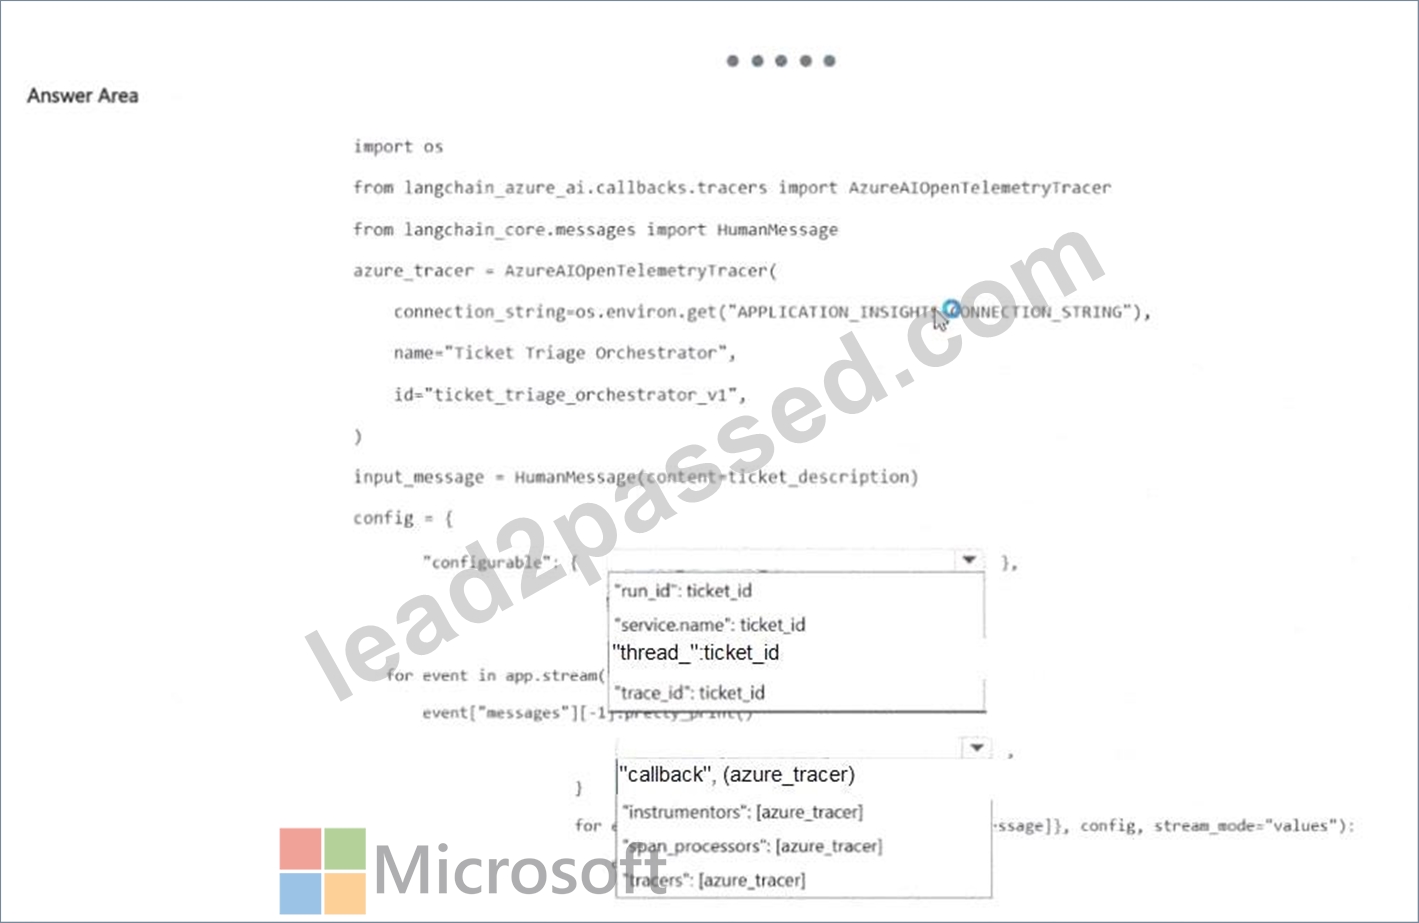
Answer:
Explanation: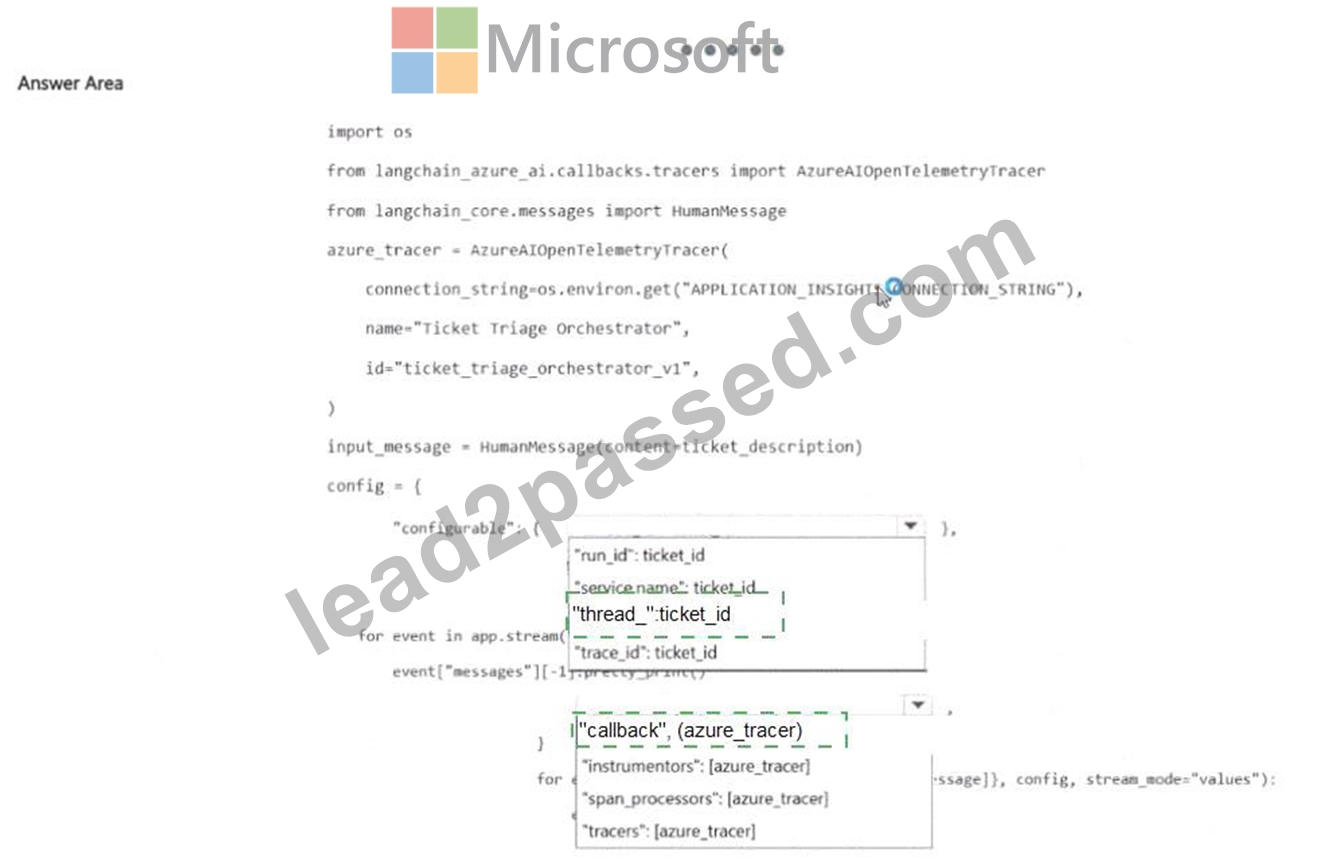
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents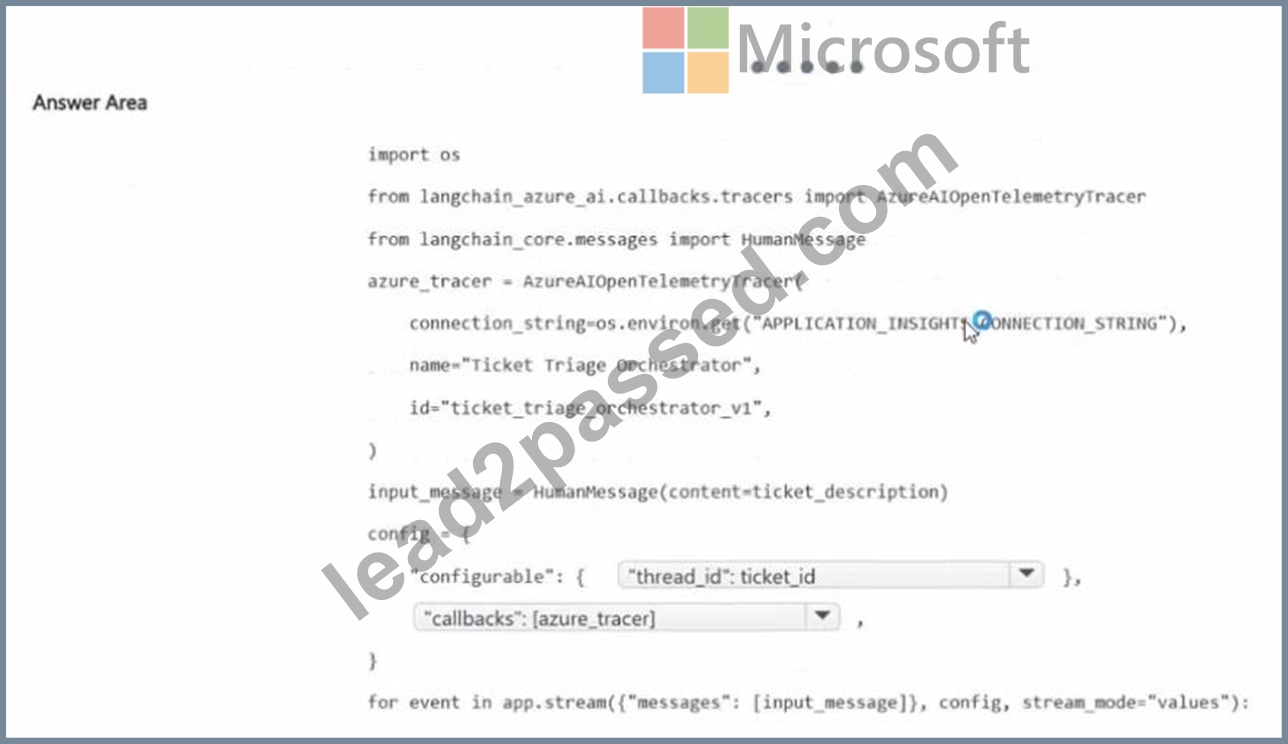
NEW QUESTION # 38
......
As sometimes new domains and topics are added to the Lead2Passed Designing and Implementing Multi-Agent AI Solutions exam syllabus, you’ll be able to get free updates of Microsoft AI-500 dumps for 365 days that cover all the latest exam topics. We provide customers instant access to all Microsoft Exams Dumps right after making the payment. Our customer support team is available 24/7 to assist you with all your issues regarding Microsoft AI-500 Exam Preparation material.
AI-500 Cheap Dumps: https://www.lead2passed.com/Microsoft/AI-500-practice-exam-dumps.html