P.S. CertShikenがGoogle Driveで共有している無料かつ新しいCKADダンプ:https://drive.google.com/open?id=1i8vpxzUaNbUKEhkeawZ8WSPsWLJyBKX2
市場で高い評価を得ている責任ある企業として、スタッフと従業員を厳格な信念を持って訓練し、CKAD学習教材に関する問題を24時間年中無休で支援しました。私たちとの購入活動を終えたとしても、CKAD試験問題に関する思いやりのあるサービスを提供しています。そして、CKADトレーニングガイドを随時更新します。CKADスタディガイドを更新したら、お客様に自動送信します。お支払い後1年間、CKAD学習準備の更新をお楽しみいただけます。
| Section | Weight | Objectives |
|---|---|---|
| Application Environment, Configuration and Security | 25% | - ConfigMaps and Secrets - Understanding and defining resource requirements, limits and quotas - ServiceAccounts - Discover and use resources that extend Kubernetes (CRD, Operators) - Understand authentication, authorization and admission control - SecurityContexts |
| Application Design and Build | 20% | - Define, build and modify container images - Choose and use the right workload resource (Deployment, DaemonSet, CronJob, etc.) - Understand multi-container Pod design patterns (e.g., sidecar, init and others) - Utilize persistent and ephemeral volumes |
| Application Observability and Maintenance | 15% | - Use built-in CLI tools to monitor Kubernetes applications - Understand API deprecation policies - Utilize container logs - Debugging in Kubernetes - Implement probes and health checks |
| Application Deployment | 20% | - Kustomize - Use Kubernetes primitives to implement common deployment strategies (e.g., blue/green or canary) - Use the Helm package manager to deploy existing packages - Understand Deployments and how to perform rolling updates |
| Services and Networking | 20% | - Provide and troubleshoot access to applications via services - Use Ingress rules to expose applications - Demonstrate basic understanding of NetworkPolicies |
最高のCKADテストトレントを提供する世界的なリーダーとして、私たちは大多数の消費者に包括的なサービスを提供し、統合サービスの構築に努めています。さらに、CKAD認定トレーニングアプリケーションだけでなく、インタラクティブな共有およびアフターサービスでもブレークスルーを達成しました。実際のところ、当社では、すべてのクライアントの適切なソリューションの問題を考慮しています。ヘルプが必要な場合は、CKAD試験トレントに関する問題に対処するための即時サポートを提供し、CKAD試験の合格を支援します。
質問 # 217
You are building a Kubernetes application that requires access to sensitive credentials stored in a Secret. The application should only have access to specific keys within the Secret, and you need to ensure that the Secret is updated without disrupting the application's functionality. How would you design and implement this functionality using Custom Resource Definitions (CRDs) and Kubernetes resources?
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define a CRD for Secret Access:
- Create a Custom Resource Definition (CRD) named 'SecretAccess' , representing the required access to the Secret. This CRD will define the following fields:
- 'secretName': The name ot the Secret containing the sensitive information.
- 'allowedKeys': A list of keys from the Secret that the application is allowed to access.
- The 'SecretAccess' CRD schema will be validated to ensure that the specified Secret and keys exist.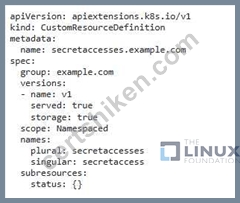
2. Create a Controller for SecretAccess CRD. - Implement a Kubernetes controller that watches for changes in 'SecretAccesS resources. - When a new 'SecretAccesS resource is created or updated, the controller: - Validates the specified Secret and allowed keys. - Creates or updates a new 'Secret resource with the requested keys from the original Secret. - Updates the 'SecretAccess' resource status with the name of the generated Secret.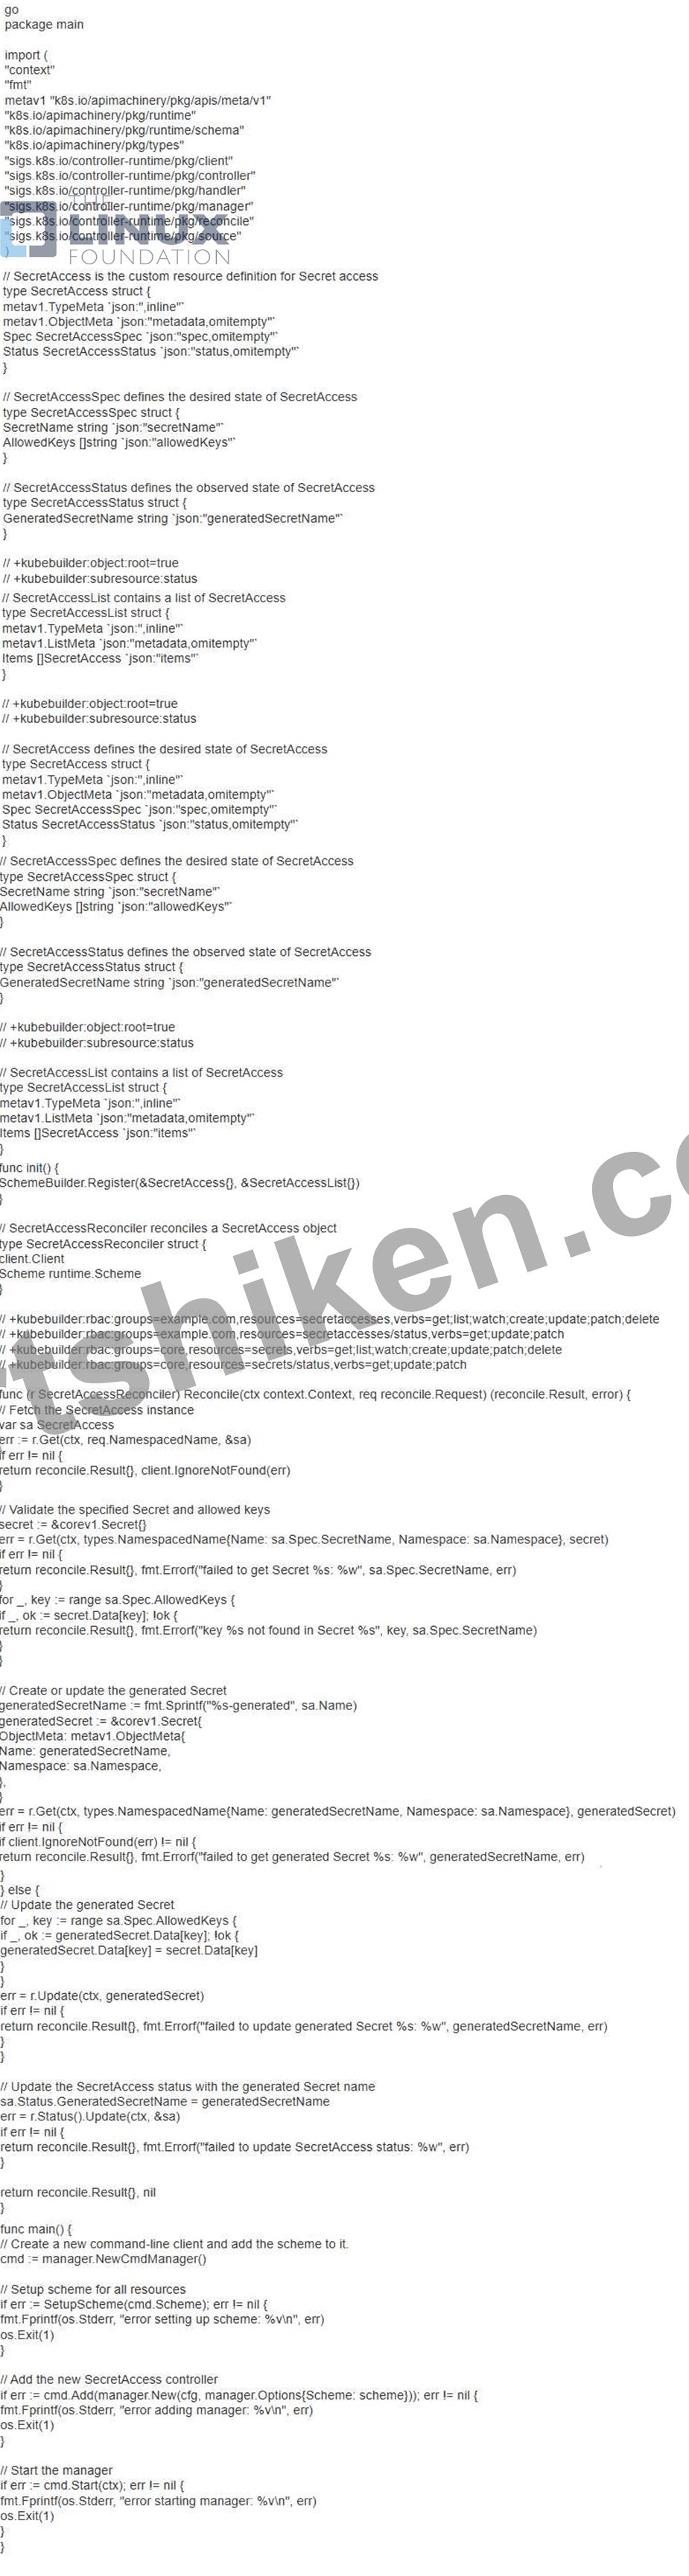
3. Create a SecretAccess Resource: - Define a 'SecretAccess' resource specifying the target Secret and allowed keys.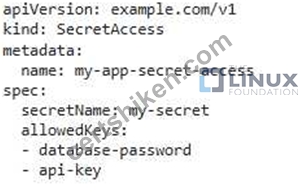
4. Update the Application to IJse the Generated Secret: - Modify your application to use the generated Secret, whiCh will contain only the allowed keys. - The generated Secret name can be retrieved from the "SecretAccess' resource status. - The application can access the Secret using the Kubernetes API, similar to accessing a regular Secret.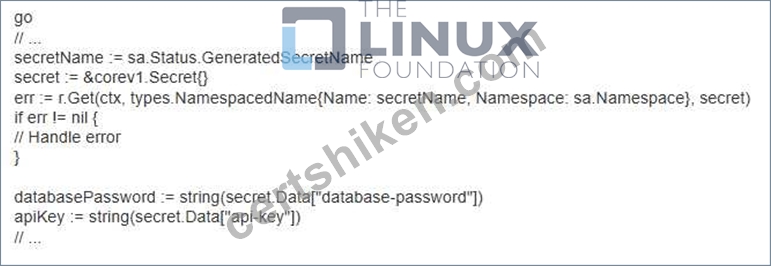
- The SecretAccesS CRD acts as a resource request for access to specific keys from a Secret_ - The controller ensures that only the requested keys are made available to the application, enhancing security. - By generating a separate Secret for each application with limited access, you prevent accidental exposure ot sensitive data. - The automated update mechanism of the controller allows you to update the original Secret without disrupting the application.,
質問 # 218
You have a Kubernetes deployment named 'wordpress-deployment' running multiple instances of a WordPress application. You want to implement a rolling update strategy with a 'maxSurge' of 1 and 'maxi-Jnavailable' of O. Additionally, you need to ensure that the update process is automatically triggered when a new image is pushed to the Docker Hub repository 'wordpress-image:latests. Implement a Kustomization file to achieve this.
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a 'kustomization.yamr file in your desired directory.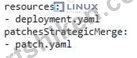
2. Create a 'deployment-yamr file (or use an existing one) with the following structure.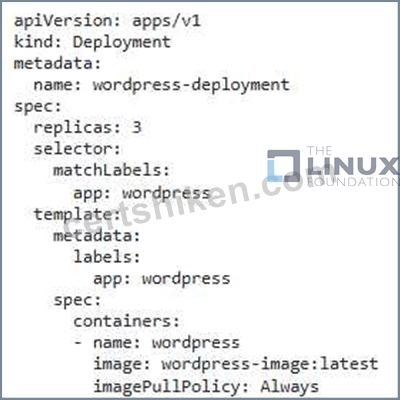
3. Create a 'patch.yamr file with the following content to configure rolling update and automatic updates: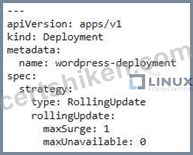
4. Apply the Kustomization: bash kubectl apply -k - The 'kustomization.yaml file defines the resources (the 'deployment.yamr file) and the patches to apply. - The 'deployment.yamr file contains the base configuration for the deployment. - The 'patch.yamr file applies a strategic merge patch to the deployment, configuring rolling updates and automatic updates triggered by new images. - The 'maxSurgew and 'maxunavailable' settings in the 'patch.yamr define the maximum number ot pods that can be added or removed during the update process. - The 'imagePullPolicy: AlwayS ensures that the new image is pulled from Docker Hub even if it exists in the pod's local cache, triggering the update.
質問 # 219
You are building a new web application that utilizes a microservice architecture- One of the microservices, 'recommendation-service', is responsible for providing personalized product recommendations to users.
This service uses a machine learning model for generating recommendations based on user purchase history and browsing behavior. The model is trained offline and its weights are stored in a 'model-store' service.
Design a mufti-container Pod for the 'recommendation-service' that incorporates the following considerations:
- The Pod should include a primary container for the 'recommendation-service' application.
- The Pod should include a secondary container that runs the 'model-store' service to provide access to the trained model weights.
- Both containers should share a common volume to ensure that the model weights are available to the 'recommendation-service' container-
- The recommendation-service' snould be able to access the model weignts from the 'model-store' container witnout relying on a network call to another service-
- The recommendation-service' container should be configured to periodically update the model weights from the 'model-store' container when a new version of the model is available.
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create the Deployment YAML:
- Define a Deployment with the name 'recommendation-service'
- Set the replicas to for redundancy and scalability.
- Specify the labels Sapp: recommendation-service' for selecting the Pods in the Deployment.
- Create a 'template' section to define the Pod specificatiom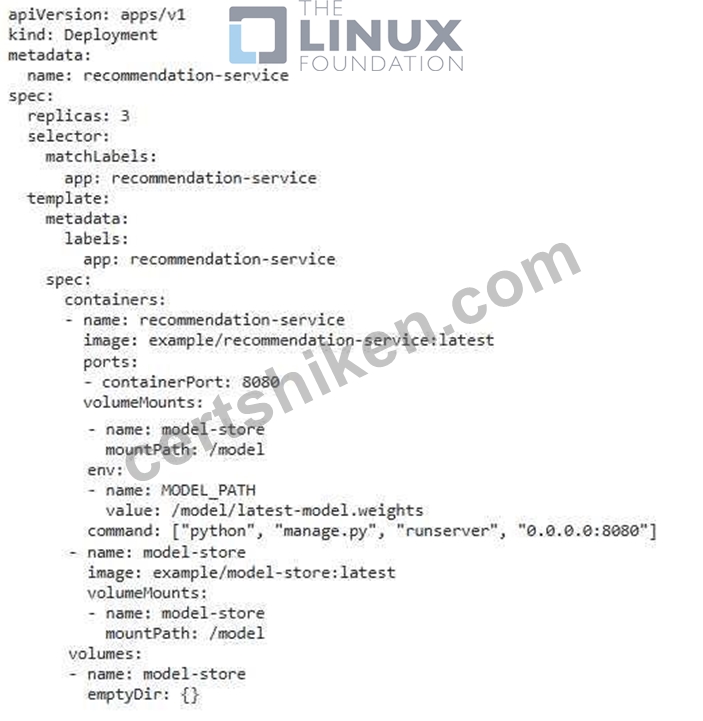
2. Deploy the Resources: - Apply the Deployment using 'kubectl apply -f deployment-yamp 3. Verify the Deployment: - Check the status of the Deployment using 'kubectl get deployments recommendation-service and ensure that three Pods are running. 4. Contigure the 'recommendation-service' - Modify the 'recommendation-service application to load the model weights from the specified path ClmodeVIatest-modeI_weightS). - Implement a mechanism within the 'recommendation-service to periodically check tor updated model weights in the shared volume. 5. Configure the 'model-store service: - Ensure that the model-store service is properly configured to store and retrieve the model weights. - Implement a mechanism in the 'model-store' service to notify the 'recommendation-service when a new model version is available. This notification can be achieved using a shared volume or a separate messaging system. 6. Test the Application: - Send requests to the 'recommendation-service' to generate recommendations. - Monitor the 'model-store' service and the shared volume to verify that the model weights are being updated correctly and the recommendation- service' is using the latest model version. Important Considerations: - Ensure that the 'recommendation-service' application is properly configured to access and load the model weights from the shared volume. - Implement a robust model management strategy, including versioning and rollback mechanisms, to ensure that the recommendation-service always uses the appropriate model. - Consider using a dedicated model store service that provides a dedicated API for retrieving and updating model weights. This can simplify the communication between the 'recommendation-service' and the model store. - Monitor the performance and resource usage of both services to ensure optimal performance.,
質問 # 220
Refer to Exhibit.
Context
You are asked to prepare a Canary deployment for testing a new application release.
Task:
A Service named krill-Service in the goshark namespace points to 5 pod created by the Deployment named current-krill-deployment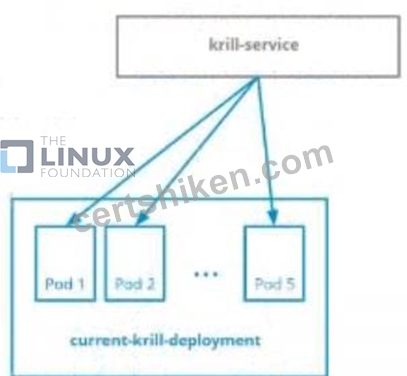
1) Create an identical Deployment named canary-kill-deployment, in the same namespace.
2) Modify the Deployment so that:
-A maximum number of 10 pods run in the goshawk namespace.
-40% of the krill-service 's traffic goes to the canary-krill-deployment pod(s)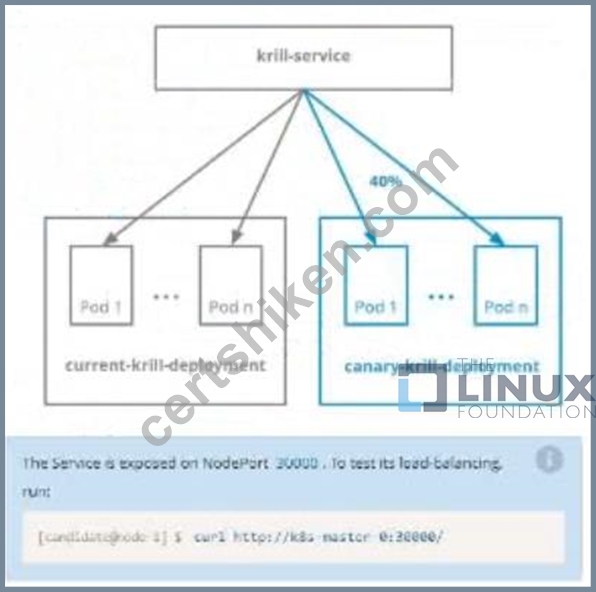
正解:
解説:
Solution: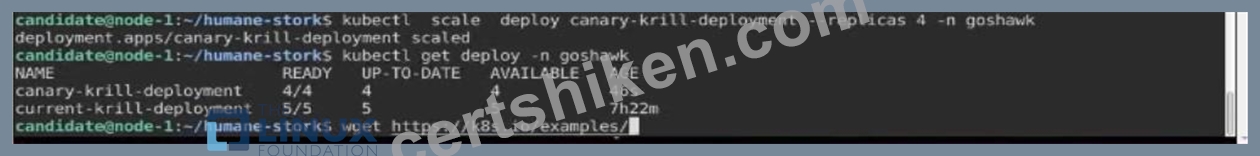
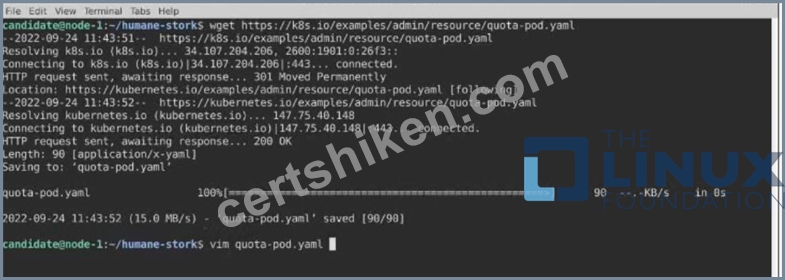
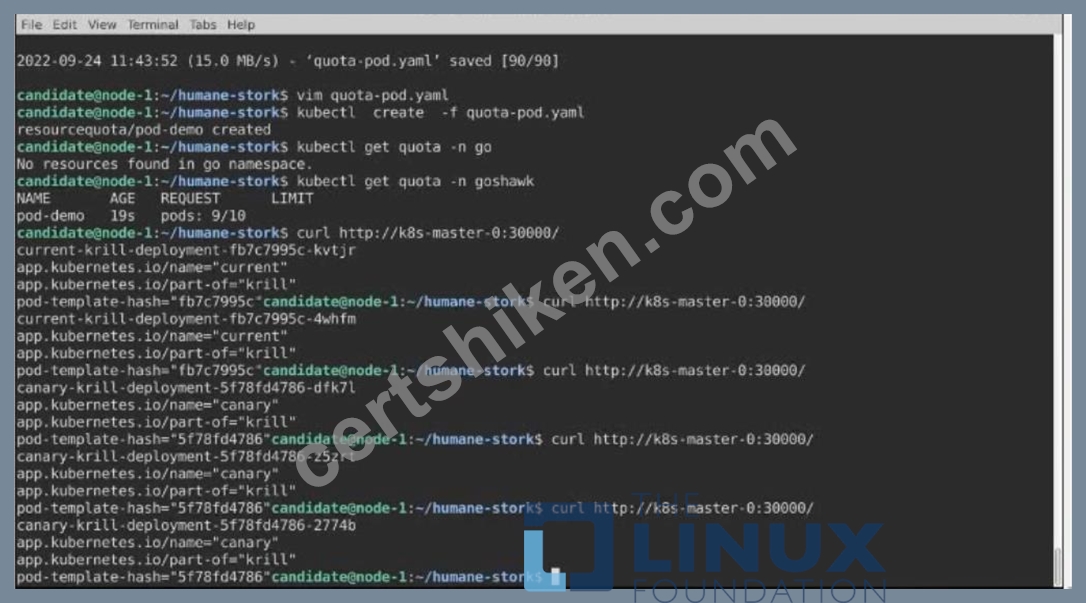
質問 # 221
You are working on a Kubernetes application that requires a scheduled job to run a data processing script every day at midnight. The script takes approximately 30 minutes to complete and requires access to a persistent volume to store its output dat a. How would you create a Job resource that meets these requirements?
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Create a Persistent Volume Claim:
- Define a Persistent Volume Claim (PVC) to request the necessary storage space.
- Specify the access mode and storage class according to your cluster configuration.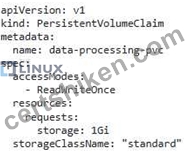
2. Define the Job Resource: - Create a Job resource With a 'cronJob' schedule to trigger the execution at midnight every day. - Specify the 'backoffLimit' to control the number of retries in case of failures. - Define the 'spec-template.spec.containers' section for the container running the data processing script. - Mount the PVC to the container using 'volumeMounts'.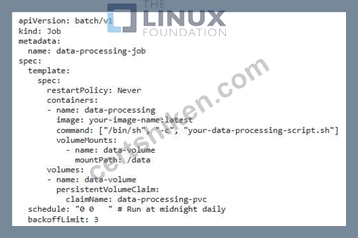
3. Create the Job: - Apply the Job YAML file using 'kubectl apply -f data-processing-job.yamr 4. Verify Job Execution: - Use 'kubectl get jobS to monitor the status of the Job. - Check the 'status. completionTime' to verify that the Job completed successfully. - Verity that the output data is stored in the mounted persistent volume. 5. Update the Script - Update the 'your-data-processing-script.sh" with the necessary commands to process the data and store the output in the "ldata' directory. 6. Monitor the Job: - Continuously monitor the Job's status and logs using 'kubectl logs' to ensure it runs correctly. Note: Replace 'your-image-namelatest and 'your-data-processing-scriptsh' with the actual image name and script file respectively,
質問 # 222
......
Linux Foundationは、短時間でCKAD認定を取得するために最善を尽くす必要があります。 認定資格を取得することが決まっている場合、CKAD質問トレントは喜んであなたに手を差し伸べます。 弊社のCKAD学習教材は、認定を取得するための最適な学習ツールになるためです。 ここで、CKAD試験問題を詳細に紹介します。紹介を注意深くお読みください。多くのメリットを得ることができます。 CKAD試験の資料に興味がある場合は、今すぐ購入できます。
CKAD技術試験: https://www.certshiken.com/CKAD-shiken.html
BONUS!!! CertShiken CKADダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1i8vpxzUaNbUKEhkeawZ8WSPsWLJyBKX2