BTW, DOWNLOAD part of Pass4suresVCE DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1DbITbhpCBAQ4kipohODjr7WKnmtZYiAX
Our products are officially certified, and our DP-750 exam materials are definitely the most authoritative product in the industry. In order to ensure the authority of our DP-750 practice prep, our company has really taken many measures. We have hired the most professioal experts to compile the content of the DP-750 study braindumps, and design the displays. So our DP-750 learning questions can stand the test of the market.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
>> DP-750 Exam Study Solutions <<
To make you capable of preparing for the Microsoft DP-750 exam smoothly, we provide actual Microsoft DP-750exam dumps. Hence, our accurate, reliable, and top-ranked Microsoft DP-750 exam questions will help you qualify for your Implementing Data Engineering Solutions Using Azure Databricks DP-750 Certification. Do not hesitate and check out Implementing Data Engineering Solutions Using Azure Databricks DP-750 practice exam to stand out from the rest of the others.
NEW QUESTION # 81
Drag and Drop Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
- asset_id
- asset_type
- asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.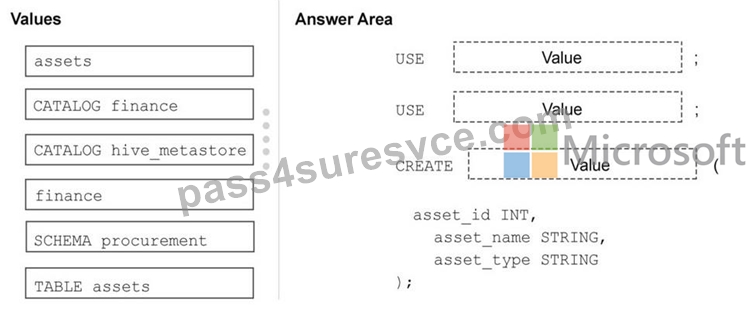
Answer:
Explanation: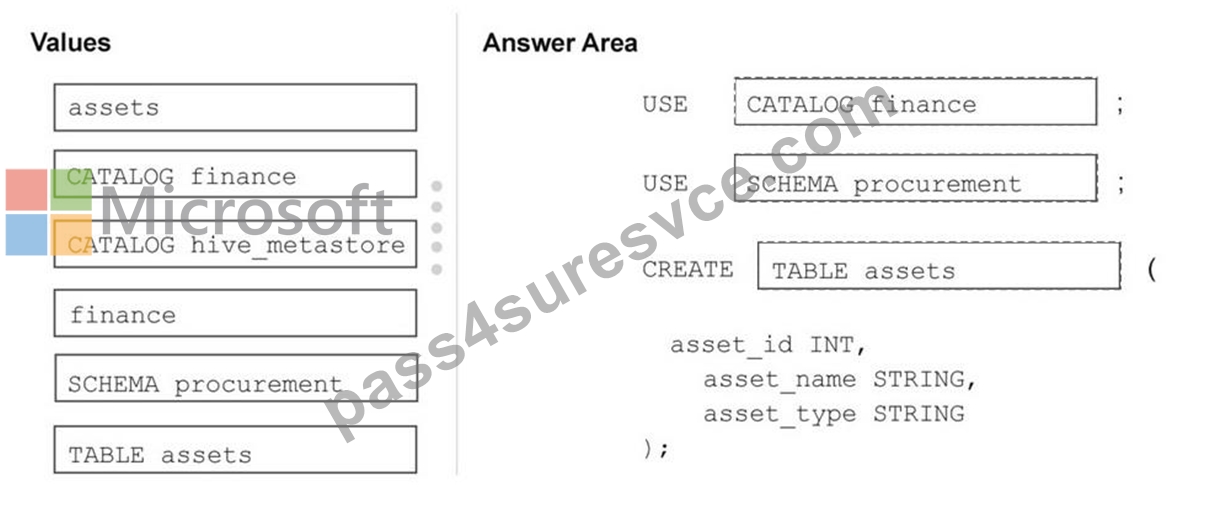
NEW QUESTION # 82
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 83
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
This is a common Python-to-PySpark trap. In pure Python, comparing a value to None with != works as expected. In PySpark, null comparisons follow SQL null semantics: any comparison involving NULL returns NULL (not True or False). So df.filter(df.order_amount != None) doesn't evaluate to True for non-null rows
- the comparison itself returns NULL for null values, and Spark interprets NULL in a filter as False, effectively dropping null rows. But the behaviour is undefined in edge cases and is not the documented approach.
More practically, Python's None and Spark's SQL NULL are different concepts. PySpark Column objects don't support Python's native equality/inequality semantics for null checking. The result is typically an empty DataFrame or incorrect filtering behaviour.
Always use .isNotNull() or .isNull() for null checks in PySpark column expressions. These methods are specifically designed for SQL-null-aware comparisons and produce correct, predictable results.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 84
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.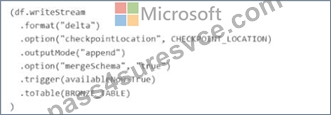
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.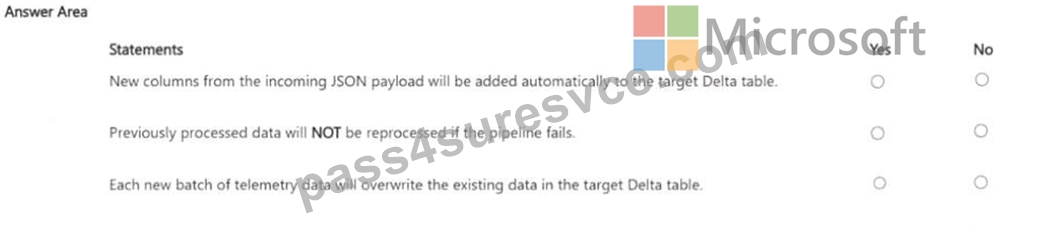
Answer:
Explanation: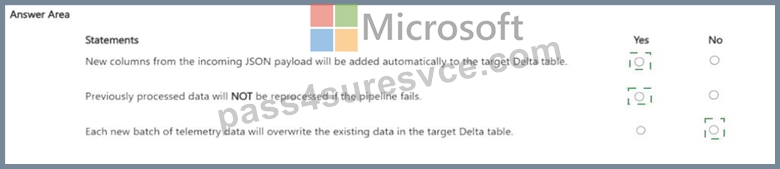
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 85
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 stores customer profile data.
Business users must analyze how customer profile records change over time. They must also be able to query earlier versions of the table.
You need to implement a solution that:
* Maintains persistent historical versions of customer profile records for long-term analysis.
* Allows users to query earlier versions of the Delta table.
* Minimizes maintenance effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.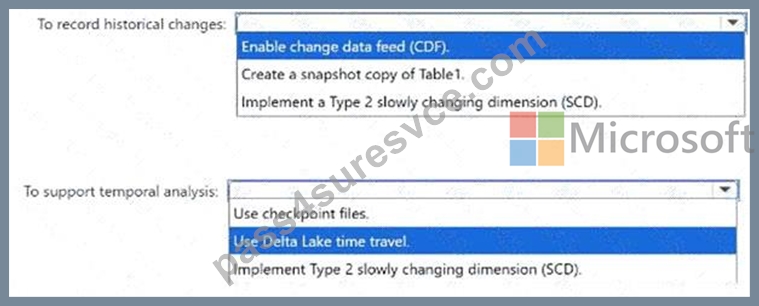
Answer:
Explanation: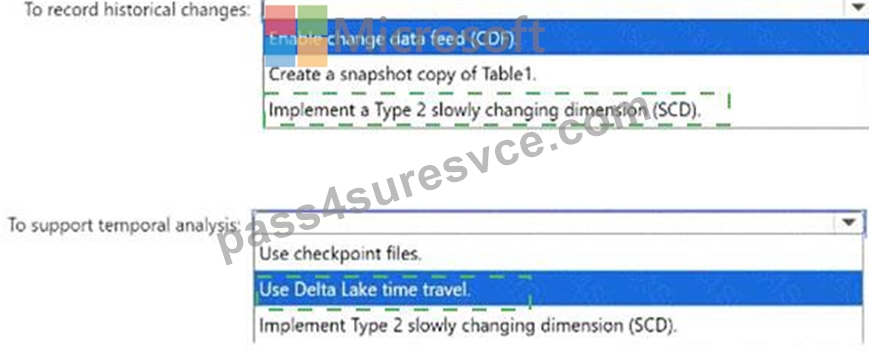
Explanation:
To record historical changes: Implement a Type 2 slowly changing dimension (SCD).
To support temporal analysis: Use Delta Lake time travel.
A Type 2 slowly changing dimension preserves customer-profile history by inserting a new record whenever a tracked attribute changes instead of overwriting the existing record. Effective dates, expiration dates, version values, or current-record indicators can identify which version applied during a particular period. This provides persistent business history for long-term analysis. Delta Lake time travel supports temporal analysis of the physical table by allowing users to query an earlier version with VERSION AS OF or TIMESTAMP AS OF. Time travel is useful for auditing and reproducing previous results, but its availability depends on retained Delta log entries and data files. Therefore, it should not replace a Type 2 SCD for permanent customer history. Together, the two features satisfy the historical-record and earlier-version requirements.
NEW QUESTION # 86
......
The successful outcomes are appreciable after you getting our DP-750 exam prep. After buying our DP-750 latest material, the change of gaining success will be over 98 percent. Many exam candidates ascribe their success to our DP-750 real questions and become our regular customers eventually. Rather than blindly assiduous hardworking for amassing knowledge of computer, you can achieve success skillfully. They are masterpieces of experts who are willing to offer the most effective and accurate DP-750 Latest Material for you.
Practice DP-750 Exams Free: https://www.pass4suresvce.com/DP-750-pass4sure-vce-dumps.html
DOWNLOAD the newest Pass4suresVCE DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1DbITbhpCBAQ4kipohODjr7WKnmtZYiAX