DP-100최신덤프공부자료덤프자료로Designing and Implementing a Data Science Solution on Azure시험패스가능

참고: DumpTOP에서 Google Drive로 공유하는 무료, 최신 DP-100 시험 문제집이 있습니다: https://drive.google.com/open?id=1HgTnqn__8ZBObzSQ2WX2MJaZ--EB5H6a
Microsoft DP-100시험이 정말 어렵다는 말을 많이 들으신 만큼 저희 DumpTOP는Microsoft DP-100덤프만 있으면Microsoft DP-100시험이 정말 쉬워진다고 전해드리고 싶습니다. Microsoft DP-100덤프로 시험패스하고 자격증 한방에 따보세요. 자격증 많이 취득하면 더욱 여유롭게 직장생활을 즐길수 있습니다.
Microsoft DP-100 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
- 1. Configure Azure AI Search
- 2. Prepare and process data
- 3. Create vector stores and indexes
- Implement generative AI solutions
- 1. Use Azure AI Foundry
- 2. Build prompt flows
- 3. Apply prompt engineering
- Evaluate and improve models
- 1. Apply responsible generative AI
- 2. Optimize for accuracy and safety
- 3. Test and evaluate responses
|
| Topic 2: Design and prepare a machine learning solution | 20-25% | - Manage Azure Machine Learning workspace
- 1. Set up Git integration
- 2. Create and configure workspace
- 3. Use developer tools and CLI
- 4. Work with registries
- Manage compute resources
- 1. Create and configure compute targets
- 2. Select environments
- 3. Attach and monitor compute
- Design a machine learning solution
- 1. Determine dataset structure and format
- 2. Define compute specifications for workloads
- 3. Select development approach
- 4. Plan model deployment requirements
- Manage data assets
- 1. Create and maintain data assets
- 2. Register and manage datastores
- 3. Select storage services
|
| Topic 3: Train and deploy models | 25-30% | - Manage models
- 1. Package and validate models
- 2. Register and version models
- 3. Interpret models and explain predictions
- Monitor and maintain models
- 1. Update and retrain models
- 2. Implement MLOps practices
- 3. Monitor performance and data drift
- Train models
- 1. Apply responsible AI principles
- 2. Use HyperDrive for hyperparameter tuning
- 3. Configure jobs and environments
- 4. Run training scripts
- Deploy models
- 1. Deploy to batch endpoints
- 2. Configure compute and scaling
- 3. Secure endpoints and manage access
- 4. Deploy to online endpoints
|
| Topic 4: Explore data and run experiments | 20-25% | - Implement pipelines
- 1. Pass data between steps
- 2. Schedule and monitor pipelines
- 3. Build reusable components
- 4. Create and publish pipelines
- Explore and visualize data
- 1. Identify features and relationships
- 2. Detect anomalies and outliers
- 3. Profile and validate data
- Run experiments
- 1. Configure experiment runs
- 2. Define parameters and configurations
- 3. Use automated machine learning
- 4. Track runs with MLflow
|
>> DP-100최신 덤프공부자료 <<
DP-100최신 덤프공부자료 100% 합격 보장 가능한 최신 덤프자료
Microsoft DP-100시험을 어떻게 패스할가 고민그만하시고 DumpTOP의Microsoft DP-100시험대비덤프를 데려가 주세요. 가격이 착한데 비해 너무나 훌륭한 덤프품질과 높은 적중율은 DumpTOP가 아닌 다른곳에서 찾아볼수 없는 혜택입니다. Microsoft DP-100 덤프구매전 데모부터 다운받아 공부해보세요.
최신 Microsoft Azure DP-100 무료샘플문제 (Q490-Q495):
질문 # 490
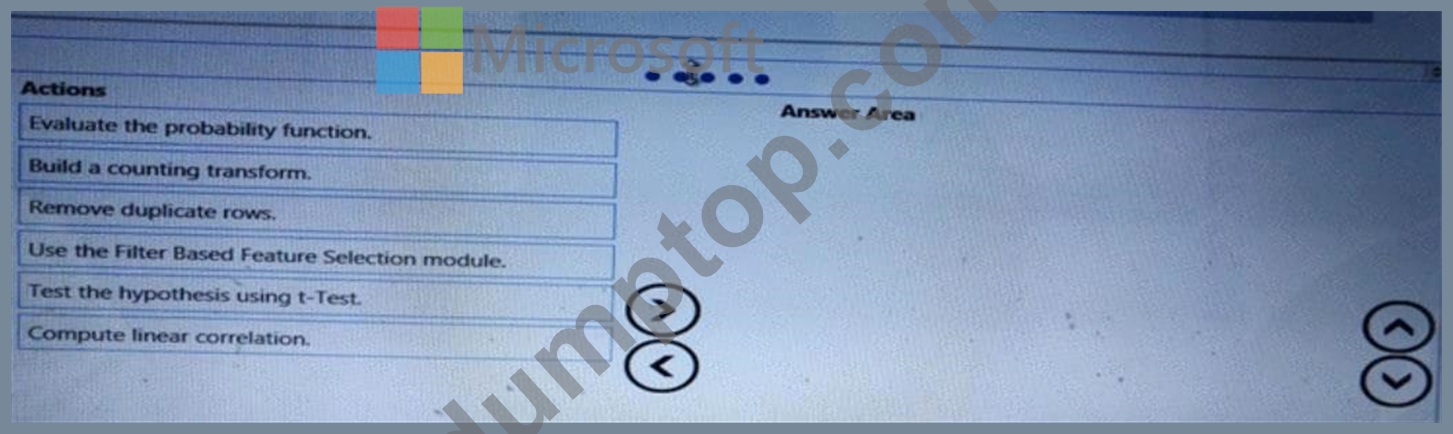
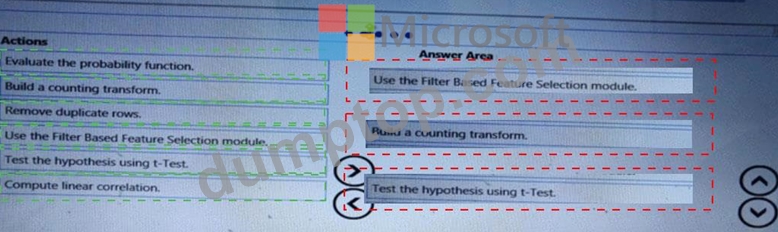
You are producing a multiple linear regression model in Azure Machine learning Studio.
Several independent variables are highly correlated.
You need to select appropriate methods for conducting elective feature engineering on all the data.
Which three actions should you perform in sequence? To answer, move the appropriate Actions from the list of actions to the answer area and arrange them in the correct order.
정답:
설명:
질문 # 491
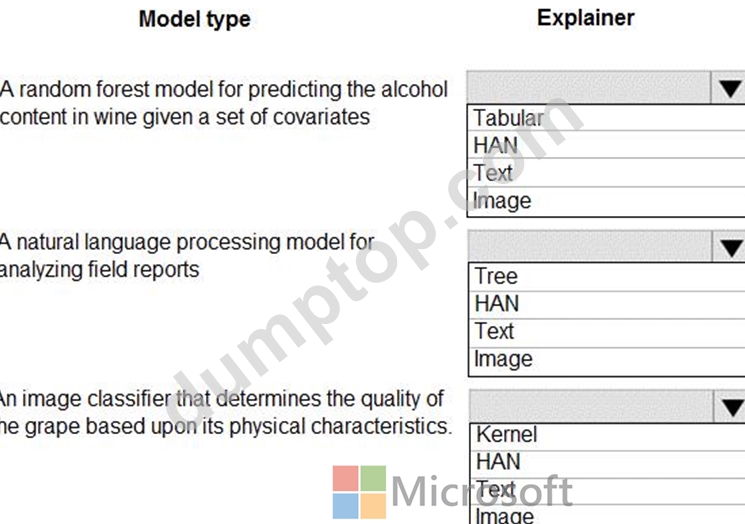
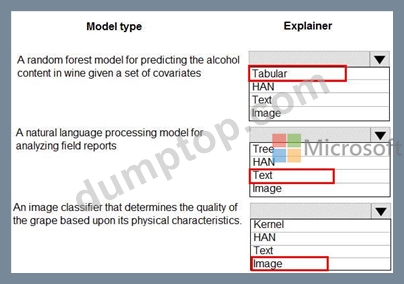
You are hired as a data scientist at a winery. The previous data scientist used Azure Machine Learning.
You need to review the models and explain how each model makes decisions.
Which explainer modules should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
정답:
설명:
Reference:
https://medium.com/microsoftazure/automated-and-interpretable-machine-learning-d07975741298
질문 # 492
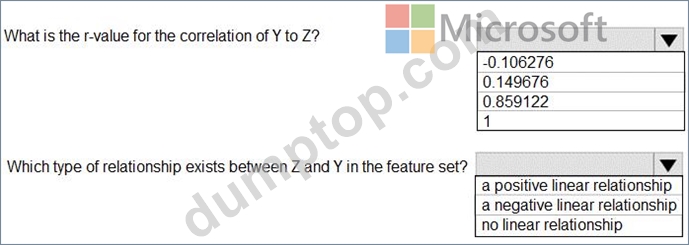
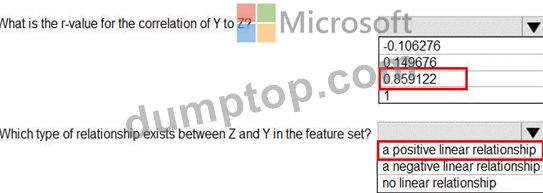
You have a feature set containing the following numerical features: X, Y, and Z.
The Poisson correlation coefficient (r-value) of X, Y, and Z features is shown in the following image:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
정답:
설명:
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation
질문 # 493
You are determining if two sets of data are significantly different from one another by using Azure Machine Learning Studio.
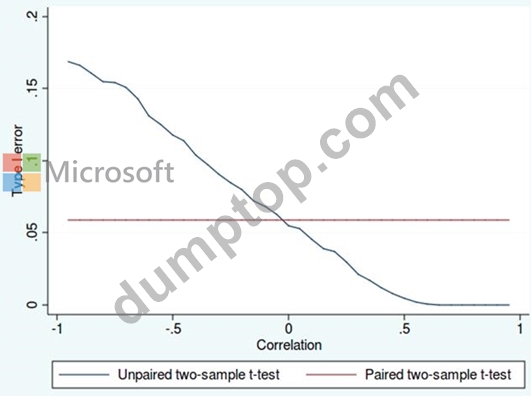
Estimated values in one set of data may be more than or less than reference values in the other set of data. You must produce a distribution that has a constant Type I error as a function of the correlation.
You need to produce the distribution.
Which type of distribution should you produce?
- A. Unpaired t-test with a one-tail option
- B. Paired t-test with a two-tail option
- C. Paired t-test with a one-tail option
- D. Unpaired t-test with a two tail option
정답:B
설명:
Choose a one-tail or two-tail test. The default is a two-tailed test. This is the most common type of test, in which the expected distribution is symmetric around zero.
Example: Type I error of unpaired and paired two-sample t-tests as a function of the correlation. The simulated random numbers originate from a bivariate normal distribution with a variance of 1.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/test-hypothesis-using-t-test
https://en.wikipedia.org/wiki/Student%27s_t-test
질문 # 494
You are analyzing a raw dataset that requires cleaning.
You must perform transformations and manipulations by using Azure Machine Learning Studio.
You need to identify the correct modules to perform the transformations.
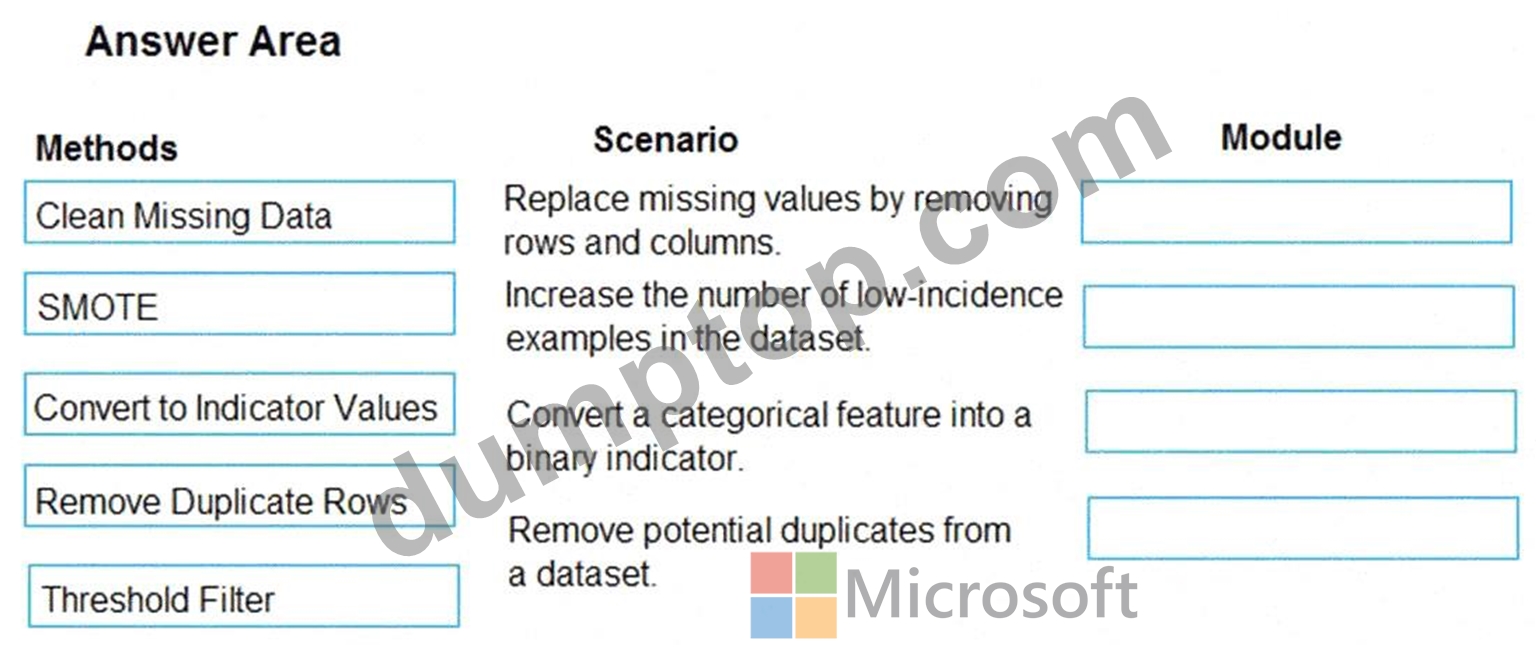
Which modules should you choose? To answer, drag the appropriate modules to the correct scenarios. Each module may be used once, more than once, or not at all.
You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
정답:
설명:
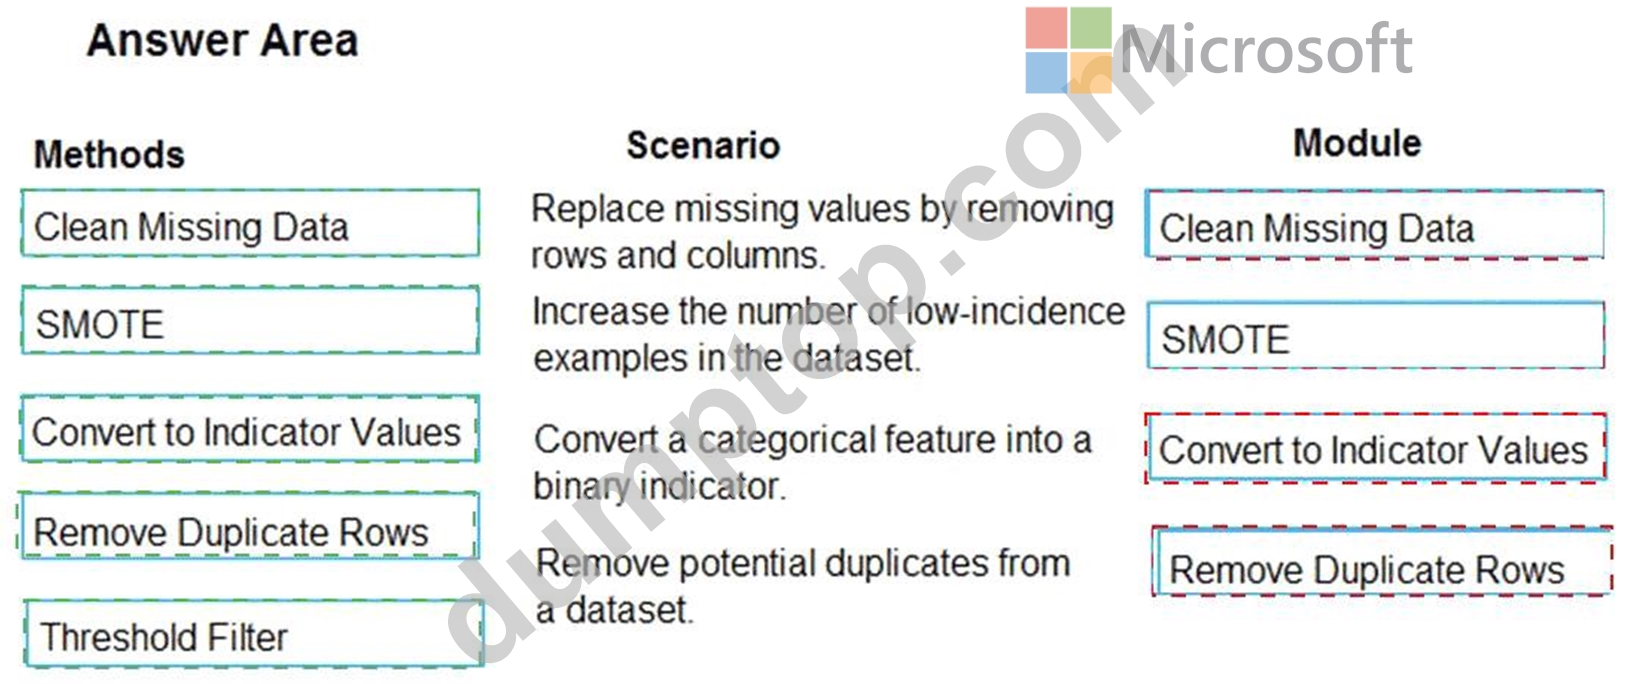
Explanation:
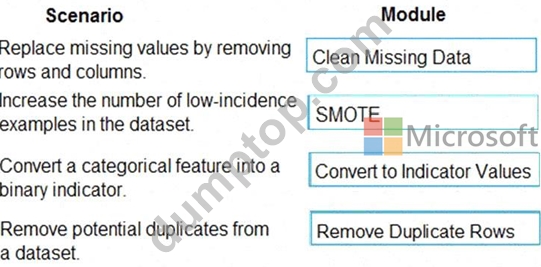
Box 1: Clean Missing Data
Box 2: SMOTE
Use the SMOTE module in Azure Machine Learning Studio to increase the number of underepresented cases in a dataset used for machine learning. SMOTE is a better way of increasing the number of rare cases than simply duplicating existing cases.
Box 3: Convert to Indicator Values
Use the Convert to Indicator Values module in Azure Machine Learning Studio. The purpose of this module is to convert columns that contain categorical values into a series of binary indicator columns that can more easily be used as features in a machine learning model.
Box 4: Remove Duplicate Rows
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/convert-to-indicator-values
질문 # 495
......
Microsoft DP-100 시험환경에 적응하고 싶은 분은 pdf버전 구매시 온라인버전 또는 테스트엔진 버전을 추가구매하시면 됩니다. 문제는 pdf버전의 문제와 같지만 pdf버전의 문제를 마스터한후 실력테스 가능한 프로그램이기에Microsoft DP-100시험환경에 익숙해져 시험을 보다 릴렉스한 상태에서 볼수 있습니다.
DP-100최신 시험대비자료: https://www.dumptop.com/Microsoft/DP-100-dump.html
- DP-100최신 덤프공부자료 최신버전 덤프 🎽 《 www.exampassdump.com 》웹사이트에서“ DP-100 ”를 열고 검색하여 무료 다운로드DP-100최고덤프
- DP-100최신 덤프공부자료 최신버전 덤프 🌶 지금➡ www.itdumpskr.com ️⬅️에서➡ DP-100 ️⬅️를 검색하고 무료로 다운로드하세요DP-100시험패스 가능한 인증덤프
- 시험대비 DP-100최신 덤프공부자료 최신버전 자료 😎 ➽ www.koreadumps.com 🢪을 통해 쉽게{ DP-100 }무료 다운로드 받기DP-100인증덤프 샘플체험
- DP-100최신 덤프데모 다운 👙 DP-100시험대비 덤프자료 🤧 DP-100높은 통과율 시험대비자료 🌱 무료로 쉽게 다운로드하려면➠ www.itdumpskr.com 🠰에서➽ DP-100 🢪를 검색하세요DP-100인증덤프 샘플체험
- 시험대비 DP-100최신 덤프공부자료 최신버전 자료 👇 오픈 웹 사이트“ www.passtip.net ”검색✔ DP-100 ️✔️무료 다운로드DP-100시험덤프자료
- DP-100덤프최신자료 💹 DP-100시험대비 덤프자료 🤿 DP-100시험준비공부 🍂 오픈 웹 사이트“ www.itdumpskr.com ”검색[ DP-100 ]무료 다운로드DP-100최신 인증시험 덤프데모
- DP-100시험합격 🤫 DP-100최신 업데이트버전 덤프공부 💱 DP-100퍼펙트 공부문제 🗺 「 www.koreadumps.com 」웹사이트에서[ DP-100 ]를 열고 검색하여 무료 다운로드DP-100최고덤프
- DP-100최신 덤프공부자료 시험준비에 가장 좋은 인기시험 기출문제모음 🧅 시험 자료를 무료로 다운로드하려면➡ www.itdumpskr.com ️⬅️을 통해⇛ DP-100 ⇚를 검색하십시오DP-100시험대비 덤프자료
- DP-100최신 덤프공부자료 최신버전 덤프 ⏯ 시험 자료를 무료로 다운로드하려면➽ www.dumptop.com 🢪을 통해⇛ DP-100 ⇚를 검색하십시오DP-100덤프최신자료
- DP-100덤프최신자료 🍹 DP-100인증덤프 샘플체험 🥺 DP-100최신 덤프데모 다운 🍍 ➠ www.itdumpskr.com 🠰의 무료 다운로드▷ DP-100 ◁페이지가 지금 열립니다DP-100최신 업데이트버전 덤프공부
- DP-100최신 덤프공부자료 시험준비에 가장 좋은 인기시험 기출문제모음 🌍 ▛ DP-100 ▟를 무료로 다운로드하려면《 kr.fast2test.com 》웹사이트를 입력하세요DP-100최신 업데이트버전 인증시험자료
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
그리고 DumpTOP DP-100 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1HgTnqn__8ZBObzSQ2WX2MJaZ--EB5H6a