Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern - Databricks-Certified-Data-Engineer-Professional Reliable Exam Practice
Now, let us show you why our Databricks-Certified-Data-Engineer-Professional exam questions are absolutely your good option. First of all, in accordance to the fast-pace changes of bank market, we follow the trend and provide the latest version of Databricks-Certified-Data-Engineer-Professional study materials to make sure you learn more knowledge. Secondly, since our Databricks-Certified-Data-Engineer-Professional training quiz appeared on the market, seldom do we have the cases of customer information disclosure. We really do a great job in this career!
| Section | Weight | Objectives |
|---|
| Topic 1: Monitoring and Alerting | 10% | - Set up alerts and notifications
- Track data lineage and metrics
- Monitor pipeline performance and health
|
| Topic 2: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Implement access control and permissions
- Secure data at rest and in transit
|
| Topic 3: Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Troubleshoot and debug pipelines
- Deploy using Asset Bundles, CLI, and APIs
|
| Topic 4: Data Governance | 7% | - Manage data assets and metadata
- Use Unity Catalog for governance
- Enforce data policies and standards
|
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code
- Implement complex data processing logic
- Use Databricks-specific libraries and APIs
|
| Topic 6: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management
- Apply data cleansing and validation rules
- Enforce data quality standards
|
| Topic 7: Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Implement Lakehouse Federation
- Manage cross-platform data access
|
| Topic 8: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance
- Apply cost management best practices
- Optimize compute and storage resources
|
| Topic 9: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources
- Handle incremental and batch data loads
- Use Auto Loader and structured streaming
|
| Topic 10: Data Modelling | 6% | - Implement dimensional and relational models
- Optimize table design and partitioning
- Design Medallion Architecture
|
>> Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern <<
Free PDF 2026 Fantastic Databricks Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern
The evergreen field of Databricks is so attractive that it provides non-stop possibilities for the one who passes the Databricks Databricks-Certified-Data-Engineer-Professional exam. So, to be there on top of the IT sector, earning the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification is essential. Because of using outdated Databricks-Certified-Data-Engineer-Professional Study Material, many candidates don't get success in the Databricks-Certified-Data-Engineer-Professional exam and lose their resources. The Databricks-Certified-Data-Engineer-Professional PDF Questions of ActualTorrent are authentic and real.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q216-Q221):
NEW QUESTION # 216
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
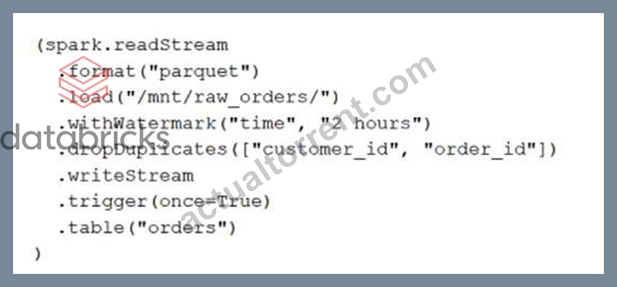
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- B. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- C. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- D. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- E. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
Answer: B
NEW QUESTION # 217
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
- A. validateSchema = false
- B. mergeSchema = true
- C. overwriteSchema = true
- D. ignoreChanges = false
Answer: B
Explanation:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
NEW QUESTION # 218
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
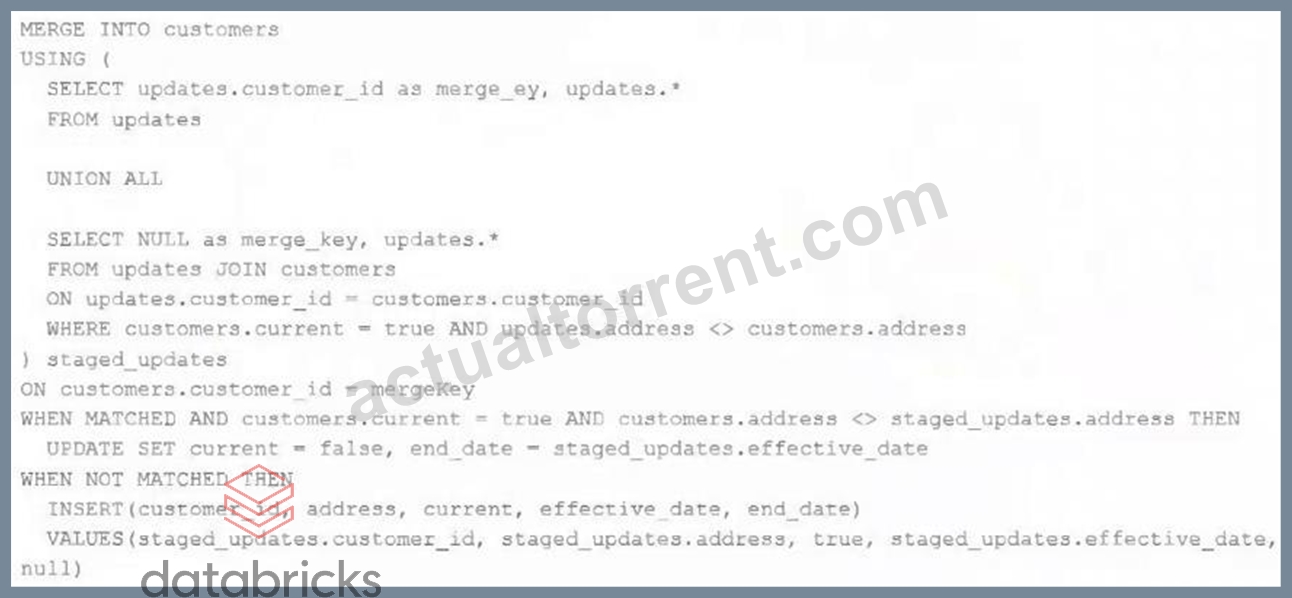
Which statement describes this implementation?
- A. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
- B. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
Answer: C
NEW QUESTION # 219
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Share the analysis with the failing notebook owner so that they can fix it quickly.
- B. Repair the run with the new parameter.
- C. Repair the run with the new parameter, and update the task by adding the missing task parameter.
- D. Update the task by adding the missing task parameter, and manually run the job.
Answer: C
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 220
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- B. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
- C. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- D. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- E. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
Answer: C
Explanation:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
NEW QUESTION # 221
......
Professional ability is very important both for the students and for the in-service staff because it proves their practical ability in the area they major in. Therefore choosing a certificate exam which boosts great values to attend is extremely important for them and the test Databricks certification is one of them. Passing the test certification can prove your outstanding major ability in some area and if you want to pass the test smoothly you’d better buy our Databricks-Certified-Data-Engineer-Professional Test Guide. We only use the certificated experts and published authors to compile our study materials and our products boost the practice test software to test the clients’ ability to answer the questions. The clients can firstly be familiar with our products in detail and then make their decisions to buy it or not.
Databricks-Certified-Data-Engineer-Professional Reliable Exam Practice: https://www.actualtorrent.com/Databricks-Certified-Data-Engineer-Professional-questions-answers.html
- Reliable Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern Spend Your Little Time and Energy to Pass Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam exam 🍐 [ www.prepawaypdf.com ] is best website to obtain “ Databricks-Certified-Data-Engineer-Professional ” for free download 😖Databricks-Certified-Data-Engineer-Professional Guaranteed Success
- Examcollection Databricks-Certified-Data-Engineer-Professional Questions Answers 🥬 Upgrade Databricks-Certified-Data-Engineer-Professional Dumps 😩 Databricks-Certified-Data-Engineer-Professional Brain Dump Free 💿 Go to website “ www.pdfvce.com ” open and search for { Databricks-Certified-Data-Engineer-Professional } to download for free 🥌Examcollection Databricks-Certified-Data-Engineer-Professional Questions Answers
- Top Databricks-Certified-Data-Engineer-Professional Dumps ♿ Latest Databricks-Certified-Data-Engineer-Professional Test Guide 🕤 Databricks-Certified-Data-Engineer-Professional Guaranteed Success 🕦 Open website ➤ www.troytecdumps.com ⮘ and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free download 🌖Databricks-Certified-Data-Engineer-Professional Brain Dump Free
- 100% Pass Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Authoritative Latest Exam Pattern 🗳 Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and obtain a free download on 【 www.pdfvce.com 】 🏀Latest Databricks-Certified-Data-Engineer-Professional Test Guide
- Valid Databricks-Certified-Data-Engineer-Professional Study Guide 🟣 Valid Databricks-Certified-Data-Engineer-Professional Study Guide 🥮 Databricks-Certified-Data-Engineer-Professional Latest Dumps Sheet 🛰 Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and download it for free on ⏩ www.testkingpass.com ⏪ website ☂Reliable Databricks-Certified-Data-Engineer-Professional Test Labs
- Upgrade Databricks-Certified-Data-Engineer-Professional Dumps 💱 Reliable Databricks-Certified-Data-Engineer-Professional Test Tips 🤪 Databricks-Certified-Data-Engineer-Professional Guaranteed Success 🏀 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 and download exam materials for free through 【 www.pdfvce.com 】 🐠Examcollection Databricks-Certified-Data-Engineer-Professional Questions Answers
- Reliable Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern Spend Your Little Time and Energy to Pass Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam exam 📡 Immediately open 《 www.examdiscuss.com 》 and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to obtain a free download 🚾Databricks-Certified-Data-Engineer-Professional Brain Dump Free
- Latest Databricks-Certified-Data-Engineer-Professional Exam Pattern - Valid Databricks Databricks Certified Data Engineer Professional Exam - Databricks-Certified-Data-Engineer-Professional Reliable Exam Practice ⭐ Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and download exam materials for free through ▶ www.pdfvce.com ◀ 😇Upgrade Databricks-Certified-Data-Engineer-Professional Dumps
- 2026 Databricks Databricks-Certified-Data-Engineer-Professional: High-quality Latest Databricks Certified Data Engineer Professional Exam Exam Pattern 🐭 Copy URL ▶ www.exam4labs.com ◀ open and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to download for free ✈Upgrade Databricks-Certified-Data-Engineer-Professional Dumps
- Valid Databricks-Certified-Data-Engineer-Professional Exam Review 🥃 Databricks-Certified-Data-Engineer-Professional Reliable Dump 🐾 New Databricks-Certified-Data-Engineer-Professional Exam Dumps ✏ Download ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free by simply searching on ➤ www.pdfvce.com ⮘ 👍Online Databricks-Certified-Data-Engineer-Professional Training
- Valid Databricks-Certified-Data-Engineer-Professional Exam Review 💇 Reliable Databricks-Certified-Data-Engineer-Professional Test Labs 🧉 Valid Databricks-Certified-Data-Engineer-Professional Study Guide 🥀 Go to website ☀ www.troytecdumps.com ️☀️ open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 🐋Databricks-Certified-Data-Engineer-Professional Brain Dump Free
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.scener.com, mahsaamini5421.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes