P.S. JPNTestがGoogle Driveで共有している無料かつ新しいData-Engineer-Associateダンプ:https://drive.google.com/open?id=1cf-M6DeNxaD-RVmxxkDrvfo13XzGtTKT
人生は自転車に乗ると似ていて、やめない限り、倒れないから。IT技術職員として、周りの人はAmazon Data-Engineer-Associate試験に合格し高い月給を持って、上司からご格別の愛護を賜り更なるジョブプロモーションを期待されますけど、あんたはこういうように所有したいますか。変化を期待したいあなたにAmazon Data-Engineer-Associate試験備考資料を提供する権威性のあるJPNTestをお勧めさせていただけませんか。
| Section | Weight | Objectives |
|---|---|---|
| Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Data Operations and Support | 22% | - Troubleshoot data workflow issues - Monitor and maintain data pipelines |
>> Data-Engineer-Associate合格体験談 <<
合格できるAmazon AWS Certified Data Engineer - Associate (DEA-C01)試験はいくつありますか? それらをすべて試してみてください! JPNTestは、AWS Certified Data Engineer - Associate (DEA-C01) コーススペシャリストが開発した実際のAmazon Data-Engineer-Associateの回答を含むAWS Certified Data Engineer - Associate (DEA-C01) Data-Engineer-Associate試験問題への完全なアクセス権をUnlimited Access Planに提示します。 Amazon AWS Certified Data Engineer - Associate (DEA-C01)テストに合格できるだけでなく、さらに良くなります! また、すべての試験の質問と回答にアクセスして、合計1800以上の試験に合格することもできます。
質問 # 303
A data engineer is launching an Amazon EMR duster. The data that the data engineer needs to load into the new cluster is currently in an Amazon S3 bucket. The data engineer needs to ensure that data is encrypted both at rest and in transit.
The data that is in the S3 bucket is encrypted by an AWS Key Management Service (AWS KMS) key. The data engineer has an Amazon S3 path that has a Privacy Enhanced Mail (PEM) file.
Which solution will meet these requirements?
正解:D
解説:
The data engineer needs to ensure that the data in an Amazon EMR cluster is encrypted both at rest and in transit. The data in Amazon S3 is already encrypted using an AWS KMS key. To meet the requirements, the most suitable solution is to create an EMR security configuration that specifies the correct KMS key for at- rest encryption and use the PEM file for in-transit encryption.
Option C: Create an Amazon EMR security configuration. Specify the appropriate AWS KMS key for at-rest encryption for the S3 bucket. Specify the Amazon S3 path of the PEM file for in-transit encryption. Use the security configuration during EMR cluster creation.This option configures encryption for both data at rest (using KMS keys) and data in transit (using the PEM file for SSL/TLS encryption). This approach ensures that data is fully protected during storage and transfer.
Options A, B, and D either involve creating unnecessary additional security configurations or make inaccurate assumptions about the way encryption configurations are attached.
References:
Amazon EMR Security Configuration
Amazon S3 Encryption
質問 # 304
A data engineer is launching an Amazon EMR cluster. The data that the data engineer needs to load into the new cluster is currently in an Amazon S3 bucket. The data engineer needs to ensure that data is encrypted both at rest and in transit.
The data that is in the S3 bucket is encrypted by an AWS Key Management Service (AWS KMS) key. The data engineer has an Amazon S3 path that has a Privacy Enhanced Mail (PEM) file.
Which solution will meet these requirements?
正解:D
解説:
To meet both encryption at rest and in transit, a single Amazon EMR security configuration can be created specifying the AWS KMS key for encryption at rest and the PEM file for in-transit encryption. The study guide clearly states:
"AWS Key Management Service (KMS) provides encryption for data at rest, and SSL/TLS ensures encryption for data in transit, providing end-to-end encryption within an AWS environment."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf A single security configuration is sufficient and the cleanest way to apply these security features during EMR cluster setup.
質問 # 305
A gaming company uses Amazon Kinesis Data Streams to collect clickstream data. The company uses Amazon Kinesis Data Firehose delivery streams to store the data in JSON format in Amazon S3. Data scientists at the company use Amazon Athena to query the most recent data to obtain business insights.
The company wants to reduce Athena costs but does not want to recreate the data pipeline.
Which solution will meet these requirements with the LEAST management effort?
正解:B
解説:
Step 1: Understanding the Problem
The company collectsclickstream datavia Amazon Kinesis Data Streams and stores it inJSON formatin Amazon S3 using Kinesis Data Firehose. They useAmazon Athenato query the data, but they want toreduce Athena costswhile maintaining the same data pipeline.
Since Athena charges based on the amount of data scanned during queries, reducing the data size (by converting JSON to a more efficient format likeApache Parquet) is a key solution to lowering costs.
Step 2: Why Option A is Correct
* Option Aprovides a straightforward way to reduce costs withminimal management overhead:
* Changing the Firehose output format to Parquet: Parquet is a columnar data format, which is more compact and efficient than JSON for Athena queries. It significantly reduces the amount of data scanned, which in turn reduces Athena query costs.
* Custom S3 Object Prefix (YYYYMMDD): Adding a date-based prefix helps in partitioning the data, which further improves query efficiency in Athena by limiting the data scanned to only relevant partitions.
* AWS Glue ETL Job for Existing Data: To handle existing data stored in JSON format, a one- time AWS Glue ETL job can combine small JSON files, convert them to Parquet, and apply the YYYYMMDD prefix. This ensures consistency in the S3 bucket structure and allows Athena to efficiently query historical data.
* ALTER TABLE ADD PARTITION: This command updates Athena's table metadata to reflect the new partitions, ensuring that future queries target only the required data.
Step 3: Why Other Options Are Not Ideal
* Option B (Apache Spark on EMR)introduces higher management effort by requiring the setup of Apache Spark jobsand anAmazon EMR cluster. While it achieves the goal of converting JSON to Parquet, it involves running and maintaining an EMR cluster, which adds operational complexity.
* Option C (Kinesis and Apache Flink)is a more complex solution involvingApache Flink, which adds a real-time streaming layer to aggregate data. Although Flink is a powerful tool for stream processing, it adds unnecessary overhead in this scenario since the company already uses Kinesis Data Firehose for batch delivery to S3.
* Option D (AWS Lambda with Firehose)suggests usingAWS Lambdato convert records in real time.
While Lambda can work in some cases, it's generally not the best tool for handling large-scale data transformations like JSON-to-Parquet conversion due to potential scaling and invocation limitations.
Additionally, running parallel Glue jobs further complicates the setup.
Step 4: How Option A Minimizes Costs
* By usingApache Parquet, Athena queries become more efficient, as Athena will scan significantly less data, directly reducing query costs.
* Firehosenatively supports Parquet as an output format, so enabling this conversion in Firehose requires minimal effort. Once set, new data will automatically be stored in Parquet format in S3, without requiring any custom coding or ongoing management.
* TheAWS Glue ETL jobfor historical data ensures that existing JSON files are also converted to Parquet format, ensuring consistency across the data stored in S3.
Conclusion:
Option A meets the requirement toreduce Athena costswithout recreating the data pipeline, using Firehose's native support forApache Parquetand a simple one-timeAWS Glue ETL jobfor existing data. This approach involvesminimal management effortcompared to the other solutions.
質問 # 306
A company receives .csv files that contain physical address dat
a. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: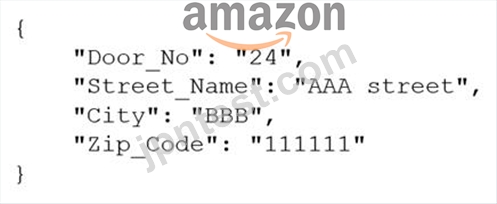
Which solution will meet this requirement with the LEAST coding effort?
正解:A
解説:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. Reference:
7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns) NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
質問 # 307
A financial company wants to use Amazon Athena to run on-demand SQL queries on a petabyte-scale dataset to support a business intelligence (BI) application. An AWS Glue job that runs during non-business hours updates the dataset once every day. The BI application has a standard data refresh frequency of 1 hour to comply with company policies.
A data engineer wants to cost optimize the company's use of Amazon Athena without adding any additional infrastructure costs.
Which solution will meet these requirements with the LEAST operational overhead?
正解:A
解説:
The best solution to cost optimize the company's use of Amazon Athena without adding any additional infrastructure costs is to use the query result reuse feature of AmazonAthena for the SQL queries. This feature allows you to run the same query multiple times without incurring additional charges, as long as the underlying data has not changed and the query results are still in the query result location in Amazon S31. This feature is useful for scenarios where you have a petabyte-scale dataset that is updated infrequently, such as once a day, and you have a BI application that runs the same queries repeatedly, such as every hour. By using the query result reuse feature, you can reduce the amount of data scanned by your queries and save on the cost of running Athena. You can enable or disable this feature at the workgroup level or at the individual query level1.
Option A is not the best solution, as configuring an Amazon S3 Lifecycle policy to move data to the S3 Glacier Deep Archive storage class after 1 day would not cost optimize the company's use of Amazon Athena, but rather increase the cost and complexity. Amazon S3 Lifecycle policies are rules that you can define to automatically transition objects between different storage classes based on specified criteria, such as the age of the object2. S3 Glacier Deep Archive is the lowest-cost storage class in Amazon S3, designed for long-term data archiving that is accessed once or twice in a year3. While moving data to S3 Glacier Deep Archive can reduce the storage cost, it would also increase the retrieval cost and latency, as it takes up to 12 hours to restore the data from S3 Glacier Deep Archive3. Moreover, Athena does not support querying data that is in S3 Glacier or S3 Glacier Deep Archive storage classes4. Therefore, using this option would not meet the requirements of running on-demand SQL queries on the dataset.
Option C is not the best solution, as adding an Amazon ElastiCache cluster between the BI application and Athena would not cost optimize the company's use of Amazon Athena, but rather increase the cost and complexity. Amazon ElastiCache is a service that offers fully managed in-memory data stores, such as Redis and Memcached, that can improve the performance and scalability of web applications by caching frequently accessed data. While using ElastiCache can reduce the latency and load on the BI application, it would not reduce the amount of data scanned by Athena, which is the main factor that determines the cost of running Athena. Moreover, using ElastiCache would introduce additional infrastructure costs and operational overhead, as you would have to provision, manage, and scale the ElastiCache cluster, and integrate it with the BI application and Athena.
Option D is not the best solution, as changing the format of the files that are in the dataset to Apache Parquet would not cost optimize the company's use of Amazon Athena without adding any additional infrastructure costs, but rather increase the complexity. Apache Parquet is a columnar storage format that can improve the performance of analytical queries by reducing the amount of data that needs to be scanned and providing efficient compression and encoding schemes. However,changing the format of the files that are in the dataset to Apache Parquet would require additional processing and transformation steps, such as using AWS Glue or Amazon EMR to convert the files from their original format to Parquet, and storing the converted files in a separate location in Amazon S3. This would increase the complexity and the operational overhead of the data pipeline, and also incur additional costs for using AWS Glue or Amazon EMR. References:
Query result reuse
Amazon S3 Lifecycle
S3 Glacier Deep Archive
Storage classes supported by Athena
[What is Amazon ElastiCache?]
[Amazon Athena pricing]
[Columnar Storage Formats]
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
質問 # 308
......
IT業種を選んだあなたは現状に自己満足することはきっとないですね。現在、どの業種の競争でも激しくなっていて、IT業種も例外ないですから、目標を立ったら勇気を持って目標を達成するために頑張るべきです。その中で、AmazonのData-Engineer-Associate試験に受かることも競争力があるモードです。この試験に合格したら、あなたのITキャリアには明るい未来があるようになります。あなたを助けるために、我々のJPNTestは真実かつ正確なトレーニング資料を提供します。JPNTestを利用したら、あなたはきっと自分の理想を実現することができます。
Data-Engineer-Associate日本語練習問題: https://www.jpntest.com/shiken/Data-Engineer-Associate-mondaishu
無料でクラウドストレージから最新のJPNTest Data-Engineer-Associate PDFダンプをダウンロードする:https://drive.google.com/open?id=1cf-M6DeNxaD-RVmxxkDrvfo13XzGtTKT