DOWNLOAD the newest Dumps4PDF Mule-Arch-201 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1kpY47veeyef2C3wZ5LSKUY6Mshjn0IOj
It is well acknowledged that people who have a chance to participate in the simulation for the real Mule-Arch-201 exam, they must have a fantastic advantage over other people to get good grade in the Mule-Arch-201 exam. Now, it is so lucky for you to meet this opportunity once in a blue. We offer you the simulation test with the Software version of our Mule-Arch-201 Preparation dumps in order to let you be familiar with the environment of test as soon as possible.
| Section | Objectives |
|---|---|
| Topic 1: Security and Compliance | - Secure API exposure and threat protection - Authentication and authorization mechanisms |
| Topic 2: API Management and Governance | - API lifecycle management - API security policies and enforcement - Governance frameworks and best practices |
| Topic 3: Integration Architecture Strategy | - API-led connectivity principles - Designing enterprise integration architecture - System, process, and experience APIs |
| Topic 4: Performance and Scalability | - High availability design patterns - Scaling Mule applications |
| Topic 5: Data Integration and Transformation | - Data mapping and transformation strategies - Batch vs real-time integration patterns |
| Topic 6: Anypoint Platform Architecture | - Runtime Fabric architecture overview - Anypoint Platform components and capabilities - Deployment models (CloudHub, hybrid, on-premises) |
>> Valid Mule-Arch-201 Test Questions <<
With many advantages such as immediate download, simulation before the real test as well as high degree of privacy, our Mule-Arch-201 actual exam survives all the ordeals throughout its development and remains one of the best choices for those in preparation for exams. Many people have gained good grades after using our Mule-Arch-201 real test, so you will also enjoy the good results. Don’t hesitate any more. Time and tide wait for no man. If you really long for recognition and success, you had better choose our Mule-Arch-201 exam demo since no other exam demo has better quality than our Mule-Arch-201 training questions.
NEW QUESTION # 87
What is a key performance indicator (KPI) that measures the success of a typical C4E that is immediately apparent in responses from the Anypoint Platform APIs?
Answer: A
Explanation:
Correct Answe r: The number of API specifications in RAML or OAS format published to Anypoint Exchange
*****************************************
>> The success of C4E always depends on their contribution to the number of reusable assets that they have helped to build and publish to Anypoint Exchange.
>> It is NOT due to any factors w.r.t # of outages, Manual vs CI/CD deployments or Publicly accessible HTTP endpoints
>> Anypoint Platform APIs helps us to quickly run and get the number of published RAML/OAS assets to Anypoint Exchange. This clearly depicts how successful a C4E team is based on number of returned assets in the response.
NEW QUESTION # 88
When could the API data model of a System API reasonably mimic the data model exposed by the corresponding backend system, with minimal improvements over the backend system's data model?
Answer: D
Explanation:
Correct Answe r: When a pragmatic approach with only limited isolation from the backend system is deemed appropriate.
*****************************************
General guidance w.r.t choosing Data Models:
>> If an Enterprise Data Model is in use then the API data model of System APIs should make use of data types from that Enterprise Data Model and the corresponding API implementation should translate between these data types from the Enterprise Data Model and the native data model of the backend system.
>> If no Enterprise Data Model is in use then each System API should be assigned to a Bounded Context, the API data model of System APIs should make use of data types from the corresponding Bounded Context Data Model and the corresponding API implementation should translate between these data types from the Bounded Context Data Model and the native data model of the backend system. In this scenario, the data types in the Bounded Context Data Model are defined purely in terms of their business characteristics and are typically not related to the native data model of the backend system. In other words, the translation effort may be significant.
>> If no Enterprise Data Model is in use, and the definition of a clean Bounded Context Data Model is considered too much effort, then the API data model of System APIs should make use of data types that approximately mirror those from the backend system, same semantics and naming as backend system, lightly sanitized, expose all fields needed for the given System API's functionality, but not significantly more and making good use of REST conventions.
The latter approach, i.e., exposing in System APIs an API data model that basically mirrors that of the backend system, does not provide satisfactory isolation from backend systems through the System API tier on its own. In particular, it will typically not be possible to "swap out" a backend system without significantly changing all System APIs in front of that backend system and therefore the API implementations of all Process APIs that depend on those System APIs! This is so because it is not desirable to prolong the life of a previous backend system's data model in the form of the API data model of System APIs that now front a new backend system. The API data models of System APIs following this approach must therefore change when the backend system is replaced.
On the other hand:
>> It is a very pragmatic approach that adds comparatively little overhead over accessing the backend system directly
>> Isolates API clients from intricacies of the backend system outside the data model (protocol, authentication, connection pooling, network address, ...)
>> Allows the usual API policies to be applied to System APIs
>> Makes the API data model for interacting with the backend system explicit and visible, by exposing it in the RAML definitions of the System APIs
>> Further isolation from the backend system data model does occur in the API implementations of the Process API tier
NEW QUESTION # 89
A retail company is using an Order API to accept new orders. The Order API uses a JMS queue to submit orders to a backend order management service. The normal load for orders is being handled using two (2) CloudHub workers, each configured with 0.2 vCore. The CPU load of each CloudHub worker normally runs well below 70%. However, several times during the year the Order API gets four times (4x) the average number of orders. This causes the CloudHub worker CPU load to exceed 90% and the order submission time to exceed 30 seconds. The cause, however, is NOT the backend order management service, which still responds fast enough to meet the response SLA for the Order API. What is the MOST resource-efficient way to configure the Mule application's CloudHub deployment to help the company cope with this performance challenge?
Answer: C
Explanation:
Correct Answe r: Use a horizontal CloudHub autoscaling policy that triggers on CPU utilization greater than 70%
*****************************************
The scenario in the question is very clearly stating that the usual traffic in the year is pretty well handled by the existing worker configuration with CPU running well below 70%. The problem occurs only "sometimes" occasionally when there is spike in the number of orders coming in.
So, based on above, We neither need to permanently increase the size of each worker nor need to permanently increase the number of workers. This is unnecessary as other than those "occasional" times the resources are idle and wasted.
We have two options left now. Either to use horizontal Cloudhub autoscaling policy to automatically increase the number of workers or to use vertical Cloudhub autoscaling policy to automatically increase the vCore size of each worker.
Here, we need to take two things into consideration:
1. CPU
2. Order Submission Rate to JMS Queue
>> From CPU perspective, both the options (horizontal and vertical scaling) solves the issue. Both helps to bring down the usage below 90%.
>> However, If we go with Vertical Scaling, then from Order Submission Rate perspective, as the application is still being load balanced with two workers only, there may not be much improvement in the incoming request processing rate and order submission rate to JMS queue. The throughput would be same as before. Only CPU utilization comes down.
>> But, if we go with Horizontal Scaling, it will spawn new workers and adds extra hand to increase the throughput as more workers are being load balanced now. This way we can address both CPU and Order Submission rate.
Hence, Horizontal CloudHub Autoscaling policy is the right and best answer.
NEW QUESTION # 90
Refer to the exhibits.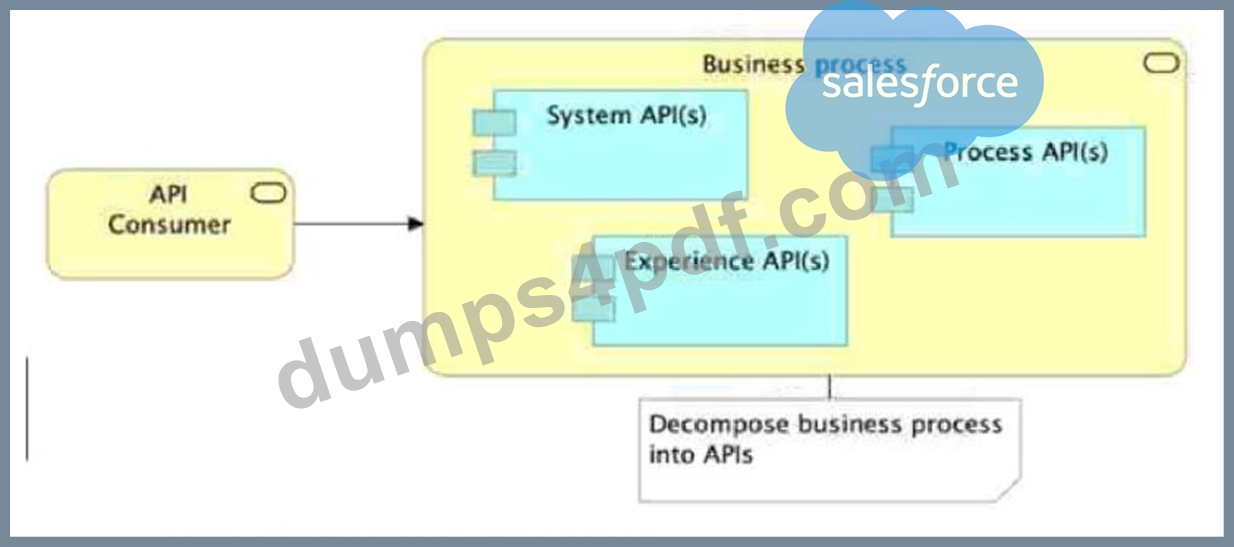
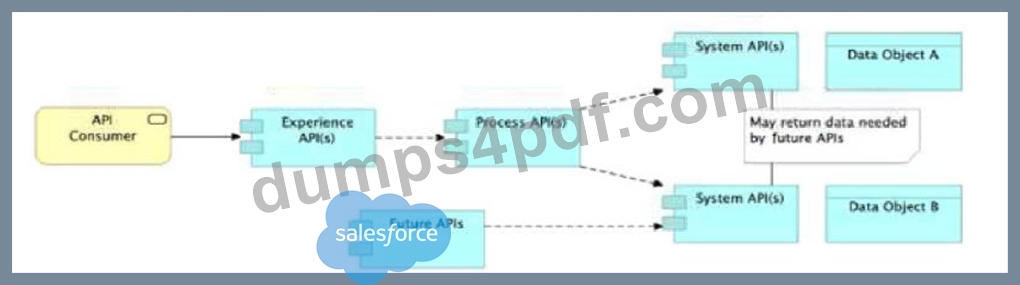
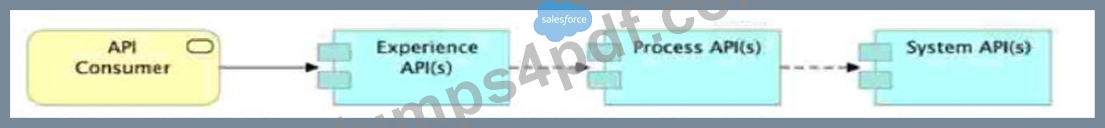
Which architectural constraint is compatible with the API-led connectivity architectural style?
Answer: C
Explanation:
Understanding API-led Connectivity Layers:
In MuleSoft's API-led connectivity approach, APIs are categorized into three layers:
Experience Layer: This layer is responsible for providing data to the end-user applications and is often customized to meet the needs of different user interfaces.
Process Layer: This layer is used to orchestrate and combine data from multiple System APIs. It acts as a mediator and business logic layer without directly interacting with the backend systems.
System Layer: This layer provides direct access to the backend systems (e.g., databases, ERPs) and is usually focused on exposing atomic data operations.
Evaluating the Architectural Constraints:
Option A: Always using a strict tiered approach by creating exactly one API per layer is not necessarily an architectural constraint of API-led connectivity. While a layered approach is recommended, it is common to have multiple APIs in each layer as needed for different functionalities.
Option B (Correct Answer): In API-led connectivity, Process APIs are generally responsible for orchestrating calls to System APIs and should not call other Process APIs. This maintains a clear separation of concerns, ensuring that Process APIs aggregate data from System APIs only and provide it to Experience APIs.
Option C: System APIs are generally designed to provide only the necessary data to meet current business requirements. Allowing them to return extra data that is not needed by Process or Experience APIs is not a best practice, as it can lead to inefficiencies.
Option D: Customizations specific to end-user applications are typically handled at the Experience Layer rather than the Process Layer, as the Experience Layer is intended to tailor the data to fit the needs of each specific client or front-end application.
Conclusion:
Option B is the correct answer as it aligns with the API-led connectivity principles. In this architectural style, Process APIs should orchestrate System APIs but should avoid interacting with other Process APIs to keep a clear separation of responsibilities across the layers.
For additional details, refer to MuleSoft documentation on API-led connectivity best practices, particularly around the roles of each layer in API orchestration and data handling.
NEW QUESTION # 91
A REST API is being designed to implement a Mule application.
What standard interface definition language can be used to define REST APIs?
Answer: B
NEW QUESTION # 92
......
You can also become part of this skilled and qualified community. To do this just enroll in the Salesforce Certified MuleSoft Platform Architect Exam and start preparation with real and valid Mule-Arch-201 practice test questions right now. The Salesforce Certified MuleSoft Platform Architect practice test questions are checked and verified by experienced and qualified Mule-Arch-201 Exam trainers. So you can trust Dumps4PDF Salesforce Certified MuleSoft Platform Architect practice test questions and start preparation with confidence.
Passing Mule-Arch-201 Score Feedback: https://www.dumps4pdf.com/Mule-Arch-201-valid-braindumps.html
BTW, DOWNLOAD part of Dumps4PDF Mule-Arch-201 dumps from Cloud Storage: https://drive.google.com/open?id=1kpY47veeyef2C3wZ5LSKUY6Mshjn0IOj