2026年Pass4Testの最新DP-700 PDFダンプおよびDP-700試験エンジンの無料共有:https://drive.google.com/open?id=1JMFs-ydXFIPE9Ew02z16OIj63xfTNz35
Microsoft複雑な知識が簡素化され、学習内容が習得しやすいPass4TestのDP-700テストトレントのセットを提供します。これにより、貴重な時間を制限しながら、Microsoftより重要な知識を獲得できます。 Implementing Data Engineering Solutions Using Microsoft Fabricガイドトレントには、時間管理とシミュレーションテスト機能が装備されています。タイムキーパーを設定して、速度を調整し、効率を改善するために注意を払うのに役立ちます。 当社の専門家チームは、DP-700認定トレーニングでImplementing Data Engineering Solutions Using Microsoft Fabric試験を準備するのに20〜30時間しかかからない非常に効率的なトレーニングプロセスを設計しました。
| Section | Objectives |
|---|---|
| Manage and monitor data solutions | - Monitor pipelines and workloads
|
| Design and implement data ingestion solutions | - Integrate external data sources
|
| Secure and govern data in Microsoft Fabric | - Data governance and compliance
|
| Develop data transformation solutions | - Data modeling and lakehouse transformation
|
当社は長年にわたり、クライアントに最高のDP-700練習問題を提供し、テストDP-700認定試験にスムーズに合格できるように常に努めています。当社は、国内の有名な業界の専門家を募集し、優秀な人材をDP-700学習ガイドを編集し、お客様に心から奉仕するために最善を尽くしました。当社は、お客様が私たちの神であり、DP-700トレーニング資料の品質に関する厳格な基準であるというサービス理念を設定しています。
質問 # 82
You are building a data loading pattern by using a Fabric data pipeline. The source is an Azure SQL database that contains 25 tables. The destination is a lakehouse.
In a warehouse, you create a control table named Control.Object as shown in the exhibit. (Click the Exhibit tab.) You need to build a data pipeline that will support the dynamic ingestion of the tables listed in the control table by using a single execution.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.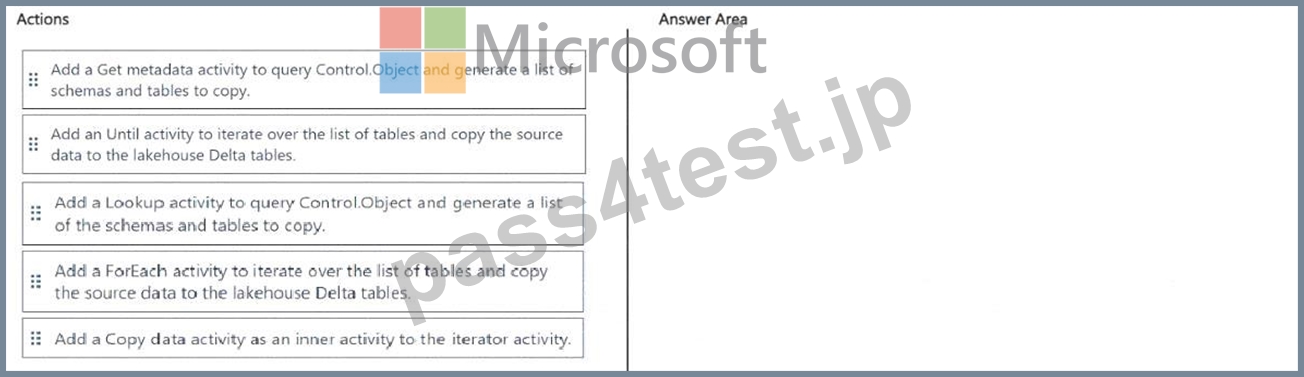
正解:
解説: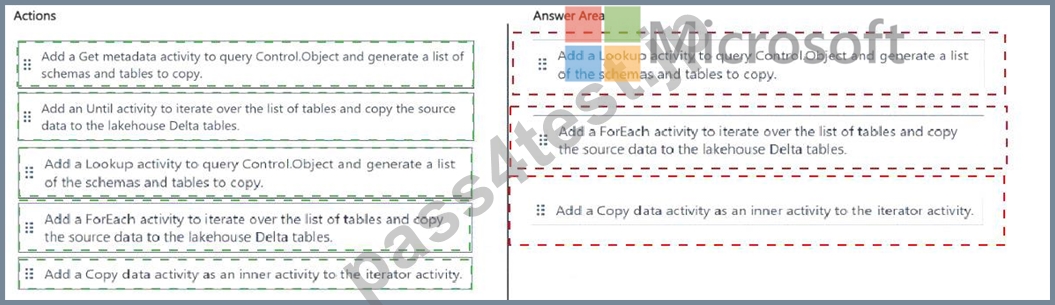
Explanation: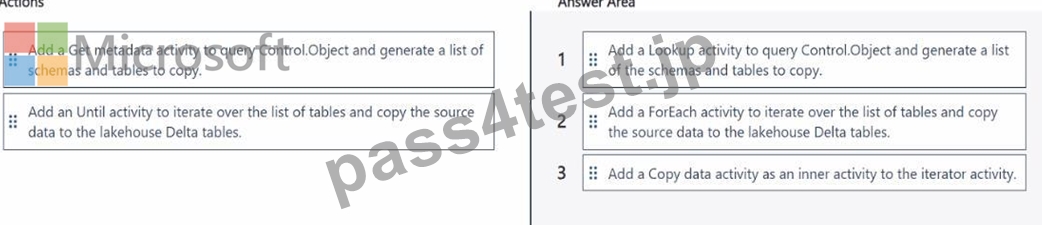
質問 # 83
HOTSPOT
You have a Fabric workspace that contains a warehouse named DW1. DW1 contains the following tables and columns.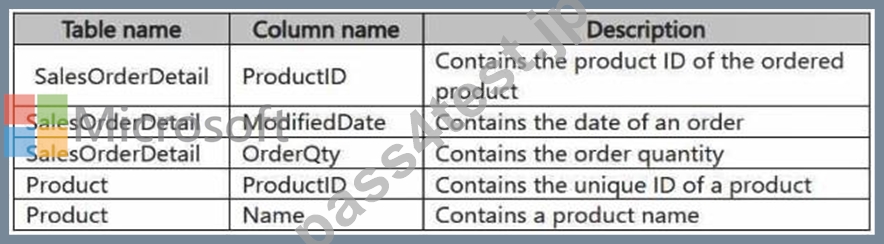
You need to create an output that presents the summarized values of all the order quantities by year and product. The results must include a summary of the order quantities at the year level for all the products.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.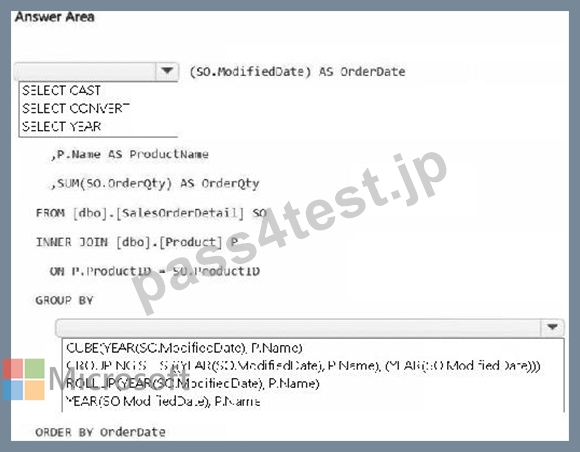
正解:
解説: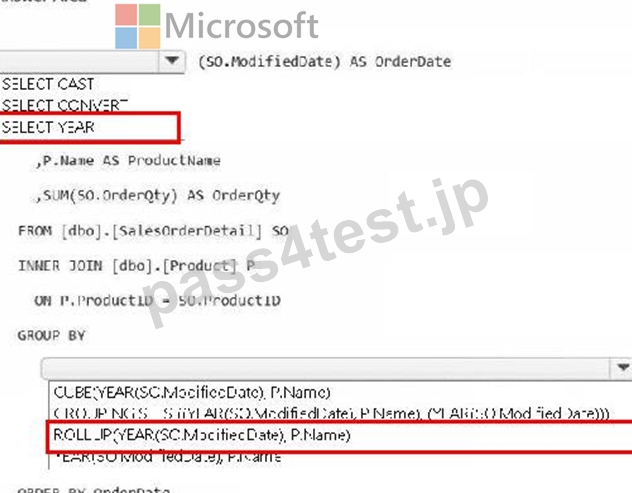
質問 # 84
You need to schedule the population of the medallion layers to meet the technical requirements.
What should you do?
正解:C
解説:
The technical requirements specify that:
Medallion layers must be fully populated sequentially (bronze # silver # gold). Each layer must be populated before the next.
If any step fails, the process must notify the data engineers.
Data imports should run simultaneously when possible.
Why Use a Data Pipeline That Calls Other Data Pipelines?
A data pipeline provides a modular and reusable approach to orchestrating the sequential population of medallion layers.
By calling other pipelines, each pipeline can focus on populating a specific layer (bronze, silver, or gold), simplifying development and maintenance.
A parent pipeline can handle:
- Sequential execution of child pipelines.
- Error handling to send email notifications upon failures.
- Parallel execution of tasks where possible (e.g., simultaneous imports into the bronze layer).
Topic 1, Contoso, LtdCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview. Company Overview
Contoso, Ltd. is an online retail company that wants to modernize its analytics platform by moving to Fabric.
The company plans to begin using Fabric for marketing analytics.
Overview. IT Structure
The company's IT department has a team of data analysts and a team of data engineers that use analytics systems.
The data engineers perform the ingestion, transformation, and loading of data. They prefer to use Python or SQL to transform the data.
The data analysts query data and create semantic models and reports. They are qualified to write queries in Power Query and T-SQL.
Existing Environment. Fabric
Contoso has an F64 capacity named Cap1. All Fabric users are allowed to create items.
Contoso has two workspaces named WorkspaceA and WorkspaceB that currently use Pro license mode.
Existing Environment. Source Systems
Contoso has a point of sale (POS) system named POS1 that uses an instance of SQL Server on Azure Virtual Machines in the same Microsoft Entra tenant as Fabric. The host virtual machine is on a private virtual network that has public access blocked. POS1 contains all the sales transactions that were processed on the company's website.
The company has a software as a service (SaaS) online marketing app named MAR1. MAR1 has seven entities. The entities contain data that relates to email open rates and interaction rates, as well as website interactions. The data can be exported from MAR1 by calling REST APIs. Each entity has a different endpoint.
Contoso has been using MAR1 for one year. Data from prior years is stored in Parquet files in an Amazon Simple Storage Service (Amazon S3) bucket. There are 12 files that range in size from 300 MB to 900 MB and relate to email interactions.
Existing Environment. Product Data
POS1 contains a product list and related data. The data comes from the following three tables:
Products
ProductCategories
ProductSubcategories
In the data, products are related to product subcategories, and subcategories are related to product categories.
Existing Environment. Azure
Contoso has a Microsoft Entra tenant that has the following mail-enabled security groups:
DataAnalysts: Contains the data analysts
DataEngineers: Contains the data engineers
Contoso has an Azure subscription.
The company has an existing Azure DevOps organization and creates a new project for repositories that relate to Fabric.
Existing Environment. User Problems
The VP of marketing at Contoso requires analysis on the effectiveness of different types of email content. It typically takes a week to manually compile and analyze the data. Contoso wants to reduce the time to less than one day by using Fabric.
The data engineering team has successfully exported data from MAR1. The team experiences transient connectivity errors, which causes the data exports to fail.
Requirements. Planned Changes
Contoso plans to create the following two lakehouses:
Lakehouse1: Will store both raw and cleansed data from the sources
Lakehouse2: Will serve data in a dimensional model to users for analytical queries Additional items will be added to facilitate data ingestion and transformation.
Contoso plans to use Azure Repos for source control in Fabric.
Requirements. Technical Requirements
The new lakehouses must follow a medallion architecture by using the following three layers: bronze, silver, and gold. There will be extensive data cleansing required to populate the MAR1 data in the silver layer, including deduplication, the handling of missing values, and the standardizing of capitalization.
Each layer must be fully populated before moving on to the next layer. If any step in populating the lakehouses fails, an email must be sent to the data engineers.
Data imports must run simultaneously, when possible.
The use of email data from the Amazon S3 bucket must meet the following requirements:
Minimize egress costs associated with cross-cloud data access.
Prevent saving a copy of the raw data in the lakehouses.
Items that relate to data ingestion must meet the following requirements:
The items must be source controlled alongside other workspace items.
Ingested data must land in the bronze layer of Lakehouse1 in the Delta format.
No changes other than changes to the file formats must be implemented before the data lands in the bronze layer.
Development effort must be minimized and a built-in connection must be used to import the source data.
In the event of a connectivity error, the ingestion processes must attempt the connection again.
Lakehouses, data pipelines, and notebooks must be stored in WorkspaceA. Semantic models, reports, and dataflows must be stored in WorkspaceB.
Once a week, old files that are no longer referenced by a Delta table log must be removed.
Requirements. Data Transformation
In the POS1 product data, ProductID values are unique. The product dimension in the gold layer must include only active products from product list. Active products are identified by an IsActive value of 1.
Some product categories and subcategories are NOT assigned to any product. They are NOT analytically relevant and must be omitted from the product dimension in the gold layer.
Requirements. Data Security
Security in Fabric must meet the following requirements:
The data engineers must have read and write access to all the lakehouses, including the underlying files.
The data analysts must only have read access to the Delta tables in the gold layer.
The data analysts must NOT have access to the data in the bronze and silver layers.
The data engineers must be able to commit changes to source control in WorkspaceA.
質問 # 85
You have a Fabric data warehouse that contains the following tables.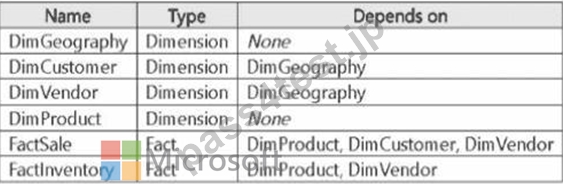
You need to refresh the tables by using an automated pipeline. The solution must ensure that table updates occur in the correct order to maintain referential integrity.
Which two tables should you refresh first? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:C、D
質問 # 86
You have a Fabric workspace named Workspace1 that contains the items shown in the following table.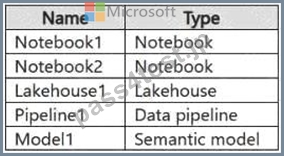
For Model1, the Keep your Direct Lake data up to date option is disabled.
You need to configure the execution of the items to meet the following requirements:
Notebook1 must execute every weekday at 8:00 AM.
Notebook2 must execute when a file is saved to an Azure Blob Storage container.
Model1 must refresh when Notebook1 has executed successfully.
How should you orchestrate each item? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.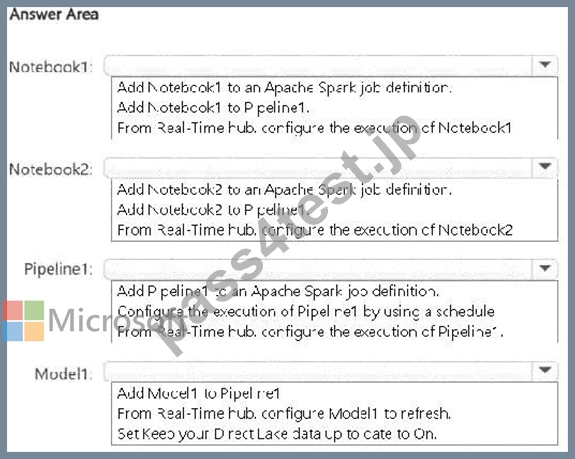
正解:
解説: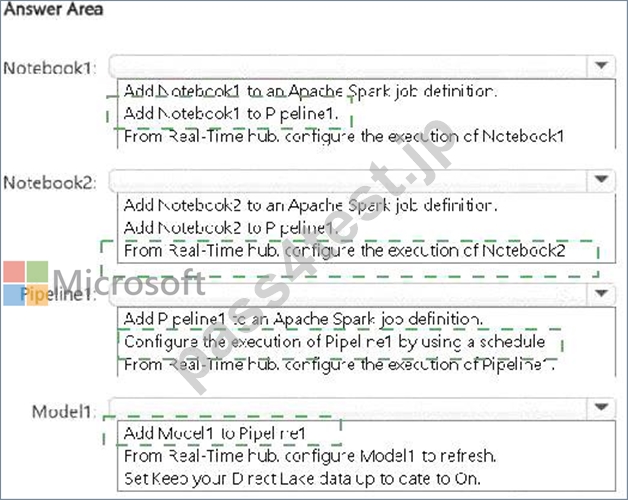
Explanation: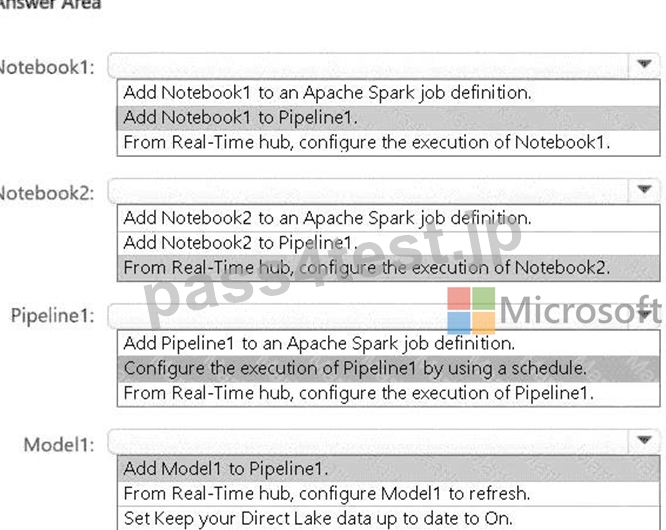
質問 # 87
......
Microsoft学習教材は、学習者が製品を使用するのに不便がないように役立つ複数の機能と思いやりのあるサービスを提供します。 DP-700学習教材を購入し、しばらくの間辛抱強く学習すれば、わずかな失敗確率でDP-700テストに合格することを保証できます。私たちの製品の価格はあなたが購入できる範囲内であり、私たちの学習教材を使用した後、あなたは確かに製品の価値があなたが支払う金額をはるかに超えていると感じるでしょう。 DP-700学習ガイドを選択することは、Implementing Data Engineering Solutions Using Microsoft Fabric成功と完璧なサービスを選択することと同じです。
DP-700試験関連情報: https://www.pass4test.jp/DP-700.html
2026年Pass4Testの最新DP-700 PDFダンプおよびDP-700試験エンジンの無料共有:https://drive.google.com/open?id=1JMFs-ydXFIPE9Ew02z16OIj63xfTNz35