P.S. Free & New DAA-C01 dumps are available on Google Drive shared by Actual4Cert: https://drive.google.com/open?id=1iuI4FHudBT0Tnp6p-3tlDXgoGN1dwCdW
Actual4Cert releases a new high pass-rate DAA-C01 valid exam preparation recently. If you are still puzzled by your test you can set your heart at rest to purchase our valid exam materials which will assist you to clear exam easily. We can guarantee purchasing Snowflake DAA-C01 Valid Exam Preparation will be the best passing methods and it always help you pass exam at first attempt. Now it is really an opportunity. Stop waiting and hesitate again!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Analysis | 30%-32% | - Perform advanced analytics using SQL
|
| Topic 2: Data Ingestion and Data Preparation | 15%-20% | - Implement data processing solutions
|
| Topic 3: Data Presentation and Data Visualization | 28%-29% | - Create dashboards
|
| Topic 4: Data Transformation and Data Modeling | 22%-30% | - Design data models
|
>> Latest DAA-C01 Practice Materials <<
If you want to participate in the IT industry's important Snowflake DAA-C01 examination, it is necessary to select Actual4Cert Snowflake DAA-C01 exam training database. Through Snowflake DAA-C01 examination certification, you will be get a better guarantee. In your career, at least in the IT industry, your skills and knowledge will get international recognition and acceptance. This is one of the reasons that why lot of people choose Snowflake DAA-C01 certification exam. So this exam is increasingly being taken seriously. So this exam is increasingly being taken seriously. Actual4Cert Snowflake DAA-C01 Exam Training materials can help you achieve your aspirations. Actual4Cert Snowflake DAA-C01 exam training materials are produced by the experienced IT experts, it is a combination of questions and answers, and no other training materials can be compared. You do not need to attend the expensive training courses. The Snowflake DAA-C01 exam training materials of Actual4Cert add to your shopping cart please. It is enough to help you to easily pass the exam.
NEW QUESTION # 25
You have a Snowflake table containing order data'. You need to calculate the shipping cost for each order based on the order amount and the destination country. You decide to use a Java UDF for this calculation, as the logic is complex and involves external APIs (simulated here). The UDF should take the order amount (FLOAT) and destination country (VARCHAR) as input and return the calculated shipping cost (FLOAT). The Java code requires external JAR files to be imported. Which of the following options correctly defines and calls the Java UDF in Snowflake, assuming the necessary JAR file has been uploaded to a stage named 'my_stage'?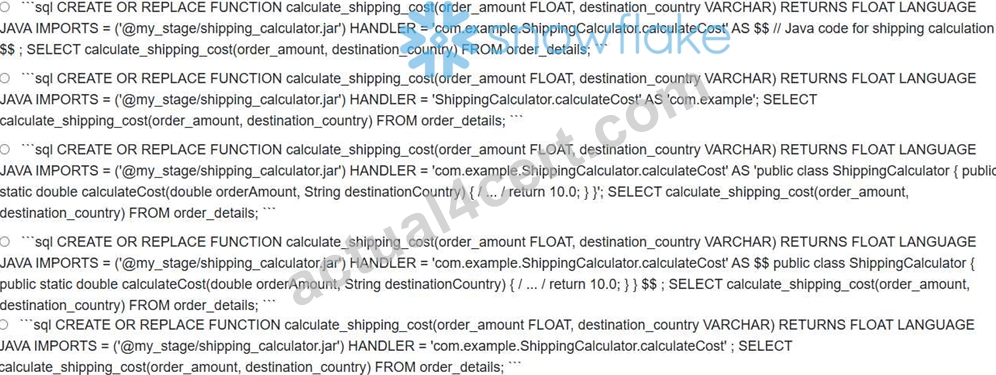
Answer: D
Explanation:
Option E is the most correct because the function definition does not require the definition of the class 'com.example.ShippingCalculator' within the function body. Since the jar file is defined within the imports section, snowflake does not need the explicit definition. Option A, C, and D requires the function and class definition which is already defined in the jar, and defining it again will lead to conflicts. Option B doesn't correctly define the class. All the rest of the options either try to define the Java code inline (which is incorrect when using IMPORTS) or have syntax errors in the UDF definition.
NEW QUESTION # 26
You are analyzing customer order data in Snowflake. The 'orders' table has columns: and 'order_totar. Your task is to identify the top 5 customers who have consistently placed high-value orders over time. You need to rank customers based on their average order total, but only consider customers who have placed at least 10 orders. Furthermore, you want to account for the recency of orders by applying a weighted average where more recent orders contribute more to the average. Which of the following approaches will efficiently achieve this goal in Snowflake?
Answer: A,C
Explanation:
Both options B and E correctly address the problem. B calculates a weighted average, filters based on the minimum order count, and then ranks customers based on the weighted average. E achieves the same result in using QUALIFY which is an important technique to filter. Option A doesn't account for weighting. C is inefficient and does not leverage Snowflake's processing power. D is unnecessarily complex with join, date series and subquery for simple operation that can be achieved using window functions.
NEW QUESTION # 27
In diagnostic analysis, what significance do demographics and relationships hold when identifying anomalies? (Select all that apply)
Answer: B,D
Explanation:
Identifying demographic variations and considering relationships are crucial in identifying anomalies during diagnostic analysis.
NEW QUESTION # 28
The image shows a table with a variant column that is storing a JSON record: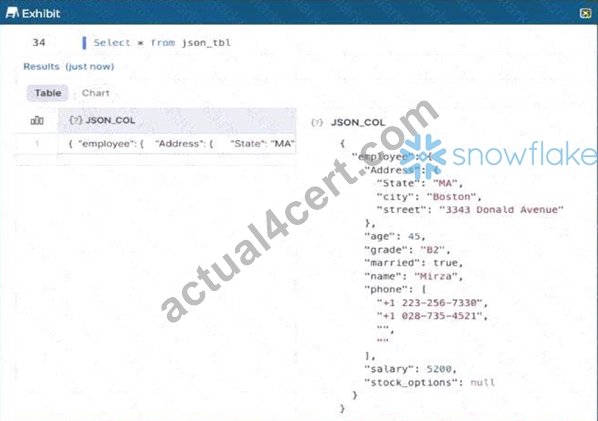
This SQL query is run: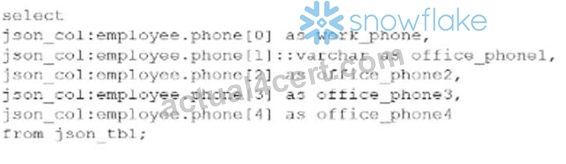
What will be the result?
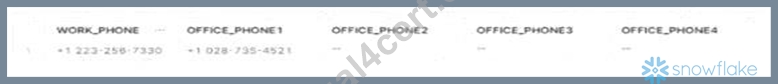


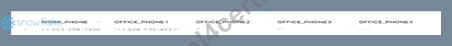
Answer: C
Explanation:
To correctly predict the output of this query, a Data Analyst must understand how Snowflake handles semi- structured data (JSON), specifically regarding path notation, data type casting, and the display of VARIANT values in the Snowsight UI.
1. Variant vs. Casted Types (Display): When you access a value within a JSON object using colon notation (e.g., json_col:employee.phone[0]), the resulting value is of the VARIANT data type. In the Snowflake Snowsight results pane, VARIANT strings are displayed with double quotes (e.g., "+1 223-256-7330").
However, when you explicitly cast a variant to a string type using the double-colon syntax (e.g., ::varchar), Snowflake extracts the value as a native SQL string, which is displayed without quotes (e.g., +1 028-735-
4521).
2. Handling Empty Strings vs. Out-of-Bounds: In the provided JSON exhibit, the phone array contains four elements at indices 0, 1, 2, and 3. The elements at indices 2 and 3 are empty strings (""). When these are queried, Snowflake returns the empty string variant, which appears as "" in the result set. The query also attempts to access phone[4]. Since the array only has four elements (max index 3), index 4 is out-of-bounds.
In Snowflake, accessing a non-existent index in an array or a non-existent key in an object returns NULL.
Evaluating the Options based on the exhibit:
* Option B correctly reflects all these behaviors: WORK_PHONE is in quotes (Variant), OFFICE_PHONE1 is not in quotes (Casted), OFFICE_PHONE2 and OFFICE_PHONE3 show the empty strings present in the JSON, and OFFICE_PHONE4 correctly shows null for the out-of-bounds access.
* Option A is incorrect because it misses the quotes for the variant column and shows the out-of-bounds index as an empty string instead of null.
* Option C is incorrect because it fails to account for the empty strings present at indices 2 and 3.
* Option D incorrectly mixes the casting logic and display.
This question tests the "Schema-on-Read" proficiency required of a SnowPro Advanced: Data Analyst, specifically the ability to predict exactly how transformed semi-structured data will materialize for end-users.
NEW QUESTION # 29
How can a Data Analyst automatically create a table structure for loading a Parquet file?
Answer: D
Explanation:
Manually defining table structures for complex semi-structured files like Parquet can be error-prone and time- consuming. Snowflake provides a specific automation workflow to handle this, involving the detection of the file's internal schema and the dynamic creation of a matching table.
The process starts with the INFER_SCHEMA function. Because Parquet files are self-describing, they contain metadata about their columns and data types. INFER_SCHEMA reads this metadata from files in a stage and returns a list of column names and types. To turn this list into an actual table, the analyst uses the CREATE TABLE ... USING TEMPLATE syntax. This command takes the output of INFER_SCHEMA as an input and automatically builds a table with the corresponding definition.
Evaluating the Options:
* Option A is incorrect because CREATE TABLE LIKE is used to copy the structure of an existing table
, not to build a new one from file metadata.
* Option C and D are incorrect because GENERATE_COLUMN_DESCRIPTION is a helper function used to create a formatted string of column definitions, but it is not the primary command used with USING TEMPLATE for automated table creation.
* Option B is the Correct answer. The combination of INFER_SCHEMA (to find the columns) and USING TEMPLATE (to build the table) is the standard Snowflake pattern for schema-on-read automation in Data Ingestion workflows.
NEW QUESTION # 30
......
Comfortable life will demoralize and paralyze you one day. So you must involve yourself in meaningful experience to motivate yourself. For example, our DAA-C01 study materials perhaps can become your new attempt. In fact, learning our DAA-C01 learning quiz is a good way to inspire your spirits. Not only that you can pass the exam and gain the according DAA-C01 certification but also you can learn a lot of knowledage and skills on the subjest.
Valid Dumps DAA-C01 Files: https://www.actual4cert.com/DAA-C01-real-questions.html
DOWNLOAD the newest Actual4Cert DAA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1iuI4FHudBT0Tnp6p-3tlDXgoGN1dwCdW