Latest Databricks Certified Professional Data Engineer Exam vce dumps & Databricks-Certified-Professional-Data-Engineer prep4sure exam

The second form is Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) web-based practice test. It can be attempted through online browsing, and you can prepare via the internet. The Databricks-Certified-Professional-Data-Engineer web-based practice test can be taken from Firefox, Microsoft Edge, Google Chrome, and Safari. You don't need to install or use any plugins or software to take the Databricks-Certified-Professional-Data-Engineer web-based practice exam. Furthermore, you can take this online mock test via any operating system.
| Section | Objectives |
|---|
| Topic 1: Data Modeling and Storage | - Delta Lake table design and optimization
- Design scalable data lakehouse architectures
- Schema evolution and data partitioning strategies
|
| Topic 2: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
- Pipeline reliability and fault tolerance
|
| Topic 3: Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning
- Implement Unity Catalog governance and access control
- Monitor and optimize Spark workloads
|
| Topic 4: Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs
- Handle batch and streaming data pipelines
- Ingest data using Apache Spark and Databricks
|
>> Databricks-Certified-Professional-Data-Engineer Valid Exam Testking <<
TOP Databricks-Certified-Professional-Data-Engineer Valid Exam Testking - Databricks Databricks Certified Professional Data Engineer Exam - High Pass-Rate Databricks-Certified-Professional-Data-Engineer Valid Test Tips
Research indicates that the success of our highly-praised Databricks-Certified-Professional-Data-Engineer test questions owes to our endless efforts for the easily operated practice system. Most feedback received from our candidates tell the truth that our Databricks-Certified-Professional-Data-Engineer guide torrent implement good practices, systems.We educate our candidates with less complicated Q&A but more essential information. And our Databricks-Certified-Professional-Data-Engineer Exam Dumps also add vivid examples and accurate charts to stimulate those exceptional cases you may be confronted with. You can rely on our Databricks-Certified-Professional-Data-Engineer test questions, and we'll do the utmost to help you succeed.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q38-Q43):
NEW QUESTION # 38
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Define a view against the products_per_order table and define the dashboard against this view.
- B. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- C. Populate the dashboard by configuring a nightly batch job to save the required to quickly update the dashboard with each query.
- D. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
Answer: A
Explanation:
Given the requirement for daily refresh of data and the need to ensure quick response times for interactive queries while controlling costs, a nightly batch job to pre-compute and save the required summary metrics is the most suitable approach.
By pre-aggregating data during off-peak hours, the dashboard can serve queries quickly without requiring on-the-fly computation, which can be resource-intensive and slow, especially with many users.
This approach also limits the cost by avoiding continuous computation throughout the day and instead leverages a batch process that efficiently computes and stores the necessary data.
The other options (A, C, D) either do not address the cost and performance requirements effectively or are not suitable for the use case of less frequent data refresh and high interactivity.
Reference:
Databricks Documentation on Batch Processing: Databricks Batch Processing Data Lakehouse Patterns: Data Lakehouse Best Practices
NEW QUESTION # 39
Review the following error traceback:
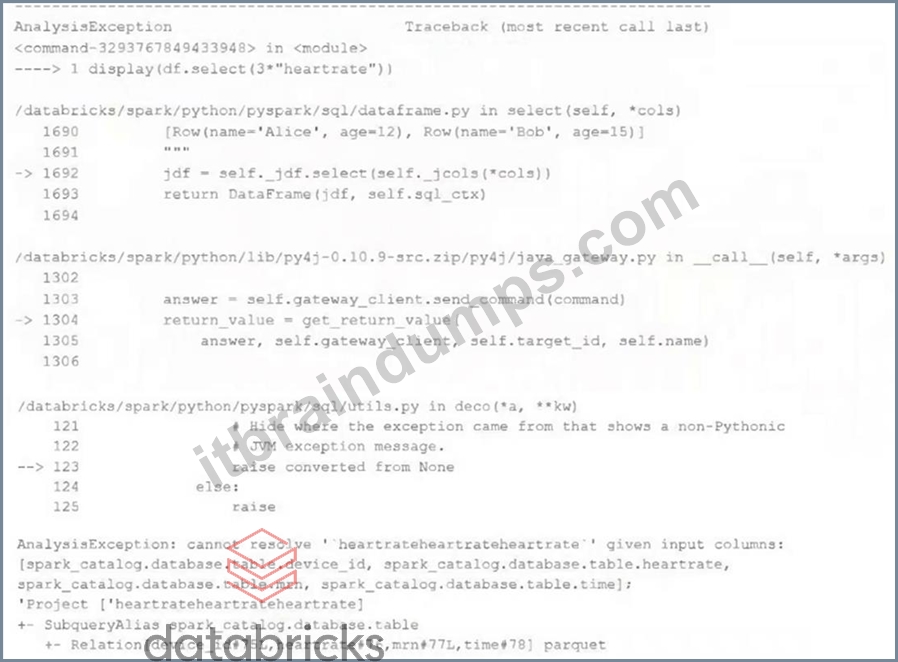
Which statement describes the error being raised?
- A. The code executed was PvSoark but was executed in a Scala notebook.
- B. There is a type error because a column object cannot be multiplied.
- C. There is no column in the table named heartrateheartrateheartrate
- D. There is a type error because a DataFrame object cannot be multiplied.
- E. There is a syntax error because the heartrate column is not correctly identified as a column.
Answer: C
Explanation:
The error being raised is an AnalysisException, which is a type of exception that occurs when Spark SQL cannot analyze or execute a query due to some logical or semantic error 1 . In this case, the error message indicates that the query cannot resolve the column name 'heartrateheartrateheartrate' given the input columns
'heartrate' and 'age'. This means that there is no column in the table named 'heartrateheartrateheartrate', and the query is invalid. A possible cause of this error is a typo or a copy-paste mistake in the query. To fix this error, the query should use a valid column name that exists in the table, such as
'heartrate'. References: AnalysisException
NEW QUESTION # 40
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:

An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. The email and ltv columns will be returned with the values in user itv.
- B. Only the email and itv columns will be returned; the email column will contain all null values.
- C. The email, age. and ltv columns will be returned with the values in user ltv.
- D. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- E. Only the email and ltv columns will be returned; the email column will contain the string "REDACTED" in each row.
Answer: E
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 41
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types.
What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
- B. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- C. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
- D. With Open Sharing, recipients cannot access Volumes, Models, or notebooks - only static Delta tables are supported.
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables-it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to-Databricks sharing supports dynamic data sharing with update visibility and streaming reads. Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 42
When you drop a managed table using SQL syntax DROP TABLE table_name how does it impact metadata, history, and data stored in the table?
- A. Drops table but keeps meta data, history and data in storage
- B. Drops table from meta store, meta data and history but keeps the data in storage
- C. Drops table from meta store, drops metadata, history, and data in storage.
- D. Drops table from meta store and data from storage but keeps metadata and history in storage
- E. Drops table and history but keeps meta data and data in storage
Answer: C
Explanation:
Explanation
For a managed table, a drop command will drop everything from metastore and storage.
See the below image to understand the differences between dropping an external table.
Diagram Description automatically generated

NEW QUESTION # 43
......
Our Itbraindumps is the most reliable backing for every Databricks-Certified-Professional-Data-Engineer candidate. All study materials required in Databricks-Certified-Professional-Data-Engineer exam are provided by Our Itbraindumps. Once you purchased our Databricks-Certified-Professional-Data-Engineer exam dump, we will try our best to help you Pass Databricks-Certified-Professional-Data-Engineer Exam. Additionally, our excellent after sales service contains one-year free update service and the guarantee of dump cost full refund if you fail the exam with our dump.
Databricks-Certified-Professional-Data-Engineer Valid Test Tips: https://www.itbraindumps.com/Databricks-Certified-Professional-Data-Engineer_exam.html
- Databricks-Certified-Professional-Data-Engineer Guide Braindumps Is Typically Beneficial for Databricks-Certified-Professional-Data-Engineer Exam - www.prep4sures.top 🟥 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and obtain a free download on ➥ www.prep4sures.top 🡄 🦰Latest Databricks-Certified-Professional-Data-Engineer Exam Dumps
- Databricks-Certified-Professional-Data-Engineer Valid Exam Testking - Latest Databricks-Certified-Professional-Data-Engineer Valid Test Tips Ensure you "Pass Guaranteed" 🚌 Easily obtain [ Databricks-Certified-Professional-Data-Engineer ] for free download through [ www.pdfvce.com ] 🎣Dumps Databricks-Certified-Professional-Data-Engineer Reviews
- Pass Guaranteed Databricks - Newest Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Valid Exam Testking ♻ Download ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ for free by simply searching on ➤ www.verifieddumps.com ⮘ 😣Valid Databricks-Certified-Professional-Data-Engineer Exam Question
- Latest Databricks-Certified-Professional-Data-Engineer Dumps Questions 📽 Databricks-Certified-Professional-Data-Engineer Exam Discount Voucher 💕 Valid Databricks-Certified-Professional-Data-Engineer Exam Question 🛷 Enter 「 www.pdfvce.com 」 and search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ to download for free 💝Databricks-Certified-Professional-Data-Engineer Well Prep
- Databricks-Certified-Professional-Data-Engineer Guide Braindumps Is Typically Beneficial for Databricks-Certified-Professional-Data-Engineer Exam - www.prep4away.com 🖱 Search on ☀ www.prep4away.com ️☀️ for 《 Databricks-Certified-Professional-Data-Engineer 》 to obtain exam materials for free download 🧦Dumps Databricks-Certified-Professional-Data-Engineer Reviews
- Latest Released Databricks Databricks-Certified-Professional-Data-Engineer Valid Exam Testking: Databricks Certified Professional Data Engineer Exam | Databricks-Certified-Professional-Data-Engineer Valid Test Tips 🍹 Download “ Databricks-Certified-Professional-Data-Engineer ” for free by simply entering ➤ www.pdfvce.com ⮘ website 🏈Reliable Databricks-Certified-Professional-Data-Engineer Test Prep
- Databricks-Certified-Professional-Data-Engineer Guide Braindumps Is Typically Beneficial for Databricks-Certified-Professional-Data-Engineer Exam - www.pass4test.com 👈 Search for { Databricks-Certified-Professional-Data-Engineer } on ➤ www.pass4test.com ⮘ immediately to obtain a free download 🏤Databricks-Certified-Professional-Data-Engineer Reliable Exam Tips
- Databricks-Certified-Professional-Data-Engineer Question Explanations ⚔ Reliable Databricks-Certified-Professional-Data-Engineer Test Prep 🎑 Latest Databricks-Certified-Professional-Data-Engineer Test Prep 🗣 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and easily obtain a free download on ➽ www.pdfvce.com 🢪 🔸Latest Databricks-Certified-Professional-Data-Engineer Exam Dumps
- Latest Released Databricks Databricks-Certified-Professional-Data-Engineer Valid Exam Testking: Databricks Certified Professional Data Engineer Exam | Databricks-Certified-Professional-Data-Engineer Valid Test Tips ✴ Easily obtain free download of ➥ Databricks-Certified-Professional-Data-Engineer 🡄 by searching on ➠ www.examcollectionpass.com 🠰 📶Latest Databricks-Certified-Professional-Data-Engineer Test Prep
- Latest Released Databricks Databricks-Certified-Professional-Data-Engineer Valid Exam Testking: Databricks Certified Professional Data Engineer Exam | Databricks-Certified-Professional-Data-Engineer Valid Test Tips 🔓 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and obtain a free download on ▶ www.pdfvce.com ◀ 🚤Online Databricks-Certified-Professional-Data-Engineer Version
- Databricks-Certified-Professional-Data-Engineer latest valid questions - Databricks-Certified-Professional-Data-Engineer vce pdf dumps - Databricks-Certified-Professional-Data-Engineer study prep material 🦚 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and download it for free immediately on ⏩ www.validtorrent.com ⏪ 🥬Databricks-Certified-Professional-Data-Engineer Latest Practice Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.flirtic.com, disqus.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, ccitonline.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes