Microsoft的AI-200考試認證,KaoGuTi是當前最新Microsoft的AI-200考試認證和考題準備問題提供認證的候選人中的佼佼者,我們資源不斷被修訂和更新,具有緊密的相關性和緊密性,今天你準備Microsoft的AI-200認證,你將要選擇你要開始的訓練,而且要通過你下一次的考題,由於我們大部分考題是每月更新一次,你將得到最好的資源與市場的新鮮品質和可靠性的保證。
| Section | Weight | Objectives |
|---|---|---|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
選擇我們KaoGuTi就是選擇成功!KaoGuTi為你提供的Microsoft AI-200 認證考試的練習題和答案能使你順利通過考試。Microsoft AI-200 認證考試的考試之前的模擬考試時很有必要的,也是很有效的。如果你選擇了KaoGuTi,你可以100%通過考試。
問題 #55
You deploy an AI application across multiple Azure regions.
The application must be able to view writes across all regions within a predictable time window.
You need to determine the appropriate consistency level.
What are two consistency levels you can use to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
答案:A,D
解題說明:
The two appropriate consistency levels for a globally distributed AI application needing to view writes within a predictable time window are Bounded Staleness and Strong.
Bounded Staleness: This provides a guarantee that reads will lag behind writes by a user- specified "staleness window" (either in time or number of operations). It delivers high availability and predictable read consistency across all regions, balancing performance with strict read-order guarantees.
Strong: This provides linearizable and absolute consistency, ensuring that writes are seen synchronously across all regions. It features an exact zero-second predictable time window, though it comes at the expense of higher latency for multi-region operations due to the time required to replicate globally.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/consistency-levels
問題 #56
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.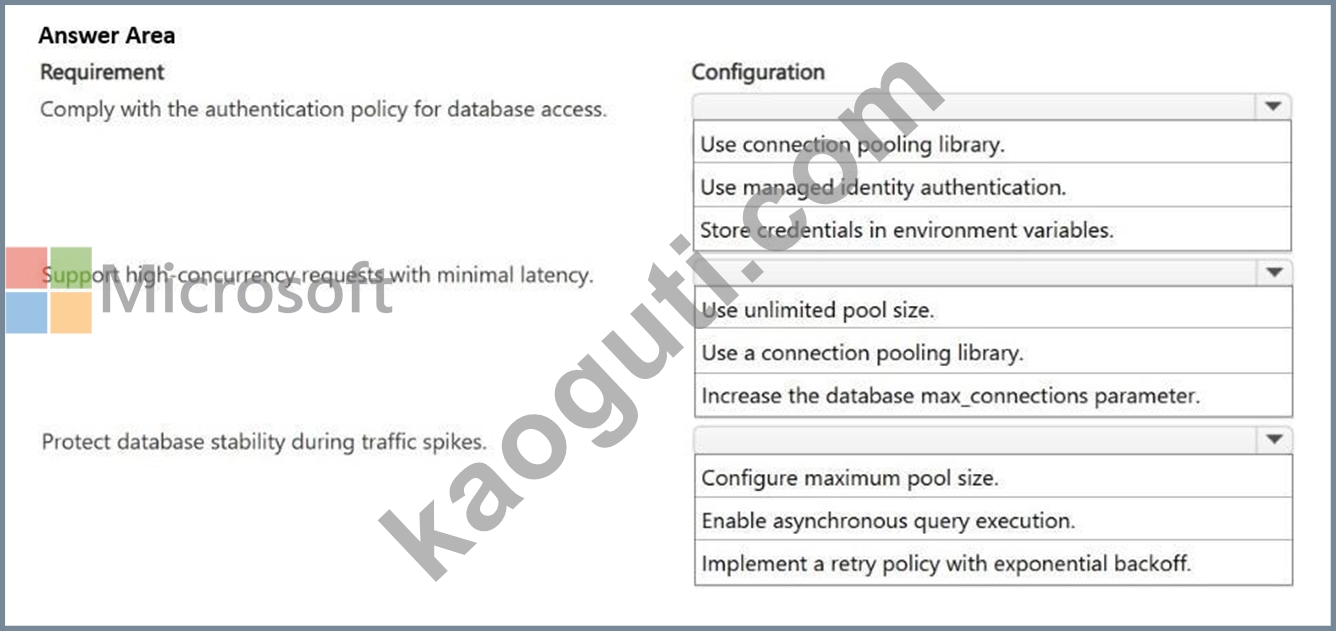
答案:
解題說明: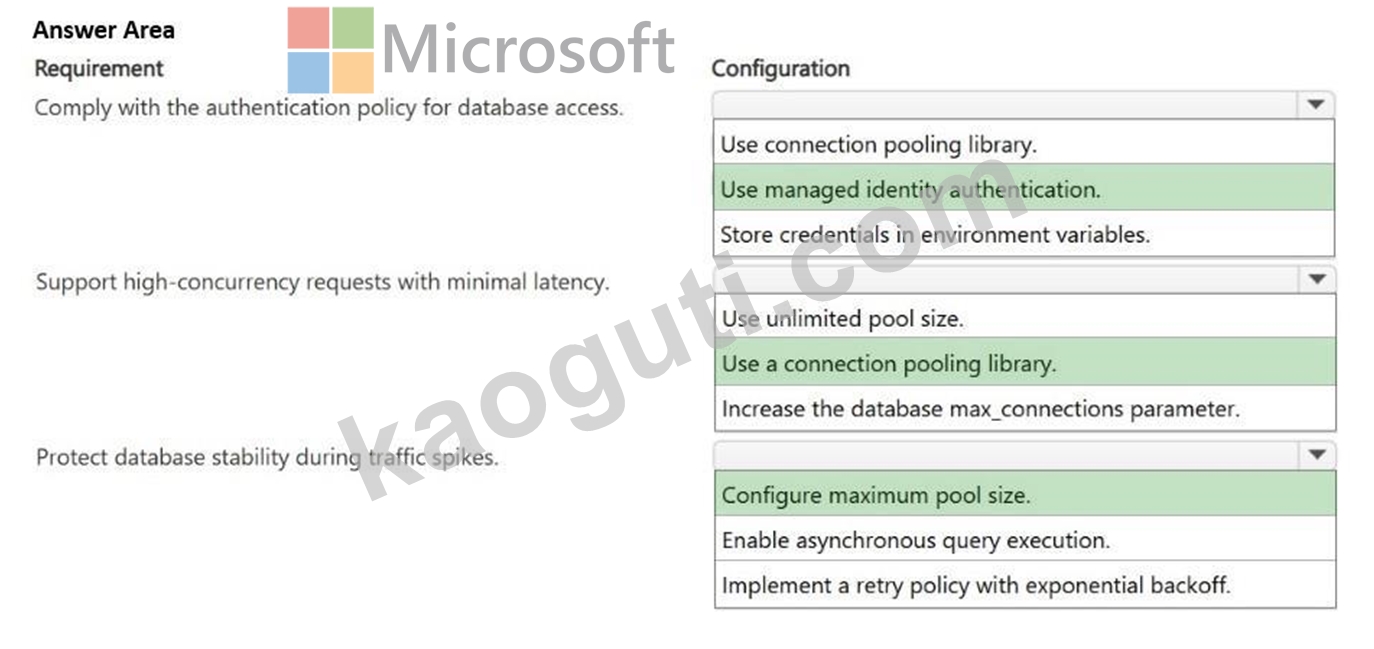
Explanation:
Box 1: Use managed identity authentication.
Scenario: Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited.' Box 2: Use a connection pooling library Scenario: Environment: Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
To support high-concurrency requests with minimal latency on Azure Database for PostgreSQL, the best action is to use a connection pooling library (or leverage Azure's built-in PgBouncer feature).
Eliminates Connection Overhead:
PostgreSQL utilizes a process-per-connection model. Forking a new backend process for every incoming request introduces substantial CPU and memory overhead, severely degrading latency under high concurrency. A connection pool keeps a warm set of reusable database sessions active.
Optimized for Azure: Microsoft provides a built-in managed PgBouncer integration for Azure Database for PostgreSQL. Enabling it in transaction mode allows the database to accept thousands of concurrent client connections while keeping actual backend processes lean and stable Box 3: Configure a maximum pool size Configure a maximum pool size is the best action to directly protect database stability during sudden traffic spikes.
Prevents Resource Exhaustion: Traffic spikes naturally lead to a surge in connection requests.
Unchecked connections consume substantial RAM and CPU overhead, which can crash the database or trigger severe latency. Limiting the pool size stops the "thundering herd" problem Acts as a Shock Absorber: When the pool hits its maximum limit, extra client requests are safely queued at the application or connection pooling layer (like Azure's built-in PgBouncer proxy) rather than overwhelming the database backend Reference:
https://docs.azure.cn/en-us/postgresql/connectivity/concepts-pgbouncer
https://learn.microsoft.com/en-au/answers/questions/5884412/best-practise-azure-postgresql-flexible-server-max
問題 #57
You are developing several microservices to run on Azure Container Apps.
You need to monitor and diagnose the microservices.
Which features should you use? To answer, select the appropriate feature in the answer area.
NOTE: Each correct selection is worth one point.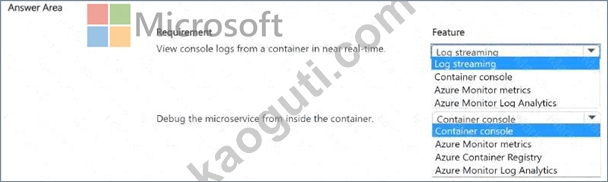
答案:
解題說明: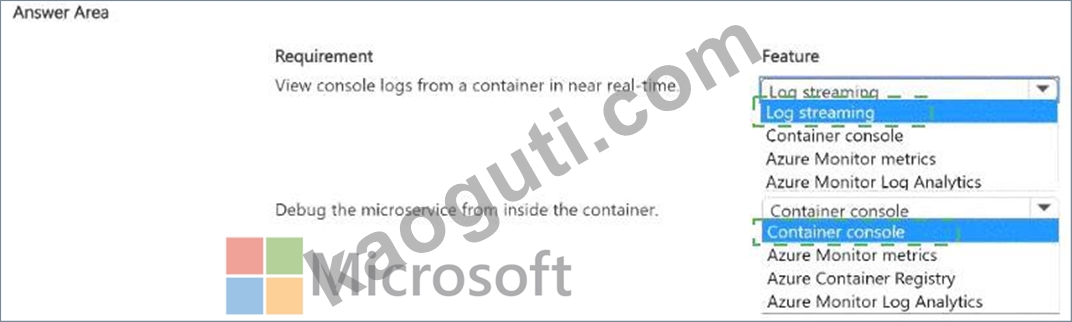
Explanation:
View console logs from a container in near real-time: Log streaming
* Debug the microservice from inside the container: Container console
For near-real-time troubleshooting, use Log streaming . Azure Container Apps supports streaming both system logs and container console logs directly through the Azure portal or Azure CLI. Microsoft documents that container console logs originate from the application ' s stdout and stderr streams, and the log-streaming feature can display them in near real time. This is the correct feature when developers need immediate visibility into container output without waiting for log ingestion into a monitoring workspace.
To debug the application from inside the running container , use the Container console . Azure Container Apps allows operators to connect interactively to a container by using the portal console or the az containerapp exec command. From there, they can run commands through shells such as bash or sh, inspect files, test network connectivity, examine environment variables, and troubleshoot runtime behavior directly in the container context.
Azure Monitor metrics are appropriate for aggregated performance measurements rather than interactive container debugging. Azure Monitor Log Analytics is useful for historical queries and centralized analysis, but Microsoft notes that ingested logs can have a delay of several minutes, so it is not the best choice for near- real-time console output.
Study Guide references: Azure Container Apps # Log streaming; Container console; observability; Azure Monitor integration; interactive troubleshooting.
問題 #58
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
答案:B
解題說明:
The lease container is the Azure Cosmos DB component that coordinates change feed processing across multiple processor instances. Microsoft defines the lease container as the state store used by the change feed processor to track progress and coordinate ownership of partition ranges among workers. Each lease corresponds to a portion of the change feed workload, and at any given time a lease is owned by one processor instance.
When several change feed processor instances use the same lease container and the same processor name while maintaining unique instance names, the processor distributes leases across the active instances by using an equal-distribution algorithm. If instances are added or removed, the processor dynamically redistributes leases, which provides automatic workload balancing and parallelism. This is exactly what is required when ingestion volume is high and each instance must process a distinct subset of partition ranges.
Indexing precision affects query indexing behavior, not change feed coordination. Strong consistency controls read consistency semantics and does not assign partitions to processors. Autoscale throughput can increase database RU/s capacity, but it does not coordinate which processor instance owns which change feed partition range.
Study Guide references: Azure Cosmos DB for NoSQL # Change Feed Processor; lease container; parallel processing; dynamic scaling and load balancing.
問題 #59
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
答案:D
解題說明:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
問題 #60
......
如果你選擇KaoGuTi,那麼成功就在不遠處。你很快就可以獲得Microsoft AI-200 認證考試的證書。我們的KaoGuTi提供的產品可以100%保證你通過考試,而且還會為你提供一年的免費的更新服務。
AI-200測試: https://www.kaoguti.com/AI-200_exam-pdf.html