A certificate may be a threshold for many corporations, it can decide that if you can enter a good company. There are AI-300 test dumps in our company with high quality, if you choose us pass guarantee and money back guarantee, if you indeed fail the exam, your money will be returned to your account. You can take easy to use the AI-300 Test Dumps, since we have the first-hand information, we will ensure that you will get the latestet information.
| Section | Objectives |
|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks - Set up Microsoft Foundry and Azure AI services for generative AI workloads |
| Topic 2: Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries |
| Topic 3: Implement generative AI quality assurance and observability | - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Implement logging, tracing, and telemetry for GenAI applications - Monitor latency, token usage, cost, and error rates |
| Topic 4: Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning |
| Topic 5: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput |
Our experts are constantly looking for creative way to immortalize our AI-300 actual exam in this line. Their masterpieces are instrumental to offer help and improve your performance in the real exam. Being dedicated to these practice materials painstakingly and pooling useful points into our AI-300 Exam Materials with perfect arrangement and scientific compilation of messages, our AI-300 practice materials can propel the exam candidates to practice with efficiency.
NEW QUESTION # 84
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.6 - AzureML kernel.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Create an environment.
Incorrect:
* Delete the Python 3.6 - AzureML kernel.
* Delete the Python 3.8 - AzureML kernel.
Note:
Before you can add a new Jupyter kernel on an Azure Machine Learning compute instance terminal, you must create a Conda environment.
Required Workflow
To officially provision and expose the new kernel to your Azure Machine Learning studio Notebooks, you need to execute the following full process from your terminal session:
Create the environment: Provision a new isolated environment (e.g., using conda create -n newenv python=3.10).
Activate the environment: Run conda activate newenv.
Install dependencies: Add the required ipykernel package using conda install ipykernel or pip install ipykernel.
Register the kernel: Bind the new environment configuration to the global Jupyter directory by running:
python -m ipykernel install --user --name newenv --display-name "My New Kernel" Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-access-terminal
NEW QUESTION # 85
A team validates a generative AI application that produces free-form text responses by using Microsoft Foundry SDK.
The evaluation dataset is registered in the Microsoft Foundry environment.
You need to configure a safety evaluation pipeline that reliably evaluates model outputs for harmful content.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.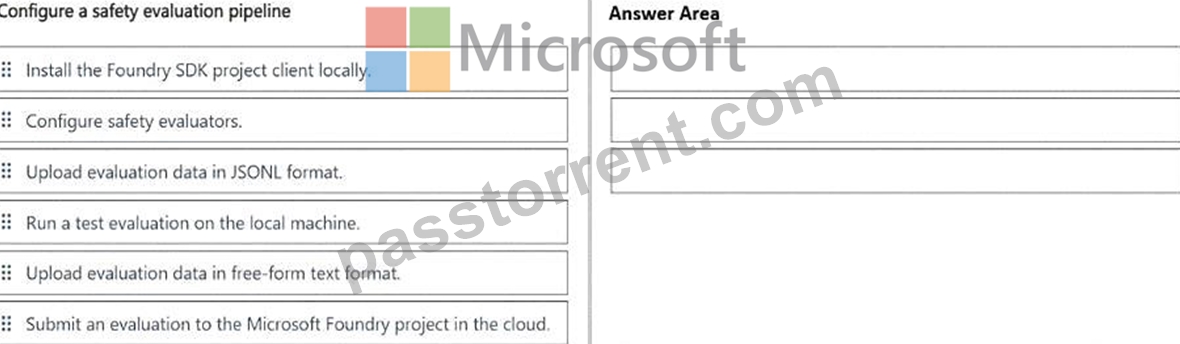
Answer:
Explanation: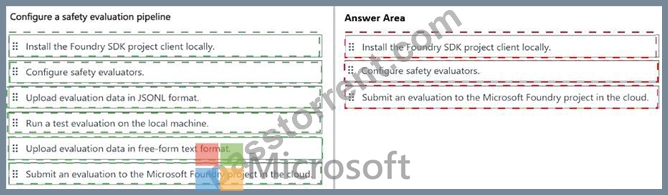
Explanation:
Correct sequence:
* Install the Foundry SDK project client locally.
* Configure safety evaluators.
* Submit an evaluation to the Microsoft Foundry project in the cloud.
The first step is to install and configure the Microsoft Foundry SDK project client . Microsoft documents the Foundry project client as the programmatic entry point for authenticating to a Foundry project and accessing its evaluation capabilities. The client typically uses DefaultAzureCredential, avoiding embedded credentials while enabling access to project resources.
Next, configure the safety evaluators that correspond to the risks that must be measured. Microsoft Foundry provides built-in safety evaluators for categories including Violence, Sexual content, Self-harm, and Hate
/Unfairness . These evaluators analyze generated responses and return structured safety assessments rather than relying on subjective manual review.
Finally, submit the evaluation to the Microsoft Foundry project in the cloud . Current Foundry evaluation workflows define the evaluator configuration, create an evaluation, and start an evaluation run in the project.
Results are persisted in Foundry for comparison, auditing, and CI/CD quality gates.
Uploading evaluation data is unnecessary because the scenario explicitly states that the dataset is already registered . Microsoft documentation specifically instructs users to skip dataset upload when a registered dataset already exists. Free-form text upload is also inappropriate because structured evaluation datasets use supported schemas such as JSONL or CSV.
Study Guide Reference: Implement generative AI quality assurance and observability - Foundry evaluations, safety evaluators, evaluation datasets, cloud evaluation runs, and harmful-content measurement.
NEW QUESTION # 86
Hotspot Question
You have an Azure Machine Learning workspace.
You plan to use Azure Machine Learning Python SDK v2 to register a component in the workspace. The component definition is stored in the local file ./components/train/train.yml.
You write code to connect to the workspace by using the ml_client object and import all required libraries.
You need to complete the remaining code.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.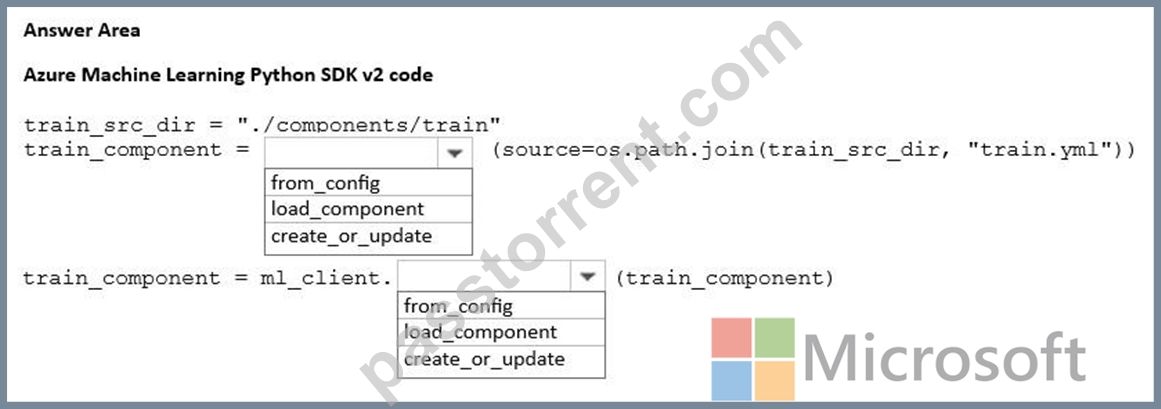
Answer:
Explanation: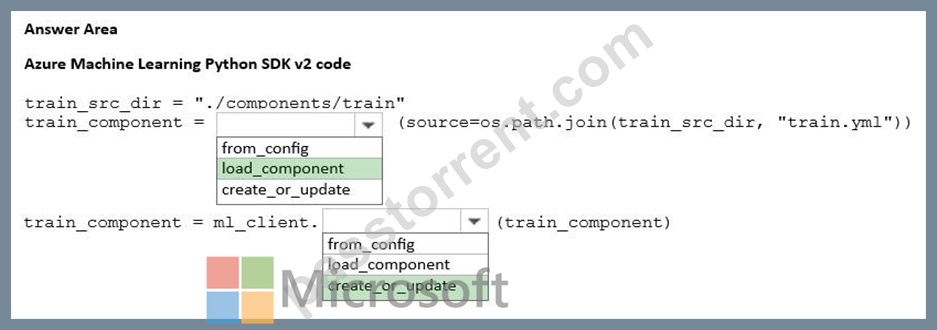
Explanation:
Box 1: load_component
train_component
Example:
Create component: training (using yaml definition)
Create and register the component. Registering it allows you to re-use it in other pipelines. Also, anyone else with access to your workspace can use the registered component.
# importing the Component Package
from azure.ai.ml import load_component
# Loading the component from the yml file
train_component = load_component(source=os.path.join(train_src_dir, "train.yml"))
# Now we register the component to the workspace
train_component = ml_client.create_or_update(train_component)
# Create (register) the component in your workspace
print(
f"Component {train_component.name} with Version {train_component.version} is registered" ) Box 2: create_or_update ml_client Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/tutorial-pipeline-python-sdk
NEW QUESTION # 87
A team uses a hosted Git repository to store training code and pipeline definitions of a machine learning experiment.
The team must ensure that access to the repository is granted without requiring each developer to store personal access tokens on their machines.
Repository access must be secure and centrally managed to reduce credential spread.
You need to enable secure access between an Azure Machine Learning workspace and the repository.
Answer: C
Explanation:
A managed identity is the appropriate credential model when an Azure-hosted workload requires centrally controlled, non-user authentication to another service that supports Microsoft Entra identities. Managed identities eliminate developer-managed credentials because Azure manages the identity lifecycle and obtains short-lived Microsoft Entra tokens at runtime. Microsoft explicitly identifies managed identities as a mechanism for Azure-hosted applications to authenticate without storing credentials, and Azure DevOps supports managed identities for secure automation and repository-related access.
This satisfies the key MLOps security requirement: authentication is associated with the workload rather than individual developers. Administrators can grant the identity only the required repository permissions, enforcing least privilege while centralizing authorization. Microsoft also recommends Microsoft Entra-based authentication over higher-risk PAT-based approaches for Azure Repos.
Option A spreads a reusable private credential among developers and creates unnecessary exposure. Option B still introduces a PAT that must be stored, protected, rotated, and revoked. Option C depends on individual interactive authentication and is unsuitable for reliable automated MLOps workflows. Microsoft documents managed identities and workload identities as approaches that eliminate persistent secrets and reduce credential-management overhead.
Study Guide Reference: Design and implement an MLOps infrastructure - source-control integration, workload authentication, managed identities, least-privilege access, and credential management.
NEW QUESTION # 88
You are preparing training data for a fine-tuning job in Microsoft Foundry.
Real production conversations cannot be used due to compliance requirements.
You need to generate synthetic interaction data that can be used for fine-tuning a generative model.
What should you do?
Answer: A
Explanation:
The correct approach is to generate synthetic prompt-response interactions that reproduce the structure and behavioral patterns of the target task. Microsoft Foundry supports synthetic data generation specifically for cases where real production data is unavailable, scarce, sensitive, or subject to privacy and compliance restrictions. Generated examples can be converted into the structured conversational format required for fine- tuning, such as JSONL containing messages with system, user, and assistant roles.
A simulator or synthetic-data generator can construct representative conversations without exposing genuine customer interactions. This allows the team to create sufficient task-specific examples, review their quality, remove unsuitable samples, and then use the resulting dataset for supervised fine-tuning. Microsoft notes that synthetic data can preserve useful task structure while avoiding reliance on proprietary or sensitive production datasets.
Option A is incorrect because evaluation logs are primarily intended for assessment and observability and are not automatically suitable as training examples. Option C directly violates the requirement because it captures real production traffic. Option D confuses training data with observability artifacts: telemetry logs and traces describe execution behavior and diagnostics rather than producing the prompt-response examples required for fine-tuning.
Study Guide Reference: Optimize generative AI systems and model performance - synthetic data generation, supervised fine-tuning datasets, simulator-based interaction generation, privacy-preserving model customization, and training-data preparation.
NEW QUESTION # 89
......
The PassTorrent is committed to making the entire AI-300 exam preparation journey simple, smart, and successful. To achieve this objective the PassTorrent is offering the top-rated and updated AI-300 exam practice test questions in three different formats. All these three PassTorrent AI-300 Exam Questions formats contain the real, valid, and error-free Operationalizing Machine Learning and Generative AI Solutions (AI-300) exam practice test questions that are ideal study material for quick Microsoft AI-300 exam preparation.
AI-300 Practice Test Online: https://www.passtorrent.com/AI-300-latest-torrent.html