Our online test engine and the windows software of the DP-750 study materials can evaluate your exercises of the virtual exam and practice exam intelligently. Our calculation system of the DP-750 study materials is designed subtly. Our evaluation process is absolutely correct. We are strictly in accordance with the detailed grading rules of the real exam. The point of every question is set separately. Once you submit your exercises of the DP-750 Study Materials, the calculation system will soon start to work.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> Microsoft DP-750 Real Questions <<
We have three versions of our DP-750 study materials, and they are PDF version, software version and online version. With the PDF version, you can print our materials onto paper and learn our DP-750 study materials in a more handy way as you can take notes whenever you want to, and you can mark out whatever you need to review later. With the software version, you are allowed to install our DP-750 study materials in all computers that operate in windows system. Besides, the software version can simulate the real test environment, which is favorable for people to better adapt to the examination atmosphere. With the online version, you can study the DP-750 Study Materials wherever you like, and you still have access to the materials even if there is no internet available on the premise that you have studied the DP-750 study materials online once before.
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: C
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 43
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.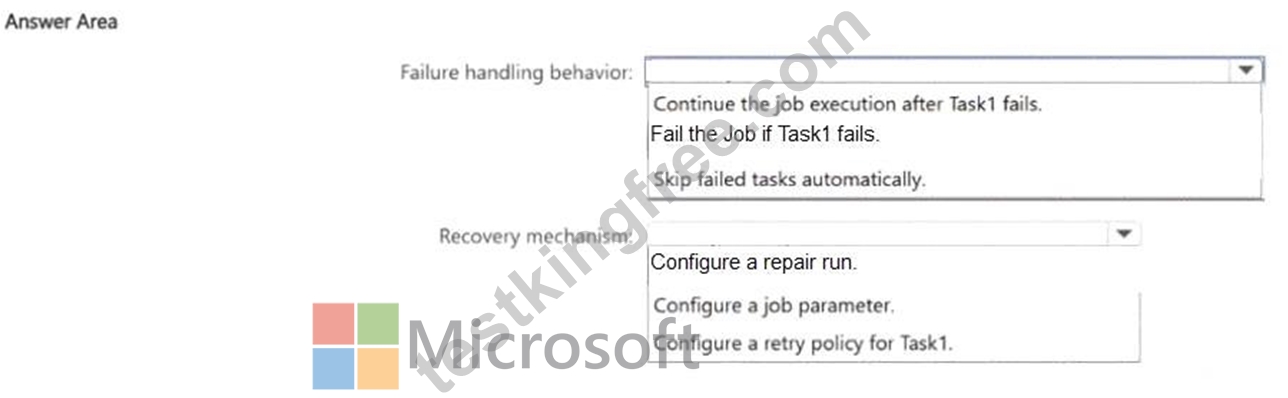
Answer:
Explanation: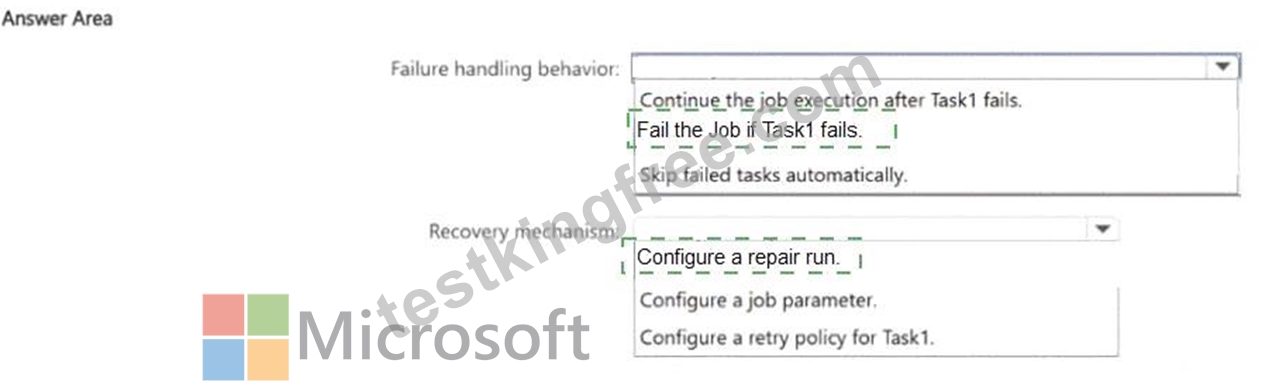
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 44
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.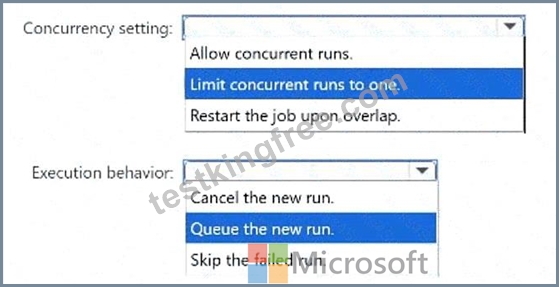
Answer:
Explanation: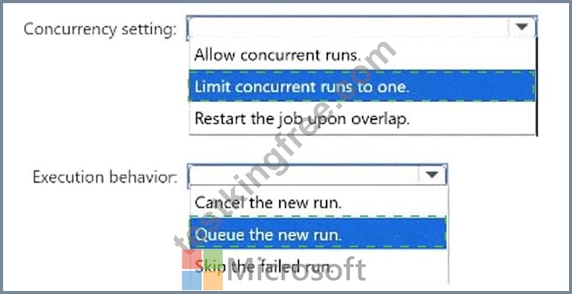
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
NEW QUESTION # 45
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
* New data must be available in near-real time (NRT).
* The data must be stored in managed Delta tables.
* The solution must minimize custom code and maintenance effort.
What should you include in the solution?
Answer: A
Explanation:
The correct answer is A - Auto Loader.
Auto Loader is exactly the right tool for this scenario: new CSV files land in ADLS Gen2, and they need to be ingested into managed Delta tables in near-real time with minimal custom code. Auto Loader uses file-system notifications or incremental directory listing to detect new arrivals, processes only the newly added files (skipping previously ingested ones), and writes results into Delta tables - all with schema inference and evolution support built in.
Option B (scheduled Spark batch jobs) adds latency tied to the schedule interval and requires custom 'what files have I already processed' tracking. Option C (external table referencing CSV files) exposes the raw files for querying but doesn't load data into managed Delta tables - it also can't provide NRT updates as files change. Option D (Azure Data Factory pipeline) introduces external orchestration overhead and is a heavier solution for something Auto Loader handles natively in a few lines of PySpark.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 47
......
If you want to get satisfaction with the preparation and get desire result in the DP-750 real exam then you must need to practice our Microsoft braindumps and latest questions because it is very useful for preparation. You will feel the atmosphere of DP-750 Actual Test with our online test engine and test your ability in any time without any limitation. There are also DP-750 free demo in our website for you download.
Guaranteed DP-750 Questions Answers: https://www.testkingfree.com/Microsoft/DP-750-practice-exam-dumps.html