Valid Databricks-Certified-Data-Engineer-Associate Test Forum Exam Instant Download | Updated Passing Databricks-Certified-Data-Engineer-Associate Score Feedback
We have always taken care to provide the best Databricks Databricks-Certified-Data-Engineer-Associate exam dumps to our customers. That's why we offer many other benefits with our product. We provide a demo version of the real product to our customers to clear their doubts about the truthfulness and accuracy of Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) preparation material. You can try the product before you buy it.
| Section | Weight | Objectives |
|---|
| Development and Ingestion | 30% | - Data ingestion patterns and methods
- 1. Delta Lake basics and usage
- 2. Batch and streaming ingestion
- 3. Connecting to external data sources
- Notebook development fundamentals
- 1. Data exploration and validation
- 2. Using PySpark and Spark SQL
|
| Data Processing & Transformations | 31% | - Query optimization and performance
- 1. Understanding query plans
- 2. Optimization strategies
- Data transformation techniques
- 1. DataFrame operations and transformations
- 2. Complex data processing logic
- 3. Aggregations, joins, and window functions
|
| Productionizing Data Pipelines | 18% | - Deployment and CI/CD
- 1. Version control integration
- 2. Databricks Asset Bundles
- Workflow orchestration
- 1. Lakeflow Jobs creation and management
- 2. Scheduling, triggers, and dependencies
- Monitoring and troubleshooting
- 1. Logging and error handling
- 2. Pipeline reliability and recovery
|
| Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
- 1. Data layout and optimization: partitioning, file sizing, caching
- 2. Compute options: clusters, SQL warehouses, serverless
- 3. Workspace navigation and management
|
| Data Governance & Quality | 11% | - Unity Catalog implementation
- 1. Permissions and access control
- 2. Data governance model
- Data quality and reliability
- 1. Data validation and quality checks
- 2. Schema enforcement and evolution
|
>> Valid Databricks-Certified-Data-Engineer-Associate Test Forum <<
Passing Databricks-Certified-Data-Engineer-Associate Score Feedback | Databricks-Certified-Data-Engineer-Associate Valid Dumps Ebook
So rest assured that with the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice questions you will not only make the entire Databricks-Certified-Data-Engineer-Associate exam dumps preparation process and enable you to perform well in the final Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) certification exam with good scores. To provide you with the updated Databricks Databricks-Certified-Data-Engineer-Associate Exam Questions the Databricks offers three months updated Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam dumps download facility, Now you can download our updated Databricks-Certified-Data-Engineer-Associate practice questions up to three months from the date of Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam purchase.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q91-Q96):
NEW QUESTION # 91
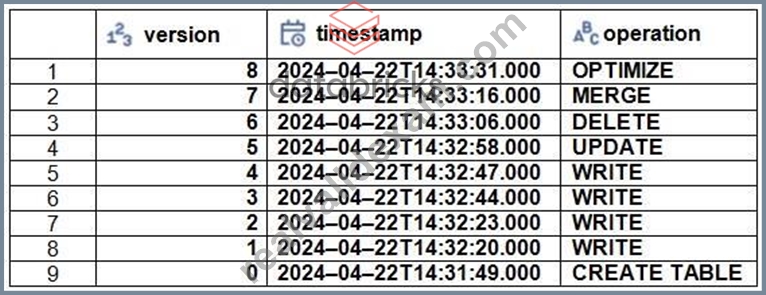
The Delta transaction log for the 'students' tables is shown using the 'DESCRIBE HISTORY students' command. A Data Engineer needs to query the table as it existed before the UPDATE operation listed in the log. Which command should the Data Engineer use to achieve this?
(Choose two.)
- A. SELECT * FROM students TIMESTAMP AS OF '2024-04-22T14:32:47.000+00:00'
- B. SELECT * FROM students FROM HISTORY VERSION AS OF 3
- C. SELECT * FROM students@v4
- D. SELECT * FROM students TIMESTAMP AS OF '2024-04-22T14:32:58.000+00:00'
- E. SELECT * FROM students VERSION AS OF 5
Answer: A,C
Explanation:
The Data Engineer wants to query the students table as it existed before the UPDATE operation.
Based on the log, the UPDATE operation happened at version 5, with the timestamp 2024-04-
22T14:32:58.000+00:00. Therefore, the table needs to be queried as it existed at version 4 or earlier, which corresponds to before the update operation.
SELECT * FROM students@v4: This will retrieve the table as it was at version 4, which is before the update, so this is correct.
SELECT * FROM students TIMESTAMP AS OF '2024-04-22T14:32:47.000+00:00': This retrieves the table as it existed before the update, using the timestamp of version 4, so this is also correct.
NEW QUESTION # 92
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. The data engineer wants to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing.
Which role must be in place to perform these actions across the metastore?
- A. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
- B. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
- C. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- D. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
Answer: C
Explanation:
In Unity Catalog, the Metastore Admin role has the highest level of authority within a metastore and is responsible for governing all data assets registered in that metastore. Metastore admins can transfer ownership of catalogs, manage privileges across all securable objects (catalogs, schemas, tables, views), and administer storage credentials, external locations, and Delta Sharing objects such as shares and recipients.
This makes the role essential when a platform owner departs and continuity must be maintained at an organizational level. Workspace admins (option B) manage workspace-level settings but do not automatically have authority over Unity Catalog ownership unless explicitly granted. Catalog owners (option D) are limited to a single catalog and cannot perform actions across the entire metastore. Account admins (option A) operate at the account level and are primarily responsible for creating metastores and assigning admins, not for day-to-day governance within an existing metastore. Databricks documentation clearly defines the Metastore Admin as the role required to centrally manage ownership, privileges, and data sharing across the metastore in Databricks.
NEW QUESTION # 93
A data engineer triggers a scheduled job but finds that the new run was not executed. The run history shows that the run was skipped with a concurrency-related queue message.
Which configuration should the engineer investigate?
- A. The cluster spot-instance availability in the cloud provider
- B. The job-level max_concurrent_runs setting and whether queueing is enabled
- C. The task-level timeout_seconds configuration
- D. The SQL warehouse permissions for the task
Answer: B
Explanation:
The engineer should inspect the job's maximum concurrent-runs configuration and its queueing setting. max_concurrent_runs controls how many active runs of the same job can execute simultaneously. When that limit has already been reached, Databricks can skip the newly triggered run if queueing is disabled. When queueing is enabled, the additional run waits until capacity becomes available instead of being skipped. Spot-instance availability might delay or prevent compute startup, but it would not normally produce a job-level concurrency message. SQL warehouse permissions affect SQL task execution after a run begins, while timeout_seconds determines how long a task may run before timing out. Therefore, option C directly addresses the reported run state. This candidate was also compared against the existing Word question bank.
NEW QUESTION # 94
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The cade block used by the data engineer is below:
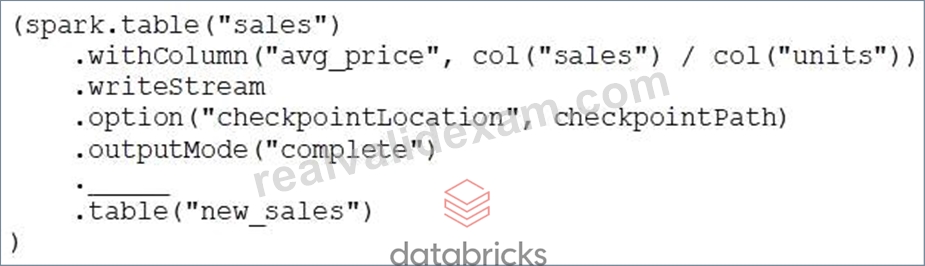
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
- A. trigger(processingTime="5 seconds")
- B. trigger()
- C. trigger(once="5 seconds")
- D. trigger("5 seconds")
- E. trigger(continuous="5 seconds")
Answer: A
Explanation:
The processingTime option specifies a time-based trigger interval for fixed interval micro-batches. This means that the query will execute a micro-batch to process data every 5 seconds, regardless of how much data is available. This option is suitable for near-real time processing workloads that require low latency and consistent processing frequency. The other options are either invalid syntax (A, C), default behavior (B), or experimental feature (E). References: Databricks Documentation - Configure Structured Streaming trigger intervals, Databricks Documentation - Trigger.
NEW QUESTION # 95
A Delta Live Table pipeline includes two datasets defined using streaming live table. Three datasets are defined against Delta Lake table sources using live table.
The table is configured to run in Production mode using the Continuous Pipeline Mode.
What is the expected outcome after clicking Start to update the pipeline assuming previously unprocessed data exists and all definitions are valid?
- A. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will be deployed for the update and terminated when the pipeline is stopped.
- B. All datasets will be updated at set intervals until the pipeline is shut down. The compute resources will persist to allow for additional testing.
- C. All datasets will be updated once and the pipeline will shut down. The compute resources will be terminated.
- D. All datasets will be updated once and the pipeline will shut down. The compute resources will persist to allow for additional testing.
Answer: A
Explanation:
In Delta Live Tables (DLT), when configured to run in Continuous Pipeline Mode, particularly in a production environment, the system is designed to continuously process and update data as it becomes available. This mode keeps the compute resources active to handle ongoing data processing and automatically updates all datasets defined in the pipeline at predefined intervals. Once the pipeline is manually stopped, the compute resources are terminated to conserve resources and reduce costs. This mode is suitable for production environments where datasets need to be kept up-to-date with the latest data.
NEW QUESTION # 96
......
You can use this Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) practice exam software to test and enhance your Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam preparation. Your practice will be made easier by having the option to customize the Databricks in Databricks-Certified-Data-Engineer-Associate exam dumps. Only Windows-based computers can run this Databricks Databricks-Certified-Data-Engineer-Associate Exam simulation software. The fact that it runs without an active internet connection is an incredible comfort for users who don't have access to the internet all the time.
Passing Databricks-Certified-Data-Engineer-Associate Score Feedback: https://www.realvalidexam.com/Databricks-Certified-Data-Engineer-Associate-real-exam-dumps.html
- 100% Pass Quiz 2026 Pass-Sure Databricks Valid Databricks-Certified-Data-Engineer-Associate Test Forum 🚉 Copy URL ➡ www.practicevce.com ️⬅️ open and search for ▷ Databricks-Certified-Data-Engineer-Associate ◁ to download for free 👮Databricks-Certified-Data-Engineer-Associate Valid Exam Papers
- Valid Valid Databricks-Certified-Data-Engineer-Associate Test Forum, Ensure to pass the Databricks-Certified-Data-Engineer-Associate Exam 🔲 The page for free download of ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ on ➡ www.pdfvce.com ️⬅️ will open immediately 🥢Best Databricks-Certified-Data-Engineer-Associate Preparation Materials
- Don't Miss Up to 365 Days of Free Updates - Buy Databricks-Certified-Data-Engineer-Associate Questions Now 🍂 Download ▷ Databricks-Certified-Data-Engineer-Associate ◁ for free by simply entering ⇛ www.examcollectionpass.com ⇚ website 🤾New Databricks-Certified-Data-Engineer-Associate Dumps Files
- Exam Databricks-Certified-Data-Engineer-Associate Actual Tests 🏛 Best Databricks-Certified-Data-Engineer-Associate Preparation Materials 😫 Databricks-Certified-Data-Engineer-Associate Latest Test Cost 🐂 Search for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ and easily obtain a free download on { www.pdfvce.com } 🌕Databricks-Certified-Data-Engineer-Associate Valid Test Discount
- Databricks-Certified-Data-Engineer-Associate Free Exam Dumps 🌌 New Databricks-Certified-Data-Engineer-Associate Dumps Files 😗 Databricks-Certified-Data-Engineer-Associate Latest Test Cost 🥐 Search for 【 Databricks-Certified-Data-Engineer-Associate 】 on [ www.torrentvce.com ] immediately to obtain a free download 😷Databricks-Certified-Data-Engineer-Associate Reliable Exam Simulations
- Reliable Databricks Databricks-Certified-Data-Engineer-Associate Online Practice Test Engine ⏩ Easily obtain ➽ Databricks-Certified-Data-Engineer-Associate 🢪 for free download through [ www.pdfvce.com ] 🙋Online Databricks-Certified-Data-Engineer-Associate Tests
- Online Databricks-Certified-Data-Engineer-Associate Tests 💺 Databricks-Certified-Data-Engineer-Associate Reliable Exam Simulations 🧢 High Databricks-Certified-Data-Engineer-Associate Quality 🛩 Download 「 Databricks-Certified-Data-Engineer-Associate 」 for free by simply entering 「 www.prepawayete.com 」 website 🥚Valid Databricks-Certified-Data-Engineer-Associate Guide Files
- Valid Valid Databricks-Certified-Data-Engineer-Associate Test Forum, Ensure to pass the Databricks-Certified-Data-Engineer-Associate Exam 💁 Open ▶ www.pdfvce.com ◀ enter 【 Databricks-Certified-Data-Engineer-Associate 】 and obtain a free download 🍖Databricks-Certified-Data-Engineer-Associate Latest Test Cost
- Databricks's Exam Questions for Databricks-Certified-Data-Engineer-Associate Ensure 100% Success on Your First Attempt 🗯 Search for ✔ Databricks-Certified-Data-Engineer-Associate ️✔️ and download it for free on ➤ www.validtorrent.com ⮘ website 🃏New Databricks-Certified-Data-Engineer-Associate Dumps Files
- Best Databricks-Certified-Data-Engineer-Associate Preparation Materials 🐫 Databricks-Certified-Data-Engineer-Associate Practice Test Engine 🚬 Databricks-Certified-Data-Engineer-Associate Latest Test Cost 🍭 Search for ➽ Databricks-Certified-Data-Engineer-Associate 🢪 and download exam materials for free through [ www.pdfvce.com ] 🤱Databricks-Certified-Data-Engineer-Associate Free Exam Dumps
- Guaranteed Databricks-Certified-Data-Engineer-Associate Success 🎱 Best Databricks-Certified-Data-Engineer-Associate Preparation Materials 🛀 Databricks-Certified-Data-Engineer-Associate Latest Test Cost 👷 Copy URL ▶ www.prepawayexam.com ◀ open and search for 《 Databricks-Certified-Data-Engineer-Associate 》 to download for free 🥡Online Databricks-Certified-Data-Engineer-Associate Tests
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.intensedebate.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes