The Best Exam Certified-Data-Engineer-Professional Forum | Amazing Pass Rate For Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional | Trustable Latest Braindumps Certified-Data-Engineer-Professional Book

Databricks Certified Data Engineer Professional has introduced practice test (desktop and web-based) for the students so they can practice anytime in an easy way. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice tests are customizable which means the students can set the time and questions according to their needs. The Certified-Data-Engineer-Professional Practice Tests have unlimited tries so that the users don't make extra mistakes when giving it the next time. Candidates can access the previously given tries from the history and avoid making mistakes in the final examination.
| Section | Objectives |
|---|
| Topic 1: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Compare streaming tables and materialized views
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Use control flow operators in pipeline components
- 7. Develop unit and integration tests for data processing code
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 3: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 4: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 5: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 6: Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Topic 7: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
|
| Topic 8: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 9: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
>> Exam Certified-Data-Engineer-Professional Forum <<
Free PDF Quiz Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Marvelous Exam Forum
Now we can say that Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions are real and top-notch Databricks Certified-Data-Engineer-Professional exam questions that you can expect in the upcoming Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam. In this way, you can easily pass the Certified-Data-Engineer-Professional exam with good scores. The countless Certified-Data-Engineer-Professional Exam candidates have passed their dream Certified-Data-Engineer-Professional certification exam and they all got help from real, valid, and updated Certified-Data-Engineer-Professional practice questions, You can also trust on SureTorrent and start preparation with confidence.
Databricks Certified Data Engineer Professional Sample Questions (Q40-Q45):
NEW QUESTION # 40
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
- B. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
Answer: A
Explanation:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
NEW QUESTION # 41
A company has a task management system that tracks the most recent status of tasks. The system takes task events as input and processes events in near real-time using Lakeflow Declarative Pipelines. A new task event is ingested into the system when a task is created or the task status is changed. Lakeflow Declarative Pipelines provides a streaming table (tasks_status) for BI users to query.
The table represents the latest status of all tasks and includes 5 columns:
task_id (unique for each task)
task_name
task_owner
task_status
task_event_time
The table enables three properties: deletion vectors, row tracking, and change data feed (CDF).
A data engineer is asked to create a new Lakeflow Declarative Pipeline to enrich the tasks_status table in near real-time by adding one additional column representing task_owner's department, which can be looked up from a static dimension table (employee).
How should this enrichment be implemented?
- A. Create a new Lakeflow Declarative Pipeline: use the readStream() function with the option skipChangeCommits to read the tasks_status table; enrich with the employee table; store the result in a new streaming table.
- B. Create a new Lakeflow Declarative Pipeline: use readStream() function with option readChangeFeed to read tasks_status table CDF; enrich with the employee table; create a new streaming table as the result table and use apply_changes() function to process the changes from the enriched CDF.
- C. Create a new Lakeflow Declarative Pipeline: use the read() function to read tasks_status table; enrich with employee table; store the result in a materialized view.
- D. Create a new Lakeflow Declarative Pipeline: use the readStream() function to read tasks_status table; enrich with the employee table; store the result in a new streaming table.
Answer: B
Explanation:
Change Data Feed (CDF) allows downstream consumers to read incremental changes (inserts, updates, deletes) from a Delta table. The documentation explains that when streaming from a Delta table with CDF enabled, developers can use readStream().option("readChangeFeed","true") to capture incremental events. For maintaining a derived table with enrichment logic, the recommended practice is to use apply_changes(), which applies CDC semantics (insert/update/delete) correctly to the target streaming table. By joining with the static employee dimension, enriched rows are generated before being merged into the new streaming target. This ensures correctness, scalability, and minimal latency. Batch reads or skipping commits do not maintain correctness for CDC pipelines.
NEW QUESTION # 42
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
- A. Cluster: New Job Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: Unlimited - B. Cluster: New Job Cluster;
Retries: None;
Maximum Concurrent Runs: 1 - C. Cluster: Existing All-Purpose Cluster;
Retries: None;
Maximum Concurrent Runs: 1 - D. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1 - E. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1
Answer: D
Explanation:
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job.
Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency. Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption. Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
NEW QUESTION # 43
A data engineering team needs to create a SQL Alert that monitors data quality across multiple columns in their customer table. They want to trigger an alert when both the percentage of customers with missing email addresses exceeds 15% AND the percentage of customers with invalid phone number formats exceeds 10%. Which SQL query pattern is appropriate for implementing this multi-column alert condition?
- A. SELECT CASE WHEN email_null_pct >15 AND phone_invalid_pct> 10 THEN 1 ELSE 0 END FROM (SELECT (COUNT (CASE WHEN email IS NULL THEN 1 END) * 100.0 / COUNT (*)) as phone_invalid_pct FROM customers) metrics
- B. SELECT COUNT (*) FROM customers WHERE email IS NULL OR phone_format_invalid = true
- C. SELECT email, phone FROM customers WHERE email IS NULL AND phone NOT RLIKE 'ˆ[0-9-
+()\\s]+$' - D. SELECT email_null_pct, phone_invalid_pct FROM (SELECT (COUNT(CASE WHEN email IS NULL THEN 1 END) *
100.0/COUNT (*)) as email_null_pct, (COUNT(CASE WHEN phone NOT RLIKE 'ˆ[0-9-+()\\s]+$' THEN 1 END)*
100.0/COUNT (*)) as phone_invalid_pct FROM customers)
Answer: D
Explanation:
This pattern computes independent percentage metrics for each data quality condition in a single aggregated query. By calculating the percentage of missing emails and invalid phone formats as separate columns, it enables the SQL Alert to evaluate a compound condition where both thresholds must be exceeded before triggering.
NEW QUESTION # 44
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
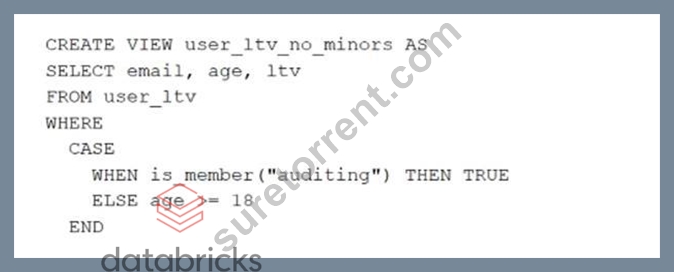
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All records from all columns will be displayed with the values in user_ltv.
- B. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
- E. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 45
......
The clients can download our Certified-Data-Engineer-Professional exam questions and use our them immediately after they pay successfully. Our system will send our Certified-Data-Engineer-Professional learning prep in the form of mails to the client in 5-10 minutes after their successful payment. The mails provide the links and if only the clients click on the links they can log in our software immediately to learn our Certified-Data-Engineer-Professional Guide materials. It is fast and convenient!
Latest Braindumps Certified-Data-Engineer-Professional Book: https://www.suretorrent.com/Certified-Data-Engineer-Professional-exam-guide-torrent.html
- New Certified-Data-Engineer-Professional Test Braindumps 🟪 Certified-Data-Engineer-Professional Vce Exam 🥤 Exam Certified-Data-Engineer-Professional Blueprint 🤲 Copy URL ✔ www.examcollectionpass.com ️✔️ open and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free ⬜New Certified-Data-Engineer-Professional Test Braindumps
- 2026 Exam Certified-Data-Engineer-Professional Forum | Latest Latest Braindumps Certified-Data-Engineer-Professional Book: Databricks Certified Data Engineer Professional 100% Pass 🔥 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ▷ www.pdfvce.com ◁ 🚛Dumps Certified-Data-Engineer-Professional Free
- Free PDF 2026 Useful Databricks Exam Certified-Data-Engineer-Professional Forum 🔸 Search for ➡ Certified-Data-Engineer-Professional ️⬅️ and download it for free immediately on ▶ www.prepawaypdf.com ◀ 🥈Certified-Data-Engineer-Professional Latest Dumps Files
- Valid Study Certified-Data-Engineer-Professional Questions 🔗 Certified-Data-Engineer-Professional Instant Access 🍕 New Certified-Data-Engineer-Professional Test Braindumps ❓ Open website ☀ www.pdfvce.com ️☀️ and search for 「 Certified-Data-Engineer-Professional 」 for free download 🎈Certified-Data-Engineer-Professional Certification Dumps
- Quiz Databricks - Efficient Certified-Data-Engineer-Professional - Exam Databricks Certified Data Engineer Professional Forum 🧷 Open ⇛ www.prepawaypdf.com ⇚ enter 【 Certified-Data-Engineer-Professional 】 and obtain a free download 🟣Certified-Data-Engineer-Professional Reliable Test Price
- Exam Certified-Data-Engineer-Professional Blueprint 👤 Certified-Data-Engineer-Professional Instant Access 🪓 Actual Certified-Data-Engineer-Professional Test Pdf 🎇 Easily obtain free download of ☀ Certified-Data-Engineer-Professional ️☀️ by searching on 「 www.pdfvce.com 」 🐝Dumps Certified-Data-Engineer-Professional Free
- 100% Pass 2026 Certified-Data-Engineer-Professional: Authoritative Exam Databricks Certified Data Engineer Professional Forum 🌳 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download it for free immediately on ▷ www.easy4engine.com ◁ 🐓New Certified-Data-Engineer-Professional Test Tips
- Certified-Data-Engineer-Professional Latest Dumps Files ⏲ Valid Study Certified-Data-Engineer-Professional Questions 🐛 Certified-Data-Engineer-Professional Exam Preparation 😱 Search for “ Certified-Data-Engineer-Professional ” on “ www.pdfvce.com ” immediately to obtain a free download 🚕Certified-Data-Engineer-Professional Vce Exam
- Experience the Real Time Databricks Certified-Data-Engineer-Professional Exam Environment 🆕 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ➥ www.troytecdumps.com 🡄 🕺New Certified-Data-Engineer-Professional Test Braindumps
- New Certified-Data-Engineer-Professional Test Tips 🤺 Certified-Data-Engineer-Professional Vce Exam 🤷 Certified-Data-Engineer-Professional Exam Preparation ⭐ Go to website 【 www.pdfvce.com 】 open and search for ▛ Certified-Data-Engineer-Professional ▟ to download for free 🎷Certified-Data-Engineer-Professional Reliable Dumps Pdf
- Free PDF 2026 Useful Databricks Exam Certified-Data-Engineer-Professional Forum 🏠 Search on ➡ www.practicevce.com ️⬅️ for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain exam materials for free download 🆔New Certified-Data-Engineer-Professional Test Braindumps
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.zazzle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes