What's more, part of that Real4Prep Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1cXM_xv7lZQMRSSEQxyYEKwjj1nWugYm5
Real4Prep has designed Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) pdf dumps format that is easy to use. Anyone can download the Databricks Databricks-Certified-Data-Engineer-Associate pdf questions file and use it from any location or at any time. Databricks PDF Questions files can be used on laptops, tablets, and smartphones. Moreover, you will get actual Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam questions in this Databricks Databricks-Certified-Data-Engineer-Associate pdf dumps file. These Databricks Databricks-Certified-Data-Engineer-Associate exam questions have a high chance of coming in the actual Databricks-Certified-Data-Engineer-Associate test. You have to memorize these Databricks-Certified-Data-Engineer-Associate questions and you will pass the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) test with brilliant results.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Data Engineer Associate Exam |
| Exam Number: | Databricks-Certified-Data-Engineer-Associate |
| Exam Duration: | 90 minutes |
| Related Certifications: | Databricks Certified Data Engineer Professional Databricks Certified Data Analyst Associate |
| Passing Score: | Not publicly disclosed, approximately 70% |
| Exam Format: | Proctored, Multiple choice |
| Certificate Validity Period: | 2 years |
| Real Exam Qty: | 45 |
| Available Languages: | English, Portuguese (Brazil), Korean, Japanese |
| Exam Price: | 200 USD |
| Recommended Training: | Databricks Documentation Databricks Academy - Data Engineer Associate Learning Path |
| Exam Registration: | Official Registration |
| Sample Questions: | Databricks Databricks-Certified-Data-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored or in-person at authorized test centers |
| Pre Condition: | No mandatory prerequisites; 6+ months hands-on experience with Databricks and data engineering tasks recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-associate |
>> Exam Databricks-Certified-Data-Engineer-Associate Materials <<
The clients can have a free download and tryout of our Databricks-Certified-Data-Engineer-Associate test practice dump before they decide to buy our products. They can use our products immediately after they pay for the Databricks-Certified-Data-Engineer-Associate test practice dump successfully. If the clients are unlucky to fail in the test we will refund them as quickly as we can. There are so many advantages of our products that we can’t summarize them with several simple words. You’d better look at the introduction of our Databricks-Certified-Data-Engineer-Associate Exam Questions in detail as follow by yourselves.
Databricks Certified Data Engineer Associate certification is essential for individuals who want to work with big data and build scalable data pipelines. Databricks Certified Data Engineer Associate Exam certification exam covers a range of topics, including data modeling, data ingestion, data transformation, data storage, and data processing. Candidates will also be tested on their knowledge of Apache Spark, a popular open-source data processing engine, and Databricks Unified Analytics Platform.
NEW QUESTION # 67
A data engineer is designing a Bronze-to-Silver pipeline on the Databricks Data Intelligence Platform. The source system sends daily CSV files, and new optional columns are added over time.
The engineer needs a storage format and table capabilities that provide all of the following:
Writes that do not conform to the defined schema are rejected.
The schema can evolve to include new optional columns without manually recreating the table.
Previous table versions can be queried for debugging and auditing.
Which solution fulfills these requirements?
Answer: C
NEW QUESTION # 68
A data engineer has configured a Structured Streaming job to read from a table, manipulate the data, and then perform a streaming write into a new table.
The code block used by the data engineer is below: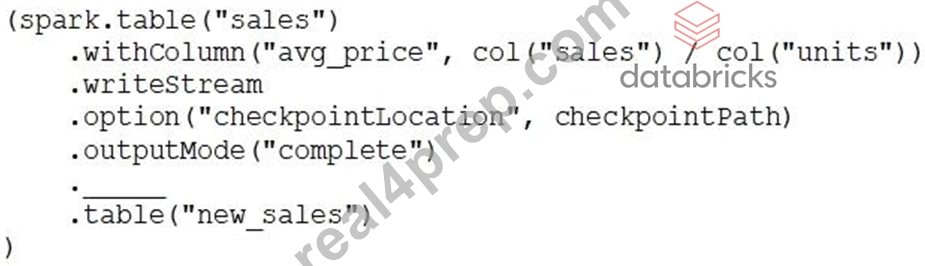
If the data engineer only wants the query to execute a micro-batch to process data every 5 seconds, which of the following lines of code should the data engineer use to fill in the blank?
Answer: C
NEW QUESTION # 69
A data engineer has realized that the data files associated with a Delta table are incredibly small. They want to compact the small files to form larger files to improve performance.
Which of the following keywords can be used to compact the small files?
Answer: E
Explanation:
The keyword that can be used to compact the small files associated with a Delta table is OPTIMIZE. The OPTIMIZE command performs file compaction on a Delta table by rewriting a set of small files into a set of larger files1. This can improve the performance of queries that scan the table by reducing the number of files that need to be read and the amount of metadata that needs to be processed1. The OPTIMIZE command can also optionally sort the data within each file by a given set of columns, which can further improve the query performance by enabling data skipping and predicate pushdown1. The OPTIMIZE command can be applied to the whole table or to a specific partition of the table1.
The other keywords are not suitable for compacting the small files associated with a Delta table. REDUCE is a keyword used in the SQL syntax for aggregating data using a user-defined function2. COMPACTION is not a valid keyword in SQL or Python. REPARTITION is a keyword used in the Python syntax for changing the number of partitions of a DataFrame or an RDD3. VACUUM is a keyword used to remove files that are no longer referenced by a Delta table and are older than a retention threshold4.
:
1: OPTIMIZE | Databricks on AWS
2: REDUCE | Databricks on AWS
3: repartition | Databricks on AWS
4: VACUUM | Databricks on AWS
NEW QUESTION # 70
A data engineer has written a function in a Databricks Notebook to calculate the population of bacteria in a given medium.
Analysts use this function in the notebook and sometimes provide input arguments of the wrong data type, which can cause errors during execution.
Which Databricks feature will help the data engineer quickly identify if an incorrect data type has been provided as input?
Answer: C
NEW QUESTION # 71
A data engineer is building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliable completion of the pipeline are the highest priorities.
Which type of Databricks cluster should the data engineer configure?
Answer: B
Explanation:
For large-scale batch ETL workloads, Databricks documentation recommends using job clusters that are created specifically for a job run and terminated automatically when the job completes. A job cluster with autoscaling enabled provides the best balance of performance, reliability, and cost efficiency for long- running nightly pipelines. Autoscaling allows the cluster to dynamically add or remove worker nodes based on the workload demands, ensuring sufficient parallelism to process very large JSON datasets efficiently while avoiding overprovisioning when demand decreases. This is especially important when processing raw data into Delta tables, where shuffle-heavy transformations and writes benefit from multiple workers. Single- node clusters (option B) are not suitable for very large volumes of data and risk excessive runtimes or job failures. High-concurrency clusters (option C) are optimized for interactive and concurrent SQL queries, not long-running batch ETL jobs. Always-on all-purpose clusters (option D) increase costs unnecessarily and are intended for interactive development, not scheduled production pipelines. Databricks best practices clearly position autoscaling job clusters as the preferred solution for reliable, cost-effective batch ETL in production on Databricks.
NEW QUESTION # 72
......
Databricks-Certified-Data-Engineer-Associate Reliable Test Sample: https://www.real4prep.com/Databricks-Certified-Data-Engineer-Associate-exam.html
BONUS!!! Download part of Real4Prep Databricks-Certified-Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=1cXM_xv7lZQMRSSEQxyYEKwjj1nWugYm5