How Test4Sure MLA-C01 Practice Questions Can Help You Pass the Exam

What's more, part of that Test4Sure MLA-C01 dumps now are free: https://drive.google.com/open?id=10PPgbQjLrz_HPOhCoMejHXop_7ODIpNC
Therefore, it is indispensable to choose a trusted website for real MLA-C01 dumps. Test4Sure is one of the most reliable platforms to get actual MLA-C01 dumps. It offers the latest and valid real AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam dumps. The product of Test4Sure is available in Amazon MLA-C01 PDF, desktop MLA-C01 practice exam software, and web-based AWS Certified Machine Learning Engineer - Associate practice test.
| Topic | Details |
|---|
| Topic 1 | - Data Preparation for Machine Learning (ML): This section of the exam measures skills of Forensic Data Analysts and covers collecting, storing, and preparing data for machine learning. It focuses on understanding different data formats, ingestion methods, and AWS tools used to process and transform data. Candidates are expected to clean and engineer features, ensure data integrity, and address biases or compliance issues, which are crucial for preparing high-quality datasets in fraud analysis contexts.
|
| Topic 2 | - ML Solution Monitoring, Maintenance, and Security: This section of the exam measures skills of Fraud Examiners and assesses the ability to monitor machine learning models, manage infrastructure costs, and apply security best practices. It includes setting up model performance tracking, detecting drift, and using AWS tools for logging and alerts. Candidates are also tested on configuring access controls, auditing environments, and maintaining compliance in sensitive data environments like financial fraud detection.
|
| Topic 3 | - ML Model Development: This section of the exam measures skills of Fraud Examiners and covers choosing and training machine learning models to solve business problems such as fraud detection. It includes selecting algorithms, using built-in or custom models, tuning parameters, and evaluating performance with standard metrics. The domain emphasizes refining models to avoid overfitting and maintaining version control to support ongoing investigations and audit trails.
|
| Topic 4 | - Deployment and Orchestration of ML Workflows: This section of the exam measures skills of Forensic Data Analysts and focuses on deploying machine learning models into production environments. It covers choosing the right infrastructure, managing containers, automating scaling, and orchestrating workflows through CI
- CD pipelines. Candidates must be able to build and script environments that support consistent deployment and efficient retraining cycles in real-world fraud detection systems.
|
>> MLA-C01 PDF Question <<
2026 Amazon The Best MLA-C01: AWS Certified Machine Learning Engineer - Associate PDF Question
Our MLA-C01 practice engine boosts high quality and we provide the wonderful service to the client. We boost the top-ranking expert team which compiles our MLA-C01 guide prep elaborately and check whether there is the update every day and if there is the update the system will send the update automatically to the client. The content of our MLA-C01 Preparation questions is easy to be mastered and seizes the focus to use the least amount of answers and questions to convey the most important information.
Amazon AWS Certified Machine Learning Engineer - Associate Sample Questions (Q226-Q231):
NEW QUESTION # 226
A company stores time-series data about user clicks in an Amazon S3 bucket. The raw data consists of millions of rows of user activity every day. ML engineers access the data to develop their ML models.
The ML engineers need to generate daily reports and analyze click trends over the past 3 days by using Amazon Athena. The company must retain the data for 30 days before archiving the data.
Which solution will provide the HIGHEST performance for data retrieval?
- A. Organize the time-series data into partitions by date prefix in the S3 bucket. Apply S3 Lifecycle policies to archive partitions that are older than 30 days to S3 Glacier Flexible Retrieval.
- B. Put each day's time-series data into its own S3 bucket. Use S3 Lifecycle policies to archive S3 buckets that hold data that is older than 30 days to S3 Glacier Flexible Retrieval.
- C. Keep all the time-series data without partitioning in the S3 bucket. Manually move data that is older than 30 days to separate S3 buckets.
- D. Create AWS Lambda functions to copy the time-series data into separate S3 buckets. Apply S3 Lifecycle policies to archive data that is older than 30 days to S3 Glacier Flexible Retrieval.
Answer: A
Explanation:
Partitioning the time-series data by date prefix in the S3 bucket significantly improves query performance in Amazon Athena by reducing the amount of data that needs to be scanned during queries. This allows the ML engineers to efficiently analyze trends over specific time periods, such as the past 3 days. Applying S3 Lifecycle policies to archive partitions older than 30 days to S3 Glacier FlexibleRetrieval ensures cost- effective data retention and storage management while maintaining high performance for recent data retrieval.
NEW QUESTION # 227
An ML engineer wants to use, prepare, and load data from Amazon S3 for analytics. The ML engineer must run an extract, transform, and load (ETL) job to discover the schema of the data and to store the metadata.
Which solution will meet these requirements with the LEAST manual effort?
- A. Create an Amazon SageMaker Data Wrangler flow to run the ETL job. Use the job to discover the schema and to store the associated metadata in an S3 bucket.
- B. Launch an Amazon EC2 instance that includes the scikit-learn library to run the ETL job. Use the job to discover the schema and to store the associated metadata in Amazon Redshift.
- C. Use AWS Glue to run the ETL job. Use the job to discover the schema and to store the associated metadata in the AWS Glue Data Catalog.
- D. Create an ETL pipeline by using Amazon Athena integrated with AWS Step Functions. Use the pipeline to run the ETL job to discover the schema and to store the associated metadata in an S3 bucket.
Answer: C
Explanation:
Option A is correct because AWS Glue is the AWS-native managed ETL service built specifically to discover schema , run ETL jobs , and store metadata in the AWS Glue Data Catalog . AWS documentation states that Glue crawlers can automatically discover and catalog new or updated data sources , and that the Data Catalog automatically captures and manages schema metadata. This directly matches the requirement to run an ETL job on data in Amazon S3, discover the schema, and store the metadata with the least manual effort.
AWS Glue is also the lowest-effort answer because the service is managed and purpose-built for this workflow. The Glue Data Catalog serves as a persistent metadata repository, and AWS documents that crawlers infer schema information and integrate it into the catalog automatically. That means the ML engineer does not need to build custom schema inference logic or manually maintain metadata storage. This is exactly the kind of manual work the question is trying to avoid.
The other options are not as good. SageMaker Data Wrangler is primarily for visual data preparation and feature engineering, not for running a managed ETL-plus-catalog workflow with schema stored in a metadata catalog. Athena with Step Functions would require assembling more custom orchestration and still does not naturally replace the Glue Data Catalog workflow. Launching an EC2 instance introduces the highest operational overhead and does not align with the requirement for least manual effort. Therefore, the best verified AWS-docs answer is A , because AWS Glue combines ETL, schema discovery, and metadata cataloging in one managed service.
NEW QUESTION # 228
A company uses Amazon SageMaker for its ML process. A compliance audit discovers that an Amazon S3 bucket for training data uses server-side encryption with S3 managed keys (SSE- S3).
The company requires customer managed keys. An ML engineer changes the S3 bucket to use server-side encryption with AWS KMS keys (SSE-KMS). The ML engineer makes no other configuration changes.
After the change to the encryption settings, SageMaker training jobs start to fail with AccessDenied errors.
What should the ML engineer do to resolve this problem?
- A. Update the IAM policy that is attached to the user that created the training jobs. Include the kms:CreateGrant permission.
- B. Update the S3 bucket policy that is attached to the S3 bucket. Set the value of the aws:SecureTransport condition key to True.
- C. Update the IAM policy that is attached to the execution role for the training jobs. Include the kms:Encrypt and kms:Decrypt permissions.
- D. Update the IAM policy that is attached to the execution role for the training jobs. Include the s3:ListBucket and s3:GetObject permissions.
Answer: C
NEW QUESTION # 229
An ML engineer is using Amazon SageMaker Canvas to build a custom ML model from an imported dataset.
The model must make continuous numeric predictions based on 10 years of data.
Which metric should the ML engineer use to evaluate the model's performance?
- A. InferenceLatency
- B. Root Mean Square Error (RMSE)
- C. Area Under the ROC Curve (AUC)
- D. Accuracy
Answer: B
Explanation:
This is a regression problem, where the target variable is continuous and numeric. AWS documentation clearly states that classification metrics such as accuracy and AUC are not appropriate for regression models.
Root Mean Square Error (RMSE) measures the square root of the average squared differences between predicted and actual values. RMSE penalizes larger errors more heavily, making it especially useful when large prediction errors are costly or undesirable.
SageMaker Canvas automatically selects regression metrics such as RMSE and MAE when building regression models. RMSE is widely used for time-based and numeric prediction problems, especially when evaluating long historical datasets.
Inference latency measures system performance, not model accuracy.
Therefore, Option D is the correct and AWS-verified answer.
NEW QUESTION # 230
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.
Answer:
Explanation:
Explanation:
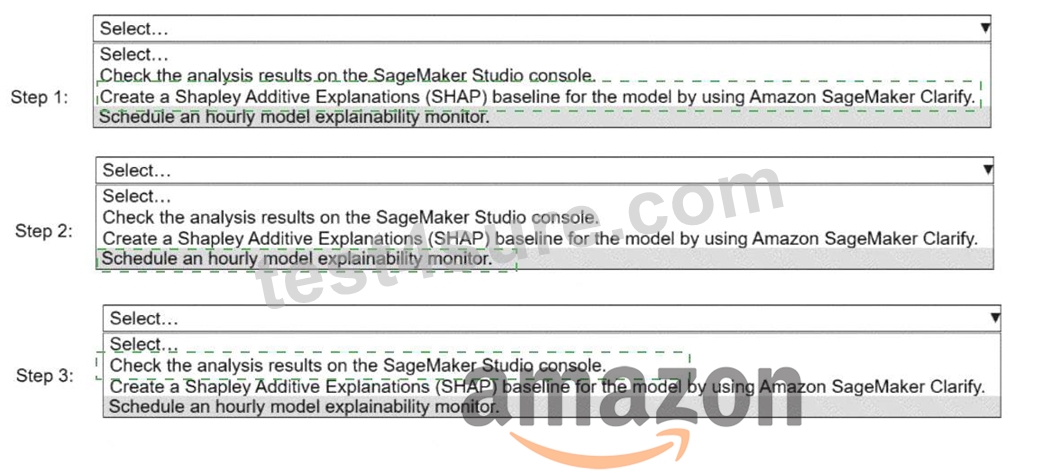
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
NEW QUESTION # 231
......
The Test4Sure team is updating the Amazon MLA-C01 study material according to the changes in the syllabus on daily basis. The users will receive MLA-C01 updates for 365 days so they can prepare according to the updated content. The 24/7 support system has been made for customers to solve their problems and serve them in the best possible ways in order to pass the AWS Certified Machine Learning Engineer - Associate (MLA-C01) certification exam on the first try!
MLA-C01 Unlimited Exam Practice: https://www.test4sure.com/MLA-C01-pass4sure-vce.html
- Newest MLA-C01 PDF Question - Easy and Guaranteed MLA-C01 Exam Success 💕 Search for ⏩ MLA-C01 ⏪ and easily obtain a free download on ▶ www.troytecdumps.com ◀ 🛩MLA-C01 Exam Bible
- Trustable MLA-C01 PDF Question - 100% Pass MLA-C01 Exam 💌 Go to website “ www.pdfvce.com ” open and search for 【 MLA-C01 】 to download for free 🕗Valid MLA-C01 Study Plan
- Pass Guaranteed Amazon - High Pass-Rate MLA-C01 - AWS Certified Machine Learning Engineer - Associate PDF Question 😢 Easily obtain ▷ MLA-C01 ◁ for free download through 【 www.testkingpass.com 】 🛅Latest MLA-C01 Exam Simulator
- Authentic Amazon MLA-C01 Dumps PDF - The Best Way To Pass Exam 🌠 Search for ☀ MLA-C01 ️☀️ and download it for free on ➽ www.pdfvce.com 🢪 website 🧣Upgrade MLA-C01 Dumps
- AWS Certified Machine Learning Engineer - Associate valid study torrent - MLA-C01 reliable study dumps - AWS Certified Machine Learning Engineer - Associate test practical information 🦧 Enter ➤ www.examcollectionpass.com ⮘ and search for { MLA-C01 } to download for free 🥄MLA-C01 Reliable Test Cram
- Trustable MLA-C01 PDF Question - 100% Pass MLA-C01 Exam 🚟 ( www.pdfvce.com ) is best website to obtain ▛ MLA-C01 ▟ for free download ❇Valid MLA-C01 Study Plan
- Authentic Amazon MLA-C01 Dumps PDF - The Best Way To Pass Exam 🎉 Search for 「 MLA-C01 」 and easily obtain a free download on ➤ www.dumpsmaterials.com ⮘ 🏟MLA-C01 Test Labs
- MLA-C01 Exam Bible ⭐ Reliable MLA-C01 Real Test 🚤 MLA-C01 Reliable Test Cram 🤶 Search for 【 MLA-C01 】 and download exam materials for free through ➥ www.pdfvce.com 🡄 🎻MLA-C01 Test Labs
- MLA-C01 Reliable Exam Testking 🏌 MLA-C01 Interactive Questions 🕯 MLA-C01 Exam Torrent ⚜ Search for ▷ MLA-C01 ◁ and download it for free immediately on ⏩ www.pdfdumps.com ⏪ 🧜Latest MLA-C01 Exam Simulator
- MLA-C01 Reliable Exam Testking 🥔 Latest MLA-C01 Exam Simulator 🛵 MLA-C01 Latest Exam Fee 🥂 Easily obtain [ MLA-C01 ] for free download through “ www.pdfvce.com ” 🔖Test MLA-C01 Engine
- Real MLA-C01 Exam Answers 🥽 Latest MLA-C01 Exam Simulator 🔚 Top MLA-C01 Questions 🏪 Search on ➽ www.testkingpass.com 🢪 for ➠ MLA-C01 🠰 to obtain exam materials for free download 📒MLA-C01 Exam Bible
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.scener.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by Test4Sure: https://drive.google.com/open?id=10PPgbQjLrz_HPOhCoMejHXop_7ODIpNC