P.S.JapancertがGoogle Driveで共有している無料の2026 Microsoft DP-100ダンプ:https://drive.google.com/open?id=1xw6fxmAFpc_GUsHHMwbmWBSAn1L7b6fJ
現在のネットワークの全盛期で、MicrosoftのDP-100の認証試験を準備するのにいろいろな方法があります。Japancertが提供した最も依頼できるトレーニングの問題と解答はあなたが気楽にMicrosoftのDP-100の認証試験を受かることに助けを差し上げます。JapancertにMicrosoftのDP-100の試験に関する問題はいくつかの種類がありますから、すべてのIT認証試験の要求を満たすことができます。
| Section | Objectives |
|---|---|
| Topic 1: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Topic 2: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 3: Design and prepare a machine learning solution | - Manage compute and data assets - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace |
| Topic 4: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 5: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
DP-100スタディガイドは無料のトライアルサービスを提供するため、スタディの内容、トピック、購入前にソフトウェアを最大限に活用する方法についての情報を入手できます。どのようなDP-100テスト準備が適切であるかを選択し、不必要な無駄を避けるために適切な選択をするのにMicrosoft良い方法です。また、DP-100練習用トレントまたはトレイルプロセスの購入で問題が発生した場合は、すぐにご連絡いただければ、専門家がオンラインでお手伝いいたします。
質問 # 215
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
You must register datastores in workspace1 for Azure Blob and Azure Data Lake Gen2 storage to meet the following requirements:
* Data scientists accessing the datastore must have the same level of access.
* Access must be restricted to specified containers or folders.
You need to configure a security access method used to register the Azure Blob and Azure Data lake Gen? storage in workspace1. Which security access method should you configure? To answer, select the appropriate options in the answers area.
NOTE: Each correct selection is worth one point.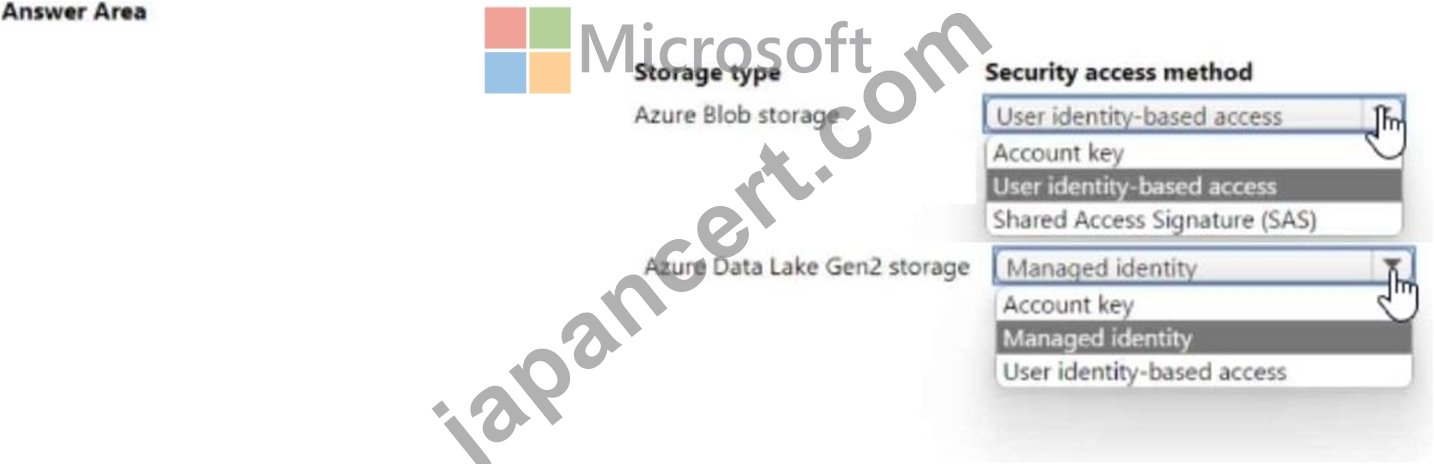
正解:
解説: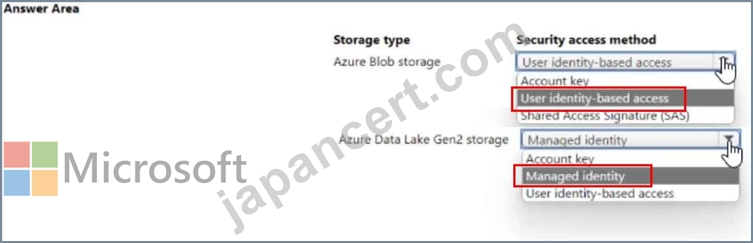
質問 # 216
You create an Azure Databricks workspace and a linked Azure Machine Learning workspace.
You have the following Python code segment in the Azure Machine Learning workspace:
import mlflow
import mlflow.azureml
import azureml.mlflow
import azureml.core
from azureml.core import Workspace
subscription_id = 'subscription_id'
resourse_group = 'resource_group_name'
workspace_name = 'workspace_name'
ws = Workspace.get(name=workspace_name,
subscription_id=subscription_id,
resource_group=resource_group)
experimentName = "/Users/{user_name}/{experiment_folder}/{experiment_name}" mlflow.set_experiment(experimentName) uri = ws.get_mlflow_tracking_uri() mlflow.set_tracking_uri(uri) Instructions: For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.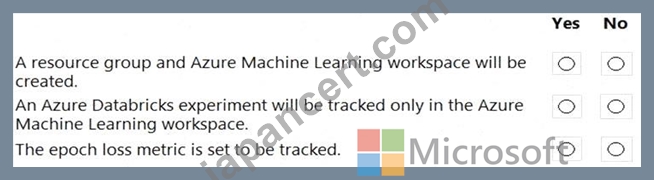
正解:
解説: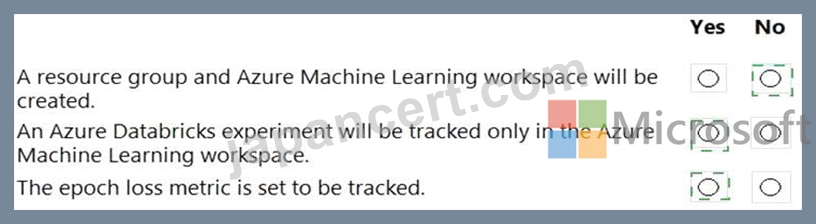
Explanation: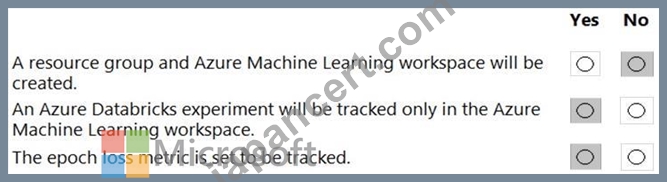
Box 1: No
The Workspace.get method loads an existing workspace without using configuration files.
ws = Workspace.get(name="myworkspace",
subscription_id='<azure-subscription-id>',
resource_group='myresourcegroup')
Box 2: Yes
MLflow Tracking with Azure Machine Learning lets you store the logged metrics and artifacts from your local runs into your Azure Machine Learning workspace.
The get_mlflow_tracking_uri() method assigns a unique tracking URI address to the workspace, ws, and set_tracking_uri() points the MLflow tracking URI to that address.
Box 3: Yes
Note: In Deep Learning, epoch means the total dataset is passed forward and backward in a neural network once.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-core/azureml.core.workspace.workspace
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-use-mlflow
質問 # 217
You publish a batch inferencing pipeline that will be used by a business application.
The application developers need to know which information should be submitted to and returned by the REST interface for the published pipeline.
You need to identify the information required in the REST request and returned as a response from the published pipeline.
Which values should you use in the REST request and to expect in the response? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.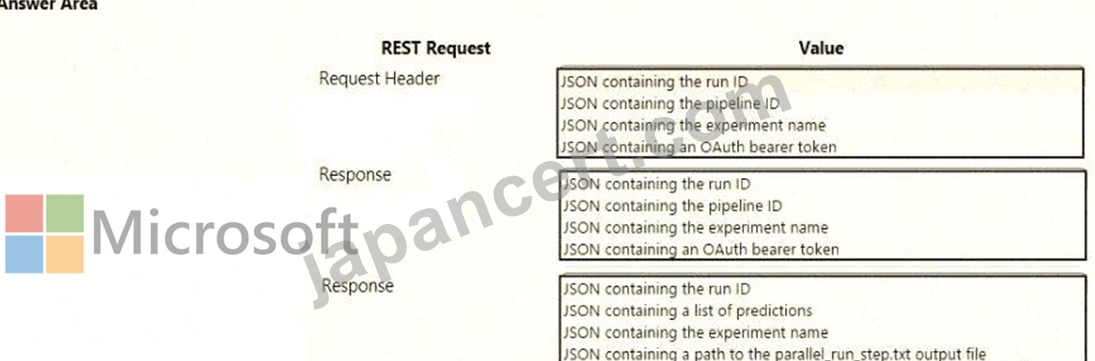
正解:
解説: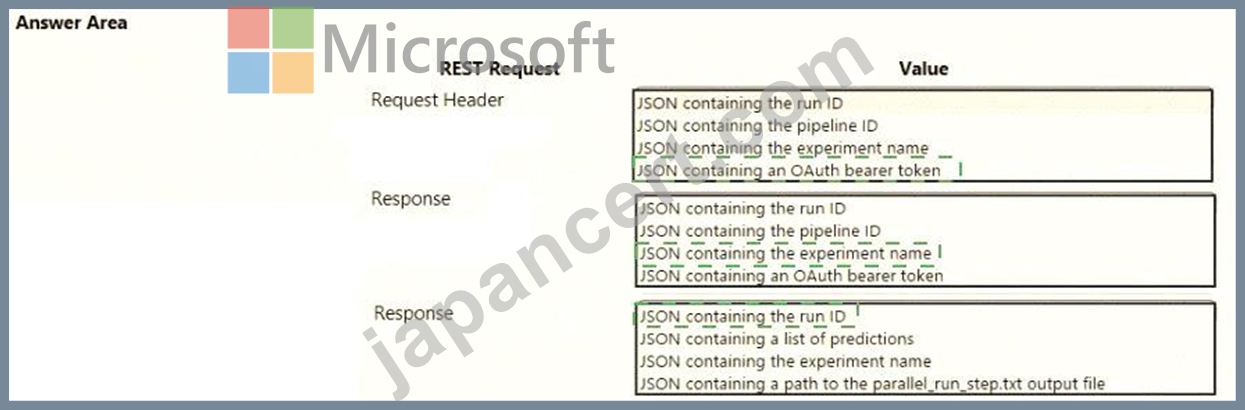
Explanation: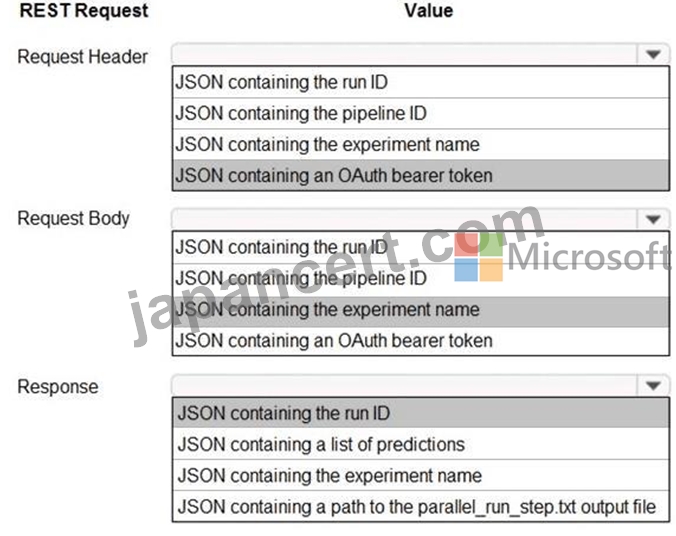
Box 1: JSON containing an OAuth bearer token
Specify your authentication header in the request.
To run the pipeline from the REST endpoint, you need an OAuth2 Bearer-type authentication header.
Box 2: JSON containing the experiment name
Add a JSON payload object that has the experiment name.
Example:
rest_endpoint = published_pipeline.endpoint
response = requests.post(rest_endpoint,
headers=auth_header,
json={"ExperimentName": "batch_scoring",
"ParameterAssignments": {"process_count_per_node": 6}})
run_id = response.json()["Id"]
Box 3: JSON containing the run ID
Make the request to trigger the run. Include code to access the Id key from the response dictionary to get the value of the run ID.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/tutorial-pipeline-batch-scoring-classification
質問 # 218
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.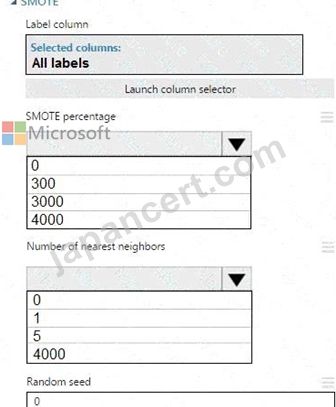
正解:
解説: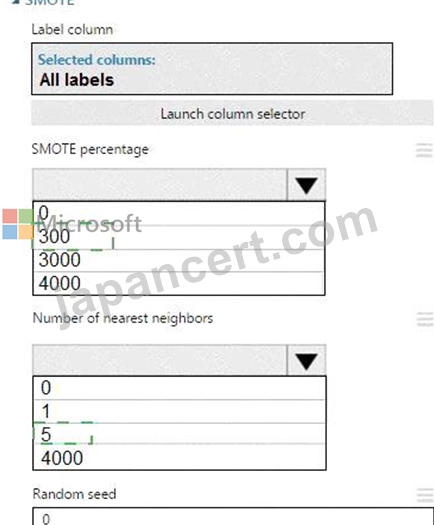
Explanation: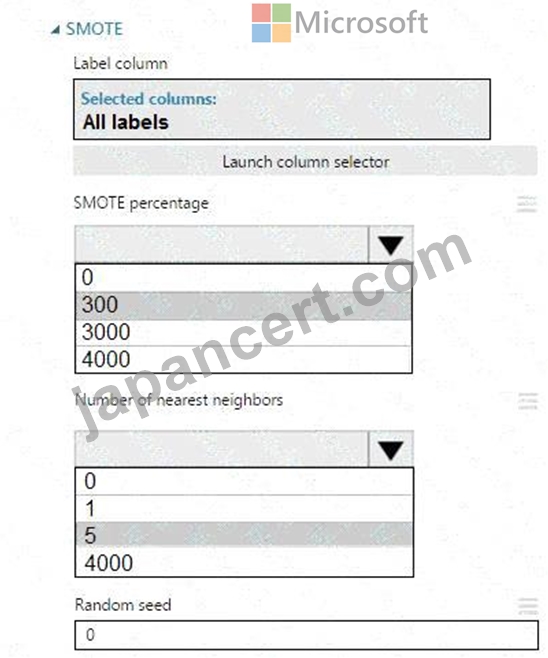
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
質問 # 219
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.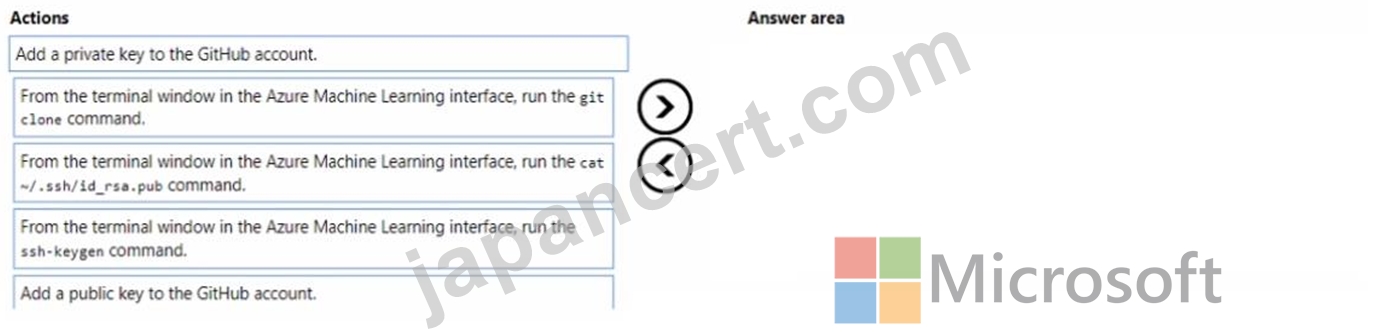
正解:
解説: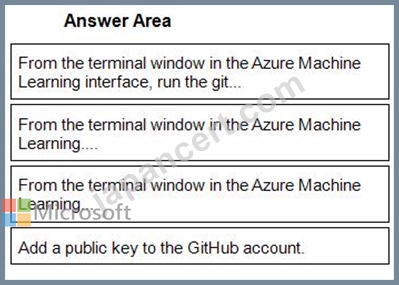
1 - From the terminal window in the Azure Machine Learning interface, run the git...
2 - From the terminal window in the Azure Machine Learning....
3 - From the terminal window in the Azure Machine Learning...
4 - Add a public key to the GitHub account.
質問 # 220
......
どうしてJapancertのMicrosoftのDP-100試験トレーニング資料はほかのトレーニング資料よりはるかに人気があるのでしょうか。それはいくつかの理由があります。第一、Japancertは受験生の要求をよく知っています。しかも、他のどのサイトよりも良いサービスを提供します。第二、専心すること。我々が決まったことを完璧に作るためにすべての不要な機会を諦めなければなりません。第三、我々は確かに最高の製品を持っていますが、粗悪品の方式で表示されたら、もちろん粗悪品と見られますから、我々は自分の製品を創造的かつプロの方法で見せます。JapancertのMicrosoftのDP-100試験トレーニング資料はこんなに成功するトレーニングですから、Japancertを選ばない理由はないです。
DP-100模擬対策問題: https://www.japancert.com/DP-100.html
P.S. JapancertがGoogle Driveで共有している無料かつ新しいDP-100ダンプ:https://drive.google.com/open?id=1xw6fxmAFpc_GUsHHMwbmWBSAn1L7b6fJ