P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by ExamBoosts: https://drive.google.com/open?id=1ovU3ySTPRWRvm7CvKff_toHwv2OfFV9h
Even if you are laid off by your company, there is no point in thinking that you couldn't make it and that it's the end of the road. No, it is not and you have a world full of opportunities till you are breathing. You can easily pass the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification exam. This Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam credential will help you get your dream job and show your expertise to the world around you. So, don't feel it with a heavy heart, but stand again, hold to your confidence, and think about how you can prepare successfully for the DP-600 test.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Most DP-600 Reliable Questions <<
The web-based DP-600 practice exam is similar to the desktop-based software. You can take the web-based DP-600 practice exam on any browser without needing to install separate software. In addition, all operating systems also support this web-based Microsoft DP-600 Practice Exam. Both Implementing Analytics Solutions Using Microsoft Fabric practice exams track your performance and help to overcome mistakes. Furthermore, you can customize your Implementing Analytics Solutions Using Microsoft Fabric practice exams according to your needs.
NEW QUESTION # 27
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.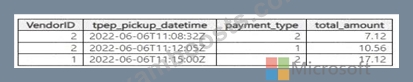
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
NOTE: Each correct selection is worth one point.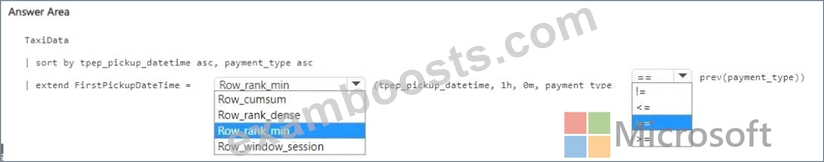
Answer:
Explanation: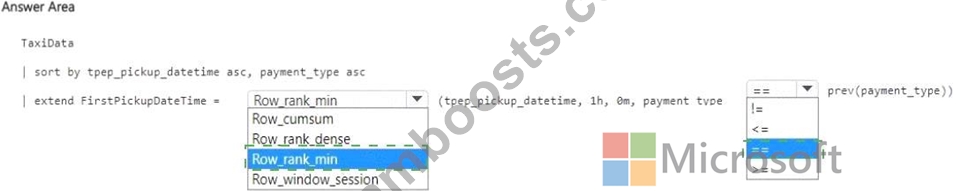
Explanation: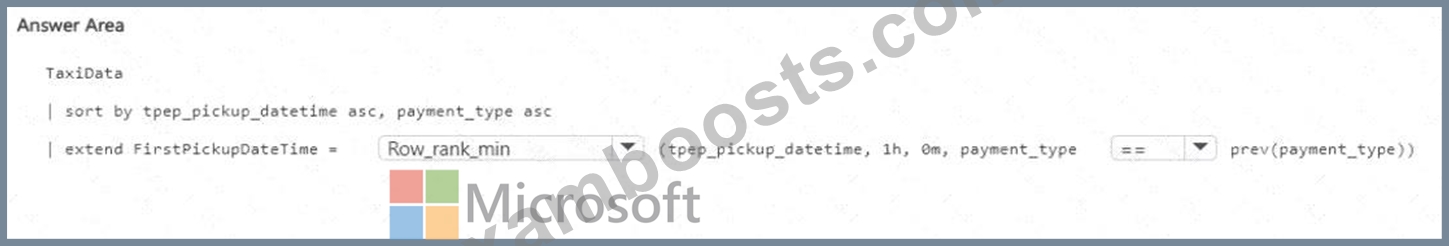
Comprehensive Detailed Explanation
We have a KQL table (TaxiData) with columns:
VendorID
tpep_pickup_datetime (timestamp)
payment_type
total_amount
The requirement:
Create a new column FirstPickupDateTime
It should contain the first pickup timestamp per hour
Partitioning should be done by payment_type
Step 1: Which windowing function?
row_cumsum # running cumulative sum (not needed here).
row_rank_dense # assigns ranks without gaps, but does not guarantee minimum value only.
row_rank_min # gives the first/minimum value in each window partition. # Correct.
row_window_session # sessionization of events, not required.
So, the correct function is row_rank_min .
Step 2: Which comparison operator?
We need to select the row where the rank = 1 (the first per partition).
So the correct operator is == (equals).
Step 3: Partitioning
The KQL query should partition by:
bin(tpep_pickup_datetime, 1h) # buckets data into 1-hour windows
payment_type # partitions further by payment type
Completed KQL Query
TaxiData
| sort by tpep_pickup_datetime asc, payment_type asc
| extend FirstPickupDateTime = row_rank_min(tpep_pickup_datetime, 1h, 0m, payment_type)
| where FirstPickupDateTime == 1
This assigns a rank within each 1-hour, per-payment-type window, then keeps the first pickup timestamp .
Why This Works
row_rank_min # ensures we capture the first occurrence in each hour.
== # filters only the first row per partition.
bin(..., 1h) ensures grouping is by hour.
References
Kusto row_rank_min() function
KQL window functions
NEW QUESTION # 28
You have a Fabric tenant that contains a semantic model named Model1. Model1 uses Import mode. Model1 contains a table named Orders. Orders has 100 million rows and the following fields.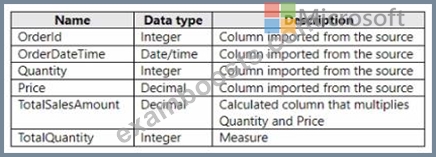
You need to reduce the memory used by Model! and the time it takes to refresh the model. Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
Answer: C,D
Explanation:
To reduce memory usage and refresh time, splitting the OrderDateTime into separate date and time columns (A) can help optimize the model because date/time data types can be more memory-intensive than separate date and time columns. Moreover, replacing TotalSalesAmount with a measure (D) instead of a calculated column ensures that the calculation is performed at query time, which can reduce the size of the model as the value is not stored but calculated on the fly. Reference = The best practices for optimizing Power BI models are detailed in the Power BI documentation, which recommends using measures for calculations that don't need to be stored and adjusting data types to improve performance.
NEW QUESTION # 29
You have a Fabric tenant that contains a Microsoft Power Bl report named Report 1.
Report1 is slow to render. You suspect that an inefficient DAX query is being executed.
You need to identify the slowest DAX query, and then review how long the query spends in the formula engine as compared to the storage engine.
Which five actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.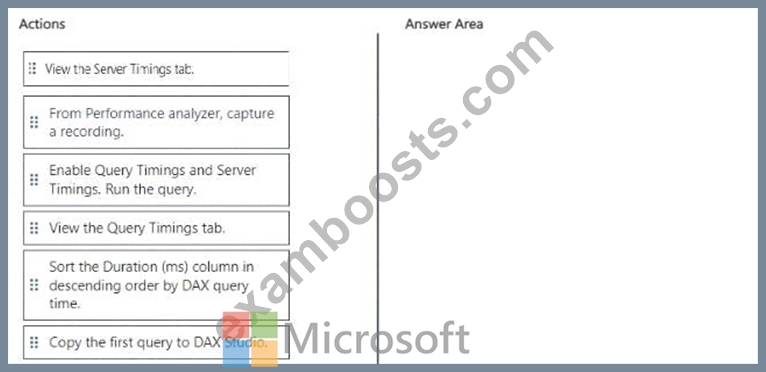
Answer:
Explanation: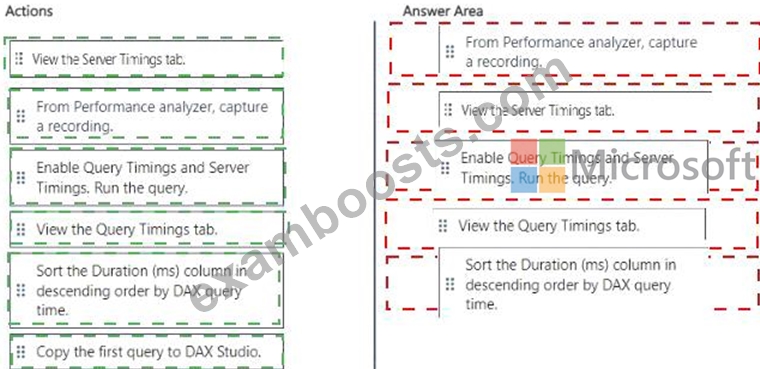
Explanation:
To identify the slowest DAX query and analyze the time it spends in the formula engine compared to the storage engine, you should perform the following actions in sequence:
* From Performance analyzer, capture a recording.
* View the Server Timings tab.
* Enable Query Timings and Server Timings. Run the query.
* View the Query Timings tab.
* Sort the Duration (ms) column in descending order by DAX query time.
NEW QUESTION # 30
You have a Microsoft Power B1 report and a semantic model that uses Direct Lake mode. From Power Si Desktop, you open Performance analyzer as shown in the following exhibit.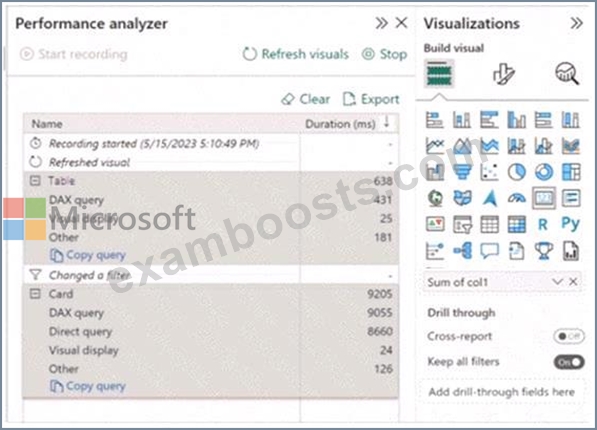
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.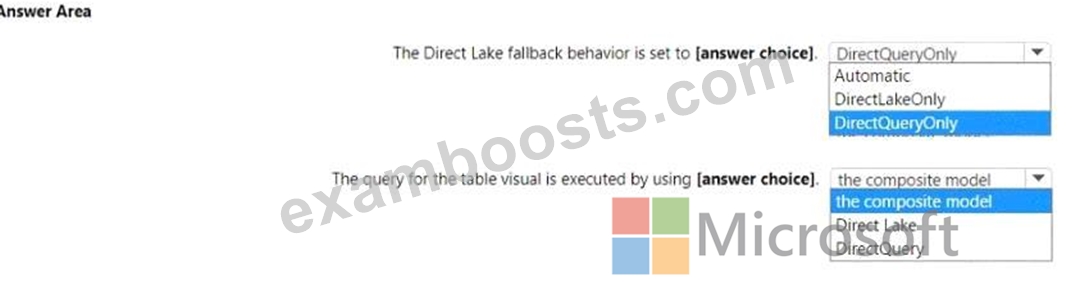
Answer:
Explanation: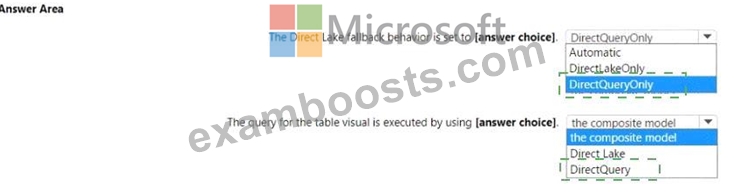
Explanation:
* The Direct Lake fallback behavior is set to: DirectQueryOnly
* The query for the table visual is executed by using: DirectQuery
In the context of Microsoft Power BI, when using DirectQuery in Direct Lake mode, there is no caching of data and all queries are sent directly to the underlying data source. The Performance Analyzer tool shows the time taken for different operations, and from the options provided, it indicates that DirectQuery mode is being used for the visuals, which is consistent with the Direct Lake setting. DirectQueryOnly as the fallback behavior ensures that only DirectQuery will be used without reverting to import mode.
NEW QUESTION # 31
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.
Which code should you run to populate the results DataFrame?




Answer: B
NEW QUESTION # 32
......
With the rapid development of economy, the demand of society for us is getting higher and higher. If you can have an international certification, then you will be more competitive in society. Our DP-600 exam materials have helped many people improve their competitive in their company or when they are looking for better jobs. Because our DP-600 Practice Questions are all the most advanced information and knowledage to equip you up as the most skilled person. Besides, you can get the certification as well.
Valid Test DP-600 Fee: https://www.examboosts.com/Microsoft/DP-600-practice-exam-dumps.html
P.S. Free & New DP-600 dumps are available on Google Drive shared by ExamBoosts: https://drive.google.com/open?id=1ovU3ySTPRWRvm7CvKff_toHwv2OfFV9h