DOWNLOAD the newest TestInsides Mule-Arch-201 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1QI7mPtBrAKYZHOleDRLp074oyB853npg
No doubt the Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) certification is one of the most challenging certification exams in the market. This Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) certification exam gives always a tough time to Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) exam candidates. The TestInsides understands this hurdle and offers recommended and real Salesforce Mule-Arch-201 exam practice questions in three different formats.
| Section | Weight | Objectives |
|---|---|---|
| Meeting API Quality Goals | 8% | - Unit & Integration Testing - Resilience & Reliability Patterns - API Performance Optimization |
| Understanding the MuleSoft Platform & Application Networks | 11% | - MuleSoft Anypoint Platform Core Concepts - C4E (Center for Enablement) Definition - Application Network Fundamentals |
| Architecting and Deploying API Implementations | 11% | - Disaster Recovery (DR) Strategies - Mule Runtime Architecture - High Availability (HA) Design |
| Deploying API Implementations to CloudHub | 11% | - CloudHub Architecture - Deployment Strategies - CloudHub 2.0 & Runtime Fabric |
| Monitoring and Analyzing Application Networks | 8% | - Anypoint Monitoring Tools - Alerting & Auditing - Analytics & Business Insights |
| Designing and Sharing APIs | 11% | - Anypoint Exchange for Sharing Assets - API Design Best Practices - API-Led Connectivity Approach |
| Applying Integration Patterns | 11% | - Batch Processing - Integration Scenarios & Patterns - Event-Driven Architecture (EDA) |
| Managing APIs | 12% | - API Lifecycle Management - API Versioning - API Security (Policies, SLAs) |
| Establishing Organizational and Platform Foundations | 17% | - Platform Foundation Setup - IT Delivery & C4E Operating Model - Governance and Compliance Framework |
>> Mule-Arch-201 Valid Exam Duration <<
If you are looking for the latest updated questions and correct answers for Salesforce Mule-Arch-201 exam, yes, you are in the right place. Our site is working on providing most helpful the real test questions answer in IT certification exams many years especially for Mule-Arch-201. Good site provide 100% real test exam materials to help you clear exam surely. If you find some mistakes in other sites, you will know how the important the site have certain power. Choosing good Mule-Arch-201 exam materials, we will be your only option.
NEW QUESTION # 46
A System API is designed to retrieve data from a backend system that has scalability challenges. What API policy can best safeguard the backend system?
Answer: B
Explanation:
Correct Answe r: SLA-based rate limiting
*****************************************
>> Client Id enforement policy is a "Compliance" related NFR and does not help in maintaining the "Quality of Service (QoS)". It CANNOT and NOT meant for protecting the backend systems from scalability challenges.
>> IP Whitelisting and OAuth 2.0 token enforcement are "Security" related NFRs and again does not help in maintaining the "Quality of Service (QoS)". They CANNOT and are NOT meant for protecting the backend systems from scalability challenges.
Rate Limiting, Rate Limiting-SLA, Throttling, Spike Control are the policies that are "Quality of Service (QOS)" related NFRs and are meant to help in protecting the backend systems from getting overloaded.
https://dzone.com/articles/how-to-secure-apis
NEW QUESTION # 47
An eCommerce company is adding a new Product Details feature to their website, A customer will launch the product catalog page, a new Product Details link will appear by product where they can click to retrieve the product detail description. Product detail data is updated with product update releases, once or twice a year, Presently the database response time has been very slow due to high volume.
What action retrieves the product details with the lowest response time, fault tolerant, and consistent data?
Answer: B
Explanation:
Scenario Analysis:
The eCommerce company's Product Details feature requires low response time and consistent data for a feature where data rarely changes (only once or twice a year).
The database response time is slow due to high volume, so querying the database directly on each request would lead to poor performance and higher response times.
Optimal Solution Requirements:
Low Response Time: Data retrieval should be fast and not depend on database performance.
Fault Tolerance and Data Consistency: Cached or stored data should be consistent and resilient in case of database unavailability, as the product details data changes infrequently.
Evaluating the Options:
Option A: Using a Cache scope would temporarily store the product details in memory, which could improve performance but might not be suitable for infrequent updates (only twice a year), as cache expiration policies typically require shorter durations.
Option B: Storing product details in Anypoint MQ and then retrieving it through a subscriber is not suitable for this use case. Anypoint MQ is better for messaging rather than as a data storage mechanism.
Option C (Correct Answer): Using an object store to store and retrieve product details is ideal. Object stores in MuleSoft are designed for persistent storage of key-value pairs, which allows storing data retrieved from the database initially. This provides quick, consistent access without querying the database on every request, aligning with requirements for low response time, fault tolerance, and data consistency.
Option D: Selecting data directly from the database for each request would not meet the performance requirement due to known slow response times from the database.
Conclusion:
Option C is the best answer, as using an object store allows caching the infrequently updated product details. This approach reduces the dependency on the database, significantly improving response time and ensuring consistent data.
Refer to MuleSoft documentation on Object Store v2 and best practices for data caching to implement this solution effectively.
NEW QUESTION # 48
Refer to the exhibit.
Three business processes need to be implemented, and the implementations need to communicate with several different SaaS applications.
These processes are owned by separate (siloed) LOBs and are mainly independent of each other, but do share a few business entities. Each LOB has one development team and their own budget In this organizational context, what is the most effective approach to choose the API data models for the APIs that will implement these business processes with minimal redundancy of the data models?
A) Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities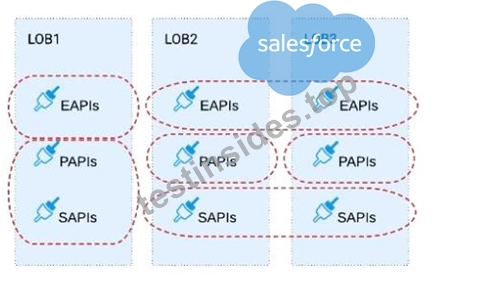
B) Build distinct data models for each API to follow established micro-services and Agile API-centric practices C) Build all API data models using XML schema to drive consistency and reuse across the organization D) Build one centralized Canonical Data Model (Enterprise Data Model) that unifies all the data types from all three business processes, ensuring the data model is consistent and non-redundant
Answer: C
Explanation:
Correct Answe r: Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.
*****************************************
>> The options w.r.t building API data models using XML schema/ Agile API-centric practices are irrelevant to the scenario given in the question. So these two are INVALID.
>> Building EDM (Enterprise Data Model) is not feasible or right fit for this scenario as the teams and LOBs work in silo and they all have different initiatives, budget etc.. Building EDM needs intensive coordination among all the team which evidently seems not possible in this scenario.
So, the right fit for this scenario is to build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.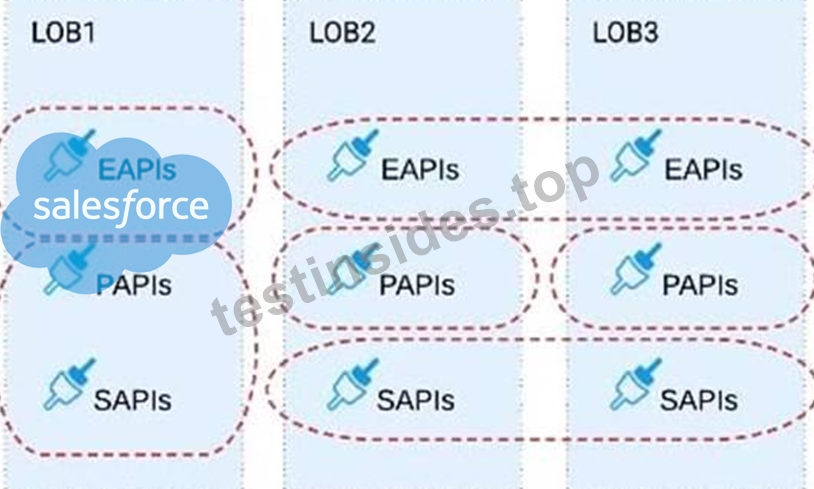
NEW QUESTION # 49
Which statement is true about Spike Control policy and Rate Limiting policy?
Answer: B
Explanation:
Understanding Spike Control and Rate Limiting Policies:
Spike Control Policy: Limits the number of requests processed by the API in a short time to handle sudden bursts of traffic. It does not queue requests but rejects any request that exceeds the allowed burst rate.
Rate Limiting Policy: Sets a limit on the number of requests that an API can handle within a given timeframe. Once the limit is reached, additional requests are rejected.
Evaluating the Options:
Option A: Incorrect. In both Spike Control and Rate Limiting policies, requests are rejected once the limit is reached. Spike Control does not queue requests; it only controls the burst rate by rejecting excessive requests.
Option B (Correct Answer): In a clustered environment, each node independently enforces the Rate Limiting and Spike Control policies, meaning that the limits apply to each node separately. This ensures that each node can control its own resource usage independently within the cluster.
Option C: This is partially correct, as Rate Limiting is often used to protect Experience APIs, but Spike Control could also be useful in limiting resource consumption under high burst conditions.
Option D: Incorrect. Although a contract is required to enforce client-specific policies, Rate Limiting and Spike Control do not require a contract to function for general traffic control.
Conclusion:
Option B is the correct answer because, in a clustered environment, Rate Limiting and Spike Control policies apply separately to each node, helping each instance to manage its own load.
For more information, refer to MuleSoft's documentation on applying Rate Limiting and Spike Control policies in a clustered environment.
NEW QUESTION # 50
An Order API must be designed that contains significant amounts of integration logic and involves the invocation of the Product API.
The power relationship between Order API and Product API is one of "Customer/Supplier", because the Product API is used heavily throughout the organization and is developed by a dedicated development team located in the office of the CTO.
What strategy should be used to deal with the API data model of the Product API within the Order API?
Answer: C
Explanation:
Correct Answe r: Convince the development team of the product API to adopt the API data model of the Order API such that integration logic of the Order API can work with one consistent internal data model
*****************************************
Key details to note from the given scenario:
>> Power relationship between Order API and Product API is customer/supplier So, as per below rules of "Power Relationships", the caller (in this case Order API) would request for features to the called (Product API team) and the Product API team would need to accomodate those requests.
NEW QUESTION # 51
......
We have a team of experts curating the real Mule-Arch-201 questions and answers for the end users. We are always working on updating the latest Mule-Arch-201 questions and providing the correct Mule-Arch-201 answers to all of our users. We will provide free updates for 1 year from the date of purchase. You can benefit from the updates Mule-Arch-201 Preparation material, and you will be able to pass the Mule-Arch-201 exam in the first attempt.
Mule-Arch-201 Vce Format: https://www.testinsides.top/Mule-Arch-201-dumps-review.html
BONUS!!! Download part of TestInsides Mule-Arch-201 dumps for free: https://drive.google.com/open?id=1QI7mPtBrAKYZHOleDRLp074oyB853npg