BONUS!!! Download part of Itcerttest DP-100 dumps for free: https://drive.google.com/open?id=18AG-q-CqOJFqMcayYFrjD9USdCJ7sefJ
In order to help all people to pass the DP-100 exam and get the related certification in a short time, we designed the three different versions of the DP-100 study materials. We can promise that the products can try to simulate the real examination for all people to learn and test at same time and it provide a good environment for learn shortcoming in study course. If you buy and use the DP-100 study materials from our company, you can complete the practice tests in a timed environment, receive grades and review test answers via video tutorials. You just need to download the software version of our DP-100 Study Materials after you buy our study materials. You will have the right to start to try to simulate the real examination. We believe that the DP-100 study materials from our company will not let you down.
| Section | Weight | Objectives |
|---|---|---|
| Explore data and train models | 35-40% | - Optimize model performance
|
| Design and prepare a machine learning solution | 20-25% | - Prepare development environments
|
| Deploy and retrain models | 10-15% | - Implement retraining pipelines
|
| Prepare a model for deployment | 20-25% | - Deploy machine learning models
|
So our high efficiency DP-100 torrent question can be your best study partner. Only 20 to 30 hours study can help you acquire proficiency in the exam. And during preparing for DP-100 exam you can demonstrate your skills flexibly with your learning experiences. The rigorous world force us to develop ourselves, thus we can't let the opportunities slip away. Being more suitable for our customers the DP-100 Torrent question complied by our company can help you improve your competitiveness in job seeking, and DP-100 exam training can help you update with times simultaneously.
NEW QUESTION # 490
Hotspot Question
You have a binary classifier that predicts positive cases of diabetes within two separate age groups.
The classifier exhibits a high degree of disparity between the age groups.
You need to modify the output of the classifier to maximize its degree of fairness across the age groups and meet the following requirements:
- Eliminate the need to retrain the model on which the classifier is
based.
- Minimize the disparity between true positive rates and false positive rates across age groups.
Which algorithm and parity constraint should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.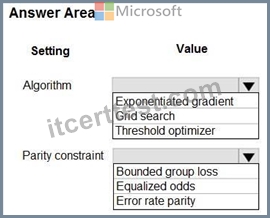
Answer:
Explanation: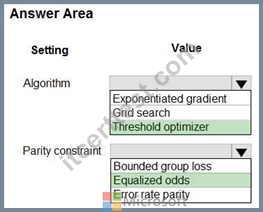
Explanation:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-fairness-ml?view=azureml-api-
2
NEW QUESTION # 491
You need to configure the Permutation Feature Importance module for the model training requirements.
What should you do? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.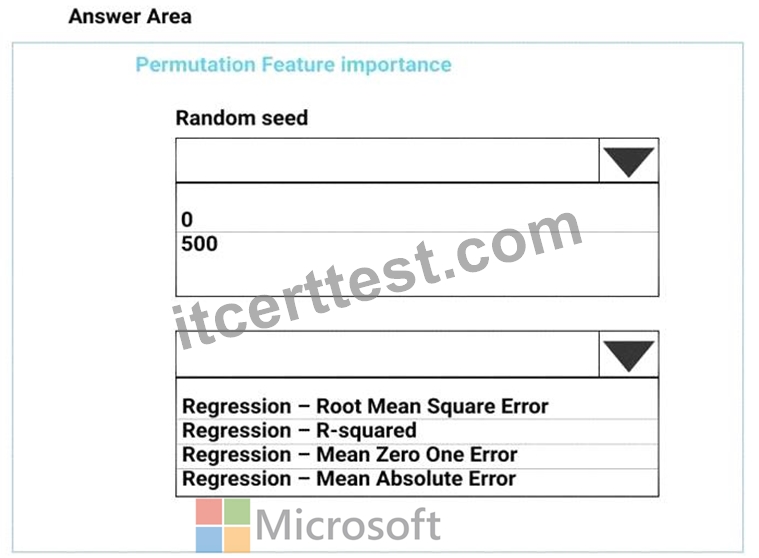
Answer:
Explanation: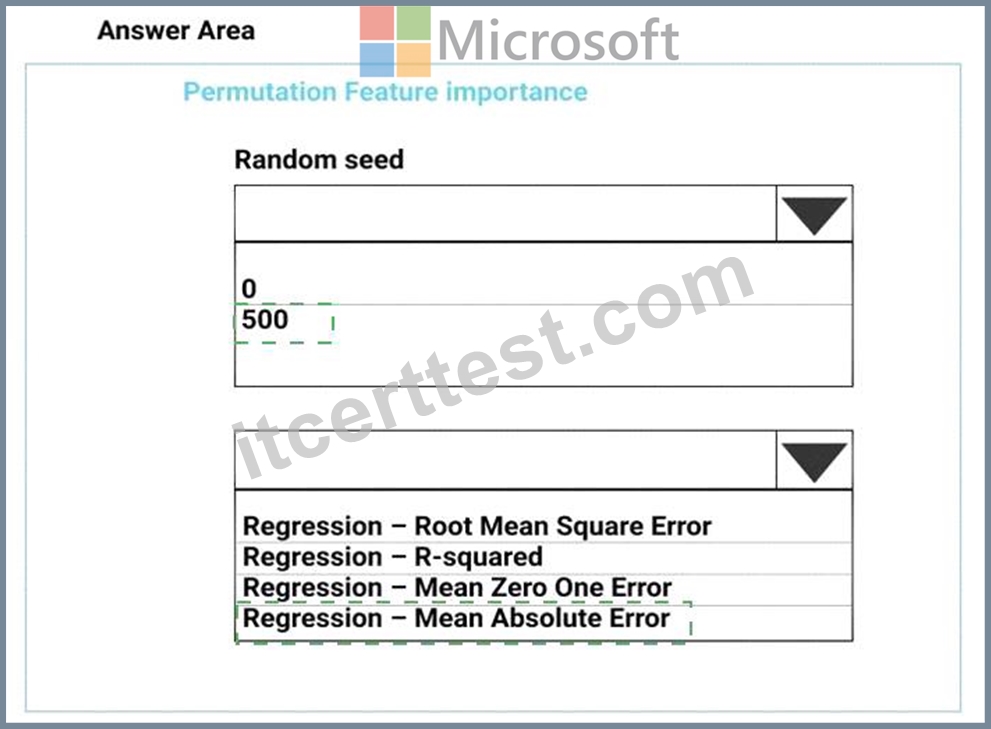
Explanation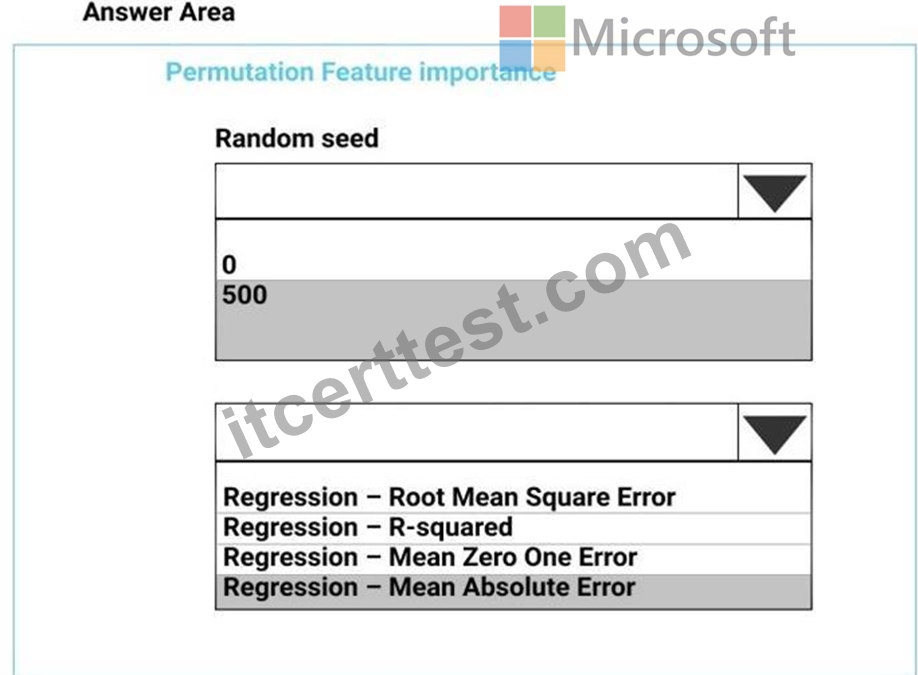
Box 1: 500
For Random seed, type a value to use as seed for randomization. If you specify 0 (the default), a number is generated based on the system clock.
A seed value is optional, but you should provide a value if you want reproducibility across runs of the same experiment.
Here we must replicate the findings.
Box 2: Mean Absolute Error
Scenario: Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
Regression. Choose one of the following: Precision, Recall, Mean Absolute Error , Root Mean Squared Error, Relative Absolute Error, Relative Squared Error, Coefficient of Determination References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importan
NEW QUESTION # 492
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You plan to use a Python script to run an Azure Machine Learning experiment. The script creates a reference to the experiment run context, loads data from a file, identifies the set of unique values for the label column, and completes the experiment run:
from azureml.core import Run
import pandas as pd
run = Run.get_context()
data = pd.read_csv('data.csv')
label_vals = data['label'].unique()
# Add code to record metrics here
run.complete()
The experiment must record the unique labels in the data as metrics for the run that can be reviewed later.
You must add code to the script to record the unique label values as run metrics at the point indicated by the comment.
Solution: Replace the comment with the following code:
run.upload_file('outputs/labels.csv', './data.csv')
Does the solution meet the goal?
Answer: B
Explanation:
label_vals has the unique labels (from the statement label_vals = data['label'].unique()), and it has to be logged.
Note:
Instead use the run_log function to log the contents in label_vals:
for label_val in label_vals:
run.log('Label Values', label_val)
8E6BA412E7DB6A14A62CC68E5EB6DAE3
Reference:
https://www.element61.be/en/resource/azure-machine-learning-services-complete-toolbox-ai
NEW QUESTION # 493
You need to define a modeling strategy for ad response.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.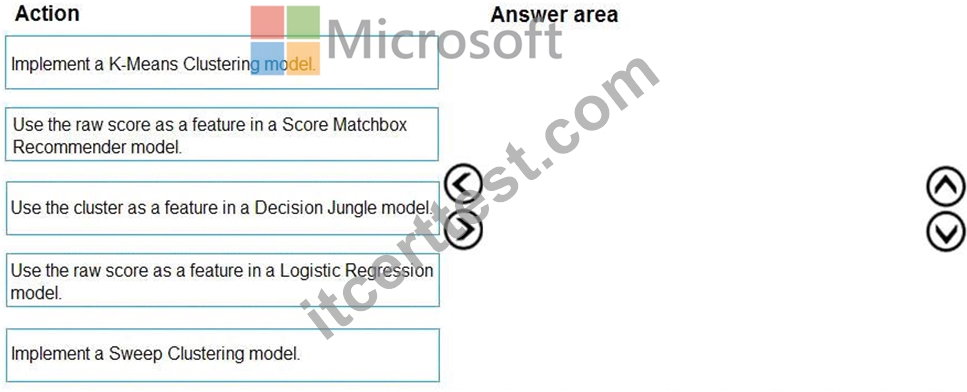
Answer:
Explanation: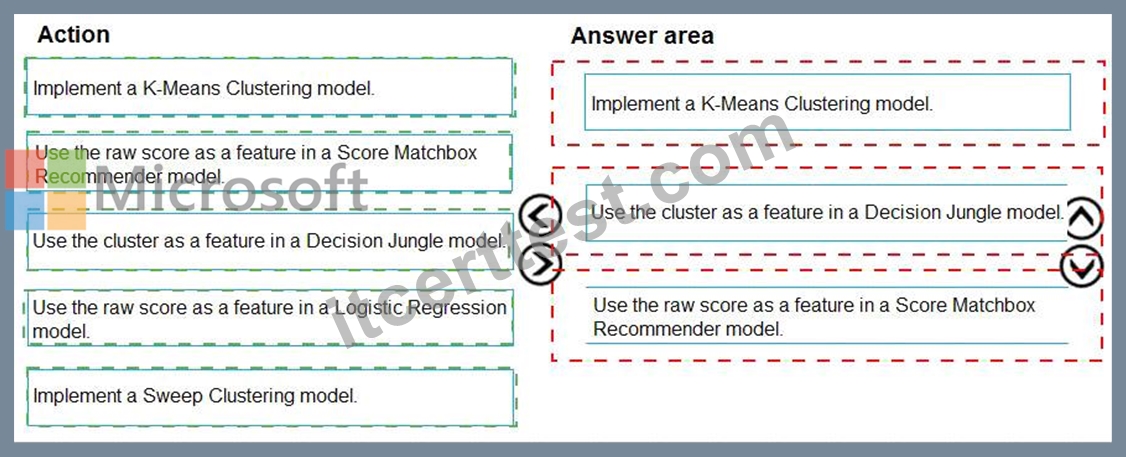
Explanation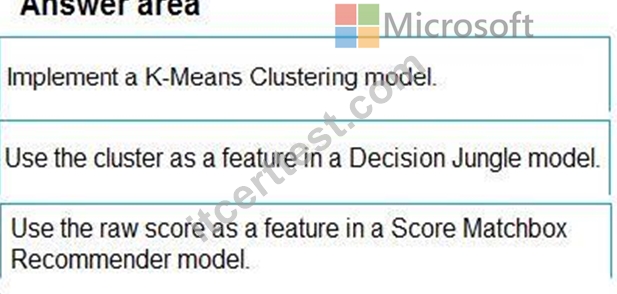
Step 1: Implement a K-Means Clustering model
Step 2: Use the cluster as a feature in a Decision jungle model.
Decision jungles are non-parametric models, which can represent non-linear decision boundaries.
Step 3: Use the raw score as a feature in a Score Matchbox Recommender model The goal of creating a recommendation system is to recommend one or more "items" to "users" of the system.
Examples of an item could be a movie, restaurant, book, or song. A user could be a person, group of persons, or other entity with item preferences.
Scenario:
Ad response rated declined.
Ad response models must be trained at the beginning of each event and applied during the sporting event.
Market segmentation models must optimize for similar ad response history.
Ad response models must support non-linear boundaries of features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/multiclass-decision-jungle
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/score-matchbox-recommende
NEW QUESTION # 494
You are a lead data scientist for a project that tracks the health and migration of birds. You create a multi-class image classification deep learning model that uses a set of labeled bird photographs collected by experts.
You have 100,000 photographs of birds. All photographs use the JPG format and are stored in an Azure blob container in an Azure subscription.
You need to access the bird photograph files in the Azure blob container from the Azure Machine Learning service workspace that will be used for deep learning model training. You must minimize data movement.
What should you do?
Answer: E
Explanation:
Explanation
We recommend creating a datastore for an Azure Blob container. When you create a workspace, an Azure blob container and an Azure file share are automatically registered to the workspace.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-access-data
NEW QUESTION # 495
......
Your success is guaranteed if you choose our DP-100 training guide to prapare for you coming exam! The questions and answers format of our DP-100 exam braindumps is rich with the most accurate information and knowledage which are collected by our professional experts who have been in this career for over ten years. what is more, our DP-100 Study Guide also provides you the latest simulating exam to enhance your exam skills. So with our DP-100 learning questions, your success is guaranteed!
New DP-100 Exam Camp: https://www.itcerttest.com/DP-100_braindumps.html
DOWNLOAD the newest Itcerttest DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=18AG-q-CqOJFqMcayYFrjD9USdCJ7sefJ