2026 Latest Test4Sure Databricks-Certified-Professional-Data-Engineer PDF Dumps and Databricks-Certified-Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU
Want to get a high-paying job? Hurry to get an international Databricks-Certified-Professional-Data-Engineer certificate! You must prove to your boss that you deserve his salary. You may think that it is not easy to obtain an international certificate. Don't worry! Our Databricks-Certified-Professional-Data-Engineer Guide materials can really help you. And our Databricks-Certified-Professional-Data-Engineer exam questions have helped so many customers to pass their exam and get according certifications. You can just look at the warm feedbacks to us on the website.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Real Exam Qty: | 59 |
| Exam Format: | Multiple Choice |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Available Languages: | Japanese, Korean, English, Portuguese (Brazil) |
| Passing Score: | 70% |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 120 minutes |
| Exam Price: | USD 200 |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Latest Databricks Databricks-Certified-Professional-Data-Engineer Exam Simulator <<
In recent years, the market has been plagued by the proliferation of learning products on qualifying examinations, so it is extremely difficult to find and select our Databricks-Certified-Professional-Data-Engineer study materials in many similar products. However, we believe that with the excellent quality and good reputation of our study materials, we will be able to let users select us in many products. Our study materials allow users to use the Databricks-Certified-Professional-Data-Engineer research material for free to help users better understand our products better. Even if you find that part of it is not for you, you can still choose other types of learning materials in our study materials.
Databricks Certified Professional Data Engineer Exam covers a wide range of topics related to data engineering using Databricks, including data ingestion, data transformation, data storage, and data orchestration. Databricks-Certified-Professional-Data-Engineer Exam also tests the candidate's proficiency in using Databricks tools and technologies such as Delta Lake, Apache Spark, and Databricks Runtime. Successful completion of the exam demonstrates that the candidate has the skills and knowledge required to design, build, and manage efficient and scalable data pipelines using Databricks. Databricks Certified Professional Data Engineer Exam certification also enhances the candidate's credibility and marketability in the job market, as it is recognized by leading organizations in the industry.
NEW QUESTION # 163
You are working on a marketing team request to identify customers with the same information between two tables CUSTOMERS_2021 and CUSTOMERS_2020 each table contains 25 columns with the same schema, You are looking to identify rows that match between two tables across all columns, which of the following can be used to perform in SQL
Answer: B
Explanation:
Explanation
Answer is,
1.SELECT * FROM CUSTOMERS_2021
2. INTERSECT
3.SELECT * FROM CUSTOMERS_2020
To compare all the rows between both the tables across all the columns using intersect will help us achieve that, an inner join is only going to check if the same column value exists across both the tables on a single column.
INTERSECT [ALL | DISTINCT]
*Returns the set of rows which are in both subqueries.
If ALL is specified a row that appears multiple times in the subquery1 as well as in subquery will be returned multiple times.
If DISTINCT is specified the result does not contain duplicate rows. This is the default.
NEW QUESTION # 164
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: C
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "WINDOW" section.
https://www.databricks.com/blog/2017/05/08/event-time-aggregation-watermarking-apache-sparks-structured-str
NEW QUESTION # 165
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.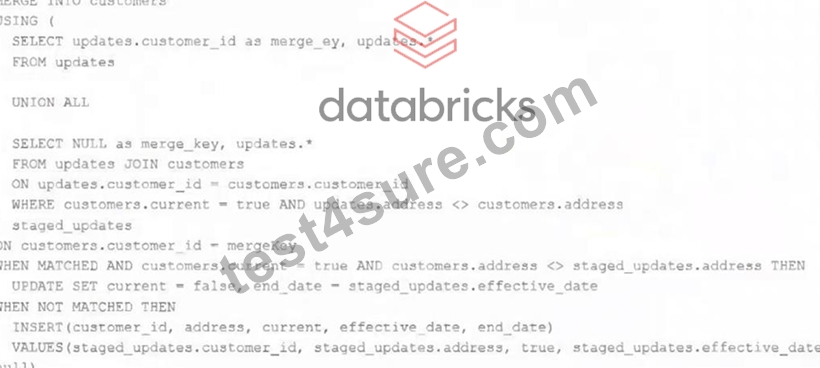
Which statement describes this implementation?
Answer: D
Explanation:
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 166
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
Answer: A
Explanation:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 167
The marketing team is launching a new campaign to monitor the performance of the new campaign for the first two weeks, they would like to set up a dashboard with a refresh schedule to run every 5 minutes, which of the below steps can be taken to reduce of the cost of this refresh over time?
Answer: B
Explanation:
Explanation
The answer is Setup the dashboard refresh schedule to end in two weeks
NEW QUESTION # 168
......
Databricks-Certified-Professional-Data-Engineer Exam Syllabus: https://www.test4sure.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-vce.html
BONUS!!! Download part of Test4Sure Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1xSx6PKDZDiWYTi9wwoNUKr-57IqpqatU