Kostenlose gültige Prüfung Databricks Databricks-Machine-Learning-Professional Sammlung - Examcollection

P.S. Kostenlose 2026 Databricks Databricks-Machine-Learning-Professional Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1h0iZ_iUxHWTRll9t6yWfZDkNfaXyYqlg
Sie wissen unbedingt die Wichtigkeit der IT-Zertifizierungsprüfugen, wenn Sie in IT-Industrie arbeiten. Es gibt verschiedene IT-Zertifizierungsprüfungen. Davon sind einige sehr beliebt, z.B Databricks-Machine-Learning-Professional. Wenn Sie keine Zertifizierung besitzen, sollen Sie sich an der Databricks Databricks-Machine-Learning-Professional Prüfung melden. Wir Pass4Test können Ihnen die Prüfungsunterlagen bieten und wir Pass4Test sind auch Ihre Garantie, Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung zu bestehen.
Databricks Databricks-Machine-Learning-Professional Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Model Deployment | 12% | - Deployment strategies
- Model rollout and version management
- Custom model serving
|
| Topic 2: Model Development | 44% | - Feature Store and automated feature pipelines
- Scalable ML pipelines with SparkML
- Advanced MLflow usage
- Distributed training and hyperparameter tuning
|
| Topic 3: ML Ops | 44% | - Automated retraining workflows
- Environment management with Databricks Asset Bundles
- Testing and validation strategies
- Model monitoring and drift detection with Lakehouse Monitoring
|
>> Databricks-Machine-Learning-Professional Prüfungsaufgaben <<
Kostenlos Databricks-Machine-Learning-Professional dumps torrent & Databricks Databricks-Machine-Learning-Professional Prüfung prep & Databricks-Machine-Learning-Professional examcollection braindumps
Pass4Test haben schon viele Prüfungsteilnehmer bei dem Bestehen der Databricks Databricks-Machine-Learning-Professional Prüfung geholfen. Unsere Schlüssel ist die Databricks Databricks-Machine-Learning-Professional Prüfungsunterlagen, die von unserer professionellen IT-Gruppe für mehrere Jahre geforscht werden. Die Antworten davon werden auch ausführlich analysiert. Die Prüfung werden immer aktualisiert. Deshalb aktualisieren wir die Prüfungsunterlagen der Databricks Databricks-Machine-Learning-Professional immer wieder. Wir tun unser Bestes, um den sicheren Erfolg zu garantieren.
Databricks Certified Machine Learning Professional Databricks-Machine-Learning-Professional Prüfungsfragen mit Lösungen (Q165-Q170):
165. Frage
A Machine Learning Engineer is building a fraud detection model that needs to use both pre- computed features from a feature table and real-time calculated features based on user location data sent with each inference request. The engineer has created a Python UDF called calculate_distance in Unity Catalog at main.fraud_detection.calculate_distance that computes the distance between a transaction location and the user's current location. The feature table main.fraud_detection.user_features contains historical user spending patterns with primary key user_id.
The engineer has written the following code to implement this scenario:

Which benefit of this implementation approach makes it suited to the real-time fraud detection use case?
- A. The FeatureLookup function avoids the need for joining the full table main.fraud_detection.user_features with training_set increasing efficiency.
- B. The model automatically performs feature lookup and computation during inference without additional serving code.
- C. The FeatureFunction caches computed distance values in the online store to improve inference latency for location pairs.
- D. The Unity Catalog registry automatically creates REST API endpoints for UDF functions used in feature computation.
Antwort: B
Begründung:
By defining both FeatureLookup and FeatureFunction objects in the training set and logging the model with the FeatureEngineeringClient, the feature logic is packaged with the model. During inference, Databricks automatically performs feature lookups from the feature table and computes the on-demand distance feature using request-time inputs, without requiring any additional custom serving or feature-joining code. This makes the approach well suited for real-time fraud detection.
166. Frage
A Machine Learning Engineer uses Lakehouse Monitoring to track their credit scoring model's performance. The existing profile metrics table contains three aggregate metrics:
- adefault_risk_score
- payment_history_score
- credit_utilization_score
They need to:
1. Create a composite risk rating that combines these three scores using weights of 0.5, 0.3, and 0.2 respectively.
2. Monitor drift of this composite score against an established baseline.
Which approach should be used to implement both requirements within Lakehouse Monitoring?
- A. Use a scheduled notebook to calculate the composite score and manually insert both the score and drift values into the profile metrics table.
- B. Create an aggregate metric for composite_risk_rating and configure a separate drift metric to monitor changes.
- C. Create a derived metric for the composite_risk_rating calculation and create a drift metric on this derived metric.
- D. Create two separate aggregate metrics: one for the composite score calculation and another for drift detection.
Antwort: C
Begründung:
Lakehouse Monitoring supports derived metrics that are computed from existing profile metrics using custom expressions. By defining a derived metric for the composite_risk_rating using the specified weights, the composite score becomes a first-class metric in the monitoring framework.
A drift metric can then be directly configured on this derived metric to compare current values against the baseline, fulfilling both the composite calculation and drift monitoring requirements in a native, governed way.
167. Frage
A Data Scientist is building a machine learning pipeline to classify raw text using a Logistic Regression model in Spark using Spark MLlib's Pipelines. This pipeline has three stages: the Tokenizer (to split the raw text in tokens), a HashingTF (to transform tokens into hashes) and the Logistic Regression itself (to perform the classification of texts). The Spark DataFrame with the training data is called trainingDF and the one with the test data is called testDF.
In order to do this, they use the following incomplete piece of code:
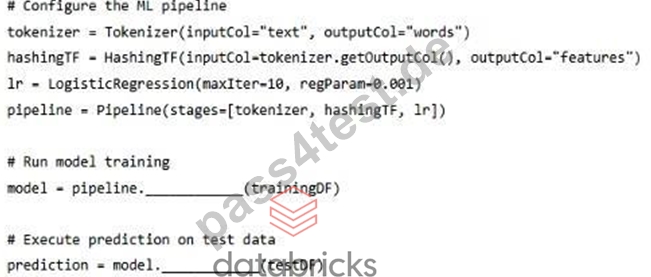
Which option correctly states:
(i) The complete command to run model training;
(ii) The complete command to execute the prediction on test data;
(iii) The object type of the model object returned by the model
training command.
Antwort: C
Begründung:
In Spark MLlib, a Pipeline is trained using the fit method, which applies all estimator stages to the training DataFrame and returns a PipelineModel. Predictions are generated by calling transform on the fitted PipelineModel, which applies the full pipeline (tokenization, feature hashing, and logistic regression) to the test DataFrame.
168. Frage
Which MLflow function registers a model to the registry?
- A. mlflow.register_model()
- B. mlflow.log_param()
- C. mlflow.deploy_model()
- D. mlflow.create_model()
Antwort: A
Begründung:
mlflow.register_model() promotes a model into the Model Registry.
169. Frage
A machine learning engineer has found drift in a production machine learning application. The engineer has determined that retraining and deploying a new model is necessary. Which statement must be true prior to deploying the new model?
- A. The new model must perform better than the original model on the most recently available data
- B. The new model must perform better than the original model on a random subset of the available data
- C. All of these statements must be true prior to deploying the new model
- D. The now model must perform better than the original model on all of the available data
Antwort: A
Begründung:
When drift is detected, it indicates that the data distribution has changed. Therefore, the new model must perform better than the original model on the most recently available data, as that data reflects current conditions. This ensures the new model is well-adapted to the current environment and will deliver more reliable predictions.
170. Frage
......
Wir sind uns darüber klar, dass die IT-Brache ein neuartiges Industriewesen ist. Sie ist auch eine der Ketten, die die Wirtschaft vorantreiben. Deswegen spielt sie eine gewichtige Rolle und man soll sie nicht ignorieren. Unsere Schulungsunterlagen zur Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung sind das Ergebnis der langjährigen ständigen Untersuchung und Erforschung von den erfahrenen IT-Experten aus Pass4Test. An ihrer Autorität besteht kein Zweifel. Falls Sie unsere Prüfungsmaterialien gekauft haben, werden wir Ihnen einjähriger Aktualisierung versprechen.
Databricks-Machine-Learning-Professional Testantworten: https://www.pass4test.de/Databricks-Machine-Learning-Professional.html
- Databricks-Machine-Learning-Professional Pass4sure Dumps - Databricks-Machine-Learning-Professional Sichere Praxis Dumps 😆 Suchen Sie auf ⏩ www.echtefrage.top ⏪ nach kostenlosem Download von 「 Databricks-Machine-Learning-Professional 」 🚔Databricks-Machine-Learning-Professional Online Tests
- Databricks-Machine-Learning-Professional Zertifizierungsantworten 🥠 Databricks-Machine-Learning-Professional Fragen Beantworten 🧷 Databricks-Machine-Learning-Professional Deutsche 🟠 Öffnen Sie die Webseite [ www.itzert.com ] und suchen Sie nach kostenloser Download von 《 Databricks-Machine-Learning-Professional 》 📑Databricks-Machine-Learning-Professional PDF Demo
- Hilfsreiche Prüfungsunterlagen verwirklicht Ihren Wunsch nach der Zertifikat der Databricks Certified Machine Learning Professional 🧕 Öffnen Sie die Webseite ☀ www.itzert.com ️☀️ und suchen Sie nach kostenloser Download von [ Databricks-Machine-Learning-Professional ] 👝Databricks-Machine-Learning-Professional Prüfung
- Echte und neueste Databricks-Machine-Learning-Professional Fragen und Antworten der Databricks Databricks-Machine-Learning-Professional Zertifizierungsprüfung ➕ Suchen Sie jetzt auf 《 www.itzert.com 》 nach ➤ Databricks-Machine-Learning-Professional ⮘ um den kostenlosen Download zu erhalten 🎄Databricks-Machine-Learning-Professional PDF Demo
- Databricks-Machine-Learning-Professional Prüfungsmaterialien 🦃 Databricks-Machine-Learning-Professional Online Test 🕕 Databricks-Machine-Learning-Professional PDF Demo ✡ Geben Sie 「 www.itzert.com 」 ein und suchen Sie nach kostenloser Download von ( Databricks-Machine-Learning-Professional ) 👖Databricks-Machine-Learning-Professional Fragen Und Antworten
- Hilfsreiche Prüfungsunterlagen verwirklicht Ihren Wunsch nach der Zertifikat der Databricks Certified Machine Learning Professional 🔕 【 www.itzert.com 】 ist die beste Webseite um den kostenlosen Download von 《 Databricks-Machine-Learning-Professional 》 zu erhalten 🤽Databricks-Machine-Learning-Professional Fragen Und Antworten
- Kostenlos Databricks-Machine-Learning-Professional dumps torrent - Databricks Databricks-Machine-Learning-Professional Prüfung prep - Databricks-Machine-Learning-Professional examcollection braindumps 👷 Öffnen Sie die Webseite ⇛ www.deutschpruefung.com ⇚ und suchen Sie nach kostenloser Download von “ Databricks-Machine-Learning-Professional ” 🥜Databricks-Machine-Learning-Professional Unterlage
- Die neuesten Databricks-Machine-Learning-Professional echte Prüfungsfragen, Databricks Databricks-Machine-Learning-Professional originale fragen 📇 Öffnen Sie die Website ( www.itzert.com ) Suchen Sie ➤ Databricks-Machine-Learning-Professional ⮘ Kostenloser Download 👙Databricks-Machine-Learning-Professional Online Tests
- bestehen Sie Databricks-Machine-Learning-Professional Ihre Prüfung mit unserem Prep Databricks-Machine-Learning-Professional Ausbildung Material - kostenloser Dowload Torrent 🟥 Suchen Sie jetzt auf ▷ www.zertpruefung.ch ◁ nach ( Databricks-Machine-Learning-Professional ) und laden Sie es kostenlos herunter 🗳Databricks-Machine-Learning-Professional PDF
- Databricks-Machine-Learning-Professional Zertifikatsfragen 🥠 Databricks-Machine-Learning-Professional Ausbildungsressourcen ⏺ Databricks-Machine-Learning-Professional Fragen Beantworten 👓 Sie müssen nur zu 【 www.itzert.com 】 gehen um nach kostenloser Download von “ Databricks-Machine-Learning-Professional ” zu suchen 🦛Databricks-Machine-Learning-Professional Testing Engine
- Hilfsreiche Prüfungsunterlagen verwirklicht Ihren Wunsch nach der Zertifikat der Databricks Certified Machine Learning Professional 🏅 Suchen Sie einfach auf ▛ de.fast2test.com ▟ nach kostenloser Download von ( Databricks-Machine-Learning-Professional ) 👯Databricks-Machine-Learning-Professional Deutsch Prüfung
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, mayagriffiths253.blogspot.com, schoolido.lu, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
Außerdem sind jetzt einige Teile dieser Pass4Test Databricks-Machine-Learning-Professional Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1h0iZ_iUxHWTRll9t6yWfZDkNfaXyYqlg