그 외, KoreaDumps AIF-C01 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1XjLwkhcoGUlcm0Ij801IH2NH6S3FMLrM
Amazon인증 AIF-C01덤프로Amazon시험을 패스,하지 못하셨다구요? 최선을 다했는데도 실패하였다는 말은 영원히 하지마세요. Amazon인증 AIF-C01시험을 패스하는 방법은 많고도 많습니다. KoreaDumps의Amazon인증 AIF-C01덤프로 시험에 다시 도전해보세요. KoreaDumps의Amazon인증 AIF-C01덤프는 착한 가격에 100%에 달하는 적중율과 패스율을 보장해드립니다. 시험에서 불합격성적표를 받으시면 덤프구매시 지불한 덤프비용을 환불처리해드립니다. KoreaDumps의Amazon인증 AIF-C01덤프로 시험패스를 꿈꿔보세요.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Applications of Foundation Models | 28% | - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan - Recognize tools for building and deploying generative AI solutions - Explain integration of foundation models into applications - Describe use cases for text, image, video, and code generation |
| Topic 2: Security, Compliance, and Governance for AI Solutions | 14% | - Security controls for AI data and models - Data protection and privacy in AI workflows - Compliance requirements and regulations - Governance frameworks for AI lifecycle |
| Topic 3: Guidelines for Responsible AI | 14% | - Identify risks and mitigation strategies for AI systems - Describe ethical and societal impacts of AI - Define responsible AI principles: fairness, transparency, privacy, safety - Explain bias detection and reduction |
| Topic 4: Fundamentals of Generative AI | 24% | - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) - Explain capabilities and use cases of generative AI - Differentiate between generative AI and traditional ML - Define generative AI and foundation models |
| Topic 5: Fundamentals of AI and ML | 20% | - Define artificial intelligence (AI), machine learning (ML), and deep learning - Describe common ML workflows and lifecycle - Identify types of ML: supervised, unsupervised, reinforcement learning - Recognize key concepts: data, models, training, inference, evaluation |
KoreaDumps 의 Amazon인증 AIF-C01덤프는 PDF버전과 소프트웨어버전 두가지 버전으로 되어있는데 소프트웨어버전은 시뮬레이션버전입니다. 소프트웨어버전의 문제를 푸는 과정은 시험현장을 연상케하여 시험환경에 먼저 적응하여 실제시험에서 높은 점수를 받도록 도와드릴수 있습니다.
질문 # 98
A company deployed a model to production. After 4 months, the model inference quality degraded. The company wants to receive a notification if the model inference quality degrades. The company also wants to ensure that the problem does not happen again.
Which solution will meet these requirements?
정답:C
설명:
The company needs to address the degradation in model inference quality after 4 months in production and prevent future occurrences by receiving notifications. Retraining the model can address the current degradation, likely caused by data drift (changes in the data distribution over time). Amazon SageMaker Model Monitor is designed to detect and monitor model drift, alerting the company when inference quality degrades, thus meeting both requirements.
Exact Extract from AWS AI Documents:
From the Amazon SageMaker Developer Guide:
"Amazon SageMaker Model Monitor enables you to monitor machine learning models in production for data drift, model performance degradation, and other quality issues. It can detect drift in feature distributions and inference quality, sending notifications when deviations are detected, allowing you to take corrective actions such as retraining the model." (Source: Amazon SageMaker Developer Guide, Monitoring Models with SageMaker Model Monitor) Detailed Explanation:
* Option A: Retrain the model. Monitor model drift by using Amazon SageMaker Clarify.
SageMaker Clarify is used for bias detection and explainability, not for monitoring model drift or inference quality in production. This option does not fully meet the requirements.
* Option B: Retrain the model. Monitor model drift by using Amazon SageMaker Model Monitor.
This is the correct answer. Retraining addresses the current degradation, and SageMaker Model Monitor can detect future drift in inference quality, sending notifications to prevent recurrence, as required.
* Option C: Build a new model. Monitor model drift by using Amazon SageMaker Feature Store.
SageMaker Feature Store is for managing and sharing features, not for monitoring model drift or inference quality. Building a new model may not be necessary if retraining can address the issue.
* Option D: Build a new model. Monitor model drift by using Amazon SageMaker JumpStart.
SageMaker JumpStart provides pre-trained models and solutions for quick deployment, but it does not offer specific tools for monitoring model drift or inference quality in production.
References:
Amazon SageMaker Developer Guide: Monitoring Models with SageMaker Model Monitor (https://docs.aws.
amazon.com/sagemaker/latest/dg/model-monitor.html)
AWS AI Practitioner Learning Path: Module on Model Monitoring and Maintenance AWS Documentation: Addressing Model Drift in Production (https://aws.amazon.com/sagemaker/)
질문 # 99
A company wants to use a large language model (LLM) on Amazon Bedrock for sentiment analysis. The company wants to know how much information can fit into one prompt.
Which consideration will inform the company's decision?
정답:C
질문 # 100
A financial company stores patterns of fraudulent behavior in a database. The company uses this data to conduct investigations.
The company wants to use a graph-based ML solution to develop an AI tool that helps with these investigations.
Which AWS service will meet these requirements?
정답:B
설명:
Comprehensive and Detailed Explanation From Exact AWS AI documents:
Amazon Neptune is a fully managed graph database service optimized for storing and querying highly connected data.
AWS guidance highlights that graph databases are ideal for:
* Fraud detection
* Relationship analysis
* Pattern discovery across entities such as users, transactions, and accounts Amazon Neptune supports popular graph models and enables ML-driven investigations by efficiently traversing relationships, which is critical for fraud pattern analysis.
Why the other options are incorrect:
* OpenSearch (A) is optimized for search and log analytics.
* Aurora (B) is a relational database, not graph-based.
* MemoryDB (D) is an in-memory data store for low-latency workloads.
AWS AI document references:
* Amazon Neptune Overview
* Graph-Based Fraud Detection on AWS
* Using Graph Databases for Investigations
질문 # 101
A company wants to customize a foundation model (FM). The company wants to understand the customization methods and data types that are available.
Select the correct customization method from the following list for each description. Select each customization method one time. (Select THREE.) Customization methods:
* Continued pre-training
* Distillation
* Fine-tuning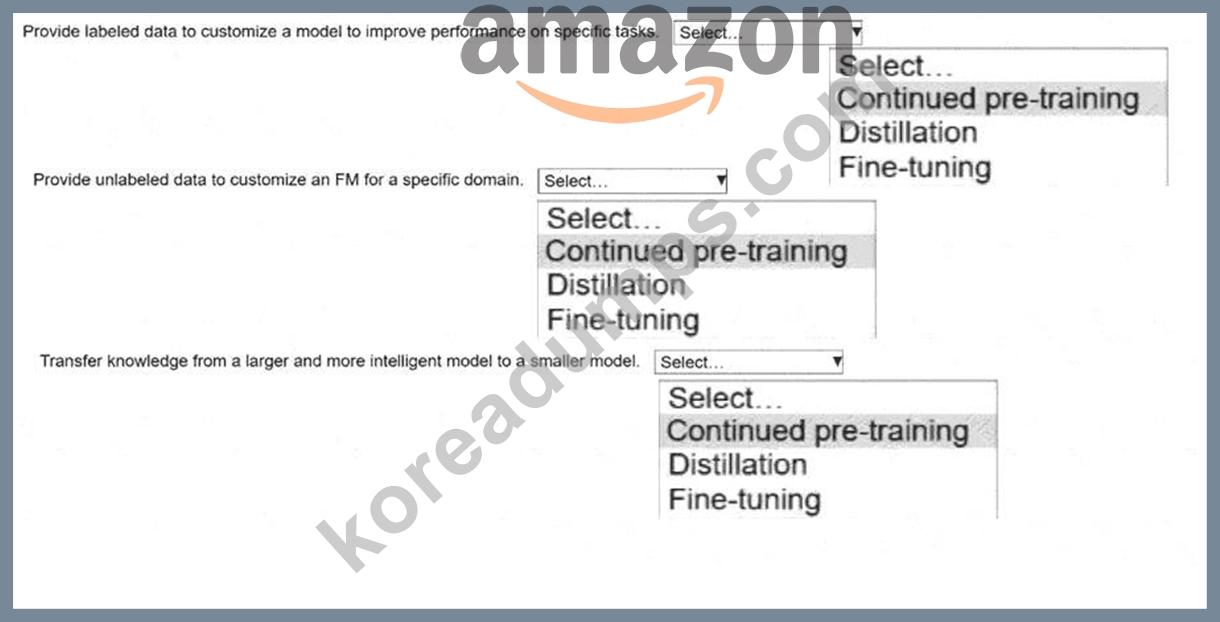
정답:
설명: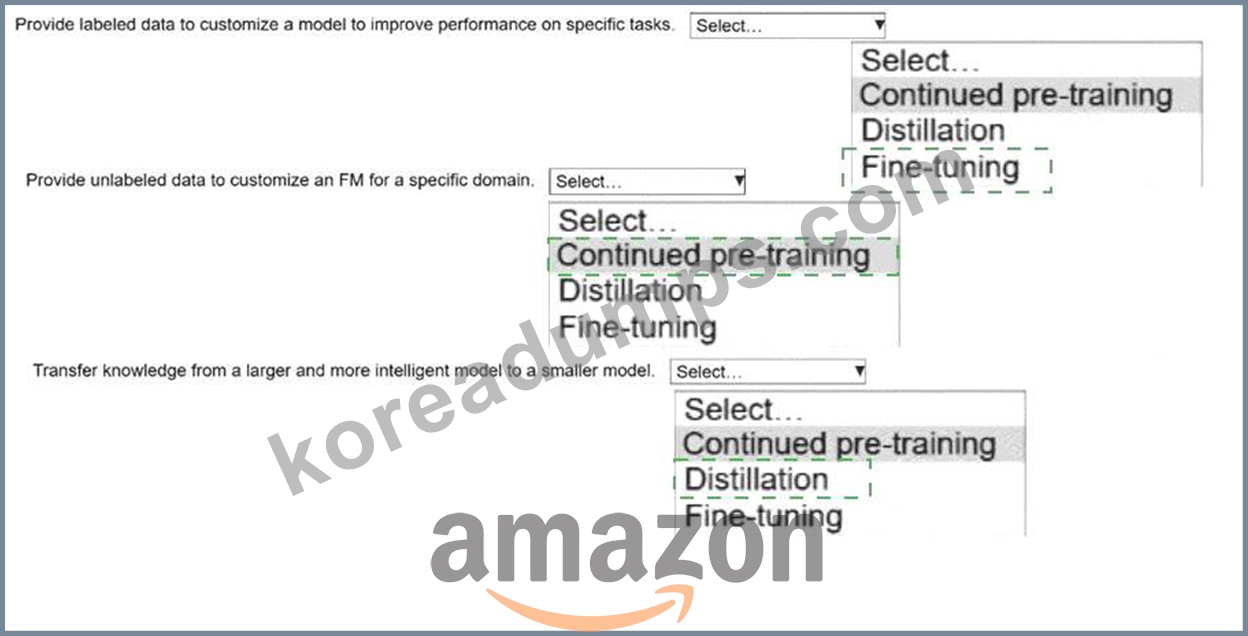
Explanation:
Provide labeled data to customize a model to improve performance on specific tasks.
The answer: Fine-tuning
Comprehensive and Detailed Explanation (AWS AI documents):
AWS generative AI guidance defines fine-tuning as the process of adapting a pre-trained foundation model using labeled, task-specific data. Fine-tuning adjusts the model's parameters so it performs better on a particular task, such as classification, summarization, or domain-specific reasoning.
Fine-tuning is commonly used when:
High-quality labeled data is available
The goal is to improve accuracy on a specific task
The base FM already has strong general capabilities
AWS AI Study Guide References:
AWS foundation model customization methods
AWS fine-tuning concepts for generative AI
Provide unlabeled data to customize a foundation model for a specific domain.
The answer:Continued pre-training
Comprehensive and Detailed Explanation (AWS AI documents):
AWS documentation describes continued pre-training as extending the training of a foundation model using large volumes of unlabeled, domain-specific data. This method helps the model better understand domain vocabulary, structure, and context without requiring labeled datasets.
Continued pre-training is useful when:
Large amounts of unlabeled domain data are available
The goal is to improve domain understanding rather than a single task
Labeling data would be expensive or impractical
AWS AI Study Guide References:
AWS generative AI training lifecycle
AWS guidance on domain adaptation using unlabeled data
Transfer knowledge from a larger and more intelligent model to a smaller model.
The answer: Distillation
Comprehensive and Detailed Explanation (AWS AI documents):
AWS generative AI materials define distillation as a technique where a smaller model (student) learns to replicate the behavior of a larger, more capable model (teacher). The goal is to retain most of the performance while reducing model size, cost, and inference latency.
Distillation is commonly used to:
Reduce operational costs
Improve inference speed
Deploy models to resource-constrained environments
AWS AI Study Guide References:
AWS model optimization techniques
AWS knowledge distillation concepts
질문 # 102
A company deployed a Retrieval Augmented Generation (RAG) application on Amazon Bedrock that gathers financial news to distribute in daily newsletters. Users have recently reported politically influenced ideas in the newsletters.
Which Amazon Bedrock Guardrails feature can identify and filter this content?
정답:A
설명:
Denied topics are the appropriate Amazon Bedrock Guardrails feature because the company wants to identify and prevent responses relating to a specific subject area-in this case, unwanted political content.
AWS explains: "You can specify a set of denied topics in a guardrail that are undesirable" for a generative AI application. When a prompt or response is identified as belonging to a configured denied topic, the guardrail can block that content and return the configured blocked-response message.
The company could therefore define a denied topic describing political advocacy, political commentary, politically influenced recommendations, or whatever political-content boundary its newsletter policy prohibits. Amazon Bedrock Guardrails evaluates content contextually against the topic definition rather than relying solely on individual keywords.
This distinction is important because political ideas can be expressed without using predictable keywords. A contextual denied-topic policy is consequently better suited than maintaining a static list of political terms.
Word filters, option A, block configured words or phrases through direct matching. They are useful for profanity, competitor names, or other exact terms but are less suitable for broad conceptual topics.
Sensitive information filters, option C, detect personally identifiable information and configured sensitive patterns. They address privacy rather than political subject matter.
Content filters, option D, detect predefined harmful-content categories. Current Amazon Bedrock Guardrails categories include Hate, Insults, Sexual, Violence, Misconduct, and Prompt Attack. Politics is not one of those predefined content-filter categories.
Denied topics are specifically intended for application-specific subjects that the organization chooses to prohibit. AWS gives examples such as a banking assistant being configured to avoid investment-advice or cryptocurrency discussions.
Consequently, the RAG architecture does not change the appropriate control. Guardrails can evaluate generated output after retrieval and generation, and the company can define politics-related content as an undesirable subject.
Therefore, the correct answer is B. Denied topics.
질문 # 103
......
Amazon인증AIF-C01시험준비를 하고 계시다면KoreaDumps에서 출시한Amazon인증AIF-C01덤프를 제일 먼저 추천해드리고 싶습니다. KoreaDumps제품은 여러분들이 제일 간편한 방법으로 시험에서 고득점을 받을수 있도록 도와드리는 시험동반자입니다. Amazon인증AIF-C01시험패는KoreaDumps제품으로 고고고!
AIF-C01인증덤프샘플 다운: https://www.koreadumps.com/AIF-C01_exam-braindumps.html
KoreaDumps AIF-C01 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1XjLwkhcoGUlcm0Ij801IH2NH6S3FMLrM