DOWNLOAD the newest LatestCram DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL
If you try to free download the demos on the website, and you will be amazed by our excellent DP-750 preparation engine. We can absolutely guarantee that even if the first time to take the exam, candidates can pass smoothly. You can find the latest version of DP-750 Practice Guide in our website and you can practice DP-750 study materials in advance correctly and assuredly. The following passages are their advantages for your information
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> DP-750 Certification Torrent <<
If you want to get something done, just roll up your sleeves and do it. If you want to clear DP-750 exam, let our training online files help you. The more difficult the thing is the more important and useful it is. Microsoft DP-750 training online files help your difficult thing become simple. Professionals be professionals! People can be defeated, but can't be beat. If you are determined to get a IT certification, you should not give up if you fail exam. Our DP-750 Training Online files will be the right exam materials for your choice.
NEW QUESTION # 84
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
Answer: B
Explanation:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
NEW QUESTION # 85
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to profile a table to meet the following requirements:
* The count of null values per column must be evaluated repeatedly as new records are added to the table.
* Changes in the count of null values must be observable over the progression of the dataset.
Which type of profile should you create?
Answer: A
Explanation:
A time series profile repeatedly calculates data-quality metrics as a table changes and preserves those measurements over time. This makes it possible to observe whether the number of null values in each column is increasing, decreasing, or remaining stable as new records are added. A snapshot profile evaluates the table at a particular point in time and is therefore insufficient when the requirement is to analyze metric progression across multiple updates. Inference is associated with deriving information such as a schema or statistical characteristics; it is not the profile type used to maintain a historical sequence of monitoring measurements.
Because the question requires repeated evaluation and the ability to observe changes throughout the dataset's progression, the time series profile satisfies both requirements.
NEW QUESTION # 86
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.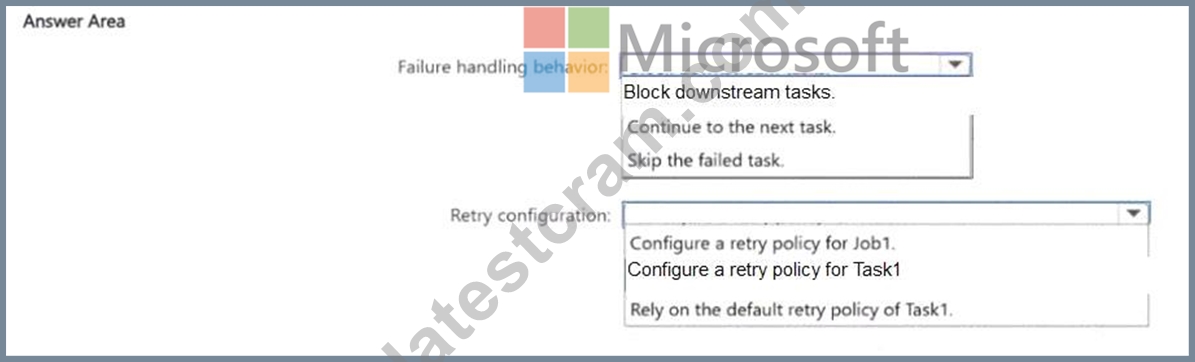
Answer:
Explanation: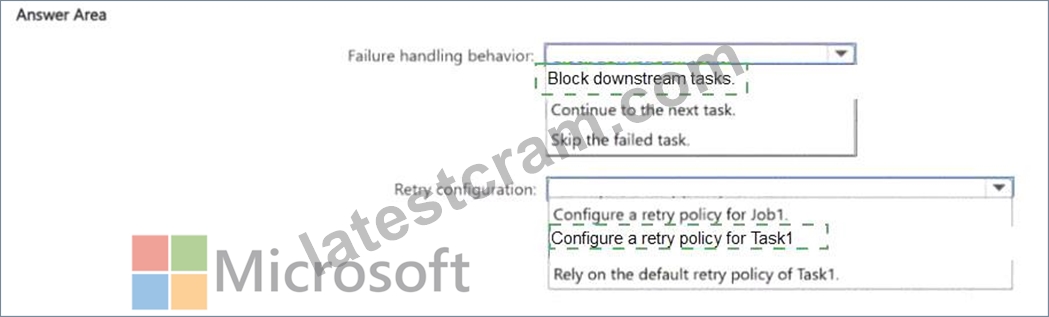
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 87
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: A
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 88
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.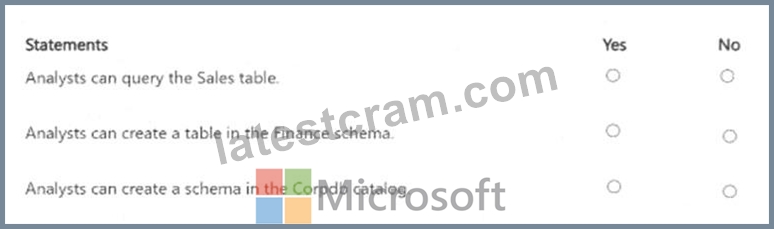
Answer:
Explanation: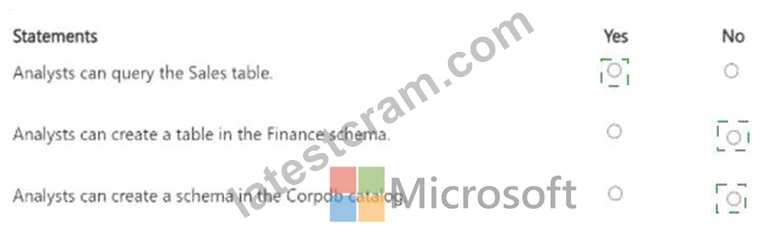
Explanation: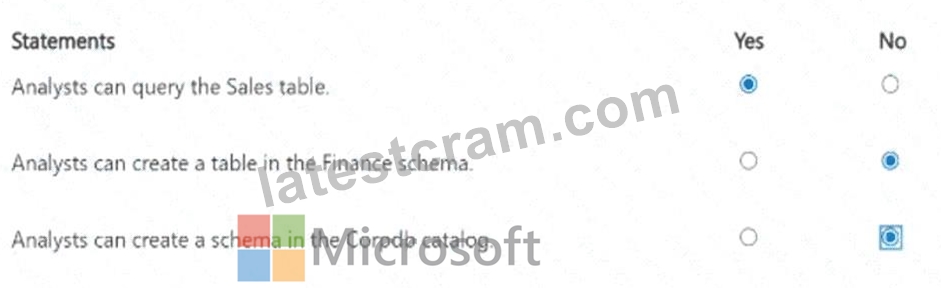
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 89
......
Before we start develop a new DP-750 real exam, we will prepare a lot of materials. After all, we must ensure that all the questions and answers of the DP-750 exam materials are completely correct. First of all, we have collected all relevant reference books. Most of the DP-750 Practice Guide is written by the famous experts in the field. And we also add the latest knowledage points into the content of the DP-750 learning questions, so that they are always being up to date.
DP-750 Latest Practice Questions: https://www.latestcram.com/DP-750-exam-cram-questions.html
2026 Latest LatestCram DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL