Our test engine is an exam simulation that makes our candidates feel the atmosphere of AI-200 actual test and face the difficulty of certification exam ahead. It reminds you of your mistakes when you practice AI-200 vce dumps next time and you can set your test time like in the formal test. Our AI-200 Training Materials cover the most content of the real exam and the accuracy of our AI-200 test answers is 100% guaranteed.
| Section | Objectives |
|---|---|
| Topic 1: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 2: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 3: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
>> Reliable AI-200 Learning Materials <<
The service of giving the free trial of our AI-200 practice engine shows our self-confidence and actual strength about study materials in our company. Besides, our company's website purchase process holds security guarantee, so you needn’t be anxious about download and install our AI-200 Exam Questions. With our company employees sending the link to customers, we ensure the safety of our AI-200 study materials that have no virus.
NEW QUESTION # 96
An application deployed to AKS depends on an internal API hosted in the same cluster. All pods are healthy and report Ready status, but requests between the services time out.
You need to determine whether the issue is related to Kubernetes service configuration or application code.
What should you do first?
Answer: A
NEW QUESTION # 97
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
Answer: C
Explanation:
Detailed Explanation: Azure Key Vault references in App Service settings satisfy the requirement to keep secrets out of container images, source control, and directly stored application configuration. App Service resolves the referenced secret at runtime by using the app identity, so the application can consume the value as a normal setting without embedding credentials in the image. GitHub secrets are build/deployment secrets rather than a runtime App Service secret-delivery mechanism. Dockerfile ENV instructions would place secret material in the image configuration and violate the case requirements.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Use Key Vault references for App Service and Functions | Managed identities for Azure resources
Topic 2, Fabrikam Inc
Background - Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure. The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security. The solution must meet strict performance, scalability, and security requirements. Current environment - Application architecture - The Recommendation engine is a customer- facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA). Embeddings are stored in Azure Database for PostgreSQL by using pgvector. Semantic retrieval uses metadata filtering combined with vector similarity search. Azure Managed Redis is used as a caching layer. Front-end and API workloads are deployed to Azure Container Apps (ACA). Batch model retraining workloads run in Azure Kubernetes Service (AKS). Container and CI/CD - Container images are stored in Azure Container Registry (ACR). CI/CD uses ACR Tasks to build images on commit. ACA environments support revision management. AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring - Logs are collected in Azure Monitor. Teams inspect container logs and Kubernetes events when troubleshooting. Developers write KQL queries to analyze latency spikes. Business requirements - Customer experience: Maintain a seamless, low-latency recommendation experience for end-users, even during unpredictable seasonal traffic spikes. Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs. Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction. Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets. Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers. Technical requirements - Performance: Semantic search latency must remain under 200 milliseconds at peak load. Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput.
Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints. Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization. Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates. Identity: Use managed identities for all service-to-service and service-to-database authentication. Plain-text credentials in configuration files are strictly prohibited. Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy. Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero. CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits. Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
NEW QUESTION # 98
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet. What should you configure?
Answer: C
NEW QUESTION # 99
Hotspot Question
You develop an application that sells AI generated images based on user input. You recently started a marketing campaign that displays unique ads every second day.
Sales data is stored in Azure Cosmos DB with the date of each sale being stored in a property named 'whenFinished'.
The marketing department requires a view that shows the number of sales for each unique ad.
You need to implement the query for the view.
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.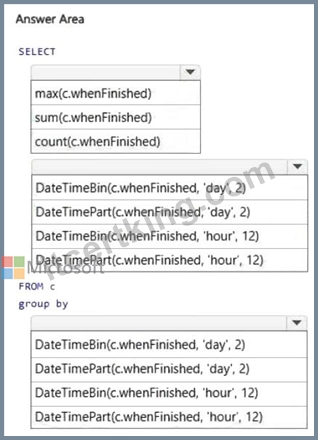
Answer:
Explanation: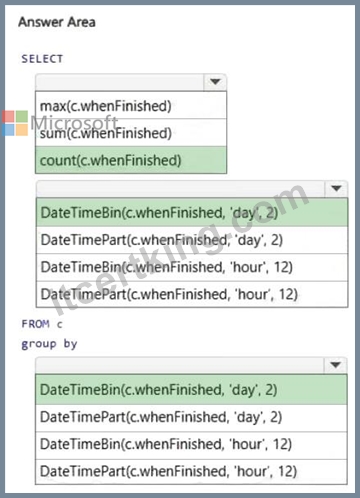
Explanation:
Box 1: count(c.whenFinished)
For the number of sales we need to use the count function.
Box 2: DateTimeBin(c.whenFinished, 'day', 2)
Box 3: DateTimeBin(c.whenFinished, 'day', 2)
Reference:
https://learn.microsoft.com/en-us/cosmos-db/query/datetimebin
NEW QUESTION # 100
Drag and Drop Question
You are provisioning and configuring a Service Bus processor for AI batch jobs.
The processor must connect to an existing queue, register handlers for message and error processing, and then begin receiving messages.
You need to provision and configure the Service Bus processor for message and error handling.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.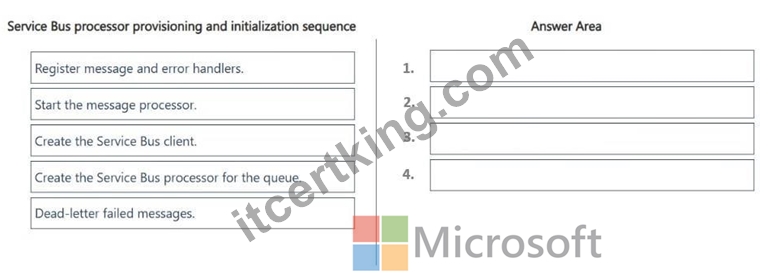
Answer:
Explanation: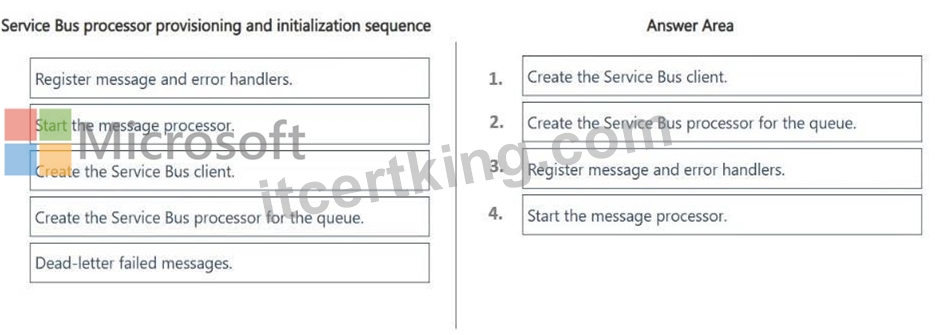
Explanation:
Step 1: Create the Service Bus client
This establishes the initial connection to your Azure Service Bus namespace using a connection string or Azure Identity credentials.
Step 2: Create the Service Bus processor for the queue
Once you have a client, you call its factory method to instantiate a processor dedicated specifically to targeting your queue Step 3: Register message and error handlers The processor requires event handlers assigned to its processing and error properties to explicitly dictate what happens when a message arrives or an exception occurs Step 4: Start the message processor The processor remains idle until you call the method to start receiving, which initiates the internal loop that listens for and pulls down messages.
Reference:
https://learn.microsoft.com/en-us/azure/service-bus-messaging/service-bus-dotnet-get-started-with-queues?tabs=passwordless
NEW QUESTION # 101
......
With the high employment pressure, more and more people want to ease the employment tension and get a better job. The best way for them to solve the problem is to get the AI-200 certification. Because the certification is the main symbol of their working ability, if they can own the AI-200 certification, they will gain a competitive advantage when they are looking for a job. An increasing number of people have become aware of that it is very important for us to gain the AI-200 Exam Questions in a short time. Because all of them have realized that it is indispensable to our daily life and work.
AI-200 Practice Test Fee: https://www.itcertking.com/AI-200_exam.html