Free demos offered by Itcerttest gives users a chance to try the product before buying. Users can get an idea of the Databricks-Certified-Professional-Data-Engineer exam dumps, helping them determine if it's a good fit for their needs. The demo provides access to a limited portion of the Databricks-Certified-Professional-Data-Engineer Dumps material to give users a better understanding of the content. Overall, Itcerttest Databricks Databricks-Certified-Professional-Data-Engineer free demo is a valuable opportunity for users to assess the value of the Itcerttest's study material before making a purchase.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Topic 2: Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Topic 3: Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Topic 4: Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Handling missing or inconsistent data - Standardization and normalization |
| Topic 5: Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Batch and incremental processing logic - Data transformation and aggregation |
| Topic 6: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Topic 7: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 8: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Topic 9: Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Topic 10: Cost & Performance Optimisation | 13% | - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling |
>> Databricks-Certified-Professional-Data-Engineer Exam Practice <<
All Of Databricks staff knows it is very difficult to get Databricks certificate. But taking Databricks certification exam and getting the certificate are a way to upgrade your ability and prove self-worth, so you have to choose to get the certificate. Isn't there an easy way to help all candidates pass their exam successfully? Of course there is. Databricks-Certified-Professional-Data-Engineer Exam Dumps are the best way. Itcerttest has everything you need and can absolutely satisfy your demands. You can visit Itcerttest.com to know more details and find the exam materials you want to.
NEW QUESTION # 165
Which of the following section in the UI can be used to manage permissions and grants to tables?
Answer: C
Explanation:
Explanation
The answer is Data Explorer
NEW QUESTION # 166
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG
post_text STRING
post_id STRING
longitude FLOAT
latitude FLOAT
post_time TIMESTAMP
date DATE
Based on the above schema, which column is a good candidate for partitioning the Delta Table?
Answer: A
Explanation:
Partitioning a Delta Lake table is a strategy used to improve query performance by dividing the table into distinct segments based on the values of a specific column. This approach allows queries to scan only the relevant partitions, thereby reducing the amount of data read and enhancing performance.
Considerations for Choosing a Partition Column:
Cardinality: Columns with high cardinality (i.e., a large number of unique values) are generally poor choices for partitioning. High cardinality can lead to a large number of small partitions, which can degrade performance.
Query Patterns: The partition column should align with common query filters. If queries frequently filter data based on a particular column, partitioning by that column can be beneficial.
Partition Size: Each partition should ideally contain at least 1 GB of data. This ensures that partitions are neither too small (leading to too many partitions) nor too large (negating the benefits of partitioning).
Evaluation of Columns:
date:
Cardinality: Typically low, especially if data spans over days, months, or years.
Query Patterns: Many analytical queries filter data based on date ranges.
Partition Size: Likely to meet the 1 GB threshold per partition, depending on data volume.
user_id:
Cardinality: High, as each user has a unique ID.
Query Patterns: While some queries might filter by user_id, the high cardinality makes it unsuitable for partitioning.
Partition Size: Partitions could be too small, leading to inefficiencies.
post_id:
Cardinality: Extremely high, with each post having a unique ID.
Query Patterns: Unlikely to be used for filtering large datasets.
Partition Size: Each partition would be very small, resulting in a large number of partitions.
post_time:
Cardinality: High, especially if it includes exact timestamps.
Query Patterns: Queries might filter by time, but the high cardinality poses challenges.
Partition Size: Similar to user_id, partitions could be too small.
Conclusion:
Given the considerations, the date column is the most suitable candidate for partitioning. It has low cardinality, aligns with common query patterns, and is likely to result in appropriately sized partitions.
Reference:
Delta Lake Best Practices
Partitioning in Delta Lake
NEW QUESTION # 167
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
Answer: B
Explanation:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
:
Databricks Documentation on Delta Live Tables: Delta Live Tables Guide
NEW QUESTION # 168
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: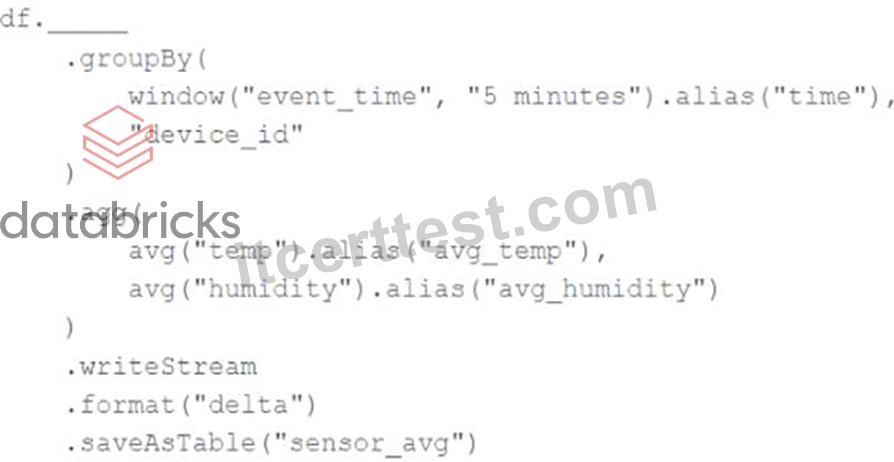
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: E
Explanation:
The correct answer is A. withWatermark("event_time", "10 minutes"). This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming. References:
* Watermarking: https://docs.databricks.com/spark/latest/structured-streaming/watermarks.html
* Windowed aggregations:
https://docs.databricks.com/spark/latest/structured-streaming/window-operations.html
NEW QUESTION # 169
Which is a key benefit of an end-to-end test?
Answer: D
Explanation:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real-world, user behavior, ensuring that the system as a whole operates correctly.
:
Software Testing: End-to-End Testing
NEW QUESTION # 170
......
We are willing to provide all people with the demo of our Databricks-Certified-Professional-Data-Engineer study tool for free. If you have any doubt about our products that will bring a lot of benefits for you. The trial demo of our Databricks-Certified-Professional-Data-Engineer question torrent must be a good choice for you. By the trial demo provided by our company, you will have the opportunity to closely contact with our Databricks-Certified-Professional-Data-Engineer Exam Torrent, and it will be possible for you to have a view of our products. More importantly, we provide all people with the trial demo for free before you buy our Databricks-Certified-Professional-Data-Engineer exam torrent and it means that you have the chance to download from our web page for free; you do not need to spend any money.
Databricks-Certified-Professional-Data-Engineer Frenquent Update: https://www.itcerttest.com/Databricks-Certified-Professional-Data-Engineer_braindumps.html