2026 Latest Real4dumps DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=10V-DzKVzvKz3WCL9WJzXoUvDzJ0EQ429
We know students run on low budgets so we made every possible effort to reduce the pre-purchase doubts. You can easily avail of our product at an affordable price. We are aware that the syllabus of DP-750 exam is extremely dynamic and changes with incoming updates, so we also offer you updates for free after purchase for 1 year. We assure you in every possible way that our Microsoft DP-750 Exam Preparation material is the most reliable there is.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 2: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Topic 4: Prepare and process data | 30-35% | - Ingest and transform data
|
With the rapid development of the economy, the demands of society on us are getting higher and higher. If you can have DP-750 certification, then you will be more competitive in society. Our study materials will help you get the according certification you want to have. Believe me, after using our study materials, you will improve your work efficiency. You will get more opportunities than others, and your dreams may really come true in the near future. DP-750 Test Guide will make you more prominent in the labor market than others, and more opportunities will take the initiative to find you.
NEW QUESTION # 24
You have an Azure Databricks workspace that is enabled for Unity Catalog You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Answer: C
Explanation:
The correct answer is B - configure a checkpoint location.
A checkpoint is the Structured Streaming mechanism for fault tolerance. Databricks writes the committed offset (i.e., how far through the source stream the job has successfully read and processed) to a durable path in ADLS Gen2 or DBFS after each micro-batch. When the cluster restarts, the engine reads that offset and resumes from the next unprocessed record - nothing is reprocessed, nothing is skipped.
Option A (increase trigger interval) affects how frequently micro-batches run but does nothing to record progress between runs. Option C (watermark) handles late-arriving events in event-time windows but doesn't control source offset tracking. Option D (enable CDF on the target table) tracks changes made to a Delta table for downstream consumers - it has no bearing on the streaming job's own fault tolerance or offset management.
Checkpointing is a required configuration for any production streaming job. Without it, every cluster restart triggers a full replay from the source.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 25
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.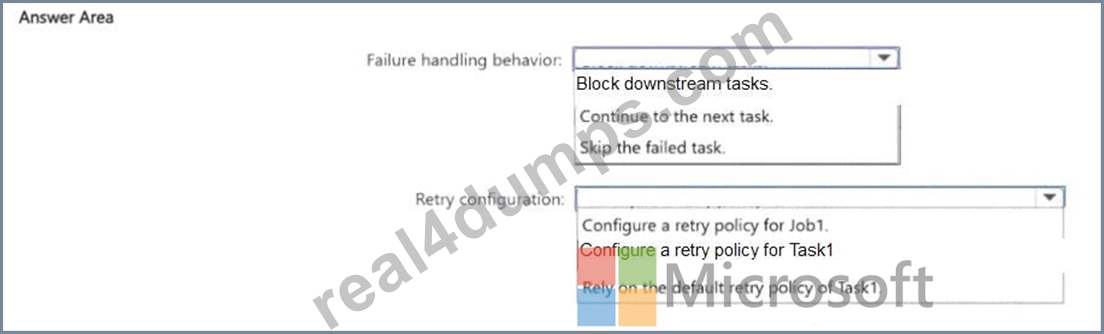
Answer:
Explanation: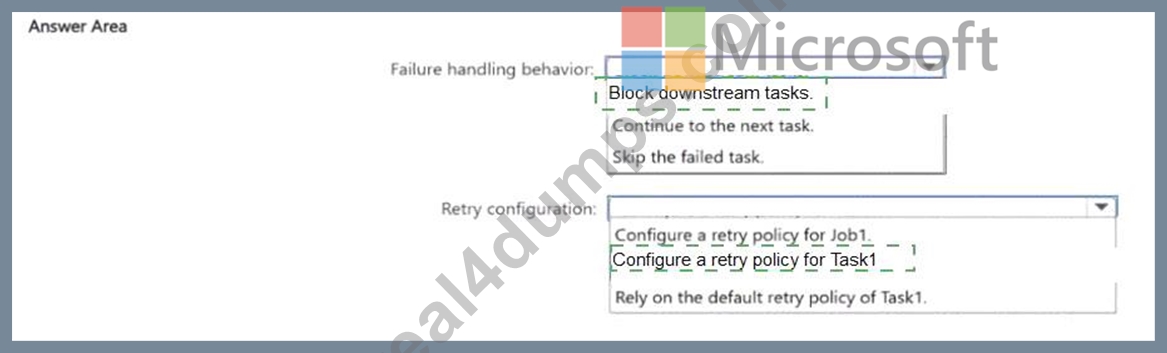
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 26
Which operation guarantees ACID compliance in Delta Lake?
Answer: D
Explanation:
Delta Lake ensures ACID compliance through its transaction log (Delta log). It tracks all changes, enabling consistency, isolation, and rollback capabilities. File append operations alone are not transactional. RDD transformations are low-level and not ACID-aware.
NEW QUESTION # 27
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: C
Explanation:
Create separate tasks for ingestion, cleansing, and curation is the best architectural fit.
This modular workflow approach natively addresses the scenario's technical challenges:
Modularity and Resource Efficiency: Splitting the pipeline into distinct, sequential tasks allows you to configure dedicated, non-interactive compute clusters tailored to the specific resource requirements of each phase (e.g., lightweight for ingestion, heavier memory for curation).
Handling Peak Loads: Independent task scaling ensures that the heavy ingestion phase can scale up to handle event hub spikes without dragging down or over-allocating resources for downstream processing.
Checkpointing & Schema Drift: Separate tasks allow structured streaming checkpoints to be cleanly isolated for each step, ensuring that if a pipeline restarts, it continues exactly where it left off without reprocessing old events. Schema evolution can also be intercepted and handled gracefully between stages rather than breaking a monolith script.
Scenario:
Technical Requirements, Contoso identifies the following environment and compute requirements:
-> Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Technical Requirements, Contoso identifies the following data ingestion and processing requirements:
-> Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
Problem Statements, The company's existing analytics environment has several issues:
Ingestion
Telemetry pipelines fall behind during peak loads.
Telemetry ingestion fails when schema drift occurs.
Streaming pipelines reprocess events after a pipeline restarts.
Reference:
https://www.meegle.com/en_us/topics/etl-pipeline/etl-pipeline-for-hadoop-ecosystems
NEW QUESTION # 28
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.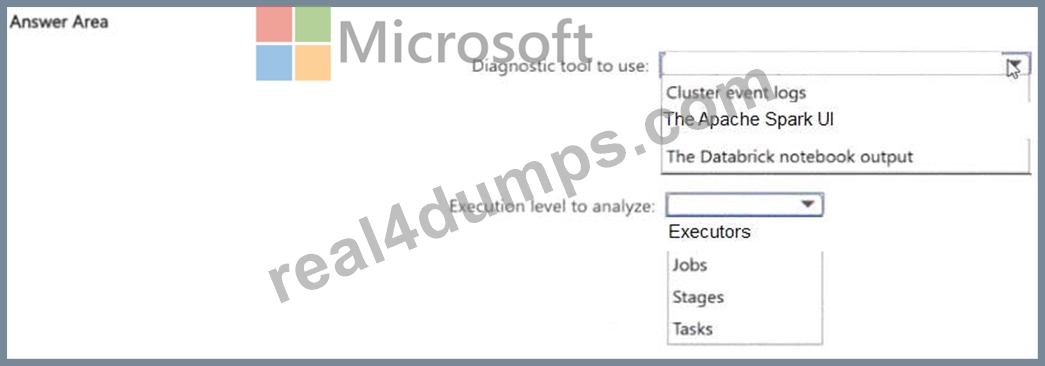
Answer:
Explanation: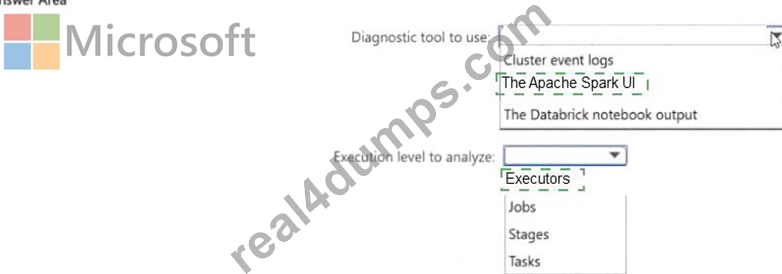
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 29
......
There are more and more same products in the market of study materials. We know that it will be very difficult for you to choose the suitable DP-750 learning guide. If you buy the wrong study materials, it will pay to its adverse impacts on you. It will be more difficult for you to pass the DP-750 Exam. So if you want to pass your exam and get the certification in a short time, choosing our DP-750 exam questions are very important for you. You will find that our DP-750 practice guide is the most suitable for you.
DP-750 Valid Guide Files: https://www.real4dumps.com/DP-750_examcollection.html
DOWNLOAD the newest Real4dumps DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10V-DzKVzvKz3WCL9WJzXoUvDzJ0EQ429