無料でクラウドストレージから最新のPass4Test ARA-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1_VRvZkkZAGoD9F27biqUVCQGQbTgzq_a
周りの多くの人は全部Snowflake ARA-C01資格認定試験にパースしまして、彼らはどのようにできましたか。今には、あなたにPass4Testを教えさせていただけませんか。我々社サイトのSnowflake ARA-C01問題庫は最新かつ最完備な勉強資料を有して、あなたに高品質のサービスを提供するのはARA-C01資格認定試験の成功にとって唯一の選択です。躊躇わなくて、Pass4Testサイト情報を早く了解して、あなたに試験合格を助かってあげますようにお願いいたします。
Snowflake ARA-C01認定を獲得するには、候補者は、スノーフレークアーキテクチャと機能に関連する幅広いトピックをカバーする厳格な試験に合格する必要があります。この試験は、60の複数選択の質問で構成され、90分間タイミングが合っています。この試験はコンピューターベースであり、候補者の自宅またはオフィスから認可されたテストセンターまたはリモートで撮影できます。
Snowflake ARA-C01認証試験を通ってからかなり人生の新しいマイレージカードがあるようで、仕事に大きく向上してIT業種のすべての方は持ちたいでしょう。多くの人はこんなに良いの認証試験を通ることが難しくて合格率はかなり低いと思っています。ちっとも努力しないと合格することが本当に難しいです。Snowflake ARA-C01試験を通るのはかなり優れた専門知識が必要です。Pass4TestがSnowflake ARA-C01認証試験を助けて通るのウエブサイトでございます。Pass4TestはSnowflake ARA-C01認証試験に向かって問題集を開発しておって、君のいい成績をとることを頑張ります。一目でわかる最新の出題傾向でわかりやすい解説、充実の補充問題などで買うことは一番お得ですよ。
Snowflake ARA-C01試験の資格を得るには、まずSnowPro Advanced Architect認定を取得する必要があります。この認定には、SnowPro Core試験に合格し、データモデリングおよびパフォーマンスチューニングの能力を示す必要があります。候補者がこの認定を取得した後、ARA-C01試験を受けて、さらに専門知識を検証することができます。
質問 # 117
Which feature provides the capability to define an alternate cluster key for a table with an existing cluster key?
正解:A
解説:
Explanation
A materialized view is a feature that provides the capability to define an alternate cluster key for a table with an existing cluster key. A materialized view is a pre-computed result set that is stored in Snowflake and can be queried like a regular table. A materialized view can have a different cluster key than the base table, which can improve the performance and efficiency of queries on the materialized view. A materialized view can also support aggregations, joins, and filters on the base table data. A materialized view is automatically refreshed when the underlying data in the base table changes, as long as the AUTO_REFRESH parameter is set to true1.
References:
* Materialized Views | Snowflake Documentation
質問 # 118
Snowflake data replication can be used to replicate data between cloud providers.
正解:A
質問 # 119
A table for IOT devices that measures water usage is created. The table quickly becomes large and contains more than 2 billion rows.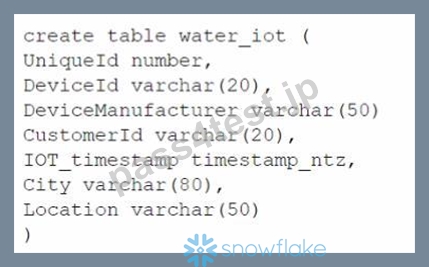
The general query patterns for the table are:
1. DeviceId, lOT_timestamp and Customerld are frequently used in the filter predicate for the select statement
2. The columns City and DeviceManuf acturer are often retrieved
3. There is often a count on Uniqueld
Which field(s) should be used for the clustering key?
正解:A
解説:
A clustering key is a subset of columns or expressions that are used to co-locate the data in the same micro-partitions, which are the units of storage in Snowflake. Clustering can improve the performance of queries that filter on the clustering key columns, as it reduces the amount of data that needs to be scanned. The best choice for a clustering key depends on the query patterns and the data distribution in the table. In this case, the columns DeviceId, IOT_timestamp, and CustomerId are frequently used in the filter predicate for the select statement, which means they are good candidates for the clustering key. The columns City and DeviceManufacturer are often retrieved, but not filtered on, so they are not as important for the clustering key.
The column UniqueId is used for counting, but it is not a good choice for the clustering key, as it is likely to have a high cardinality and a uniform distribution, which means it will not help to co-locate the data.
Therefore, the best option is to use DeviceId and CustomerId as the clustering key, as they can help to prune the micro-partitions and speed up the queries. References: Clustering Keys & Clustered Tables, Micro-partitions & Data Clustering, A Complete Guide to Snowflake Clustering
質問 # 120
A company is designing high availability and disaster recovery plans and needs to maximize redundancy and minimize recovery time objectives for their critical application processes. Cost is not a concern as long as the solution is the best available. The plan so far consists of the following steps:
1. Deployment of Snowflake accounts on two different cloud providers.
2. Selection of cloud provider regions that are geographically far apart.
3. The Snowflake deployment will replicate the databases and account data between both cloud provider accounts.
4. Implementation of Snowflake client redirect.
What is the MOST cost-effective way to provide the HIGHEST uptime and LEAST application disruption if there is a service event?
正解:D
解説:
To provide the highest uptime and least application disruption in case of a service event, the best option is to use the Business Critical Snowflake edition and connect the applications using the <organization_name>-
<accountLocator> URL. The Business Critical Snowflake edition offers the highest level of security, performance, and availability for Snowflake accounts. It includes features such as customer-managed encryption keys, HIPAA compliance, and 4-hour RPO and RTO SLAs. It also supports account replication and failover across regions and cloud platforms, which enables business continuity and disaster recovery. By using the <organization_name>-<accountLocator> URL, the applications can leverage the Snowflake Client Redirect feature, which automatically redirects the client connections to the secondary account in case of a failover. This way, the applications can seamlessly switch to the backup account without any manual intervention or configuration changes. The other options are less cost-effective or less reliable because they either use a lower edition of Snowflake, which does not support account replication and failover, or they use the <organization_name>-<connection_name> URL, which does not support client redirect and requires manual updates to the connection string in case of a failover. References:
* [Snowflake Editions] 1
* [Replication and Failover/Failback] 2
* [Client Redirect] 3
* [Snowflake Account Identifiers] 4
質問 # 121
What are purposes for creating a storage integration? (Choose three.)
正解:A、B、D
解説:
A storage integration is a Snowflake object that stores a generated identity and access management (IAM) entity for an external cloud provider, such as Amazon S3, Google Cloud Storage, or Microsoft Azure Blob Storage. This integration allows Snowflake to read data from and write data to an external storage location referenced in an external stage1.
One purpose of creating a storage integration is to support multiple external stages using one single Snowflake object. An integration can list buckets (and optional paths) that limit the locations users can specify when creating external stages that use the integration. Note that many external stage objects can reference different buckets and paths and use the same storage integration for authentication1. Therefore, option C is correct.
Another purpose of creating a storage integration is to avoid supplying credentials when creating a stage or when loading or unloading data. Integrations are named, first-class Snowflake objects that avoid the need for passing explicit cloud provider credentials such as secret keys or access tokens. Integration objects store an IAM user ID, and an administrator in your organization grants the IAM user permissions in the cloud provider account1. Therefore, option D is correct.
A third purpose of creating a storage integration is to store a generated IAM entity for an external cloud provider regardless of the cloud provider that hosts the Snowflake account. For example, you can create a storage integration for Amazon S3 even if your Snowflake account is hosted on Azure or Google Cloud Platform. This allows you to access data across different cloud platforms using Snowflake1. Therefore, option B is correct.
Option A is incorrect, because creating a storage integration does not control access to Snowflake data using a master encryption key. Snowflake encrypts all data using a hierarchical key model, and the master encryption key is managed by Snowflake or by the customer using a cloud provider's key management service. This is independent of the storage integration feature2.
Option E is incorrect, because creating a storage integration does not create private VPC endpoints. Private VPC endpoints are a network configuration option that allow direct, secure connectivity between VPCs without traversing the public internet. This is also independent of the storage integration feature3.
Option F is incorrect, because creating a storage integration does not manage credentials from multiple cloud providers in one single Snowflake object. A storage integration is specific to one cloud provider, and you need to create separate integrations for each cloud provider you want to access4.
質問 # 122
......
ARA-C01最新試験情報: https://www.pass4test.jp/ARA-C01.html
2026年Pass4Testの最新ARA-C01 PDFダンプおよびARA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1_VRvZkkZAGoD9F27biqUVCQGQbTgzq_a