Our company is a professional certificate study materials provider. We have occupied in this field for years, we are in the leading position of providing exam materials. DP-800 training materials of us is high-quality and accurate, for we have a profession team to verify and update the DP-800 answers and questions. We have received many good feedbacks from our customers for helping pass the exam successfully. Furthermore, we provide you free update for one year after purchasing DP-800 exam dumps from us.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Exam Format: | Case studies, Multiple choice |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Available Languages: | English |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
>> Valid DP-800 Exam Syllabus <<
There are Developing AI-Enabled Database Solutions (DP-800) exam questions provided in Developing AI-Enabled Database Solutions (DP-800) PDF questions format which can be viewed on smartphones, laptops, and tablets. So, you can easily study and prepare for your Developing AI-Enabled Database Solutions (DP-800) exam anywhere and anytime. You can also take a printout of these Microsoft PDF Questions for off-screen study. To improve the Developing AI-Enabled Database Solutions (DP-800) exam questions, VCE4Plus always upgrades and updates its DP-800 dumps PDF format and it also makes changes according to the syllabus of the Developing AI-Enabled Database Solutions (DP-800) exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 22
You need to enable similarity search to provide the analysts with the ability to retrieve the most relevant health summary reports. The solution must minimize latency.
What should you include in the solution?
Answer: C
Explanation:
The correct answer is D because the requirement is to enable similarity search over embedding vectors and to minimize latency . Microsoft documents that CREATE VECTOR INDEX is specifically used to create an index on vector data for approximate nearest neighbor (ANN) search , which is designed to accelerate vector similarity queries compared to exact k-nearest-neighbor scans.
This matches the scenario exactly. The VehicleHealthSummary table already includes an Embeddings (vector (1536)) column. In Microsoft SQL platforms, embeddings are stored in vector columns and queried for semantic similarity. To improve performance and reduce response time, Microsoft recommends a vector index , not a regular B-tree nonclustered index and not a full-text index. A vector index is purpose-built for finding the most similar vectors efficiently.
The other options are not appropriate:
* A would require manual comparison logic and would increase latency rather than minimize it.
* B is incorrect because a standard nonclustered index is not the index type used for vector similarity operations.
* C is incorrect because full-text indexes are for textual token-based search, not numeric vector embeddings.
Microsoft's current documentation is explicit that vector indexes support approximate nearest neighbor search , and that the optimizer can use the ANN index automatically for vector queries. That is the exam- aligned design choice when the goal is fast retrieval of the most relevant health summary reports from an embeddings column.
Topic 2, Fabrikam Case
- To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Existing Environment - Azure Environment - Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables: * Patients * Employees * Procedures * Transactions * UsefulPrompts * ProcedureDocuments You store a column master key as a secret in Azure Key Vault. You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements - Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent. Requirements - Planned Changes - Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration. Security Requirements - Fabrikam identifies the following security requirements: * The TransactionProcessing application must use a passwordless connection to DB1. * The Employees table contains two columns named TaxID and Salary that must be encrypted at rest. * Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data. Database Performance Requirements Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing Fabrikam identifies the following AI-related requirements: * Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF). * Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric. * The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements - Fabrikam identifies the following development requirements: * Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total. * Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API: o Read data from the procedures table without authentication. o Read and insert data into the Transactions table once authenticated. o Execute the sp_UpdateProcedurePatient stored procedure. * Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days. * Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.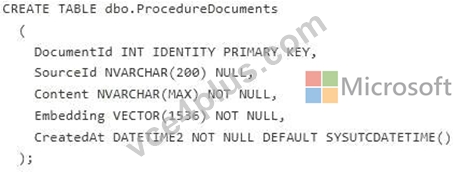
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.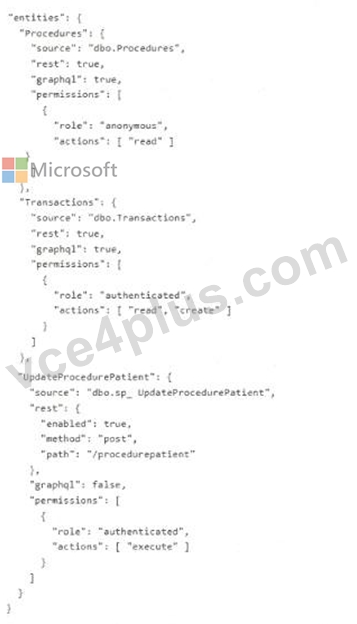
NEW QUESTION # 23
Drag and Drop Question
You have a SQL database in Microsoft Fabric that contains a table named WebSite.Logs.
WebSite.Logs stores application telemetry data. WebSite.Logs contains a nvarchar (max) column named log that stores JSON documents.
You have a daily report that filters by the $.severity JSON property and returns LogId, LogDateTime, and log. The report frequently causes full table scans.
You need to modify WebSite.Logs to support efficient filtering by $.severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.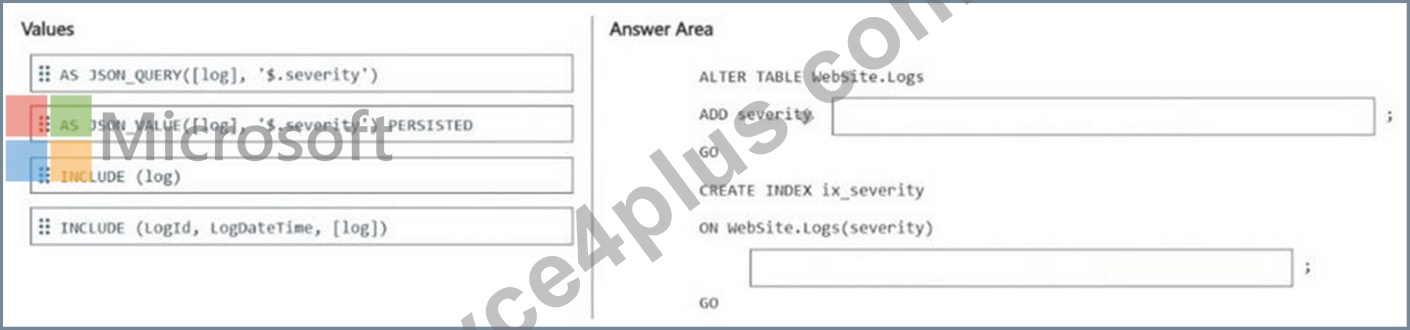
Answer:
Explanation: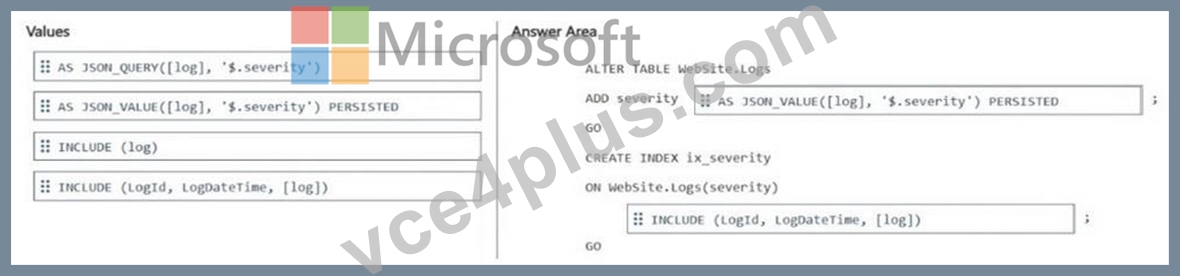
NEW QUESTION # 24
You have a SQL database in Microsoft Fabric that contains a nvarchar (max) column named MessageText. An ID is always contained within the first paragraph of MessageText.
You need to write a Transact-SQL query that uses REGEXP_SUBSTR to extract the ID from MessageText.
What should you include in the query?
Answer: B
Explanation:
To extract an ID (e.g., alphanumeric) from the first paragraph of an nvarchar(max) column in Microsoft Fabric using STRING_ESCAPE, use STRING_SPLIT or CHARINDEX to isolate the first paragraph, apply STRING_ESCAPE, and a regex pattern.
Note: T-SQL does not natively support a REGEXP_SUBSTR function like Oracle/Snowflake. The solution below uses STRING_ESCAPE followed by pattern matching via PATINDEX and SUBSTRING to extract a typical alphanumeric ID.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/queries/contains-transact-sql
NEW QUESTION # 25
Hotspot Question
You have a Microsoft Fabric workspace named Workspace1 that contains a SQL database named SalesDB and an API for GraphQL item named SalesApi.
You have a Microsoft Entra group named SqlUsers.
From Workspace1, you assign permission to SalesApi as shown in the following exhibit.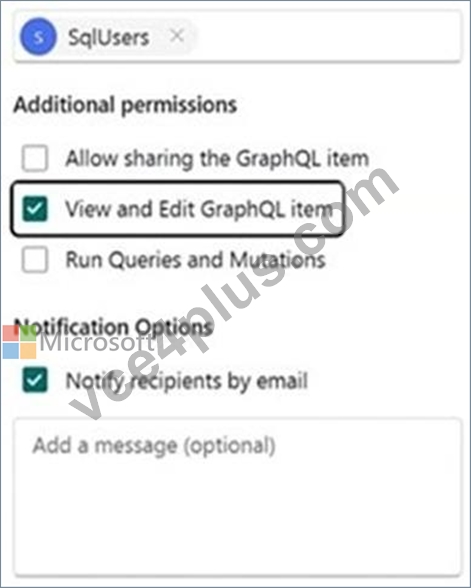
The connection to SalesDB has the connectivity option configured as shown in the following exhibit.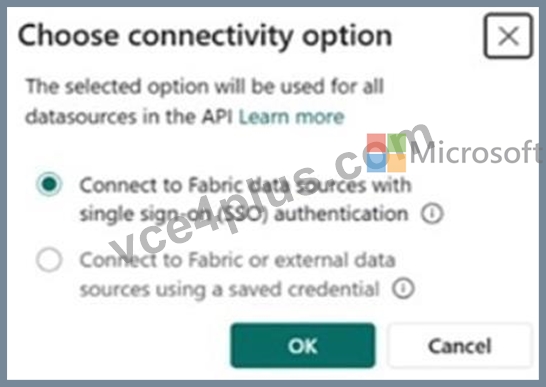
SqlUsers has the Viewer role for Workspace1.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.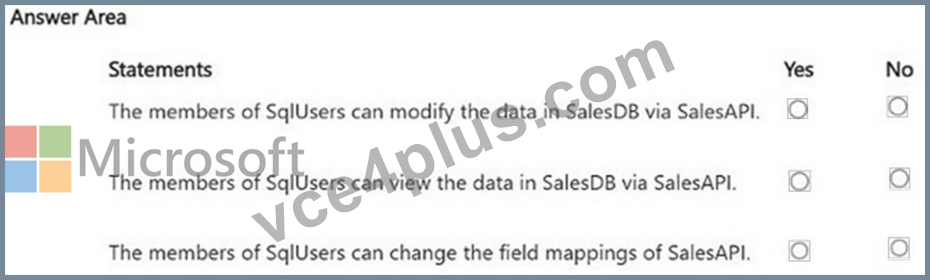
Answer:
Explanation: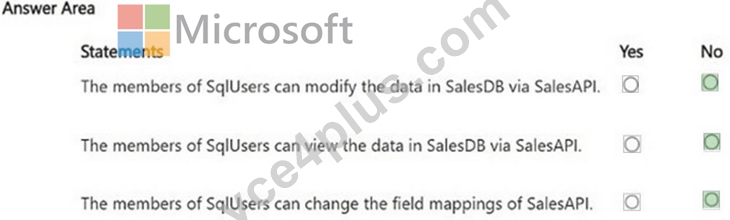
NEW QUESTION # 26
You have an Azure SQL database that contains a table named Table1. Table1 contains 25,000,000 rows of data and a datetime2 column named DateKey. The data in Table1 spans the years 2020 through 2021.
You need to partition the data in Table1 by year. The solution must minimize how long it takes to rebuild or reindex the table.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.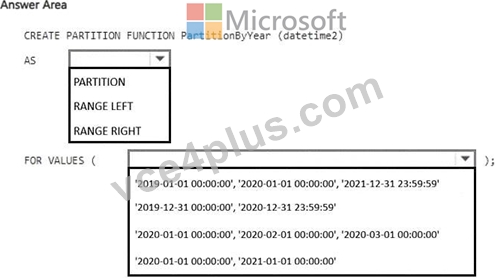
Answer:
Explanation: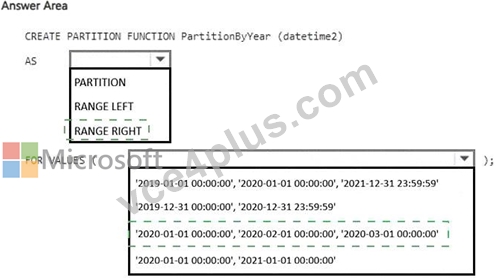
Explanation:
* Partition range # RANGE RIGHT
* Boundary values # ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is to use RANGE RIGHT with boundary values at the start of each year :
CREATE PARTITION FUNCTION PartitionByYear (datetime2)
AS RANGE RIGHT
FOR VALUES (
' 2020-01-01 00:00:00 ' ,
' 2021-01-01 00:00:00 '
);
Microsoft documents that with RANGE RIGHT , each boundary value belongs to the partition on its right .
For date-based partitioning, this is the natural pattern because a boundary such as 2021-01-01 becomes the lower boundary of the 2021 partition.
With these boundaries, the resulting ranges are effectively:
* Partition 1: dates before 2020-01-01
* Partition 2: 2020-01-01 through before 2021-01-01
* Partition 3: 2021-01-01 and later
This cleanly separates the 2020 and 2021 data into year-aligned partitions. Microsoft specifically recommends RANGE RIGHT for date-based boundaries because the first day of a period remains in the same partition as the rest of that period.
The other boundary choices are incorrect or less appropriate:
* Using year-end timestamps with RANGE LEFT is more cumbersome and can be sensitive to datetime2 precision.
* Monthly boundaries would partition by month, not year.
* Including 2019 and a 2021-12-31 23:59:59 boundary creates unnecessary partitions and is not the cleanest year-based design.
Therefore:
* First dropdown: RANGE RIGHT
* Second dropdown: ' 2020-01-01 00:00:00 ' , ' 2021-01-01 00:00:00 '
NEW QUESTION # 27
......
DP-800 Cost Effective Dumps: https://www.vce4plus.com/Microsoft/DP-800-valid-vce-dumps.html