BONUS!!! Download part of BraindumpsPrep Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1EwSJadkhcv-zMg0c-ReK6S0iIade5ei-
The BraindumpsPrep is on a mission to support its users by providing all the related and updated Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam questions to enable them to hold the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) certificate with prestige and distinction. What adds to the dominance of the BraindumpsPrep market is its promise to give its customers the latest Databricks-Generative-AI-Engineer-Associate Practice Exams. The hardworking and strenuous support team is always looking to refine the Databricks-Generative-AI-Engineer-Associate prep material and bring it to the level of excellence. It materializes this goal by taking responses from above 90,000 competitive professionals.
| Section | Weight | Objectives |
|---|---|---|
| Governance | 8% | - Apply safety filters and guidelines - Manage permissions and logging |
| Assembling and Deploying Apps | 22% | - Package and deploy models - Build and deploy RAG pipelines - Use Vector Search |
| Design Applications | 14% | - Define functional requirements - Design and architect applications - Select appropriate models |
| Application Development | 30% | - Integrate Databricks tools (LangChain, etc.) - Implement prompt engineering - Develop LLM chains |
| Data Preparation | 14% | - Manage data quality and chunking - Prepare data for RAG applications |
| Evaluation and Monitoring | 12% | - Monitor deployed applications - Evaluate model quality and performance |
>> Mock Databricks-Generative-AI-Engineer-Associate Exams <<
You don't need to worry about wasting your precious time but failing to get the Databricks-Generative-AI-Engineer-Associate certification. Many people have used our Databricks-Generative-AI-Engineer-Associate study materials and the pass rate of the exam is 99%. If any incident happens and you don't pass the Databricks-Generative-AI-Engineer-Associate exam, we will give you a full refund. Our sincerity stems are from the good quality of our products. We will give you one year's free update of the exam study materials you purchase and 24/7 online service. Now just make up your mind and get your Databricks-Generative-AI-Engineer-Associate Exam Torrent!
NEW QUESTION # 34
A Generative Al Engineer is deciding between using LSH (Locality Sensitive Hashing) and HNSW (Hierarchical Navigable Small World) for indexing their vector database Their top priority is semantic accuracy Which approach should the Generative Al Engineer use to evaluate these two techniques?
Answer: D
Explanation:
The task is to choose between LSH and HNSW for a vector database index, prioritizing semantic accuracy. The evaluation must assess how well each method retrieves semantically relevant results. Let's evaluate the options.
Option A: Compare the cosine similarities of the embeddings of returned results against those of a representative sample of test inputs Cosine similarity measures semantic closeness between vectors, directly assessing retrieval accuracy in a vector database. Comparing returned results' embeddings to test inputs' embeddings evaluates how well LSH or HNSW preserves semantic relationships, aligning with the priority.
Databricks Reference: "Cosine similarity is a standard metric for evaluating vector search accuracy" ("Databricks Vector Search Documentation," 2023).
Option B: Compare the Bilingual Evaluation Understudy (BLEU) scores of returned results for a representative sample of test inputs BLEU evaluates text generation (e.g., translations), not vector retrieval accuracy. It's irrelevant for indexing performance.
Databricks Reference: "BLEU applies to generative tasks, not retrieval" ("Generative AI Cookbook").
Option C: Compare the Recall-Oriented-Understudy for Gisting Evaluation (ROUGE) scores of returned results for a representative sample of test inputs ROUGE is for summarization evaluation, not vector search. It doesn't measure semantic accuracy in retrieval.
Databricks Reference: "ROUGE is unsuited for vector database evaluation" ("Building LLM Applications with Databricks").
Option D: Compare the Levenshtein distances of returned results against a representative sample of test inputs Levenshtein distance measures string edit distance, not semantic similarity in embeddings. It's inappropriate for vector-based retrieval.
Databricks Reference: No specific support for Levenshtein in vector search contexts.
Conclusion: Option A (cosine similarity) is the correct approach, directly evaluating semantic accuracy in vector retrieval, as recommended by Databricks for Vector Search assessments.
NEW QUESTION # 35
A Generative Al Engineer is working with a retail company that wants to enhance its customer experience by automatically handling common customer inquiries. They are working on an LLM-powered Al solution that should improve response times while maintaining a personalized interaction. They want to define the appropriate input and LLM task to do this.
Which input/output pair will do this?
Answer: D
Explanation:
The task described in the question involves enhancing customer experience by automatically handling common customer inquiries using an LLM-powered AI solution. This requires the system to process input data (customer inquiries) and generate personalized, relevant responses efficiently. Let's evaluate the options step-by-step in the context of Databricks Generative AI Engineer principles, which emphasize leveraging LLMs for tasks like question answering, summarization, and retrieval-augmented generation (RAG).
* Option A: Input: Customer reviews; Output: Group the reviews by users and aggregate per-user average rating, then respond
* This option focuses on analyzing customer reviews to compute average ratings per user. While this might be useful for sentiment analysis or user profiling, it does not directly address the goal of handling common customer inquiries or improving response times for personalized interactions. Customer reviews are typically feedback data, not real-time inquiries requiring immediate responses.
* Databricks Reference: Databricks documentation on LLMs (e.g., "Building LLM Applications with Databricks") emphasizes that LLMs excel at tasks like question answering and conversational responses, not just aggregation or statistical analysis of reviews.
* Option B: Input: Customer service chat logs; Output: Group the chat logs by users, followed by summarizing each user's interactions, then respond
* This option uses chat logs as input, which aligns with customer service scenarios. However, the output-grouping by users and summarizing interactions-focuses on user-specific summaries rather than directly addressing inquiries. While summarization is an LLM capability, this approach lacks the specificity of finding answers to common questions, which is central to the problem.
* Databricks Reference: Per Databricks' "Generative AI Cookbook," LLMs can summarize text, but for customer service, the emphasis is on retrieval and response generation (e.g., RAG workflows) rather than user interaction summaries alone.
* Option C: Input: Customer service chat logs; Output: Find the answers to similar questions and respond with a summary
* This option uses chat logs (real customer inquiries) as input and tasks the LLM with identifying answers to similar questions, then providing a summarized response. This directly aligns with the goal of handling common inquiries efficiently while maintaining personalization (by referencing past interactions or similar cases). It leverages LLM capabilities like semantic search, retrieval, and response generation, which are core to Databricks' LLM workflows.
* Databricks Reference: From Databricks documentation ("Building LLM-Powered Applications," 2023), an exact extract states:"For customer support use cases, LLMs can be used to retrieve relevant answers from historical data like chat logs and generate concise, contextually appropriate responses."This matches Option C's approach of finding answers and summarizing them.
* Option D: Input: Customer reviews; Output: Classify review sentiment
* This option focuses on sentiment classification of reviews, which is a valid LLM task but unrelated to handling customer inquiries or improving response times in a conversational context.
It's more suited for feedback analysis than real-time customer service.
* Databricks Reference: Databricks' "Generative AI Engineer Guide" notes that sentiment analysis is a common LLM task, but it's not highlighted for real-time conversational applications like customer support.
Conclusion: Option C is the best fit because it uses relevant input (chat logs) and defines an LLM task (finding answers and summarizing) that meets the requirements of improving response times and maintaining personalized interaction. This aligns with Databricks' recommended practices for LLM-powered customer service solutions, such as retrieval-augmented generation (RAG) workflows.
NEW QUESTION # 36
A Generative AI Engineer I using the code below to test setting up a vector store: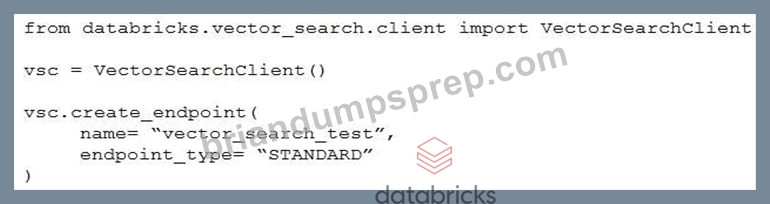
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: D
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 37
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: D
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using a neutralizer to normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
Neutralizing Underlying Documents:
A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with a specific tone and style (like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
Why Other Options Improve Results:
A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) is not an effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 38
A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.
Which action should they take to elicit the desired behavior from this LLM?
Answer: A
Explanation:
The LLM classifies mushroom species accurately but includes unwanted reasoning text, and the engineer wants only the label. Let's assess how to control output format effectively.
Option A: Use few shot prompting to instruct the model on expected output format Few-shot prompting provides examples (e.g., input: description, output: label). It can work but requires crafting multiple examples, which is effort-intensive and less direct than a clear instruction.
Databricks Reference: "Few-shot prompting guides LLMs via examples, effective for format control but requires careful design" ("Generative AI Cookbook").
Option B: Use zero shot prompting to instruct the model on expected output format Zero-shot prompting relies on a single instruction (e.g., "Return only the label") without examples. It's simpler than few-shot but may not consistently enforce succinctness if the LLM's default behavior is verbose.
Databricks Reference: "Zero-shot prompting can specify output but may lack precision without examples" ("Building LLM Applications with Databricks").
Option C: Use zero shot chain-of-thought prompting to prevent a verbose output format Chain-of-Thought (CoT) encourages step-by-step reasoning, which increases verbosity-opposite to the desired outcome. This contradicts the goal of label-only output.
Databricks Reference: "CoT prompting enhances reasoning but often results in detailed responses" ("Databricks Generative AI Engineer Guide").
Option D: Use a system prompt to instruct the model to be succinct in its answer A system prompt (e.g., "Respond with only the species label, no additional text") sets a global instruction for the LLM's behavior. It's direct, reusable, and effective for controlling output style across queries.
Databricks Reference: "System prompts define LLM behavior consistently, ideal for enforcing concise outputs" ("Generative AI Cookbook," 2023).
Conclusion: Option D is the most effective and straightforward action, using a system prompt to enforce succinct, label-only responses, aligning with Databricks' best practices for output control.
NEW QUESTION # 39
......
365 days free upgrades are provided by Databricks Databricks-Generative-AI-Engineer-Associate exam dumps you purchased change. To avoid confusion, get the Databricks Databricks-Generative-AI-Engineer-Associate practice exam and start studying. To guarantee success on the first try, subject matter experts have created all of the Databricks Databricks-Generative-AI-Engineer-Associate Exam Material.
Databricks-Generative-AI-Engineer-Associate Valid Braindumps Book: https://www.briandumpsprep.com/Databricks-Generative-AI-Engineer-Associate-prep-exam-braindumps.html
BONUS!!! Download part of BraindumpsPrep Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1EwSJadkhcv-zMg0c-ReK6S0iIade5ei-