AI-500 is an Microsoft certification exam, so AI-500 is the first step to set foot on the road of Microsoft certification. AI-500 certification exam become more and more fiery and more and more people participate in AI-500 Exam, but passing rate of AI-500 certification exam is not very high.When you select AI-500 exam, do you want to choose an exam training courses?
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 3: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 4: Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
>> AI-500 Valid Exam Bootcamp <<
The AI-500 practice questions offered by PassTestking is the latest and valid AI-500 study material which suitable for all of you. Our free demo is especially for you to free download for try before you buy. Improve your professional ability with our AI-500 certification. Getting qualified by the certification will position you for better job opportunities and higher salary. Now, let’s start your preparation with our AI-500 Training Material. You can get a lot from the simulate AI-500 exam guide and get your certification easily.
NEW QUESTION # 68
You have a Microsoft Foundry Agent Sen/ice solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and set scope for each memory search tool to
{{Suserld}} Does this meet the goal?
Answer: B
Explanation:
A dedicated memory store for each agent establishes agent-domain isolation. Setting each memory search tool
' s scope to the current user identity establishes the second isolation dimension: users within the same agent domain receive separate logical memory collections. Microsoft Foundry Memory documents `scope` as the partitioning mechanism and specifically supports `{{$userId}}` for automatic per-user isolation. Memory associated with one scope can be deleted without removing memories stored under other scopes, which satisfies the deletion requirement. The source text renders the token imperfectly as `{{Suserld}}`; the current documented syntax is `{{$userId}}`. Interpreting the question as the documented user-scope token, the design satisfies domain isolation, user isolation, and per-user deletion. Therefore A, Yes, is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 69
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator agent that sends a mix of simple requests, reasoning-heavy tasks, and tool-calling workflows to a single premium model deployment.
Response quality is acceptable, but costs are too high, and latency varies significantly across requests.
You need to recommend a solution to reduce token utilization based on the complexity of the user input.
What should you include in the recommendation?
Answer: A
Explanation:
The workload mixes simple prompts, reasoning-heavy tasks, and tool-calling workflows, so a single premium model is over-provisioned for many requests. Microsoft Foundry ' s model router evaluates request complexity and routes each request to an appropriate model from a configured pool. Simple work can use lower-cost, lower-latency models, while complex reasoning can still be assigned to a more capable model.
Structured outputs constrain response format but do not reduce model capability according to request complexity. Prompt Optimizer can improve prompt quality but does not perform per-request model selection, and choosing another flagship model would preserve the same all-requests-use-premium pattern. Therefore A directly addresses the cost and latency variability by matching model capacity to workload complexity. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - Model router
NEW QUESTION # 70
You have a multitenant platform that uses Microsoft Foundry agents. The agents use conversation-based history for active turns, and the platform runs on multiple stateless container instances. Each tenant has a different transcript retention period, and users expect preferences from previous conversations to influence future sessions.
You need to persist cross-session memory after a service conversation is deleted The solution must meet the following requirements:
* Apply tenant-specific retention to transcript exports.
* Keep the compute tier stateless during scale-out.
* Minimize operational complexity
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.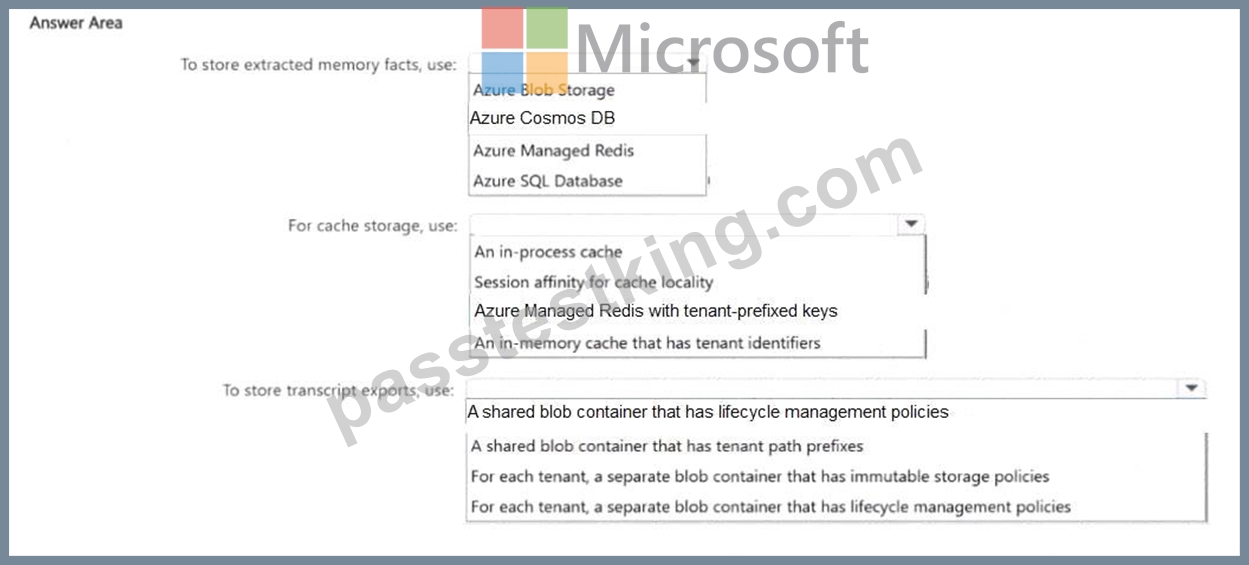
Answer:
Explanation: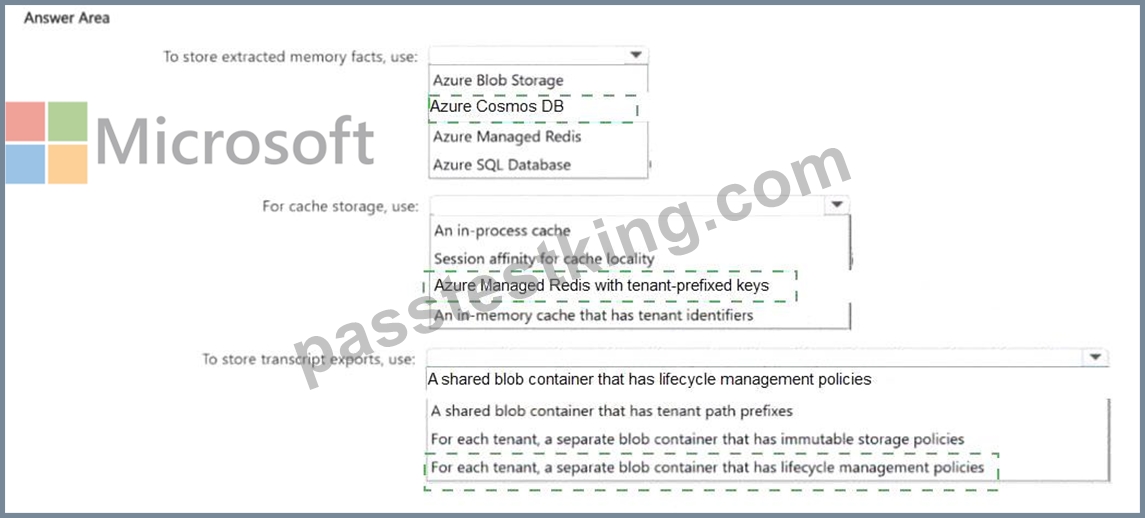
Explanation:
Extracted memory facts: Azure Cosmos DB; Cache: Azure Managed Redis with tenant-prefixed keys; Transcript exports: A shared blob container with lifecycle management policies.
The design separates durable memory, distributed cache, and retained transcripts. Azure Cosmos DB is appropriate for durable extracted facts that must survive deletion of a service conversation and remain available across stateless compute instances. Azure Managed Redis provides a shared low-latency cache; tenant-prefixed keys are a standard multitenant pattern that avoids local-process affinity. Transcript exports belong in Blob Storage, where lifecycle management rules can enforce retention and can be filtered by prefixes or tags so different tenant retention policies can coexist in one managed storage design. This combination keeps the compute tier stateless while avoiding unnecessary per-tenant infrastructure. The important security requirement is that every persistence layer also enforce tenant authorization, not just naming conventions. Within the options provided, the stated combination minimizes operational complexity while meeting cross-session persistence and retention needs. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure Architecture Center - multitenant data and cache patterns
NEW QUESTION # 71
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: B
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 72
You are validating the outcome of the consultant proposal for the Patient Intake agent.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.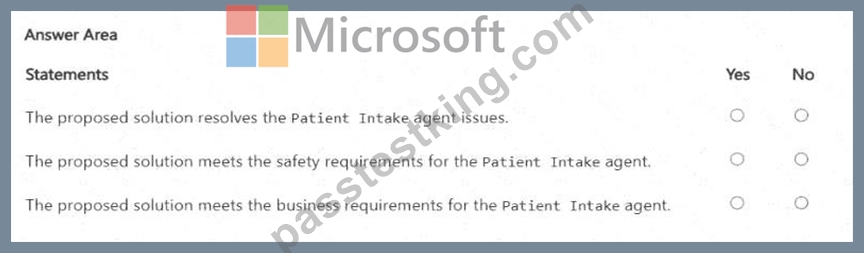
Answer:
Explanation: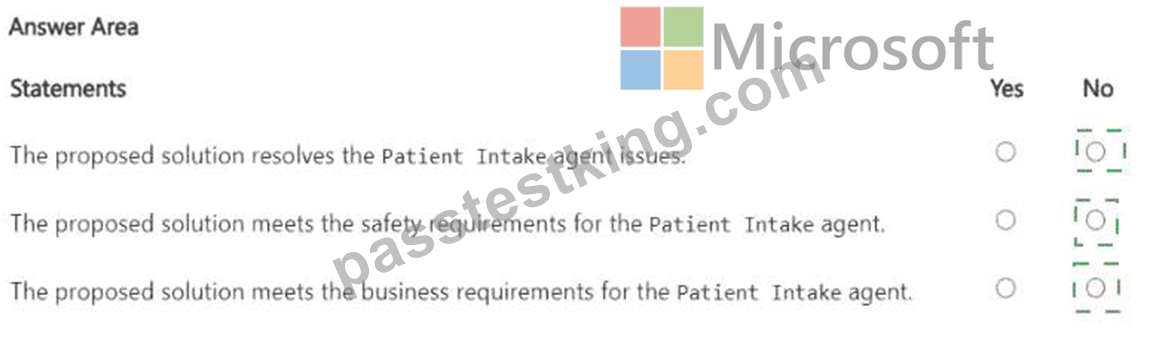
Explanation:
No / No / No
All three consultant-proposal statements should be rejected. Applying the highest sensitivity to every guardrail control is not automatically safer because it can increase false positives and unnecessarily block legitimate clinical interactions; controls should be tuned to the actual risk and tested. Telling the model in a system prompt to ignore hate speech is not equivalent to enabling the platform content-safety controls required for public-facing agents. Finally, repeatedly prompting patients to verify symptoms does not address long-context growth and can worsen token usage and latency. Microsoft guidance separates deterministic safety controls, evaluation, and context-management mechanisms from ordinary prompt instructions. The proposal also hardcodes medical behavior in prompts, contrary to the requirement to avoid embedding new clinical logic in the core prompt. A robust design would use appropriate content-safety/guardrail controls, validated intervention points, and a deliberate memory/compaction strategy rather than relying on increasingly restrictive or repetitive prompt text. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: AI-500 Study Guide - guardrails, context management, and evaluation
NEW QUESTION # 73
......
If you buy and use the AI-500 study materials from our company, you can complete the practice tests in a timed environment, receive grades and review test answers via video tutorials. You just need to download the software version of our AI-500 Study Materials after you buy our study materials. You will have the right to start to try to simulate the real examination. We believe that the AI-500 study materials from our company will not let you down.
AI-500 Valid Vce Dumps: https://www.passtestking.com/Microsoft/AI-500-practice-exam-dumps.html