New Soft Databricks-Certified-Data-Engineer-Professional Simulations - Databricks-Certified-Data-Engineer-Professional Valid Exam Experience

With our excellent Databricks-Certified-Data-Engineer-Professional exam questions, you can get the best chance to obtain the Databricks-Certified-Data-Engineer-Professional certification to improve yourself, for better you and the better future. With our Databricks-Certified-Data-Engineer-Professional training guide, you are acknowledged in your profession. The Databricks-Certified-Data-Engineer-Professional exam braindumps can prove your ability to let more big company to attention you. Then you have more choice to get a better job and going to suitable workplace. Why not have a try on our Databricks-Certified-Data-Engineer-Professional Exam Questions, you will be pleasantly surprised our Databricks-Certified-Data-Engineer-Professional exam questions are the best praparation material.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Governance | 7% | - Enforce data policies and standards
- Use Unity Catalog for governance
- Manage data assets and metadata
|
| Topic 2: Monitoring and Alerting | 10% | - Set up alerts and notifications
- Monitor pipeline performance and health
- Track data lineage and metrics
|
| Topic 3: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Apply data cleansing and validation rules
- Implement schema evolution and management
|
| Topic 4: Cost & Performance Optimisation | 13% | - Apply cost management best practices
- Improve query and pipeline performance
- Optimize compute and storage resources
|
| Topic 5: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources
- Use Auto Loader and structured streaming
- Handle incremental and batch data loads
|
| Topic 6: Data Sharing and Federation | 5% | - Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
- Manage cross-platform data access
|
| Topic 7: Data Modelling | 6% | - Design Medallion Architecture
- Implement dimensional and relational models
- Optimize table design and partitioning
|
| Topic 8: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
- Implement complex data processing logic
|
| Topic 9: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines
- Deploy using Asset Bundles, CLI, and APIs
- Implement CI/CD and DevOps practices
|
| Topic 10: Ensuring Data Security and Compliance | 10% | - Implement access control and permissions
- Secure data at rest and in transit
- Ensure data privacy and compliance
|
>> New Soft Databricks-Certified-Data-Engineer-Professional Simulations <<
Precious Databricks Certified Data Engineer Professional Exam Guide Dumps Will be Your Best Choice - Itcerttest
Databricks-Certified-Data-Engineer-Professional test guide is not only the passbooks for students passing all kinds of professional examinations, but also the professional tools for students to review examinations. In the past few years, Databricks-Certified-Data-Engineer-Professional question torrent has received the trust of a large number of students and also helped a large number of students passed the exam smoothly. That is to say, there is absolutely no mistake in choosing our Databricks-Certified-Data-Engineer-Professional Test Guide to prepare your exam, you will pass your exam in first try and achieve your dream soon.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q28-Q33):
NEW QUESTION # 28
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Use merge into to insert, update, or delete the most recent entry for each pk_id into a bronze table, then propagate all changes throughout the system.
- B. Ingest all log information into a bronze table; use merge into to insert, update, or delete the most recent entry for each pk_id into a silver table to recreate the current table state.
- C. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- D. Create a separate history table for each pk_id resolve the current state of the table by running a Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from union all filtering the history tables for the most recent state.
- E. Iterate through an ordered set of changes to the table, applying each in turn; rely on Delta Lake's versioning ability to create an audit log.
Answer: B
Explanation:
CDF captures changes only from a Delta table and is only forward-looking once enabled. The CDC logs are writing to object storage. So you would need to ingestion those and merge into downstream tables.
NEW QUESTION # 29
A view is registered with the following code:
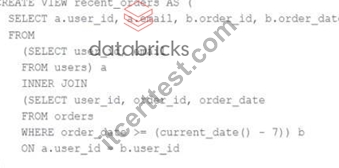
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- C. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
Answer: D
NEW QUESTION # 30
The data engineering team maintains the following code:
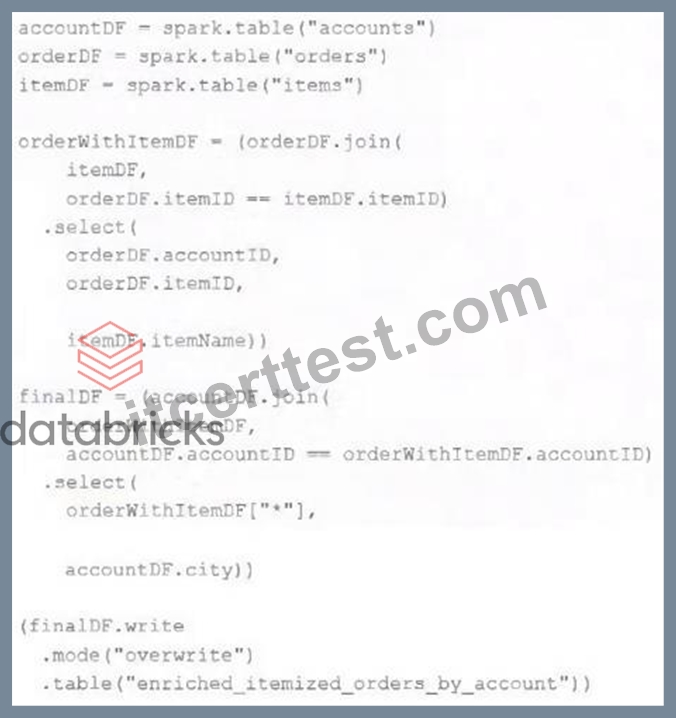
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- B. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- C. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- D. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- E. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
Answer: A
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 31
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
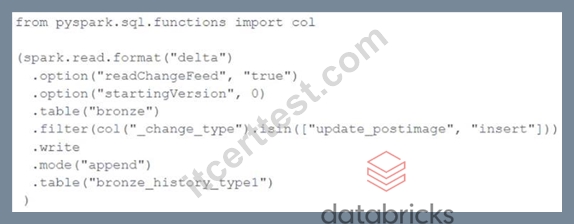
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- B. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- C. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- D. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- E. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
Answer: E
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 32
A company stores account transactions in a Delta Lake table. The company needs to apply frequent account-level correlations (e.g., UPDATE statements) but wants to avoid rewriting entire Parquet files for each change to reduce file churn and improve write performance. Which Delta Lake feature should they enable?
- A. Enable deletion vectors on the Delta table
- B. Partition the Delta table by account_id
- C. Enable automatic file compaction on writes
- D. Enable change data feed on the Delta table
Answer: A
Explanation:
Deletion vectors allow Delta Lake to track row-level deletes and updates without rewriting entire Parquet files. By recording changes separately from the base files, this feature significantly reduces file churn and improves write performance for workloads with frequent row-level modifications such as account-level updates.
NEW QUESTION # 33
......
Databricks Databricks-Certified-Data-Engineer-Professional study guide offer you free demo to have a try before buying, so that you can have a better understanding of what you are going to buy. Free update for one year is also available, and in this way, you can get the latest information for the exam during your preparation. The update version for Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional Exam Dumps will be sent to your email address automatically.
Databricks-Certified-Data-Engineer-Professional Valid Exam Experience: https://www.itcerttest.com/Databricks-Certified-Data-Engineer-Professional_braindumps.html
- Fantastic New Soft Databricks-Certified-Data-Engineer-Professional Simulations – Find Shortcut to Pass Databricks-Certified-Data-Engineer-Professional Exam 😤 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 and download exam materials for free through “ www.dumpsmaterials.com ” 🕚Databricks-Certified-Data-Engineer-Professional New Braindumps Questions
- Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims ⛅ Databricks-Certified-Data-Engineer-Professional Reliable Exam Review 🐡 Databricks-Certified-Data-Engineer-Professional Key Concepts 🌔 Search for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ on ⇛ www.pdfvce.com ⇚ immediately to obtain a free download 😩Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims
- Use Databricks Certified Data Engineer Professional Exam sure pass guide dumps to pass Databricks Certified Data Engineer Professional Exam actual test 👣 Copy URL ▷ www.torrentvce.com ◁ open and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 🤴Databricks-Certified-Data-Engineer-Professional Certification Test Answers
- Choosing New Soft Databricks-Certified-Data-Engineer-Professional Simulations - Get Rid Of Databricks Certified Data Engineer Professional Exam 💥 Enter ⏩ www.pdfvce.com ⏪ and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to download for free 🗺Databricks-Certified-Data-Engineer-Professional Valid Exam Materials
- 100% Pass Quiz Databricks-Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Exam Pass-Sure New Soft Simulations 🐕 Download ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free by simply entering ▷ www.practicevce.com ◁ website 🍺Databricks-Certified-Data-Engineer-Professional Answers Real Questions
- Databricks-Certified-Data-Engineer-Professional Exam Experience 🐧 Databricks-Certified-Data-Engineer-Professional Valid Test Format 🕜 Databricks-Certified-Data-Engineer-Professional Valid Exam Materials 🚝 ▷ www.pdfvce.com ◁ is best website to obtain ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download 💓Reliable Databricks-Certified-Data-Engineer-Professional Test Forum
- Reliable Databricks-Certified-Data-Engineer-Professional Exam Vce 🧄 Test Databricks-Certified-Data-Engineer-Professional Engine 🦮 Databricks-Certified-Data-Engineer-Professional Test Vce Free 🎻 Search for { Databricks-Certified-Data-Engineer-Professional } on ✔ www.prepawaypdf.com ️✔️ immediately to obtain a free download 🏄Databricks-Certified-Data-Engineer-Professional Exam Preparation
- Key Features of Pdfvce Databricks Databricks-Certified-Data-Engineer-Professional Practice Material for Exam Preparation 🟫 Open 《 www.pdfvce.com 》 enter ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and obtain a free download 🌄Exam Databricks-Certified-Data-Engineer-Professional Vce
- Key Features of www.vce4dumps.com Databricks Databricks-Certified-Data-Engineer-Professional Practice Material for Exam Preparation 🚨 Search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ and easily obtain a free download on { www.vce4dumps.com } 🍉Databricks-Certified-Data-Engineer-Professional Reliable Exam Sims
- Download Databricks-Certified-Data-Engineer-Professional Real Dumps and Start This Journey 🤲 Download { Databricks-Certified-Data-Engineer-Professional } for free by simply entering ✔ www.pdfvce.com ️✔️ website 🏰Databricks-Certified-Data-Engineer-Professional Instant Access
- Use Databricks Certified Data Engineer Professional Exam sure pass guide dumps to pass Databricks Certified Data Engineer Professional Exam actual test 🌐 Open ➥ www.prepawayexam.com 🡄 enter 「 Databricks-Certified-Data-Engineer-Professional 」 and obtain a free download 🎫Databricks-Certified-Data-Engineer-Professional Valid Exam Materials
- www.stes.tyc.edu.tw, www.impactio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, fortunetelleroracle.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes