BONUS!!! Download part of PDFDumps Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=1xpCFiqgMve-Nr9gwWYbVBkyplorzzkwq
You have the option to change the topic and set the time according to the actual Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam. The Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) practice questions give you a feeling of a real exam which boost confidence. Practice under real Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam situations is an excellent way to learn more about the complexity of the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam dumps.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Available Languages: | Japanese, English, Korean, Portuguese (Brazil) |
| Exam Format: | Multiple Choice, Multiple Select |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Real Exam Qty: | 45 |
| Exam Price: | $200 USD |
| Passing Score: | Scaled Score (approx. 70%) |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 2 years |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> New Databricks-Generative-AI-Engineer-Associate Test Review <<
Our company has built the culture of integrity from our establishment. You just need to pay the relevant money for the Databricks-Generative-AI-Engineer-Associate practice materials. Our system will never deduct extra money from your debit cards. Also, your payment information of the Databricks-Generative-AI-Engineer-Associate Study Materials will be secret. No one will crack your passwords. Our payment system will automatically delete your payment information once you finish paying money for our Databricks-Generative-AI-Engineer-Associate exam questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 83
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Answer: B
Explanation:
Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
Explanation of Options:
Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON. This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs, Option B is the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
NEW QUESTION # 84
A Generative Al Engineer is deciding between using LSH (Locality Sensitive Hashing) and HNSW (Hierarchical Navigable Small World) for indexing their vector database Their top priority is semantic accuracy Which approach should the Generative Al Engineer use to evaluate these two techniques?
Answer: A
Explanation:
The task is to choose between LSH and HNSW for a vector database index, prioritizing semantic accuracy.
The evaluation must assess how well each method retrieves semantically relevant results. Let's evaluate the options.
* Option A: Compare the cosine similarities of the embeddings of returned results against those of a representative sample of test inputs
* Cosine similarity measures semantic closeness between vectors, directly assessing retrieval accuracy in a vector database. Comparing returned results' embeddings to test inputs' embeddings evaluates how well LSH or HNSW preserves semantic relationships, aligning with the priority.
* Databricks Reference:"Cosine similarity is a standard metric for evaluating vector search accuracy"("Databricks Vector Search Documentation," 2023).
* Option B: Compare the Bilingual Evaluation Understudy (BLEU) scores of returned results for a representative sample of test inputs
* BLEU evaluates text generation (e.g., translations), not vector retrieval accuracy. It's irrelevant for indexing performance.
* Databricks Reference:"BLEU applies to generative tasks, not retrieval"("Generative AI Cookbook").
* Option C: Compare the Recall-Oriented-Understudy for Gisting Evaluation (ROUGE) scores of returned results for a representative sample of test inputs
* ROUGE is for summarization evaluation, not vector search. It doesn't measure semantic accuracy in retrieval.
* Databricks Reference:"ROUGE is unsuited for vector database evaluation"("Building LLM Applications with Databricks").
* Option D: Compare the Levenshtein distances of returned results against a representative sample of test inputs
* Levenshtein distance measures string edit distance, not semantic similarity in embeddings. It's inappropriate for vector-based retrieval.
* Databricks Reference: No specific support for Levenshtein in vector search contexts.
Conclusion: Option A (cosine similarity) is the correct approach, directly evaluating semantic accuracy in vector retrieval, as recommended by Databricks for Vector Search assessments.
NEW QUESTION # 85
A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.
Which method should the engineer use to achieve this integration?
Answer: C
Explanation:
A Delta Sync index with managed embeddings supports the workflow described. The engineer identifies the source text column and configures the embedding model endpoint. Databricks computes embeddings as part of synchronization and maintains the corresponding searchable index. This removes the requirement to calculate vectors independently and write them into the source table before indexing. With self-managed embeddings, the application or upstream pipeline must already provide the embedding vectors. A Direct Vector Access index requires explicit updates through an API or SDK and does not automatically synchronize with the source Delta table. "Hybrid embedding computing" is not the relevant index configuration; hybrid search combines retrieval techniques. Managed embeddings and Delta synchronization therefore address both automatic vector generation and source-data integration. Databricks documentation
NEW QUESTION # 86
A Generative AI Engineer has been reviewing issues with their company's LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
Answer: B
Explanation:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity. Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to "identify the legal jurisdiction," followed by a step to "extract relevant statutes," and finally a step to "summarize the findings." This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output. It also allows for intermediate validation and error handling between steps, which is impossible in a single-call architecture.
NEW QUESTION # 87
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: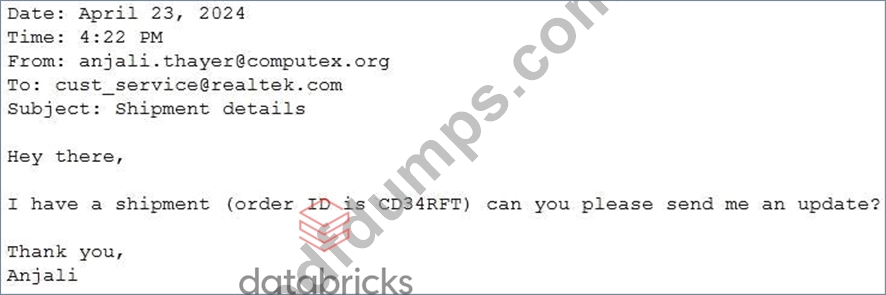
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: A
Explanation:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 88
......
Databricks-Generative-AI-Engineer-Associate Pdf Free: https://www.pdfdumps.com/Databricks-Generative-AI-Engineer-Associate-valid-exam.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1xpCFiqgMve-Nr9gwWYbVBkyplorzzkwq