Haben Sie an der Microsoft DP-750 Zertifizierungsprüfung teilgenommen? Was kann ich machen, wenn ich die Prüfung ablege, daran ich nicht selbstbewusst bin? Gibt es Abkürzung für die DP-750 Prüfung? Es gibt nicht genug Zeit, die Bücher auswendig zu lernen. Sind Sie der ähnlichen Meinungen? Wenn ja, kümmern Sie sich nicht darum, weil Sie immer noch die Chance haben diese DP-750 Prüfung gut vorzubereiten, obwohl die Prüfungszeit vor Ihnen schnell auftaucht? Wie kann ich diese Chance finden? Das ist die Microsoft DP-750 Dumps von Fast2test. Es gibt hocheffektive Prüfungsunterlagen zur Zertifizierung. Es kann Ihnen helfen, in kurzer Zeit die Prüfungsfragen vorzubereiten. Die Hitz-Rate dieser dumps sind sehr hoch. Deshalb können Sie Microsoft DP-750 Zertifizierungsprüfung bestehen, wenn Sie die Prüfungsfragen und -antworten gut lernen.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
Wollen Sie Ihre Fähigkeit beim Lernen der Microsoft DP-750 Zertifzierungsunterlagen verbessern und sich von anderen besser anerkannt? Microsoft Prüfungen helfen Ihnen, Ihre Fähigkeit zu verbessern. Wenn Sie die DP-750 Zertifizierung besitzen, können Sie Ihre Arbeit besser erledigen. Obwohl die DP-750 Prüfung sehr schwierig ist, können Sie sich nicht um die Vorbereitung der Prüfung sorgen. Nach der Nutzung der Fast2test DP-750 Dumps können Sie die Microsoft DP-750 Prüfung zu bestehen und auch die entsprechenden Kenntnisse beherrschen.
37. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.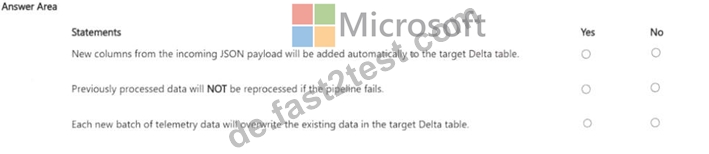
Antwort:
Begründung: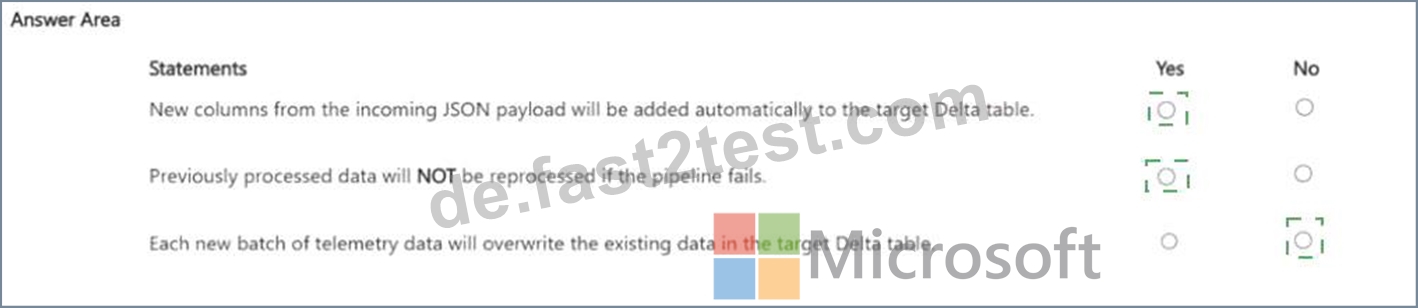
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
38. Frage
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
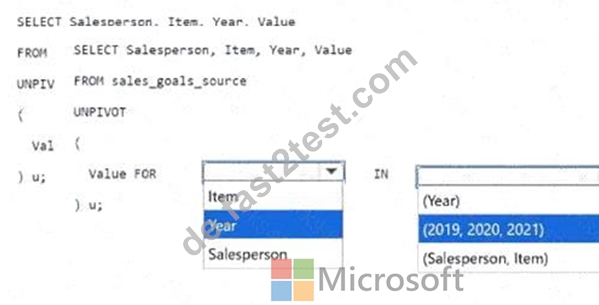
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Antwort:
Begründung: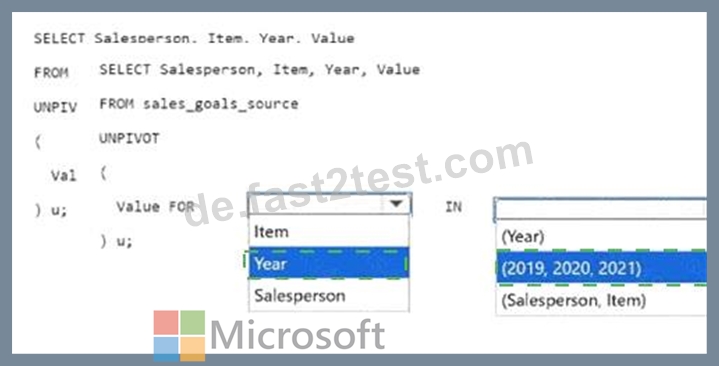
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
39. Frage
You have an Azure Databticks workspace that contains an all-purpose compute cluster named Cluster1.
Cluser1 is used for
interactive development.
You need to configure Cluster1 to meet the following requirements:
* Automatically add and remove worker nodes based on workload demand
* Automatically shut down when the cluster has been idle for a specific period.
What should you configure for each requirement? To answer, drag the appropriate options to the correct requirements. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.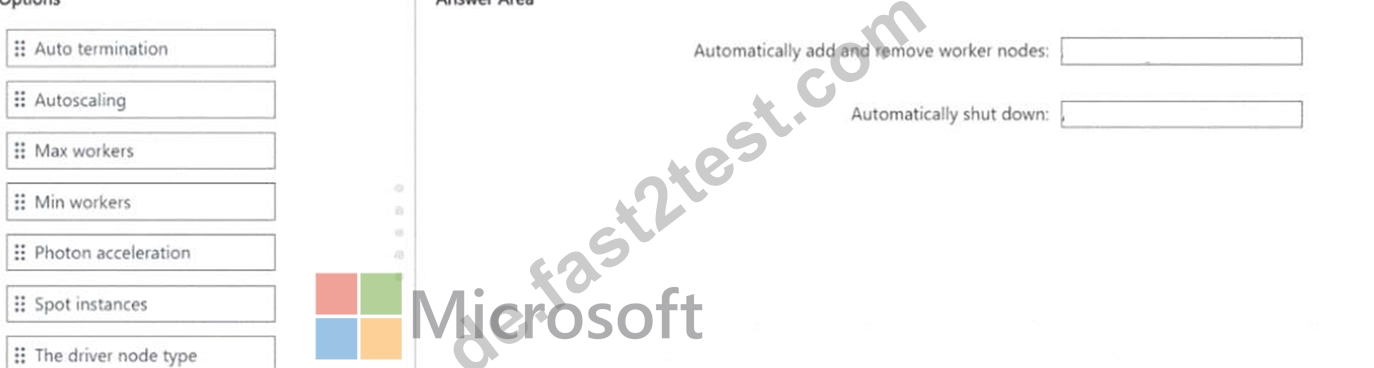
Antwort:
Begründung: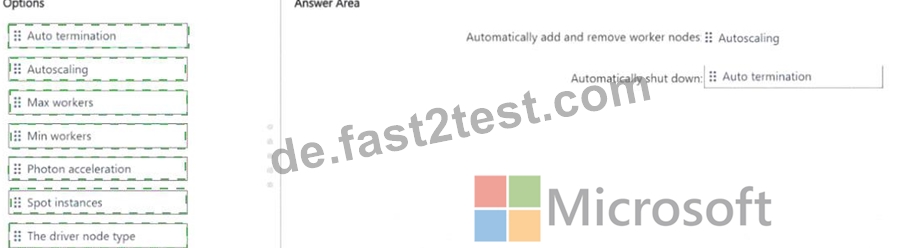
Explanation:
Two separate cluster settings address the two requirements:
Autoscaling handles the first requirement - dynamically adding workers when the workload is heavy and removing them when it lightens. You set a minimum and maximum node count, and Databricks adjusts the cluster size between those bounds based on task queue depth.
Auto-termination handles the second - the cluster shuts itself down after a configurable idle period (e.g., 30 minutes with no active queries), preventing wasted spend on a development cluster left running overnight.
These two settings are independent and complementary: autoscaling manages horizontal elasticity during active use, while auto-termination manages complete shutdown during inactivity. Both are configured in the cluster creation UI under the Compute section.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
40. Frage
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.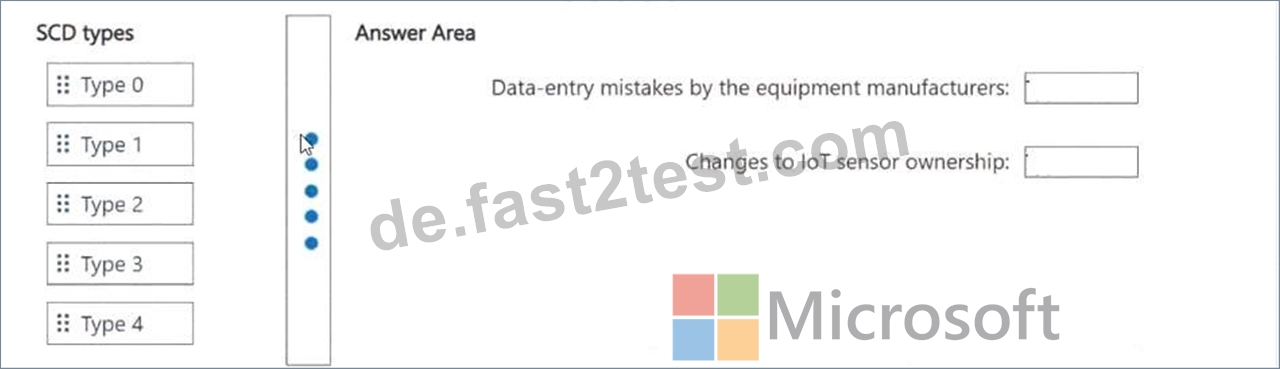
Antwort:
Begründung: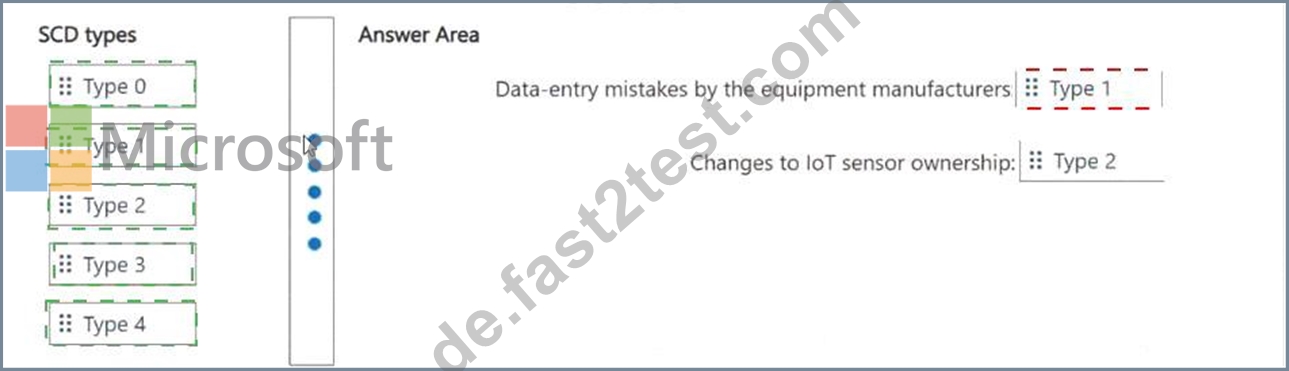
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
41. Frage
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.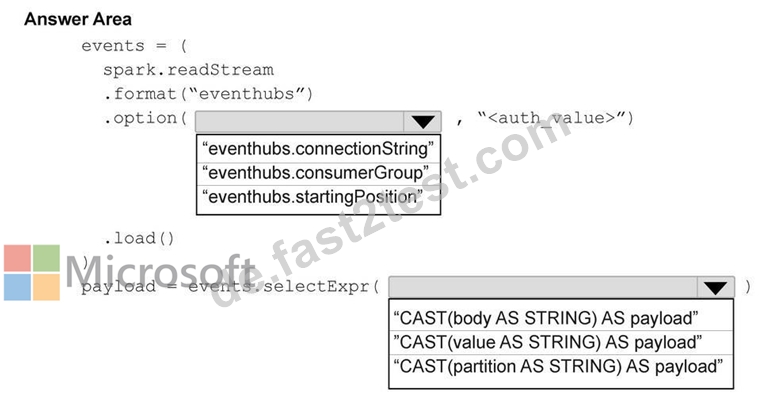
Antwort:
Begründung: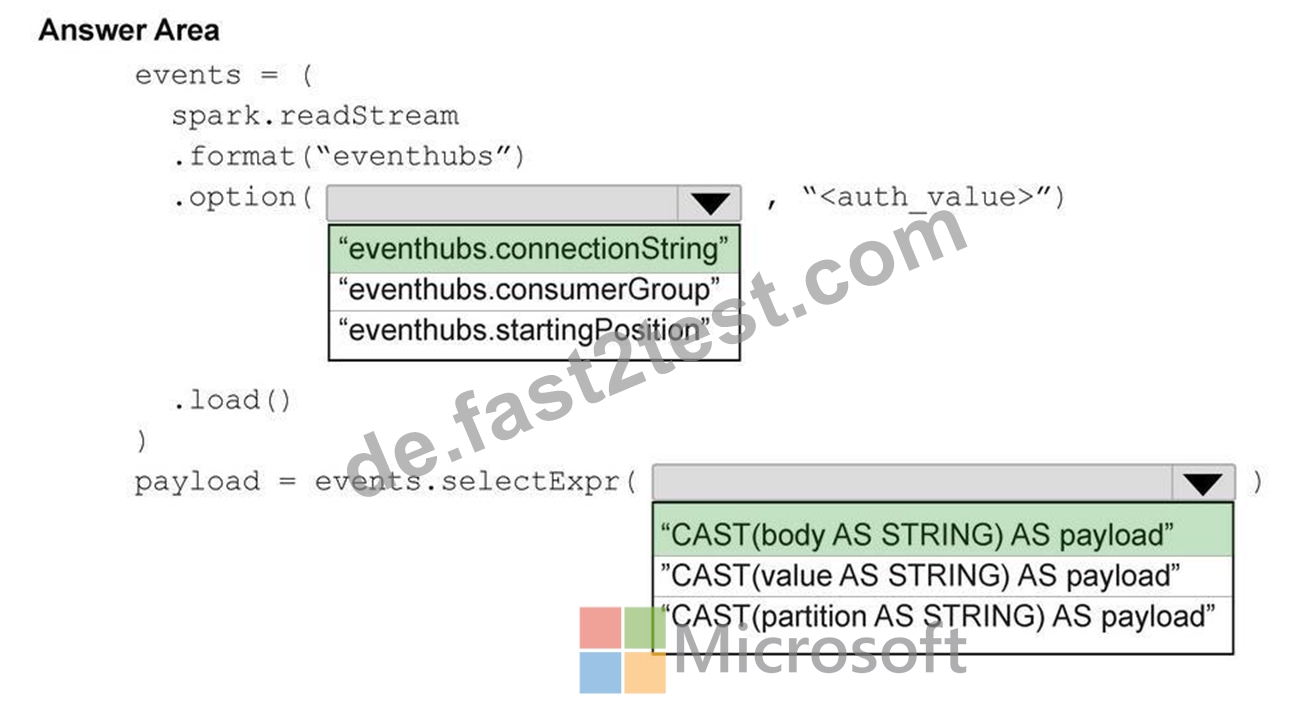
42. Frage
......
Niemand will ein ganz ein leichtes Leben führen und in einer niedrigen Position weniges Gehalt beziehen. Eines Tages wird man vielleicht gekündigt oder in die Rente treten. Dieses Leben ist wirklich langweilig. Wollen Sie nicht ein vielfältiges Leben führen? Das macht nichts. Heute sage ich Ihnen eine Abkürzung zum Erfolg, nämlich, die Microsoft DP-750 Zertifizierungsprüfung zu bestehen. Mit dem Zertifikat können Sie ein besseres Leben führen und ein exzellenter IT-Expert werden und von anderen akzeptiert werden. Die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von Fast2test können ganz leicht Ihren Traum verwirklichen. Zögern Sie noch? Schicken Sie doch schnell Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von Fast2test in den Warenkorb.
DP-750 Trainingsunterlagen: https://de.fast2test.com/DP-750-premium-file.html