자신을 부단히 업그레이드하려면 많은 노력이 필요합니다. IT업종 종사자라면 국제승인 IT인증자격증을 취득하는것이 자신을 업그레이드하는것과 같습니다. Nutanix인증 NCP-BC-7.5시험을 패스하여 원하는 자격증을 취득하려면ITDumpsKR의Nutanix인증 NCP-BC-7.5덤프를 추천해드립니다. 하루빨리 덤프를 공부하여 자격증 부자가 되세요.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Test BCDR Solutions | 25% | - Verify site connectivity and replication throughput - Perform disaster recovery validation procedures - Validate recovery plan execution and outcomes - Execute planned, unplanned, and test failovers |
| Topic 2: Perform BCDR Operational Tasks | 25% | - Self-service restore operations - Post-failover cleanup and re-protection - Migrate legacy protection domains to modern policies - Execute failover and failback workflows - Snapshot-based VM and volume recovery |
| Topic 3: Troubleshoot BCDR Failures | 20% | - Fix third-party backup integration problems - Diagnose network-related replication failures - Troubleshoot replication and protection policy issues - Resolve misconfigurations in DR environments - Resolve storage and snapshot errors |
| Topic 4: Interpret and Configure BCDR Requirements | 30% | - Create and configure recovery plans - Design secure BCDR environments: segmentation, RBAC, approval policies - Select replication types: Async, NearSync, Synchronous, Metro - Configure snapshot policies and retention - Translate business requirements into RPO/RTO objectives - Configure network and storage for BCDR - Determine prerequisites for BCDR configuration |
ITDumpsKR의 Nutanix 인증 NCP-BC-7.5시험덤프공부자료는 pdf버전과 소프트웨어버전 두가지 버전으로 제공되는데 Nutanix 인증 NCP-BC-7.5실제시험예상문제가 포함되어있습니다.덤프의 예상문제는 Nutanix 인증 NCP-BC-7.5실제시험의 대부분 문제를 적중하여 높은 통과율과 점유율을 자랑하고 있습니다. ITDumpsKR의 Nutanix 인증 NCP-BC-7.5덤프를 선택하시면 IT자격증 취득에 더할것 없는 힘이 될것입니다.
질문 # 97
An administrator finds replications for Marketing VMs are failing to replicate. After doing some digging the administrator was able to find the following:
* Connectivity was confirmed on ports 2020 and 2009 between the clusters
* All other VMs are replicating successfully
* Cluster wide storage has plenty of remaining space
* No firewall exists between the sites
* Marketing VMs are running Windows, successful VMs are running Linux
What could be causing the Marketing VMs to fail replications?
정답:C
설명:
In a complex BCDR environment, replication failures that affect only a specific subset of virtual machines- while others on the same cluster succeed-usually point to a configuration mismatch rather than a general network or storage issue. Since the ports (2009 and 2020) are confirmed open and storage is available, the transport layer is functional. The fact that Linux VMs are succeeding while Windows (Marketing) VMs are failing suggests that the two groups may be mapped to different destination storage containers. In Nutanix replication, if a container mapping is explicitly set for one set of entities (the Linux VMs) but not for another (the Marketing VMs), the second group might be defaulting to a destination container that is either missing, misconfigured, or has restricted permissions. This specific scenario implies that the successful Linux VMs are benefiting from a correctly configured container mapping on the remote site, whereas the Marketing VMs are likely attempting to replicate to a location where mapping is invalid or non-existent. Troubleshooting this requires an administrator to verify the Prism Central container mapping settings to ensure that the storage targets for all protected categories are reachable and correctly associated with the destination storage pool.
질문 # 98
Two AHV clusters are 4 ms RTT apart. The business requires:
* 0 RPO
* Automatic failover
* No application performance degradation
* Hybrid HCI nodes with 100 TB capacity
What storage configuration must be validated before enabling synchronous replication?
정답:C
설명:
Synchronous replication is a high-performance disaster recovery solution designed to provide a Zero Recovery Point Objective (RPO) by mirroring every write operation in real-time between two clusters.
Because the system must wait for the remote site to acknowledge every write before confirming the operation to the application, the underlying storage media must be capable of extremely low-latency I/O.
On hybrid clusters that utilize both Solid State Drives (SSDs) and Hard Disk Drives (HDDs), Nutanix mandates a minimum of one SSD per node to support synchronous replication. The SSD tier is used to store metadata and provide the high-speed " Oplog " where incoming writes are initially landed before being drained to the HDD tier. If a cluster were to attempt synchronous replication using only HDDs (Option D), the mechanical latency of the spinning disks combined with the network Round Trip Time (RTT) would cause severe application performance degradation, failing the business requirement. Even though the cluster has large capacity requirements (100 TB), the presence of an SSD tier is a technical prerequisite for the software to even enable the synchronous consistency feature. Therefore, ensuring at least one SSD exists in every node of the hybrid cluster is the critical storage validation step required before implementation.
질문 # 99
An administrator has received the following alert: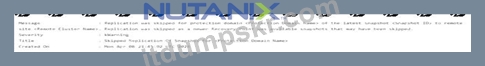
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
정답:B
설명:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
질문 # 100
An administrator configures a VM-VM Anti-Affinity policy for a web application cluster to ensure high availability. The application is protected by a Protection Policy in Prism Central. A failover occurs, moving the VMs to the recovery site.
What determines whether the VM-VM Anti-Affinity rules are active on the recovery site?
정답:D
설명:
VM-VM Anti-Affinity rules are used in Nutanix to ensure that specific virtual machines (such as the nodes of a database cluster or redundant web servers) never run on the same physical host, thereby protecting the application from a single host failure. These rules are typically managed through Prism Central (PC) in a modern deployment.
However, in the context of Disaster Recovery (DR) between two different clusters or availability zones, there is a technical limitation regarding the replication of these affinity policies. While the virtual machine ' s data and primary metadata (CPU, RAM, Disks) are replicated by the Cerebro service, the affinity rules are often considered local cluster constraints. In many versions of Nutanix Disaster Recovery (specifically the initial iterations of Leap/Prism Central-based DR), these affinity policies are not natively " synchronized " or enforced at the recovery site during a failover. This means that when the VMs are recovered at the destination cluster, the hypervisor ' s dynamic scheduler (ADS) may place them on the same host if that host has the most available resources. To maintain anti-affinity at the recovery site, an administrator would typically need to manually recreate the affinity policies at the destination AZ or use specialized orchestration scripts.
Understanding this limitation is vital for ensuring that high-availability requirements are still met after a disaster recovery event has occurred.
질문 # 101
A deployment uses native encryption for replication traffic between two clusters. An administrator subsequently enables network segmentation to isolate this traffic. Which specific maintenance step must be performed to ensure the encrypted replication functions correctly on the new segmented network?
정답:A
설명:
Nutanix allows for the encryption of replication traffic " on the wire " using IPSec tunnels between clusters.
When an administrator enables network segmentation for Disaster Recovery, the replication traffic is moved from the default management network to a new, dedicated subnet and set of virtual interfaces.
Because the native replication encryption relies on IPSec gateways to secure the communication, the underlying VPN configuration must be aware of the network paths it is protecting. If the traffic is now originating from a new segmented subnet, the IPSec VPN gateway configuration at both the primary and recovery sites must be updated to include these new subnet ranges. If this step is missed, the encrypted tunnel will not recognize the segmented traffic as valid for the VPN, causing replication to fail even if the physical network is reachable. Regenerating KMS tokens (Option C) relates to data-at-rest encryption on physical drives, not traffic-in-transit. Restarting services (Option D) might be part of the general segmentation workflow, but the specific requirement for " encrypted replication " stability in this context is the alignment of the IPSec VPN policy with the new segmented network topology.
질문 # 102
......
ITDumpsKR는 여러분이 Nutanix인증NCP-BC-7.5시험 패스와 추후사업에 모두 도움이 되겠습니다.ITDumpsKR제품을 선택함으로 여러분은 시간과 돈을 절약하는 일석이조의 득을 얻을수 있습니다. Nutanix인증NCP-BC-7.5 인증시험패스는 아주 어렵습니다. 자기에 맞는 현명한 학습자료 선택은 성공의 지름길을 내딛는 첫발입니다. 퍼펙트한 자료만이Nutanix인증NCP-BC-7.5시험에서 성공할수 있습니다. ITDumpsKR시험문제와 답이야 말로 퍼펙트한 자료이죠. ITDumpsKR Nutanix인증NCP-BC-7.5인증시험자료는 100% 패스보장을 드립니다
NCP-BC-7.5시험패스 인증덤프문제: https://www.itdumpskr.com/NCP-BC-7.5-exam.html