We aim to leave no misgivings to our customers on our DP-750 practice braindumps so that they are able to devote themselves fully to their studies on DP-750 guide materials and they will find no distraction from us. I suggest that you strike while the iron is hot since time waits for no one. with the high pass rate as 98% to 100%, you will be sure to pass your DP-750 Exam and achieve your certification easily.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
>> DP-750 Latest Exam Price <<
Are you still searching proper DP-750 exam study materials, or are you annoying of collecting these study materials? As the professional IT exam dumps provider, Free4Dump has offered the complete DP-750 Exam Materials for you. So you can save your time to have a full preparation of DP-750 exam.
NEW QUESTION # 92
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1.
You need to meet the following requirements:
- Records that violate rule1 must NOT be written to Table1, but the
pipeline must continue processing valid records.
- Data engineers must be able to review expectation metrics by using
minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.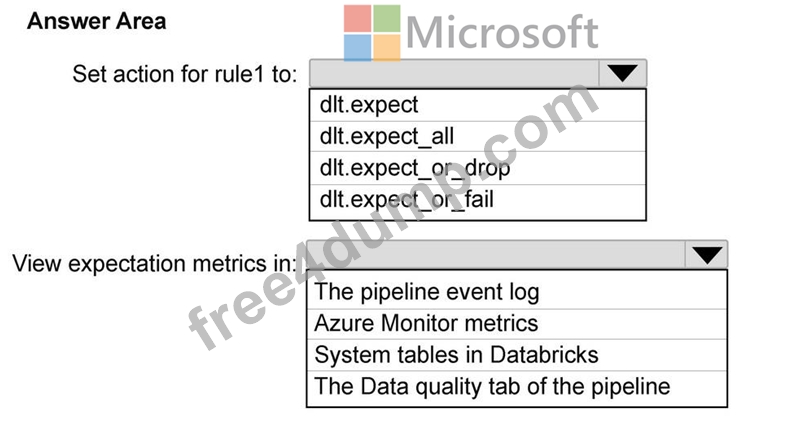
Answer:
Explanation: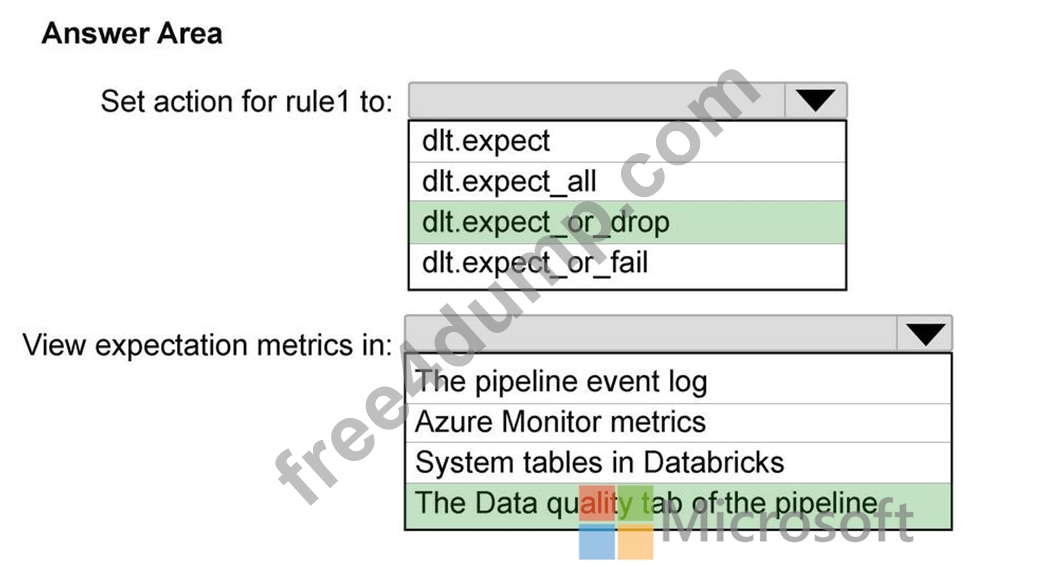
NEW QUESTION # 93
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: D
Explanation:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
NEW QUESTION # 94
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 95
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.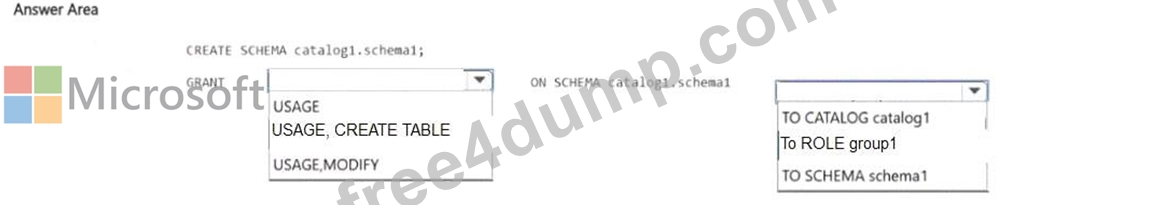
Answer:
Explanation: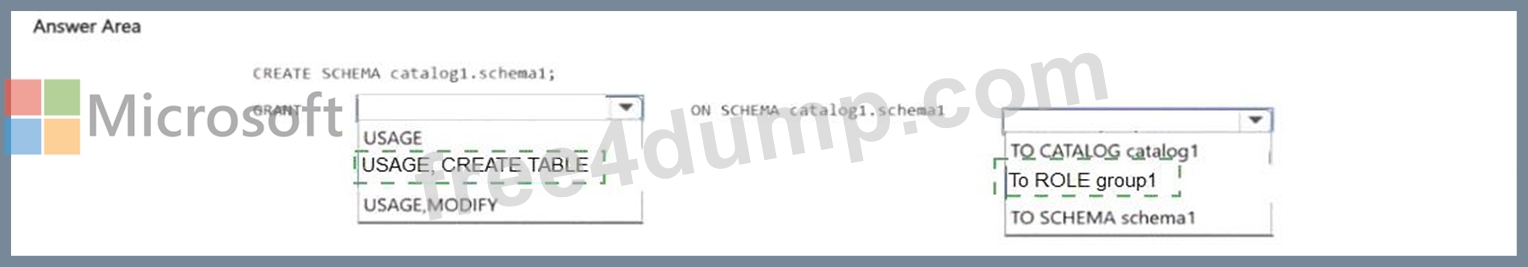
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 96
You have an Azure Databricks workspace that is enabled for Unity Catalog You have a complex job named Job1 that contains eight tasks. Job! takes multiple hours to complete During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: D
Explanation:
The correct answer is B - Repair the current job run.
Repair Run is designed for exactly this situation: a long-running job where most tasks succeeded but the final task failed due to a transient issue. Instead of restarting the entire eight-task job from the beginning - wasting hours of compute - Repair Run re-executes only the failed task and any dependents that were skipped as a result. All tasks that completed successfully are marked done and their outputs are reused.
Option A (update job parameters) changes configuration for future runs but doesn't re-execute the failed task in the current run. Option C (Restart Job1) re-runs every task from the start - precisely what the question says to avoid. Option D (disable and re-enable the schedule) creates a brand-new run on the next schedule trigger, again starting from the beginning rather than repairing the existing run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 97
......
We are equipped with a team of IT elites who have a good knowledge of IT field and do lots of study in Microsoft certification exam. All dumps free of Free4Dump are creating based on the actual test. Our colleagues check the updating of DP-750 Test Questions everyday to make sure that all answers are latest and valid. Our DP-750 test study material contains valid top questions and detailed exam answers.
DP-750 Exam Discount: https://www.free4dump.com/DP-750-braindumps-torrent.html