BONUS!!! Download part of PrepAwayPDF AI-200 dumps for free: https://drive.google.com/open?id=1dG_8LRGpMkIc95TO-uM6T6y_zJu8JJK4
Some of our customers are white-collar workers with no time to waste, and need a Microsoft certification urgently to get their promotions, meanwhile the other customers might aim at improving their skills. So we try to meet different requirements by setting different versions of our AI-200 question and answers. The special one is online AI-200 engine version. As an online tool, it is convenient and easy to study, supports all Web Browsers and system including Windows, Mac, Android, iOS and so on. You can apply this version of AI-200 exam questions on all eletric devices.
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions |
| Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Plan security and compliance requirements - Select appropriate Azure AI services |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
>> Latest AI-200 Dumps Ebook <<
PrepAwayPDF is the best choice for those in preparation for exams. Many people have gained good grades after using our AI-200 real test, so you will also enjoy the good results. Our free demo of AI-200 training material provides you with the free renewal in one year so that you can keep track of the latest points happening in the world. As the questions of exams of our AI-200 Exam Torrent are more or less involved with heated issues and customers who prepare for the exams must haven’t enough time to keep trace of exams all day long.
NEW QUESTION # 131
You optimize an AI inference API that uses Redis caching.
You must reduce the risk of serving outdated data while minimizing cache management overhead.
You need to implement the caching strategy that satisfies the requirements.
What should you do?
Answer: D
Explanation:
Trigger invalidation when source data changes is the best action.
Data Freshness: This is a proactive cache-aside or write-through approach. By explicitly deleting or updating the specific Redis key when the underlying database or model data changes, you completely eliminate the risk of serving stale data.
Low Overhead: It keeps cache management overhead minimal because invalidation logic is execution-dependent (event-driven). Instead of constantly updating expirations or relying on heavy computing logic, you only trigger an action when a write/change event occurs.
Incorrect:
[not B]
Set eviction policy to allkeys-lru:
This policy is a memory management feature, not a data-freshness strategy. It only deletes the Least Recently Used (LRU) keys when your Redis instance runs out of RAM. If memory usage is stable, outdated data will sit in the cache forever, posing a major risk of serving stale inferences.
[not D]
Reset expiration on each read (Sliding TTL):
This actively increases the risk of serving outdated data. If a specific AI response is highly popular and read continuously, its expiration window will extend indefinitely. The data remains stuck in the cache even if the source data undergoes critical updates.
Reference:
https://oneuptime.com/blog/post/2026-01-30-llm-caching-strategies/view
NEW QUESTION # 132
You are developing a Java application that uses Apache Cassandra to store key and value data.
You plan to use a new Azure Cosmos DB resource and the Azure Cosmos DB for Apache Cassandra API in the application. You create a Microsoft Entra ID group named Azure Cosmos DB Creators to enable provisioning of Azure Cosmos DB accounts, databases, and containers.
The Microsoft Entra ID group must not be able to access the keys that are required to access the data.
You need to restrict access to the Microsoft Entra ID group.
Which role-based access control should you use?
Answer: D
Explanation:
The Azure Cosmos DB Operator built-in role should be used.
Provisioning Capabilities: The Azure Cosmos DB Operator role provides permissions to manage and provision Azure Cosmos accounts, databases, and containers (such as keyspaces and tables for the Apache Cassandra API).
Key Restriction: Unlike the DocumentDB Account Contributor role, it explicitly cannot access or read the account keys or connection strings. This satisfies the security requirement that the Microsoft Entra ID group must not have access to the keys required to read/write the underlying data.
Reference:
https://medium.com/azure-terraformer/terraforming-cosmos-db-access-control-arm-role-definitions-and-their-not-so-evil-twin-5de03cd92965
NEW QUESTION # 133
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to optimize vector search queries based on the technical requirements. What should you do?
Answer: A
Explanation:
Scenario: Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
*-> Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
To optimize vector similarity queries that must be performed only against products satisfying mandatory metadata constraints, you should Create a B-tree index on metadata filter columns.
1. Evaluate Query Execution OrderIn PostgreSQL with pgvector, combining metadata filters with vector similarity searches often triggers a multi-stage execution plan. When metadata filtering is highly restrictive, creating a B-tree index allows the database engine to quickly narrow down the row scanned before or during the vector evaluation, preventing a costly full-table scan.
2. Assess Indexing Trade-offs
B-tree Index (Metadata): Directly addresses the requirement that vector calculations must be performed only against products satisfying mandatory metadata constraints. It optimizes the metadata filtering step, significantly reducing compute overhead and isolating the target rows for vector processing.
IVFFlat Index (Vector): While an IVFFlat index speeds up high-dimensional approximate nearest neighbor (ANN) searches, it divides vectors into lists. If a metadata filter is applied after an IVFFlat index scan, it can lead to severe recall degradation or inaccurate results because rows matching the metadata might reside in unsearched vector lists. (Note: For newer workloads, HNSW is generally preferred over IVFFlat for better recall and performance, but regular B-trees remain vital for the metadata layer).
3. Ensure Index Residency in RAM
By isolating the dataset using a compact B-tree index on metadata columns, you minimize the active working set. This helps fulfill your operational requirement to ensure that high-dimensional vector indexes and target rows remain resident in RAM for efficient mathematical throughput.
Reference:
https://www.applied-ai.com/briefings/enterprise-rag-architecture/
NEW QUESTION # 134
You need to secure an Azure OpenAI resource so that it is only reachable from your virtual network and not from the public internet.
What should you configure?
Answer: D
Explanation:
Configure an Azure Private Endpoint through Azure Private Link for the Azure OpenAI resource and disable public network access. A private endpoint assigns the Azure OpenAI service a private IP address from the selected virtual-network subnet, enabling workloads inside the VNet-or connected networks with suitable routing and DNS-to reach the service over private Azure networking rather than through its public endpoint. Microsoft explicitly documents private endpoints as the mechanism for accessing an Azure OpenAI resource after public network access is disabled.
For complete network isolation, creating the private endpoint alone is not sufficient if the resource continues accepting public connections. Microsoft security guidance recommends validating private endpoint connectivity and then disabling public network access , ensuring that permitted application traffic flows through Private Link. Private DNS should also be configured so the normal Azure OpenAI hostname resolves to the private endpoint address from within the VNet.
Azure AI Content Safety controls harmful-content detection rather than network accessibility. API key rotation improves credential hygiene but does not prevent public network connectivity. CORS controls browser-origin behavior and is not a network-isolation boundary.
Therefore, the required network architecture is Private Endpoint + Azure Private Link , with public network access disabled.
Study Guide references: Azure OpenAI networking; Azure Private Link; private endpoints; private DNS; public network access controls.
NEW QUESTION # 135
Hotspot Question
You plan to develop an Azure Functions app with an HTTP trigger.
The app must support the following functionality:
- Event-driven scaling
- Ability to use custom Linux images for function execution
You need to identify the app's hosting plan and the maximum amount of time that the app function can take to respond to incoming requests.
Which configuration setting values should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.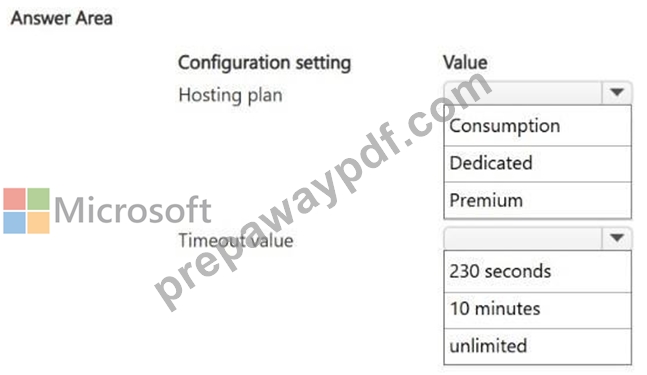
Answer:
Explanation: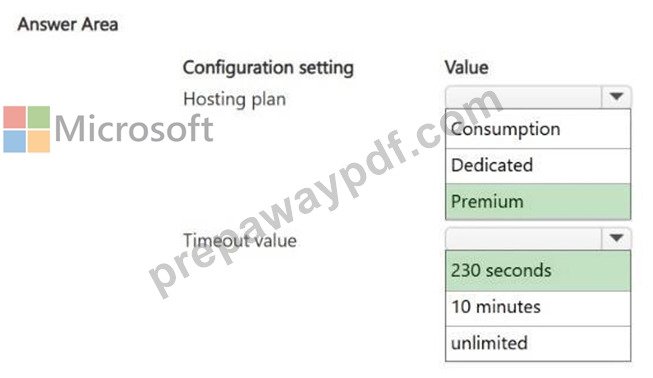
Explanation:
Box 1: Premium
To fulfill your requirements, you should use the Azure Functions Premium plan (also known as the Elastic Premium plan).
Event-Driven Scaling: It features dynamic, automatic scale-out driven by the Azure scale controller. It can scale down to zero instances when idle, ensuring you only pay for active compute time.
Custom Linux Images: Unlike the base Consumption plan, the Premium plan allows you to deploy and run your functions inside a custom Linux container image. This lets you bring your own custom OS dependencies, specialized tools, or specific runtime environments.
Box 2: 230 seconds
The correct maximum timeout value to use for an HTTP-triggered function is 230 seconds.
Azure Load Balancer Limit: Regardless of the specific Azure Functions hosting plan or timeout configurations you set in host.json, the Azure Functions Scale and Hosting documentation states that an HTTP-triggered function has a hard limit of 230 seconds to respond to a request.
Idle Timeout: This constraint is strictly enforced due to the default idle timeout of the underlying Azure Load Balancer. If your function runs longer than 230 seconds without returning a response, the connection will be dropped, resulting in a timeout error.
Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-deployment-technologies
https://learn.microsoft.com/en-us/azure/azure-functions/functions-scale
NEW QUESTION # 136
......
All of our considerate designs have a strong practicability. We are still researching on adding more useful buttons on our AI-200 test answers. The aim of our design is to improve your learning and all of the functions of our products are completely real. Then the learning plan of the AI-200 Exam Torrent can be arranged reasonably. You need to pay great attention to the questions that you make lots of mistakes. If you are interested in our products, click to purchase and all of the functions. Try to believe us and give our AI-200 exam guides a chance to certify.
Exam AI-200 Questions Pdf: https://www.prepawaypdf.com/Microsoft/AI-200-practice-exam-dumps.html
P.S. Free & New AI-200 dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=1dG_8LRGpMkIc95TO-uM6T6y_zJu8JJK4