100% Pass Quiz 2026 Databricks - Certified-Data-Engineer-Professional Reliable Exam Cost

With the qualification certificate, you are qualified to do this professional job. Therefore, getting the test Certified-Data-Engineer-Professional certification is of vital importance to our future employment. And the Certified-Data-Engineer-Professional study tool can provide a good learning platform for users who want to get the test Certified-Data-Engineer-Professionalcertification in a short time. If you can choose to trust us, I believe you will have a good experience when you use the Certified-Data-Engineer-Professional study guide, and you can pass the exam and get a good grade in the test Certified-Data-Engineer-Professional certification.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Topic 2: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures
- Use Spark UI, Query Profiler, and system tables
|
| Topic 3: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
| Topic 4: Developing Code for Data Processing using Python and SQL | ~22% | - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
- Implement scalable Python/SQL code and project structures
|
| Topic 5: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Topic 6: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Topic 7: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| Topic 8: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering
- Apply dimensional modeling techniques
|
| Topic 9: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
>> Certified-Data-Engineer-Professional Reliable Exam Cost <<
Certified-Data-Engineer-Professional Reliable Study Questions & Certified-Data-Engineer-Professional Test Tutorials
The services provided by our Certified-Data-Engineer-Professional test questions are quite specific and comprehensive. First of all, our test material comes from many experts. The gold content of the materials is very high, and the updating speed is fast. By our Certified-Data-Engineer-Professional exam prep, you can find the most suitable information according to your own learning needs at any time, and make adjustments and perfect them at any time. Our Certified-Data-Engineer-Professional Learning Materials not only provide you with information, but also for you to develop the most suitable for your learning schedule, this is tailor-made for you, according to the timetable to study and review. I believe you can improve efficiency.
Databricks Certified Data Engineer Professional Sample Questions (Q122-Q127):
NEW QUESTION # 122
A data engineer is optimizing a MERGE operation on an 800GB UC-managed table that experiences frequent updates and deletions. Which two actions should the engineer prioritize to improve MERGE performance? (Choose two.)
- A. Use ZORDER on high-cardinality columns.
- B. Enable deletion vectors on the table if not already enabled.
- C. Partition the table by date.
- D. Overwrite the table instead of Merge.
- E. Apply liquid clustering using the merge join keys.
Answer: B,E
Explanation:
Liquid clustering on the merge join keys improves data locality and reduces the amount of data scanned during MERGE operations, which is especially effective for large, frequently updated tables. Enabling deletion vectors avoids rewriting entire Parquet files for updates and deletes, significantly reducing I/O and improving MERGE performance on Unity Catalog-managed tables.
NEW QUESTION # 123
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.
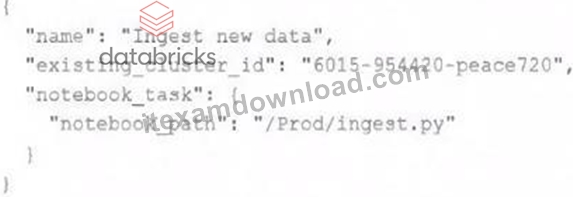
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
- A. The logic defined in the referenced notebook will be executed three times on the referenced existing all purpose cluster.
- B. The logic defined in the referenced notebook will be executed three times on new clusters with the configurations of the provided cluster ID.
- C. Three new jobs named "Ingest new data" will be defined in the workspace, and they will each run once daily.
- D. One new job named "Ingest new data" will be defined in the workspace, but it will not be executed.
- E. Three new jobs named "Ingest new data" will be defined in the workspace, but no jobs will be executed.
Answer: E
Explanation:
Databricks jobs create will create a new job with the same name each time it is run.
In order to overwrite the extsting job you need to run databricks jobs reset
NEW QUESTION # 124
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
- B. Parse the Delta Lake transaction log to identify all newly written data files.
- C. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
- D. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
Answer: D
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 125
A data engineer wants to enforce the principle of least privilege when configuring ACLs for Databricks jobs in a collaborative workspace. Which approach should the data engineer use?
- A. Grant all users CAN MANAGE permission on all jobs to avoid access issues.
- B. Grant CAN RUN permission to everyone and CAN MANAGE to a single admin group.
- C. Assign users only the minimum permission level (e.g., CAN RUN or CAN VIEW) required for their role on each job.
- D. Use only folder-level permissions and avoid setting permissions on individual jobs.
Answer: C
Explanation:
Assigning the minimum required permission level on each job ensures users can perform only the actions necessary for their role. This directly enforces the principle of least privilege while maintaining secure and controlled access in a collaborative workspace.
NEW QUESTION # 126
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- B. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
- C. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- D. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
Answer: A
Explanation:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
NEW QUESTION # 127
......
You can free download part of ITExamDownload's practice questions and answers about Databricks Certification Certified-Data-Engineer-Professional Exam online. Once you decide to select ITExamDownload, ITExamDownload will make every effort to help you pass the exam. If you find that our exam practice questions and answers is very different form the actual exam questions and answers and can not help you pass the exam, we will immediately 100% full refund.
Certified-Data-Engineer-Professional Reliable Study Questions: https://www.itexamdownload.com/Certified-Data-Engineer-Professional-valid-questions.html
- Certified-Data-Engineer-Professional Latest Braindumps Pdf 🚘 Exam Certified-Data-Engineer-Professional Vce 🥃 Certified-Data-Engineer-Professional Intereactive Testing Engine 🚠 Open { www.prep4sures.top } and search for 「 Certified-Data-Engineer-Professional 」 to download exam materials for free 👲Certified-Data-Engineer-Professional Reliable Test Camp
- Certified-Data-Engineer-Professional Reliable Test Camp 🐪 Exam Certified-Data-Engineer-Professional Vce 🥏 Training Certified-Data-Engineer-Professional Material ✌ Go to website ➤ www.pdfvce.com ⮘ open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🧙Sample Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Practice Materials Have High Quality and High Accuracy - www.exam4labs.com 😀 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply entering ( www.exam4labs.com ) website 📋Preparation Certified-Data-Engineer-Professional Store
- Preparation Certified-Data-Engineer-Professional Store 🎨 Certified-Data-Engineer-Professional Reliable Test Camp 📘 Exams Certified-Data-Engineer-Professional Torrent 🧚 Search for ▷ Certified-Data-Engineer-Professional ◁ and download it for free immediately on ⮆ www.pdfvce.com ⮄ 📨Certified-Data-Engineer-Professional Valid Exam Syllabus
- Certified-Data-Engineer-Professional Reliable Exam Pdf 🧝 Real Certified-Data-Engineer-Professional Exams ⛳ Latest Certified-Data-Engineer-Professional Test Sample 🙎 Copy URL ➥ www.vce4dumps.com 🡄 open and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 🐍Sample Certified-Data-Engineer-Professional Exam
- Training Certified-Data-Engineer-Professional Material 🩱 Certified-Data-Engineer-Professional Reliable Braindumps 🐘 Sample Certified-Data-Engineer-Professional Exam 🖍 Open ⏩ www.pdfvce.com ⏪ enter ➽ Certified-Data-Engineer-Professional 🢪 and obtain a free download 🏍Sample Certified-Data-Engineer-Professional Exam
- Free PDF Quiz Databricks - Certified-Data-Engineer-Professional Pass-Sure Reliable Exam Cost 🕝 Search on ▷ www.pdfdumps.com ◁ for ➽ Certified-Data-Engineer-Professional 🢪 to obtain exam materials for free download 🚟Certified-Data-Engineer-Professional Answers Real Questions
- Free PDF Quiz Databricks - Certified-Data-Engineer-Professional Pass-Sure Reliable Exam Cost 🧒 Immediately open ➥ www.pdfvce.com 🡄 and search for ▷ Certified-Data-Engineer-Professional ◁ to obtain a free download 💏Certified-Data-Engineer-Professional Intereactive Testing Engine
- Sample Certified-Data-Engineer-Professional Exam 🥩 Certified-Data-Engineer-Professional Latest Braindumps Pdf 🔭 Authentic Certified-Data-Engineer-Professional Exam Questions 🟦 Download ▷ Certified-Data-Engineer-Professional ◁ for free by simply entering ⇛ www.exam4labs.com ⇚ website 🦒Certified-Data-Engineer-Professional Practice Test Pdf
- Free PDF Quiz Databricks - Certified-Data-Engineer-Professional Pass-Sure Reliable Exam Cost 🐧 Search for ( Certified-Data-Engineer-Professional ) and download exam materials for free through 【 www.pdfvce.com 】 🐲Real Certified-Data-Engineer-Professional Exams
- Certified-Data-Engineer-Professional Practice Test Pdf 📑 Certified-Data-Engineer-Professional Practice Test Pdf 🦃 Certified-Data-Engineer-Professional Practice Test Pdf 🕠 Simply search for ▛ Certified-Data-Engineer-Professional ▟ for free download on ➽ www.troytecdumps.com 🢪 🔇Exam Certified-Data-Engineer-Professional Vce
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.chordie.com, Disposable vapes