In recent years, our AI-500 test torrent has been well received and have reached 99% pass rate with all our dedication. As a powerful tool for a lot of workers to walk forward a higher self-improvement, our AI-500 certification training continue to pursue our passion for advanced performance and human-centric technology. A good deal of researches has been made to figure out how to help different kinds of candidates to get Designing and Implementing Multi-Agent AI Solutions certification. We revise and update the Designing and Implementing Multi-Agent AI Solutions guide torrent according to the changes of the syllabus and the latest developments in theory and practice. We base the AI-500 Certification Training on the test of recent years and the industry trends through rigorous analysis.
| Section | Weight | Objectives |
|---|---|---|
| Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize prompt and model performance
|
| Architect multi-agent solutions | 15-20% | - Specify technology components for multi-agent solutions
|
The BraindumpQuiz is a leading platform that has been helping the Designing and Implementing Multi-Agent AI Solutions (AI-500) exam candidates in exam preparation and boosting their confidence to pass the final AI-500 exam. The BraindumpQuiz is offering real, valid, and updated Designing and Implementing Multi-Agent AI Solutions (AI-500) practice questions. These Designing and Implementing Multi-Agent AI Solutions (AI-500) exam questions are verified by Microsoft AI-500 exam trainers.
NEW QUESTION # 49
You have a Microsoft Foundry agent that completes benefits enrollment during a single user conversation The agent collects the required enrollment fields during 15 turns. Users can correct earlier values before final submission. The current implementation sends the complete transcript with every model request.
You need to change the context accumulation strategy for the active enrollment. The solution must meet the following requirements:
* Preserve the latest value for each required enrollment field until submission.
* Bound the maximum number of tokens sent with each model request
* Preserve user corrections until submission.
* Prevent durable cross-session memory.
What should you do?
Answer: A
Explanation:
The application must preserve the latest authoritative value of each enrollment field even when the user corrects an earlier value, while also placing a firm bound on prompt size. A session-scoped enrollment-state snapshot provides deterministic structured state: each correction overwrites the previous field value. A recent- turn sliding window then preserves enough conversational context for natural interaction without resending the full 15-turn transcript. Response chaining with a fixed number of prior turns can lose an important field once it falls outside the retained history. Summarization can omit or distort corrected values, and automatic truncation likewise offers no guarantee that the latest value of every required field survives. Because the state is scoped only to the active enrollment and is not written to long-term memory, the design also avoids durable cross-session memory. Therefore A is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Agent Framework - workflow state and context management
NEW QUESTION # 50
You have a Microsoft Foundry multi-agent customer support solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. A custom guardrail is assigned to the agents.
You discover that some legitimate support requests are blocked, and some injected instructions in retrieved documents are allowed.
You need to validate the updated guardrail. The solution must meet the following requirements:
* Identify false positives and false negatives.
* Verify policy coverage across the agent solution
* Prevent changing the production agent behavior during testing
* Measure intervention accuracy by using a control and intervention point.
What should you do?
Answer: A
Explanation:
The updated guardrail must be evaluated with known benign and adversarial cases so false positives and false negatives can be measured explicitly. Running labeled cases through every relevant workflow path also tests whether the guardrail is applied consistently at the intended intervention points. Microsoft AI-500 guidance includes guardrail testing with synthetic or curated data and emphasizes evaluation before production rollout.
Playground-only spot checks are too narrow to establish coverage. Switching production to annotate-only would change live behavior and use customers as the test population, violating the requirement to avoid production changes. A compliance configuration review verifies that a policy exists but does not measure whether it correctly detects or misses real inputs. Option B is therefore the only approach that produces repeatable evidence of intervention accuracy and policy coverage without changing production behavior. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: AI-500 Study Guide - guardrail testing and evaluation
NEW QUESTION # 51
You are designing an enterprise automation solution that has a web portal for users and the following types of workflows:
* Routine workflows that use prompt-defined agents, approved knowledge stores, and HTTPS tools
* Modernization workflows that use custom Microsoft Agent Framework code packaged as container images with predefined handoffs and task states You need to recommend Azure services that meets the following requirements:
* The routine workflows must run agents in a fully managed environment.
* The user portal must be deployed as a managed platform as a service (PaaS) web app
* The modernization workflows must run agents in serverless containers that support automatic scaling What should you recommend for each requirement? To answer, drag the appropriate services to the correct components. Each service may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.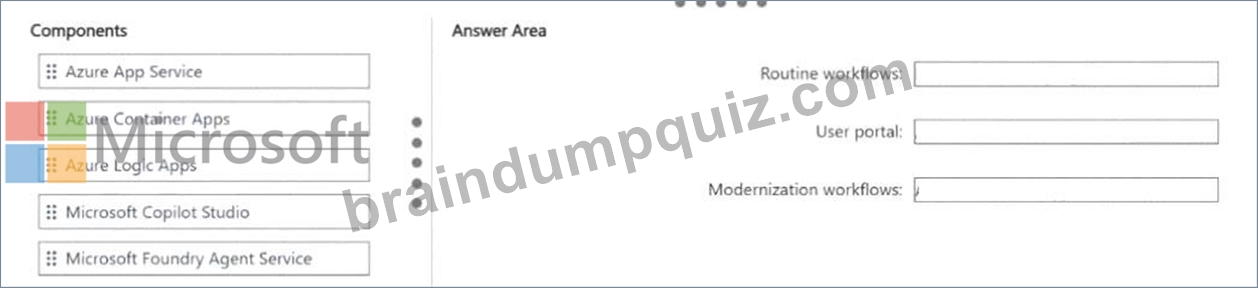
Answer:
Explanation: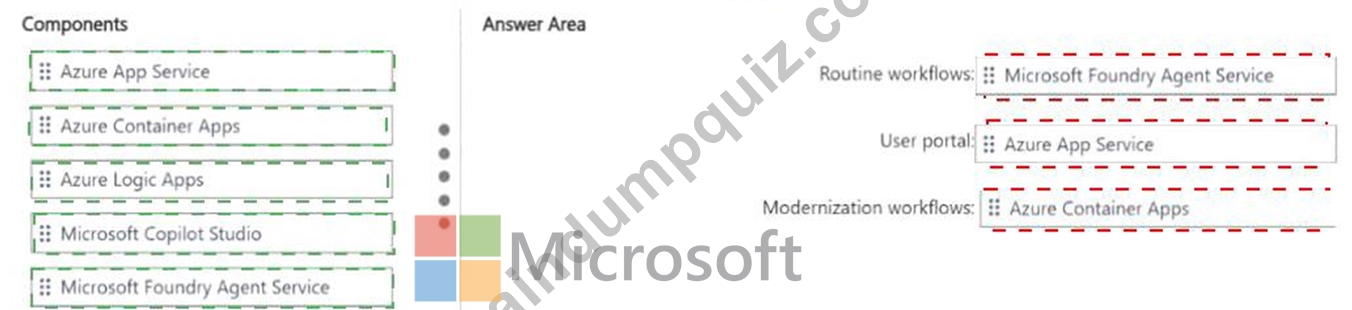
Explanation:
Routine workflows: Microsoft Foundry Agent Service; User portal: Azure App Service; Modernization workflows: Azure Container Apps.
The three workload types map to three different managed Azure services. Prompt-defined agents that use approved knowledge and HTTPS tools fit Microsoft Foundry Agent Service because it provides a managed agent runtime and hosted agent capabilities without requiring the team to operate the underlying orchestration infrastructure. The user portal is a conventional managed web application, making Azure App Service the direct PaaS fit. The modernization workflow is custom Microsoft Agent Framework code packaged as container images and therefore needs a serverless container platform; Azure Container Apps supplies managed container execution and automatic scaling while preserving control of the custom application image.
Logic Apps targets integration workflows rather than arbitrary Agent Framework containers, and Copilot Studio is not the requested general-purpose container runtime. The answer therefore selects the managed service that matches each component ' s execution model. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry Agent Service overview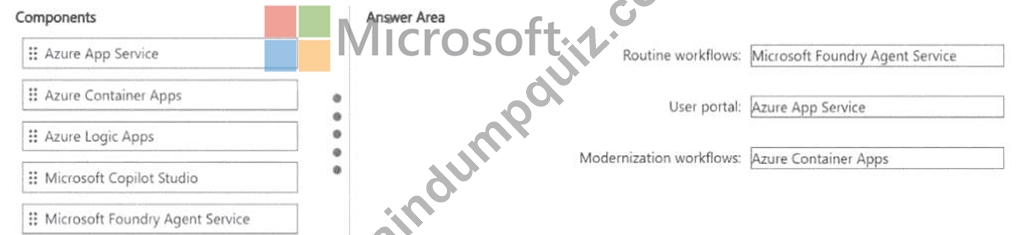
NEW QUESTION # 52
You need to recommend changes to decrease the Claim Approval duration without breaking any existing functionality.
What should you recommend?
Answer: A
Explanation:
Fraud-check, Policy-eligibility, and Document-summary are independent specialist activities, so running them concurrently reduces wall-clock time without changing their outputs. The Decision agent is different because the case study states that it depends on the results of those three agents. It therefore must execute only after the independent work completes. Microsoft Agent Framework ' s concurrent orchestration pattern is designed for independent participants whose results can be fanned in later, while dependency-driven work should remain ordered. Running all four agents concurrently would violate the Decision agent ' s data dependency.
Running all four sequentially would preserve correctness but add unnecessary latency. Disabling memory would also change functionality unrelated to the performance bottleneck. The optimal graph is therefore a parallel fan-out of the three independent specialists followed by a fan-in and Decision step, which preserves behavior while minimizing end-to-end claim-approval duration. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 53
You have a Microsoft Foundry multi-agent solution. The agents contain the CI/CD evaluation gates shown in the following table.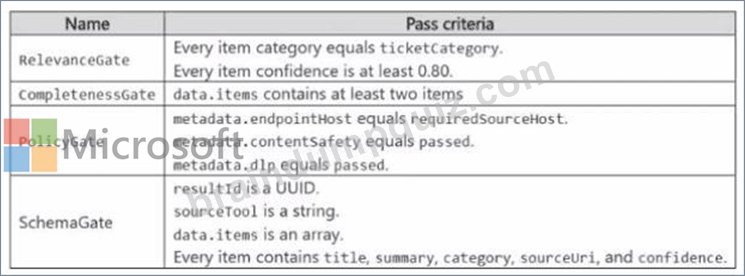
You call one of the agents by using the request context in the evaluation process as shown in the following table.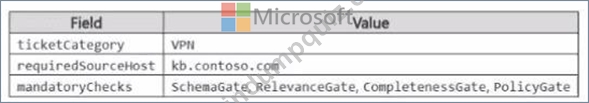
The agent receives the following results for the tool.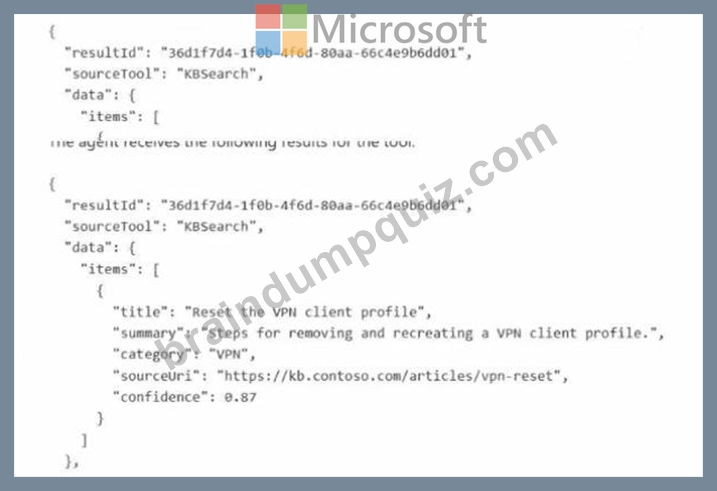
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.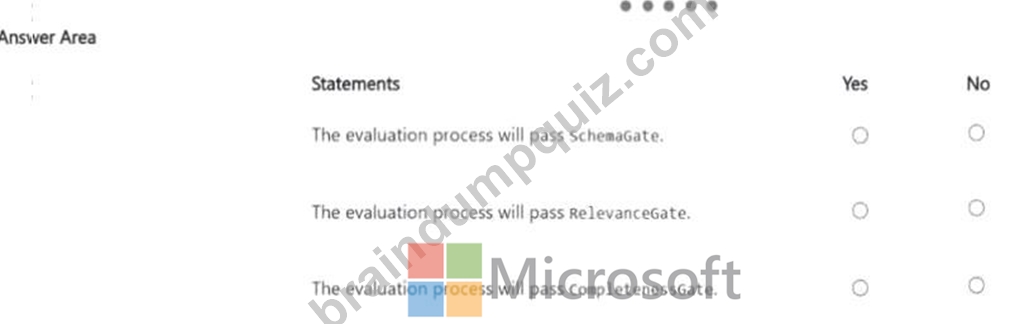
Answer:
Explanation: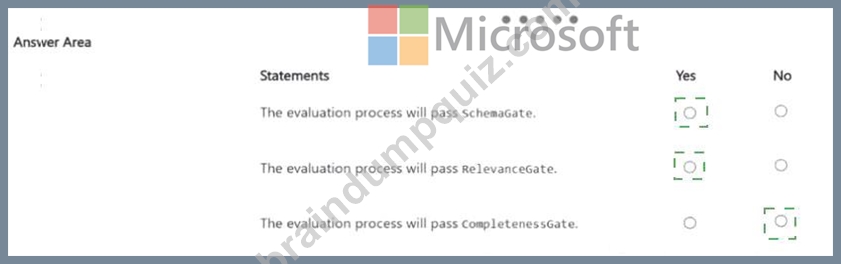
Explanation:
SchemaGate: Yes; RelevanceGate: Yes; CompletenessGate: No.
The supplied tool result satisfies the structural requirements of SchemaGate: it includes a valid-looking UUID result identifier, a string sourceTool value, an items array, and the required fields on the item. RelevanceGate also passes because the request category is VPN, the returned item category is VPN, and its confidence value of 0.87 is above the required 0.80 threshold. CompletenessGate fails because the rule requires at least two items while the response contains only one. This is a deterministic gate evaluation rather than an LLM-judge interpretation, so the values should be checked directly against the declared criteria. Microsoft Foundry evaluation datasets and CI/CD quality gates are designed to make exactly these regression checks repeatable before release. Therefore the correct sequence is Yes, Yes, No. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets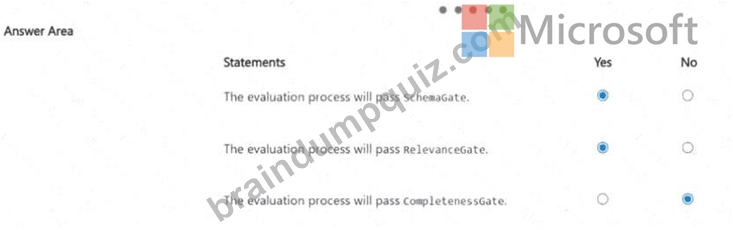
NEW QUESTION # 54
......
Our customers comment that the AI-500 latest dumps pdf covers most questions of actual test. Most questions in our AI-500 dumps valid will appear in the real test because Microsoft exam prep is created based on the formal test. If you practice the AI-500 Test Questions and remember the key points of study guide, the rate of you pass will reach to 95%.
AI-500 Best Study Material: https://www.braindumpquiz.com/AI-500-exam-material.html