BTW, DOWNLOAD part of TestInsides 3V0-25.25 dumps from Cloud Storage: https://drive.google.com/open?id=1oK5nyapPNRNlOwIgQVGJDC4K0SJ3iPhT
It was a Xi'an coach byword that if you give up, the game is over at the same time. The game likes this, so is the exam. Not having enough time to prepare for their exam, many people give up taking IT certification exam. However, with the help of the best training materials, you can completely pass VMware 3V0-25.25 test in a short period of time. Don't you believe in it? TestInsides real questions and answers are the materials that it can help you get high marks and pass the certification exam. Please try it.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> 3V0-25.25 Test Preparation <<
The VMware 3V0-25.25 certification is one of the hottest career advancement credentials in the modern VMware world. The 3V0-25.25 certification can help you to demonstrate your expertise and knowledge level. With only one badge of 3V0-25.25 certification, successful candidates can advance their careers and increase their earning potential. The VMware 3V0-25.25 Certification Exam also enables you to stay updated and competitive in the market which will help you to gain more career opportunities.
NEW QUESTION # 24
How should the Global Managers (GMs) and Local Managers (LMs) be distributed to ensure high availability and optimal performance in a multi-site NSX Federation deployment comprised of three sites? (Choose two.)
Answer: B,E
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)Federation deployment across multiple sites, the management architecture is designed to provide "Global Visibility" while maintaining "Local Autonomy." This is achieved through the coordinated distribution ofGlobal Managers (GMs)andLocal Managers (LMs).
For a three-site deployment,NSX Federationbest practices mandate that each site maintains its ownLocal Manager (LM) Cluster(Option A). The LM is responsible for the site-specific control plane, communicating with local Transport Nodes (ESXi and Edges) to program the data plane. If the connection to the GM is lost, the LM ensures the local site continues to function normally. For production environments, these must be clusters (typically 3 nodes) rather than single nodes to ensure local management remains available.
To protect theGlobal Manageritself-which is the source of truth for all global networking and security policies-the GM cluster should bestretched across the three sites(Option D). In a standard 3-node GM cluster, placing one node at each site ensures that the Federation management plane can survive the complete failure of an entire site. This "stretched" cluster configuration provides a high level of resilience and ensures that an administrator can still manage global policies from any surviving location.
Option B is incorrect because the GM does not communicate directly with the data plane of a site; it must go through an LM. Option C is a risk to availability. Option E is incorrect because vSphere HA cannot protect against a site-wide disaster, and a single appliance represents a significant single point of failure for the entire global network configuration.
NEW QUESTION # 25
The administrator is implementing a multi-location VMware Cloud Foundation (VCF) environment. The design requires centralized security and networking policies across multiple VCF instances. What action must the administrator take to satisfy the requirements?
Answer: D
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
In aVMware Cloud Foundation (VCF)Multi-Site or Multi-Instance design, the requirement for "centralized security and networking policies" is fulfilled byNSX Federation. Federation introduces theGlobal Manager (GM), which provides a single pane of glass to manage objects that span across different VCF sites.
Historically, in early versions of NSX-T, Global Managers were deployed manually. However, within the VCF framework (VCF 4.x, 5.x, and 9.0), the deployment and lifecycle management of theGlobal Manager clusterare fully integrated intoSDDC Manager. According to the VCF Design Guide and "Deploying and Configuring NSX Federation" documents, the verified best practice is to use the SDDC Manager UI or API to trigger the GM deployment.
When an administrator usesSDDC Manager(Option C), the process is automated: SDDC Manager deploys the appliances, configures the virtual IP (VIP), handles the certificate management, and ensures that the GM is properly integrated into the VCF Bill of Materials (BOM). This automation is critical for maintaining supportability, as it ensures the GM version is perfectly aligned with the Local Managers (LMs) already present in the Management and Workload domains.
Option A is discouraged because manual deployments lead to configuration drift and issues with future automated upgrades. Option B is incorrect as VCF Operations is for monitoring, not deployment. Option D is incorrect because theVCF Installeris primarily used for the initial "bring-up" of the Management Domain; subsequent management components like GMs are handled by the SDDC Manager once the initial site is active. Thus, SDDC Manager is the authoritative tool for deploying the Global Manager cluster in a VCF multi-location environment.
NEW QUESTION # 26
An administrator has noticed that both the active and standby Global Managers have gone offline.
What is the correct sequence of events to restore the Global Managers?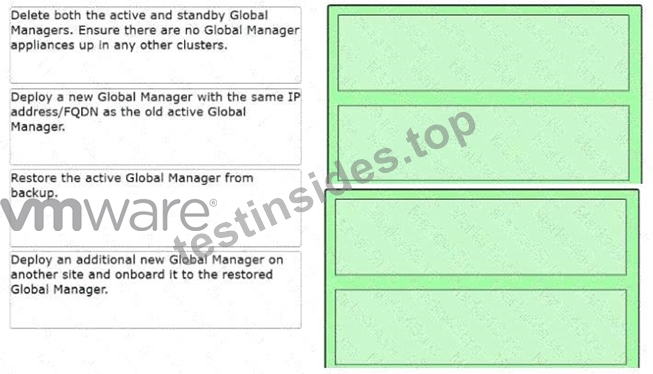
Answer:
Explanation: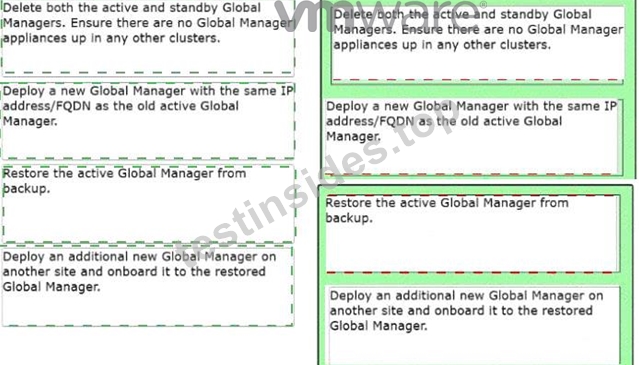
Explanation:
* Step 1: Delete both the active and standby Global Managers. Ensure there are no Global Manager appliances up in any other clusters.
* Step 2: Deploy a new Global Manager with the same IP address/FQDN as the old active Global Manager.
* Step 3: Restore the active Global Manager from backup.
* Step 4: Deploy an additional new Global Manager on another site and onboard it to the restored Global Manager.
In aVMware Cloud Foundationmulti-site deployment usingNSX Federation, the Global Manager (GM) manages the global networking configuration across multiple sites. If the entire GM cluster (Active and Standby) fails, the following architectural principles apply:
* Cleanup (Step 1):Before initiating a restore, the environment must be "cleaned." If old, failed VMs remain in the inventory or on the hosts, they can cause IP address conflicts or UUID mismatches during the deployment of the new appliance. You must ensure the management plane is clear of the original failed nodes.
* Identity Consistency (Step 2):When restoring an NSX appliance (Local or Global) from backup, the new appliancemustbe deployed with the exact sameIP address and FQDNas the original active node.
This is critical because the existing Local Managers (LMs) at each site already have established thumbprints and communication channels tied to that specific identity.
* The Restore Operation (Step 3):Once the "seed" appliance is deployed, the restore process is triggered through the NSX Manager UI/API. This process re-populates the database with the global segments, firewall rules, and Tier-0/Tier-1 configurations.
* Restoring Redundancy (Step 4):The backup only contains the configuration of the cluster. It does not
"restore" the standby VM itself. High Availability (HA) must be manually re-established by deploying a second GM appliance at the secondary site and joining it to the newly restored Global Manager cluster to act as the standby.
NEW QUESTION # 27
An administrator is troubleshooting why workloads in NSX cannot reach the external network 10.100.0.0/16.
The Tier-0 Gateway is in Active/Active mode and has the following configuration:
* Uplink-1 (VLAN 100): 192.168.100.0/24 -> router R1 at 192.168.100.1
* Uplink-2 (VLAN 101): 192.168.101.0/24 -> router R2 at 192.168.101.1
* A static route for 10.100.0.0/16 was added with both next-hops (192.168.100.1 and 192.168.101.1).
* The Scope of this route is set to Uplink-1.
Symptoms:
* Virtual Machines (VMs) cannot reach 10.100.0.0/16
* Traceroute from the VM stops at the Tier-0 gateway with "Destination Net Unreachable"
* Pings from the Edge nodes to both 192.168.100.1 and 192.168.101.1 are success What explains why workloads in NSX cannot reach the external network?
Answer: C
Explanation:
Comprehensive and Detailed 250 to 350 words of Explanation From VMware Cloud Foundation (VCF) documents:
Troubleshooting routing in a VMware Cloud Foundation (VCF) environment requires a deep understanding of how theNSX Tier-0 Gatewayprocesses forwarding entries. In anActive/Activeconfiguration, the Tier-0 gateway is designed to utilize ECMP (Equal Cost Multi-Pathing) to distribute traffic across multiple paths to the physical network.
The specific failure described-where a traceroute fails at the Tier-0 with "Destination Net Unreachable" despite the Edge nodes having basic ping connectivity to the routers-points toward a routing table entry error rather than a physical connectivity issue. In NSX, when a static route is created, an administrator has the option to set a"Scope."The Scope explicitly tells the NSX routing engine which interface should be used to reach the defined next-hops.
In this scenario, the administrator has defined two next-hops (R1 and R2) but has restricted the scope of the static route toUplink-1 only. Because R2 (192.168.101.1) is on a different subnet/VLAN (VLAN 101) that is associated withUplink-2, the Tier-0 gateway cannot resolve the next-hop for R2 via Uplink-1. Furthermore, if the gateway detects an inconsistency between the defined next-hop and the scoped interface, it may invalidate the route or fail to install it correctly in the forwarding information base (FIB) for the service router.
According to VMware documentation, theScopeshould typically be left as "All Uplinks" or carefully matched to the interfaces that have Layer 2 reachability to the next-hop. By scoping it to only Uplink-1, the router R2 becomes unreachable for that specific route entry. Even for R1, if the hashing mechanism of the Active
/Active Tier-0 attempts to use a component of the gateway not associated with that scope, the traffic will fail.
The error "Destination Net Unreachable" at the Tier-0 hop confirms that the Tier-0 has no valid, functional path in its routing table for the 10.100.0.0/16 network due to this scoping conflict.
NEW QUESTION # 28
An administrator is configuring NSX resource sharing to allow shared access to multiple resources in the default space.
By default, which user role owns the shared resources for the default space?
Answer: D
Explanation:
In NSX Multi-Tenancy (Projects), theEnterprise Adminacts as the provider-level administrator who owns global objects in the default space. This ensures central control over resources that are shared across different projects.
NEW QUESTION # 29
......
If people buy and use the 3V0-25.25 study materials with bad quality to prepare for their exams, it must do more harm than good for their exams, thus it can be seen that the good and suitable 3V0-25.25 study materials is so important for people’ exam that people have to pay more attention to the study materials. In order to help people pass the exam and gain the certification, we are glad to the 3V0-25.25 Study Materials from our company for you.
3V0-25.25 Intereactive Testing Engine: https://www.testinsides.top/3V0-25.25-dumps-review.html
DOWNLOAD the newest TestInsides 3V0-25.25 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1oK5nyapPNRNlOwIgQVGJDC4K0SJ3iPhT