What's more, part of that Prep4away DP-800 dumps now are free: https://drive.google.com/open?id=1a-K6GxkxI0KZ0Q65RjKv4uZNDEriCSYI
First and foremost, our company has prepared DP-800 free demo in this website for our customers. Second, it is convenient for you to read and make notes with our versions of DP-800 exam materials. Last but not least, we will provide considerate on line after sale service for you in twenty four hours a day, seven days a week. So let our DP-800 Practice Guide to be your learning partner in the course of preparing for the exam, it will be a wise choice for you to choose our DP-800 study dumps.
| Section | Objectives |
|---|---|
| Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
It is impossible to overstate the significance of valid DP-800 exam questions. The latest and actual DP-800 exam questions are essential to clear the DP-800 exam in one go. Applicants are better prepared to succeed when they prepare with the updated Microsoft DP-800 Questions. These DP-800 exam questions give applicants the knowledge they need to quickly ace the DP-800 examination.
NEW QUESTION # 15
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.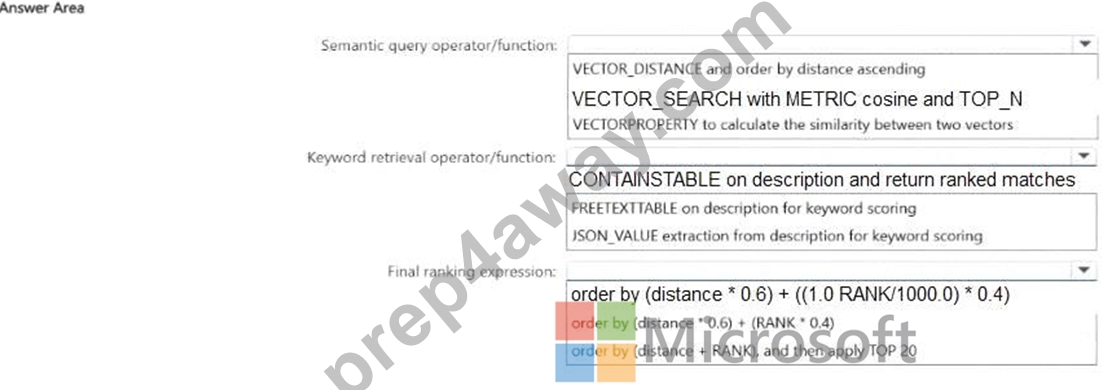
Answer:
Explanation: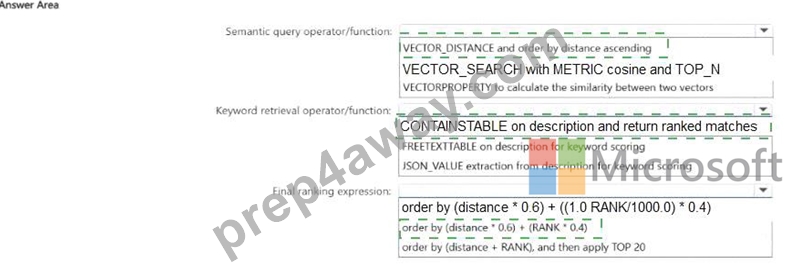
Explanation: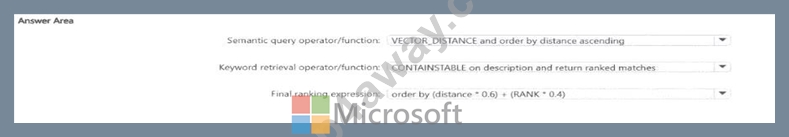
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
NEW QUESTION # 16
You have a GitHub Codespaces environment that has GitHub Copilot Chat installed and is connected to a SQL database in Microsoft Fabric named DB1. DB1 contains tables named Sales.Orders and Sales.Customers.
You use GitHub Copilot Chat in the context of DB1.
A company policy prohibits sharing customer Personally Identifiable Information (PII), secrets, and query result sets with any AI service.
You need to use GitHub Copilot Chat to write and review Transact-SQL code for a new stored procedure that will join Sales.Orders to Sales.Customers and return customer names and email addresses. The solution must NOT share the actual data in the tables with GitHub Copilot Chat.
What should you do?
Answer: D
Explanation:
To use GitHub Copilot Chat effectively in this environment without exposing sensitive data, you should focus your prompts entirely on the schema and logic rather than the data itself.
Since Copilot Chat can "see" your open files, the best approach is to provide the table structures as DDL (Data Definition Language) statements or a simplified description.
Steps to generate the stored procedure:
Define the Schema: Open a new SQL file in your Codespace. Paste the CREATE TABLE scripts (without any data) for your two tables.
Prompt Copilot: Use the Chat view to request the procedure.
Example Prompt: "Based on the table definitions in my open file, write a T-SQL stored procedure that joins TableA and TableB on [Join Column]. Include logic to filter by [Parameter] and ensure no PII columns are included in the SELECT statement." Review for PII/Secrets: Before executing, manually verify that the generated code doesn't include hardcoded secrets or call PII columns you intended to omit.
Security Check: Because you are in a Codespace, ensure your .env files or connection strings are in your .gitignore so they aren't indexed by Copilot.
Reference:
https://github.com/orgs/community/discussions/141924
NEW QUESTION # 17
What is Retrieval-Augmented Generation (RAG)?
Answer: D
Explanation:
RAG enhances LLM responses by retrieving relevant SQL data before generating answers.
NEW QUESTION # 18
You have an Azure SQL database named AdventureWorksDB that contains a table named dbo.Employee.
You have a C# Azure Functions app that uses an HTTP-triggered function with an Azure SQL input binding to query dbo.Employee.
You are adding a second function that will react to row changes in dbo.Employee and write structured logs.
You need to configure AdventureWorksDB and the app to meet the following requirements:
* Changes to dbo.Employee must trigger the new function within five seconds.
* Each invocation must processes no more than 100 changes.
Which two database configurations should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Azure Functions' Azure SQL trigger requires change tracking to be enabled on the source table. Microsoft' s SQL trigger documentation states that setting up change tracking for the Azure SQL trigger requires two steps : enable change tracking on the database and enable change tracking on the table being monitored.
Since the question asks specifically which database configurations you should perform, enabling change tracking on dbo.Employee is one of the required database-side steps.
To meet the latency requirement that changes trigger the function within five seconds , the relevant trigger setting is Sql_Trigger_PollingIntervalMs . Microsoft documents this setting as the delay, in milliseconds, between processing each batch of changes, and a value of 5000 means the trigger polls every 5 seconds .
A few clarifications about the other options:
* B is not the documented setting name. The documented app setting is Sql_Trigger_BatchSize or host setting MaxBatchSize , not "SetSql Trigger MaxBatchSize". The screenshot wording suggests a distractor.
* D is also required in practice for the trigger to work, but the question asks for two answers and includes the polling setting plus the table-level CT setting as the actionable choices presented.
* F is wrong because the Azure SQL trigger uses change tracking , not CDC.
NEW QUESTION # 19
You have an Azure SQL database that stores order data.
A reporting query aggregates monthly revenue per customer runs frequently.
You need to reduce how long it takes to retrieve the calculated values. The solution must NOT alter any underlying table structure.
What should you do?
Answer: B
Explanation:
Creating an indexed view using WITH SCHEMABINDING, including COUNT_BIG(*), and creating a unique clustered index is a valid and effective approach to significantly improve the performance of your frequent reporting query without altering the underlying table structure.
This process materializes the aggregated data and stores it physically in the database, so the query optimizer can read from the precomputed view rather than rescanning the base tables every time the query runs.
Reference:
https://learn.microsoft.com/en-us/sql/relational-databases/views/create-indexed-views
NEW QUESTION # 20
......
The paper materials students buy on the market are often not able to reuse. After all the exercises have been done once, if you want to do it again you will need to buy it again. But with DP-800 test question, you will not have this problem. All customers who purchased DP-800 Study Tool can use the learning materials without restrictions, and there is no case of duplicate charges. For the PDF version of DP-800 test question, you can print multiple times, practice multiple times, and repeatedly reinforce your unfamiliar knowledge.
DP-800 Exam Materials: https://www.prep4away.com/Microsoft-certification/braindumps.DP-800.ete.file.html
DOWNLOAD the newest Prep4away DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1a-K6GxkxI0KZ0Q65RjKv4uZNDEriCSYI