P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by LatestCram: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL
You only need 20-30 hours to learn our DP-750 test braindumps and then you can attend the exam and you have a very high possibility to pass the exam. For many people whether they are the in-service staff or the students they are busy in their job, family lives and other things. But you buy our DP-750 prep torrent you can mainly spend your time energy and time on your job, the learning or family lives and spare little time every day to learn our Implementing Data Engineering Solutions Using Azure Databricks exam torrent. Our answers and questions are compiled elaborately and easy to be mastered. Because our DP-750 Test Braindumps are highly efficient and the passing rate is very high you can pass the exam fluently and easily with little time and energy needed.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> DP-750 Latest Test Preparation <<
DP-750 study guide provides free trial services, so that you can gain some information about our study contents, topics and how to make full use of the software before purchasing. It’s a good way for you to choose what kind of DP-750 training prep is suitable and make the right choice to avoid unnecessary waste. Our purchase process is of the safety and stability if you have any trouble in the purchasing DP-750 practice materials or trail process, you can contact us immediately.
NEW QUESTION # 29
You have an Apache Spark DataFrame named salesDF that contains the following columns:
* Product
* Region
* Sales
* Date
You need to create a pivot table that shows the total sales by product for each region.
How should you complete the PySpark code segment? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* groupBy
* pivot
The groupBy( " Region " ) operation establishes one aggregation group for each geographical region in the DataFrame. The subsequent pivot( " Product " ) operation converts every distinct Product value into a separate output column. Finally, agg(F.sum( " Sales " )) calculates the total sales for every product within each region. The resulting DataFrame contains one row per region and one column for each product, with the corresponding aggregated sales value. cogroup combines grouped datasets and is not used for creating a conventional pivot table. coalesce controls the number of DataFrame partitions or replaces null values, depending on its context. The sum function is already provided inside the aggregation expression and therefore is not required in either blank.
NEW QUESTION # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.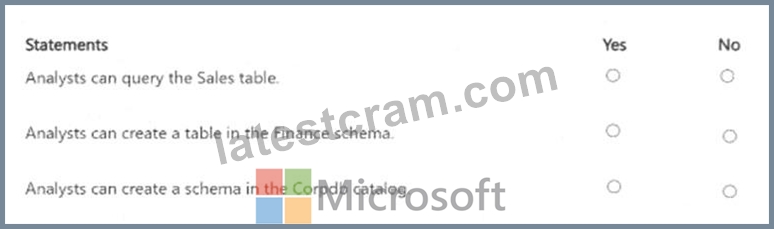
Answer:
Explanation: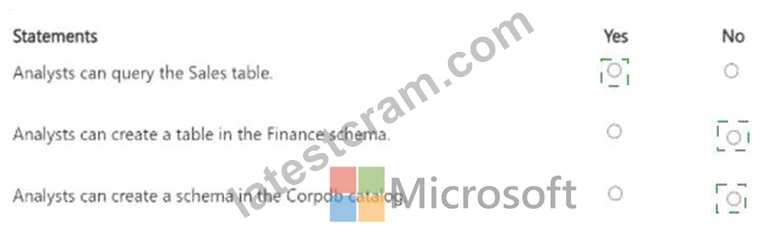
Explanation: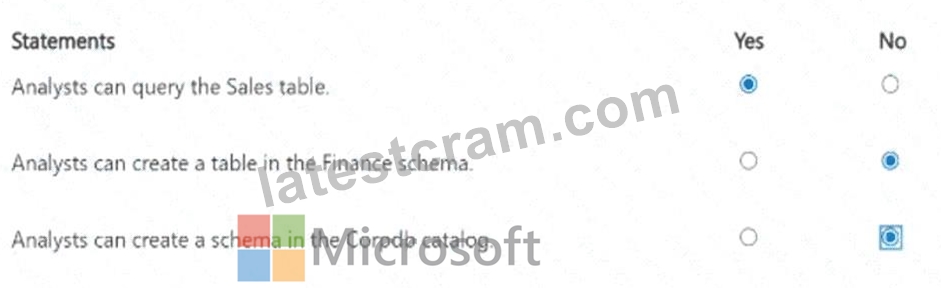
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 31
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Answer: D
Explanation:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 32
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders.
Sales_orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows.
You need to load the daily data into Sales_orders. The solution must meet the following requirements:
- Preserve the existing data.
- Add only the new records.
- Minimize processing effort.
Which command should include in the loading strategy?
Answer: A
Explanation:
The best command for this scenario is INSERT INTO.
The INSERT INTO command appends new rows directly to the end of an existing Delta table.
Because your daily CSV file contains only new records and zero updates to existing rows, simply appending the data completely satisfies your requirements. It leaves all historical data untouched and requires the absolute lowest processing power because Databricks does not need to scan, modify, or rewrite any existing files.
Incorrect:
The UPDATE command is used to modify values in rows that already exist in the table based on a matching condition. It cannot be used to add entirely new rows to a table, and it requires a heavy scan of the data to find matches, which violates the requirement to keep processing low.
The INSERT OVERWRITE command deletes all the existing historical data in the table (or a specific partition) and replaces it with the data from the new CSV file. Using this would erase your historical sales data.
Reference:
https://medium.com/@jithujosekokken/understanding-data-patterns-in-medallion-architecture-full- incremental-and-change-only-loads-e33db28e51f4
NEW QUESTION # 33
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: A
Explanation:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
NEW QUESTION # 34
......
The Implementing Data Engineering Solutions Using Azure Databricks is ideal whether you're just beginning your career in open source or planning to advance your career. Moreover, the Implementing Data Engineering Solutions Using Azure Databricks also serves as a great stepping stone to earning advanced Implementing Data Engineering Solutions Using Azure Databricks. Success in the DP-750 exam is the basic requirement to get the a good job. You get multiple career benefits after cracking the Implementing Data Engineering Solutions Using Azure Databricks. These benefits include skills approval, high-paying jobs, and promotions. Read on to find more important details about the Microsoft DP-750 Exam Questions.
DP-750 Dumps Free: https://www.latestcram.com/DP-750-exam-cram-questions.html
BONUS!!! Download part of LatestCram DP-750 dumps for free: https://drive.google.com/open?id=19DTHFm41zAL1agvEMFKdQ-rwwSjz1rgL